2026 Latest Pass4sureCert DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1JUaFXfdtgRbfAnAyQ4fzmO7VARsYj5PI
DP-750 exam dumps have a higher pass rate than products in the same industry. If you want to pass DP-750 certification, then it is necessary to choose a product with a high pass rate. Our study materials guarantee the pass rate from professional knowledge, services, and flexible plan settings. According to user needs, DP-750 exam prep provides everything possible to ensure their success. The 99% pass rate is the proud result of our study materials. If you join, you will become one of the 99%. I believe that pass rate is also a big criterion for your choice of products, because your ultimate goal is to obtain DP-750 Certification. In DP-750 exam dumps, you can do it.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
>> New DP-750 Test Objectives <<
It is well known that certificates are not versatile, but without a DP-750 certification you are a little inferior to the same competitors in many ways. Compared with the people who have the same experience, you will have the different result and treatment if you have a DP-750 Certification. Without doubt, you will get a higher salary if you have a DP-750 certification or you can enter into a bigger company. And our DP-750 exam materials can make your dream come true.
NEW QUESTION # 26
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 27
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: B
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 28
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 29
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: C
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 30
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.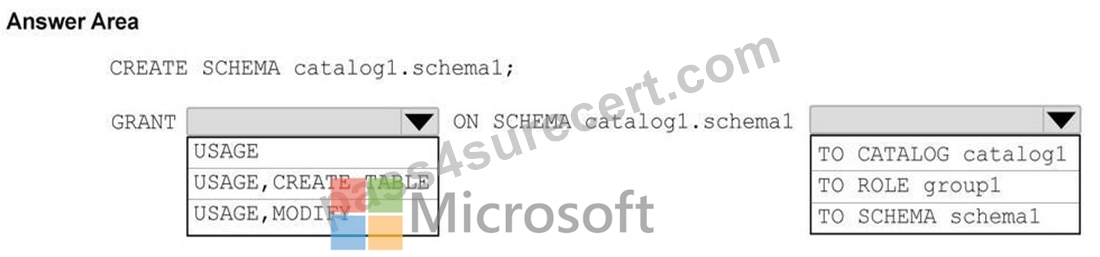
Answer:
Explanation: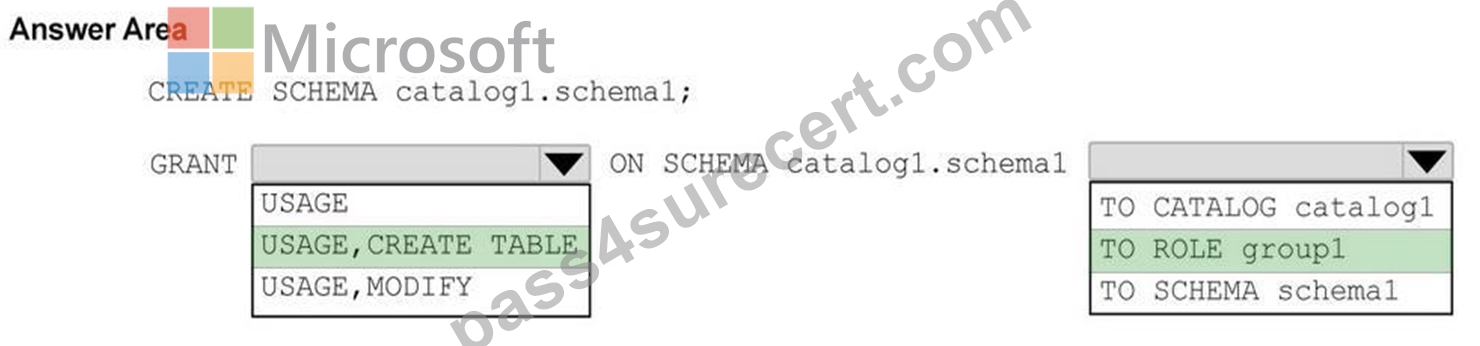
NEW QUESTION # 31
......
Pass4sureCert DP-750 valid test will assist you to pass your DP-750 actual test with ease. You will never regret to choose our DP-750 exam engine test. Here are some outstanding properties which can benefit all of you. The detailed explanations are offered where available to ensure you fully understand why to choose the correct answers. All the questions cover the main points which the DP-750 Actual Exam required. The answers of each question are correct and verified by our IT experts which can ensure you 100% pass.
DP-750 Exams: https://www.pass4surecert.com/Microsoft/DP-750-practice-exam-dumps.html
DOWNLOAD the newest Pass4sureCert DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1JUaFXfdtgRbfAnAyQ4fzmO7VARsYj5PI