Exam Databricks Certified-Data-Engineer-Professional Consultant & Certified-Data-Engineer-Professional Passguide

The pass rate is 98.65%, and we can ensure you pass the exam if you choose Certified-Data-Engineer-Professional training materials from us. In addition, we have professional experts to compile and verify Certified-Data-Engineer-Professional questions and answers, therefore you can just use them at ease. We also pass guarantee and money back guarantee if you fail to pass the exam. Free update for Certified-Data-Engineer-Professional Training Materials is available, namely, in the following year, you don’t need to spend a cent, but you can get the latest information of the exam. And the latest version for Certified-Data-Engineer-Professional exam briandumps will send to your email automatically.
| Section | Objectives |
|---|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Compare streaming tables and materialized views
- 6. Develop unit and integration tests for data processing code
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
>> Exam Databricks Certified-Data-Engineer-Professional Consultant <<
Certified-Data-Engineer-Professional Passguide & Certified-Data-Engineer-Professional Detailed Study Dumps
If you come to our website to choose Certified-Data-Engineer-Professional study materials, you will enjoy humanized service. Firstly, we have chat windows to wipe out your doubts about our Certified-Data-Engineer-Professional study materials. You can ask any question about our study materials. All of our online workers are going through special training. They are familiar with all details of our Certified-Data-Engineer-Professional Study Materials. Also, you have easy access to our free demo. Once you apply for our free trials of the study materials, our system will quickly send it via email.
Databricks Certified Data Engineer Professional Sample Questions (Q70-Q75):
NEW QUESTION # 70
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
- B. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
- C. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
- D. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
Answer: B
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 71
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data. Which configuration will provide the optimal performance while enabling these capabilities?
- A. Share tables WITH HISTORY, ensure tables don't have partitioning enabled, and enable CDF before sharing.
- B. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
- C. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- D. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
Answer: A
Explanation:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads, providers must share Delta tables WITH HISTORY. Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams.
Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support.
Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
NEW QUESTION # 72
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- B. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- C. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- D. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- E. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
Answer: A
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 73
The data engineering team maintains the following code:
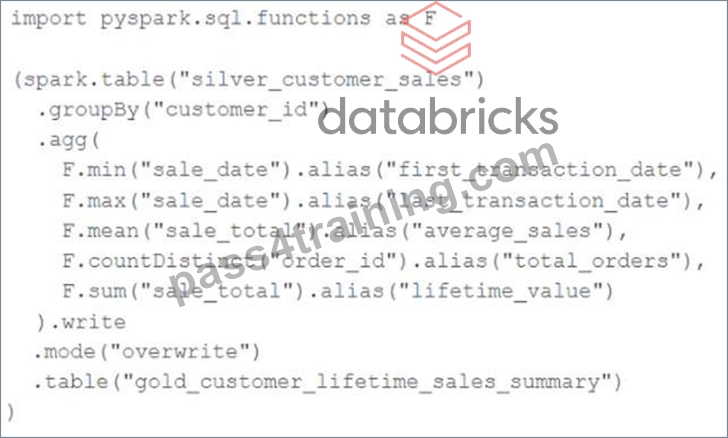
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- B. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- C. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
- D. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- E. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
Answer: E
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 74
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source.
That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
- A. Data can never be permanently dropped or deleted from Delta Lake, so data loss is not possible under any circumstance.
- B. Delta Lake schema evolution can retroactively calculate the correct value for newly added fields, as long as the data was in the original source.
- C. The Delta log and Structured Streaming checkpoints record the full history of the Kafka producer.
- D. Ingestine all raw data and metadata from Kafka to a bronze Delta table creates a permanent, replayable history of the data state.
- E. Delta Lake automatically checks that all fields present in the source data are included in the ingestion layer.
Answer: D
Explanation:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines.
Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information.
NEW QUESTION # 75
......
This is the most unique and helpful method of Databricks Certified-Data-Engineer-Professional exam preparation. Web-based practice exam helps you study with more concentration because it gives you a simulated Databricks Certified-Data-Engineer-Professional exam environment. This helps you in preventing Databricks Certified-Data-Engineer-Professional Exam anxiety and also gives you a broad insight into the Databricks Certified-Data-Engineer-Professional exam pattern. You can get examination experience before the actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam.
Certified-Data-Engineer-Professional Passguide: https://www.pass4training.com/Certified-Data-Engineer-Professional-pass-exam-training.html
- Realistic Exam Certified-Data-Engineer-Professional Consultant - Leader in Qualification Exams - Top Certified-Data-Engineer-Professional Passguide 🚝 Easily obtain ▶ Certified-Data-Engineer-Professional ◀ for free download through { www.prepawayexam.com } 📢Certified-Data-Engineer-Professional Test Tutorials
- Free PDF 2026 The Best Databricks Certified-Data-Engineer-Professional: Exam Databricks Certified Data Engineer Professional Consultant ⛑ Open website ▷ www.pdfvce.com ◁ and search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download 📺Certified-Data-Engineer-Professional Latest Test Braindumps
- Certified-Data-Engineer-Professional Authorized Exam Dumps 🍈 Certified-Data-Engineer-Professional Latest Test Dumps 🚃 Real Certified-Data-Engineer-Professional Questions 💛 Search on ✔ www.examcollectionpass.com ️✔️ for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download 🎴Certified-Data-Engineer-Professional Reliable Exam Voucher
- Free PDF 2026 The Best Databricks Certified-Data-Engineer-Professional: Exam Databricks Certified Data Engineer Professional Consultant 🏗 Search for ▷ Certified-Data-Engineer-Professional ◁ and download it for free immediately on ⇛ www.pdfvce.com ⇚ 🔥Certified-Data-Engineer-Professional Authorized Exam Dumps
- Buy Updated Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Dumps Today with Up to one year of Free Updates 🐪 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free immediately on “ www.prep4away.com ” 🏐Exam Certified-Data-Engineer-Professional Braindumps
- Certified-Data-Engineer-Professional Actual Braindumps ☝ Exam Dumps Certified-Data-Engineer-Professional Zip 👄 Certified-Data-Engineer-Professional Study Materials Review 👮 Easily obtain ▛ Certified-Data-Engineer-Professional ▟ for free download through ( www.pdfvce.com ) 🏚Exam Certified-Data-Engineer-Professional Braindumps
- Exam Dumps Certified-Data-Engineer-Professional Zip 🧤 Exam Certified-Data-Engineer-Professional Braindumps ⛪ Certified-Data-Engineer-Professional Latest Test Braindumps 🎿 Immediately open ▛ www.exam4labs.com ▟ and search for ( Certified-Data-Engineer-Professional ) to obtain a free download 🧨Certified-Data-Engineer-Professional Authorized Exam Dumps
- Test Certified-Data-Engineer-Professional Dumps Free ✳ Certified-Data-Engineer-Professional Latest Exam Registration 🐤 Certified-Data-Engineer-Professional Actual Braindumps 👷 Open website { www.pdfvce.com } and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 👉Certified-Data-Engineer-Professional Study Group
- Trustworthy Exam Certified-Data-Engineer-Professional Consultant - Leader in Qualification Exams - Valid Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional ↘ Search for ➡ Certified-Data-Engineer-Professional ️⬅️ on 《 www.troytecdumps.com 》 immediately to obtain a free download 🔏Real Certified-Data-Engineer-Professional Questions
- High-quality Databricks - Exam Certified-Data-Engineer-Professional Consultant 🦱 Download { Certified-Data-Engineer-Professional } for free by simply entering ▷ www.pdfvce.com ◁ website 😚Certified-Data-Engineer-Professional Test Engine Version
- Certified-Data-Engineer-Professional Study Materials Review 🎍 Exam Certified-Data-Engineer-Professional Braindumps 🚏 Exam Dumps Certified-Data-Engineer-Professional Zip 🌄 Easily obtain free download of “ Certified-Data-Engineer-Professional ” by searching on ▶ www.prepawaypdf.com ◀ 🗻Exam Dumps Certified-Data-Engineer-Professional Zip
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, zenwriting.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes