Microsoft DP-600 New APP Simulations & DP-600 Practice Test Engine

BONUS!!! Download part of Actual4dump DP-600 dumps for free: https://drive.google.com/open?id=1P0qR_-ndMBuoT1gcTBvKPl1uVGUD7Cv6
The Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam questions are the real, valid, and updated DP-600 Exam Questions that are specifically designed for quick and complete DP-600 exam preparation. With Actual4dump Implementing Analytics Solutions Using Microsoft Fabric (DP-600) practice test questions you can start Microsoft DP-600 exam preparation immediately.
Microsoft DP-600 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
|---|
| Exam Number: | DP-600 |
|---|
| Available Languages: | Korean, Chinese (Simplified), English, Japanese |
|---|
| Certificate Validity Period: | 1 year |
|---|
| Exam Duration: | 120 minutes |
|---|
| Exam Price: | $165 USD |
|---|
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
|---|
| Passing Score: | 700/1000 |
|---|
| Exam Format: | Case studies, Multiple-choice, Drag-and-drop |
|---|
| Real Exam Qty: | 40-60 |
|---|
| Sample Questions: | Microsoft DP-600 Sample Questions |
|---|
| Exam Way: | Online proctored or in-person testing center |
|---|
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
|---|
>> Microsoft DP-600 New APP Simulations <<
Free PDF DP-600 - Implementing Analytics Solutions Using Microsoft Fabric –High Pass-Rate New APP Simulations
As the saying goes, an inch of time is an inch of gold; time is money. If time be of all things the most precious, wasting of time must be the greatest prodigality. We believe that you will not want to waste your time, and you must want to pass your DP-600 Exam in a short time, so it is necessary for you to choose our Implementing Analytics Solutions Using Microsoft Fabric prep torrent as your study tool. If you use our products, you will just need to spend 20-30 hours to take your exam.
| Topic | Details |
|---|
| Topic 1 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
| Topic 2 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| Topic 3 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
Microsoft Implementing Analytics Solutions Using Microsoft Fabric Sample Questions (Q143-Q148):
NEW QUESTION # 143
You have a Fabric tenant that contains a semantic model.
You need to prevent report creators from populating visuals by using implicit measures.
What are two tools that you can use to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct answer is worth one point.
- A. Microsoft Power BI Desktop
- B. Microsoft SQL Server Management Studio (SSMS)
- C. DAX Studio
- D. Tabular Editor
Answer: A,B
Explanation:
Microsoft Power BI Desktop (A) and Tabular Editor (B) are the tools you can use to prevent report creators from using implicit measures. In Power BI Desktop, you can define explicit measures which can be used in visuals. Tabular Editor allows for advanced model editing, where you can enforce the use of explicit measures. References = Guidance on using explicit measures and preventing implicit measures in reports can be found in the Power BI and Tabular Editor official documentation.
NEW QUESTION # 144
What should you recommend using to ingest the customer data into the data store in the AnatyticsPOC workspace?
- A. a stored procedure
- B. a Spark notebook
- C. a dataflow
- D. a pipeline that contains a KQL activity
Answer: C
Explanation:
For ingesting customer data into the data store in the AnalyticsPOC workspace, a dataflow (D) should be recommended. Dataflows are designed within the Power BI service to ingest, cleanse, transform, and load data into the Power BI environment. They allow for the low-code ingestion and transformation of data as needed by Litware's technical requirements. References = You can learn more about dataflows and their use in Power BI environments in Microsoft's Power BI documentation.
NEW QUESTION # 145
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.
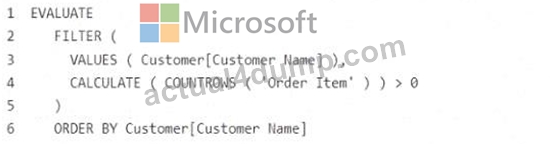
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:

Does this meet the goal?
Answer: A
Explanation:
The suggested replacement does not improve performance. COUNTROWS('Order Item') < 0 is always false (row counts cannot be negative), so the NOT will always evaluate to true. This means the filter condition becomes non-selective and would return all customers, not just those with orders. Therefore, it does not meet the optimization goal.
NEW QUESTION # 146
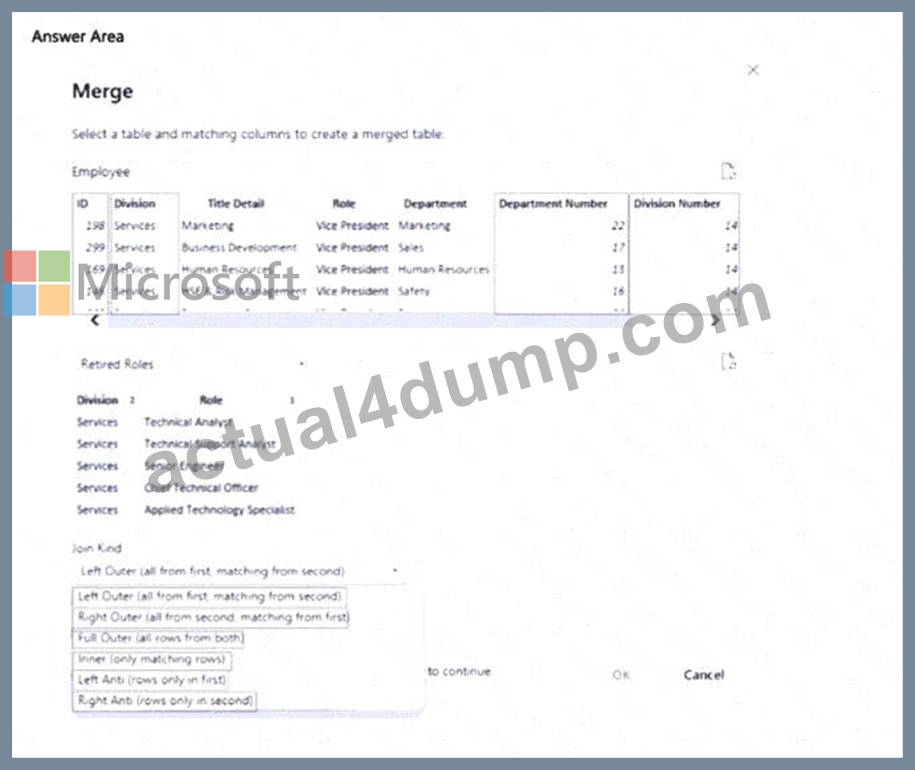
You have two Microsoft Power Bl queries named Employee and Retired Roles.
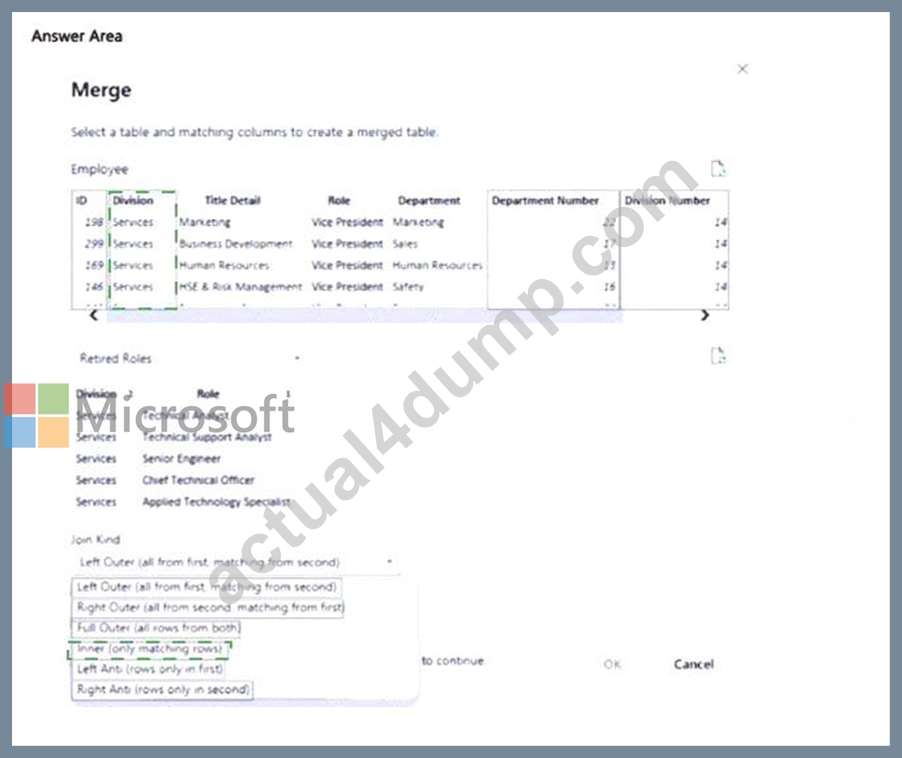
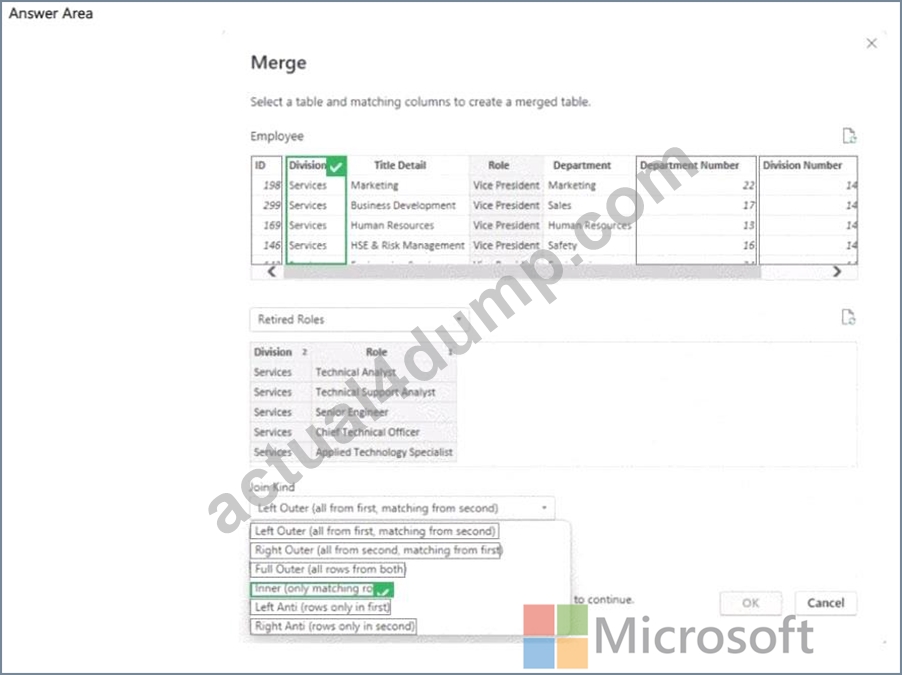
You need to merge the Employee query with the Retired Roles query. The solution must ensure that rows in the Employee query that match the Retired Roles query are removed.
Which column and Join Kind should you use in Power Query Editor? To answer, select the appropriate options in the answer area.
NOTE: Each correct answer is worth one point
Answer:
Explanation:
Explanation:
NEW QUESTION # 147
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.
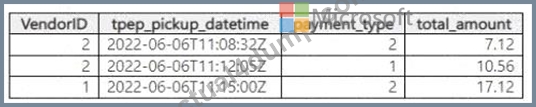
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
NOTE: Each correct selection is worth one point.
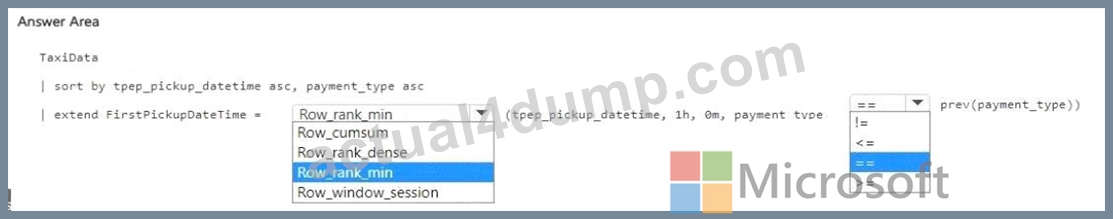
Answer:
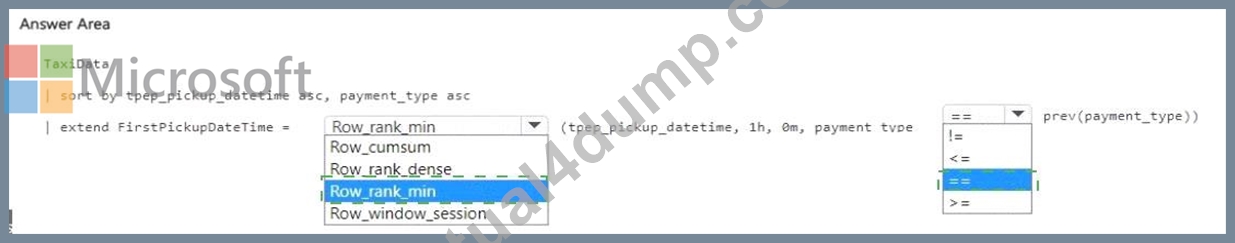
Explanation:
Explanation:
Comprehensive Detailed Explanation
We have a KQL table (TaxiData) with columns:
VendorID
tpep_pickup_datetime (timestamp)
payment_type
total_amount
The requirement:
Create a new column FirstPickupDateTime
It should contain the first pickup timestamp per hour
Partitioning should be done by payment_type
Step 1: Which windowing function?
row_cumsum # running cumulative sum (not needed here).
row_rank_dense # assigns ranks without gaps, but does not guarantee minimum value only.
row_rank_min # gives the first/minimum value in each window partition. # Correct.
row_window_session # sessionization of events, not required.
So, the correct function is row_rank_min .
Step 2: Which comparison operator?
We need to select the row where the rank = 1 (the first per partition).
So the correct operator is == (equals).
Step 3: Partitioning
The KQL query should partition by:
bin(tpep_pickup_datetime, 1h) # buckets data into 1-hour windows
payment_type # partitions further by payment type
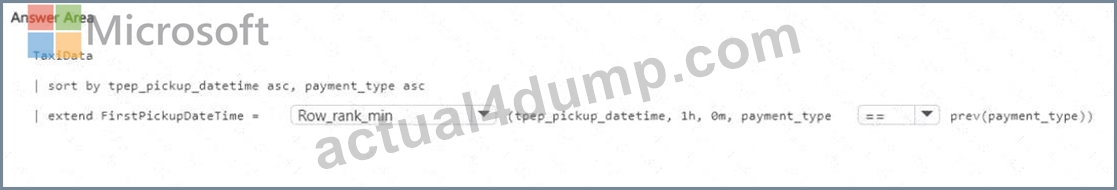
Completed KQL Query
TaxiData
| sort by tpep_pickup_datetime asc, payment_type asc
| extend FirstPickupDateTime = row_rank_min(tpep_pickup_datetime, 1h, 0m, payment_type)
| where FirstPickupDateTime == 1
This assigns a rank within each 1-hour, per-payment-type window, then keeps the first pickup timestamp .
Why This Works
row_rank_min # ensures we capture the first occurrence in each hour.
== # filters only the first row per partition.
bin(..., 1h) ensures grouping is by hour.
References
Kusto row_rank_min() function
KQL window functions
NEW QUESTION # 148
......
DP-600 Practice Test Engine: https://www.actual4dump.com/Microsoft/DP-600-actualtests-dumps.html
- 2026 Trustable 100% Free DP-600 – 100% Free New APP Simulations | DP-600 Practice Test Engine 🤭 Copy URL 「 www.examcollectionpass.com 」 open and search for ▷ DP-600 ◁ to download for free 🥉DP-600 Test Score Report
- 2026 Trustable 100% Free DP-600 – 100% Free New APP Simulations | DP-600 Practice Test Engine 🐾 The page for free download of ▶ DP-600 ◀ on [ www.pdfvce.com ] will open immediately ⛽Certification DP-600 Sample Questions
- DP-600 Exam Collection - DP-600 Study Materials - DP-600 Valid Braindumps 📦 [ www.vce4dumps.com ] is best website to obtain ⇛ DP-600 ⇚ for free download 🦦DP-600 Reliable Exam Pattern
- Test DP-600 Centres 🦑 Test DP-600 Centres 🦳 DP-600 Test Pdf 🔸 Search for 「 DP-600 」 and obtain a free download on 「 www.pdfvce.com 」 🆗Test DP-600 Centres
- Cost-Effective Microsoft DP-600 Exam [2026] 🧽 Search for ➥ DP-600 🡄 and download exam materials for free through “ www.validtorrent.com ” 👩DP-600 Test Score Report
- Reliable DP-600 Exam Book 🦍 Reliable DP-600 Exam Book 👧 Reliable DP-600 Exam Book 😭 Search on ▛ www.pdfvce.com ▟ for ➠ DP-600 🠰 to obtain exam materials for free download 🕎DP-600 Reliable Exam Topics
- Free PDF Quiz 2026 Microsoft DP-600: Professional Implementing Analytics Solutions Using Microsoft Fabric New APP Simulations 😱 Simply search for 《 DP-600 》 for free download on ▛ www.prepawaypdf.com ▟ 💷Practice DP-600 Mock
- DP-600 Latest Exam 🧘 Valid DP-600 Test Topics 🌠 Reliable DP-600 Exam Book 📡 Open website ⏩ www.pdfvce.com ⏪ and search for ( DP-600 ) for free download 🍱DP-600 Test Score Report
- Latest DP-600 Exam Notes 📕 DP-600 Test Score Report 🥐 DP-600 Test Pdf 🤵 Search for ☀ DP-600 ️☀️ and download it for free on ▶ www.vce4dumps.com ◀ website 👜DP-600 Test Book
- Cost-Effective Microsoft DP-600 Exam [2026] ⛅ Search for “ DP-600 ” and download it for free immediately on ⮆ www.pdfvce.com ⮄ 🚔Reliable DP-600 Exam Book
- Reliable DP-600 Exam Book 🛫 Practice DP-600 Mock 😕 DP-600 Test Pdf ☎ ➥ www.verifieddumps.com 🡄 is best website to obtain ➠ DP-600 🠰 for free download 🍱DP-600 Latest Braindumps Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest Actual4dump DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1P0qR_-ndMBuoT1gcTBvKPl1uVGUD7Cv6