2026 Latest PrepAwayPDF SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1D3Qp9rD0YGXsBMWlgR1PSwgcsr6eoWka
Snowflake SPS-C01 exam torrent is famous for instant download. You will receive downloading link and password within ten minutes, and if you don’t receive, just contact us, we will check for you. In addition, SPS-C01 Exam Materials are high quality, it covers major knowledge points for the exam, you can have an easy study if you choose us.
| Section | Objectives |
|---|---|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
>> Latest SPS-C01 Study Notes <<
All the PrepAwayPDF Snowflake SPS-C01 practice questions are real and based on actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam topics. The web-based Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test is compatible with all operating systems like Mac, IOS, Android, and Windows. Because of its browser-based Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice exam, it requires no installation to proceed further. Similarly, Chrome, IE, Firefox, Opera, Safari, and all the major browsers support the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test.
NEW QUESTION # 357
Which of the following statements are correct regarding account identifiers and their usage when creating Snowpark sessions in Python?
Answer: B,C
Explanation:
Account identifiers provide a unique way to connect to Snowflake accounts. If the identifier includes the region ID, specifying it separately is redundant. Snowflake supports both 'Organization Name-Account Name' and legacy account locators. Option A is incorrect because account identifiers are case-insensitive. Option B is incorrect, account identifiers can be used across regions. Option D is incorrect.
NEW QUESTION # 358
You're developing a Snowpark Python application to process log files stored in an external stage 's3_logs'. These logs are in plain text, with each line representing a log entry. You need to filter log entries based on a specific keyword and extract timestamps from the matching lines. Which of the following approaches, using and Snowpark DataFrames, will efficiently accomplish this, avoiding unnecessary data transfer to the client?
Answer: E
Explanation:
Option E provides the most efficient solution. By using 'session.read.option('PATTERN', ' you load the data directly into a DataFrame within Snowflake. A UDTF (User-Defined Table Function) is then used to process each partition of the DataFrame, performing the filtering and timestamp extraction in parallel within the Snowflake environment, minimizing data transfer to the client. Option A is highly inefficient as it downloads all files to the client. Option B is less efficient than E because it processes all rows through a single UDF instead of distributed processing using UDTF. It also assumes all log data can be held in a single dataframe which can create memory issues Option C is similar to B and it uses UDF instead of UDTF making it less efficient. Option D introduces external dependencies to the solution.
NEW QUESTION # 359
You are working with a Snowpark DataFrame 'products df' containing product information, including 'product_id', 'price', and 'discount'. You need to update the 'price' column in the 'products' table based on the following logic: If 'discount' is greater than 0.2, reduce the 'price' by 15%. If 'discount' is between 0.1 and 0.2 (inclusive), reduce the 'price' by 5%. Otherwise, keep the 'price' as is. Which of the following Snowpark code snippets efficiently implements this update? Assume 'products' table already exists and is correctly populated.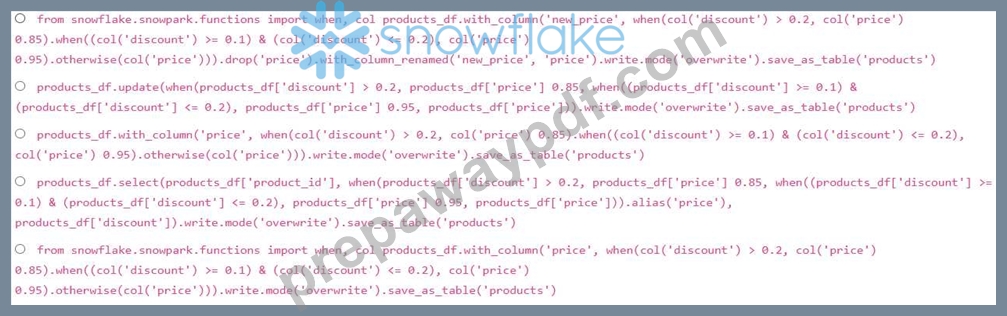
Answer: D
Explanation:
Option E is the most concise and correct solution. It uses 'with_column' to directly update the 'price' column based on the discount conditions, using nested 'when' functions for the logic and persists the change. Option A, while technically correct, is less efficient because it creates a new column ('new_price'), drops the original 'price' column, and then renames the new column. Option B tries to use an 'update' method which doesn't exist directly on Snowpark DataFrames in that way. Option C works correctly. Option D has an issue that it won't keep the original schema of the table being updated as it is selecting each of the columns.
NEW QUESTION # 360
You have a Snowpark DataFrame 'employees' with columns 'employee_id' (INT), 'name' (STRING), 'department' (STRING), and 'salary' (DOUBLE). You want to create a new DataFrame that contains the top 3 highest-paid employees within each department. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





Answer: C,D,E
Explanation:
The most efficient and correct approaches are A, C, and D. These options utilize window functions in Snowpark to efficiently rank employees within each department. Option A uses , which assigns a unique rank to each row within a partition, even if there are ties in salary. Option C uses 'rank()' , which assigns the same rank to rows with equal salary values, resulting in possible gaps in the ranking sequence. Option D uses , which assigns consecutive ranks without gaps, even if there are ties in salary. The most appropriate ranking function will depend on the specific ranking requirement but all three would provide top 3 employees. Option B is incorrect because Snowpark 'apply' does not support groupby operations effectively, resulting in an error. Finally E will only return 2 employees, which would make it incorrect.
NEW QUESTION # 361
Consider a JSON structure representing product information, where prices are stored as strings due to inconsistent data quality. You need to calculate the average price of products. However, some price strings contain non-numeric characters (e.g., '$', commas). Which of the following approaches, using Snowpark DataFrame operations, is the MOST robust and efficient way to clean and cast the price data to a numeric type for accurate average calculation?





Answer: C
Explanation:
Option D is the most robust. It uses 'regexp_replace' to remove '$' and commas from the price string and then uses which handles cases where the cleaned string still cannot be converted to a number gracefully (returning NULL instead of throwing an error). Then computes the average on this column. Option A would fail in some cases as it cast the string to float directly, so some string format won't work, it's better using Option B would throw error while casting when the number is not in float format. Option C would throw error while casting as to_number need to be called with a format to work. Option E would raise conversion error because return variant and not numeric type to be cast to float.
NEW QUESTION # 362
......
IT certification exam cost is really large cost for most candidates in the whole world. Passing exam at first attempt will be everyone's goal. Now our Snowflake SPS-C01 valid exam cram review can help you achieve your goal. Recent years we are engaging in providing 100% pass-rate SPS-C01 Valid Exam Cram review for buyers from all over the world, and help thousands of candidates go through exam every year. If you have doubt in your test, let us help you pass exam for sure.
Latest SPS-C01 Examprep: https://www.prepawaypdf.com/Snowflake/SPS-C01-practice-exam-dumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=1D3Qp9rD0YGXsBMWlgR1PSwgcsr6eoWka