Our users are all over the world, and users in many countries all value privacy. Our AI-200 simulating exam ' global system of privacy protection standards has reached the world's leading position. No matter where you are, you don't have to worry about your privacy being leaked if you ask questions about our AI-200 Exam Braindumps or you pay for our AI-200 practice guide by your credit card. It is safe for our customers to buy our AI-200 learning materials!
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
>> AI-200 Reliable Test Bootcamp <<
Our company has always been keeping pace with the times, so we are pushing renovation about AI-200 test engine all the time to meet the different requirements of diversified production market. However it is obvious that different people have different preferences on AI-200 preparation materials, thus we have three kinds of versions. If you are used to study with paper-based materials you can choose the PDF version. If you would like to get the mock test before the Real AI-200 Exam you can choose the software version, if you want to study in anywhere at any time then our online APP version should be your best choice.
NEW QUESTION # 121
You are provisioning and configuring a Service Bus processor for AI batch jobs.
The processor must connect to an existing queue, register handlers for message and error processing, and then begin receiving messages.
You need to provision and configure the Service Bus processor for message and error handling.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.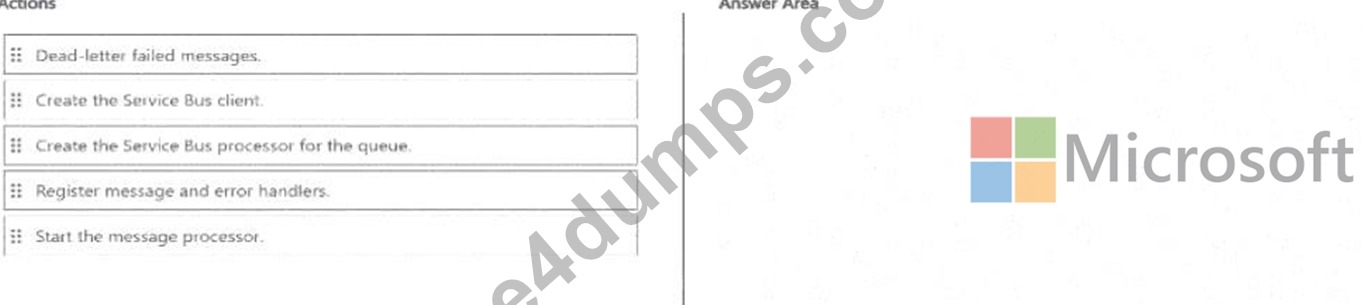
Answer:
Explanation: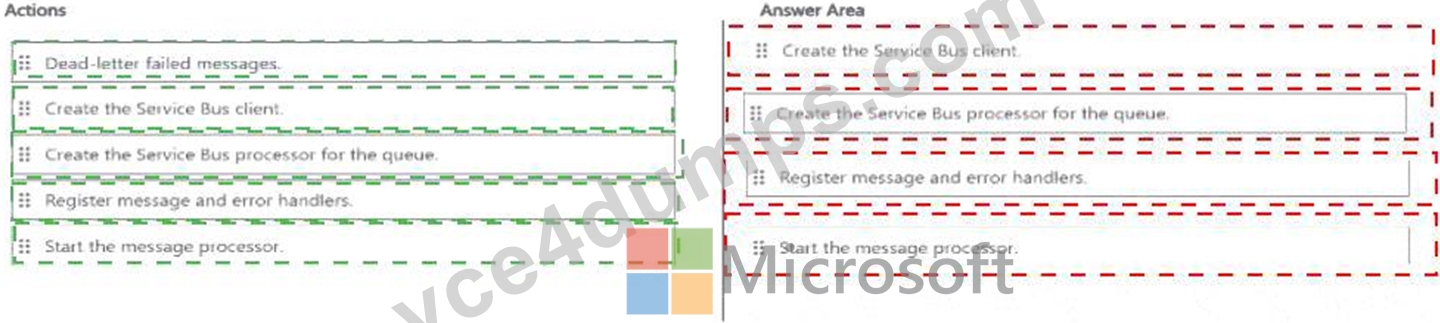
Explanation: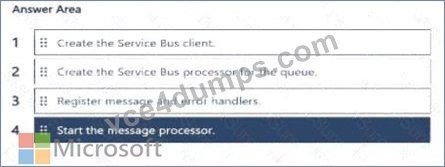
Verified Answer: 1) Create the Service Bus client; 2) create the queue processor/receiver; 3) register message and error handlers; 4) start the message processor.
Detailed Explanation: The processor depends on a namespace client/connection, so the client is created first.
Next, the queue-specific processor or receiver is created from that client. Message and error callbacks must be registered before processing starts so incoming messages and failures have defined handlers. Starting the processor is therefore the final step. Dead-lettering failed messages is an optional application settlement decision and is not a prerequisite for constructing and starting the processor.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
NEW QUESTION # 122
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to deploy Azure Function resources and apps to meet the business and technical requirements. What should you use?
Answer: A
Explanation:
GitHub Actions is the correct tool to use.
Automated Pipeline: It natively automates infrastructure deployment (Bicep) and code compilation through version-controlled workflows.
Eliminates Local Deployments: Workloads are triggered by repository events (like a code merge), removing the need for manual command-line interventions.
Auditability & Repeatability: It keeps a centralized log of every deployment, ensuring a clear audit trail for governance.
Scenario:
Technical Requirements
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Business Requirements
Development efforts must be minimized.
Reference:
https://github.com/marketplace/actions/azure-functions-action
NEW QUESTION # 123
You are developing an AI application that retrieves database credentials from Key Vault by using the Azure SDK for Python.
The application must use managed identity for authentication.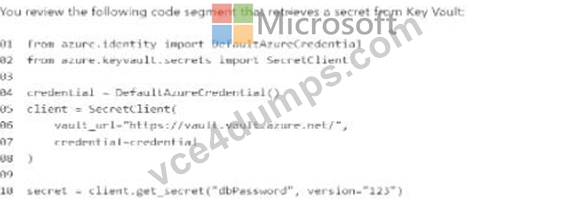
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.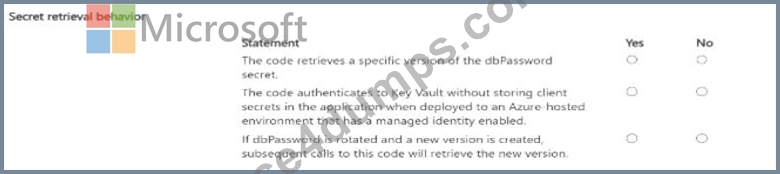
Answer:
Explanation: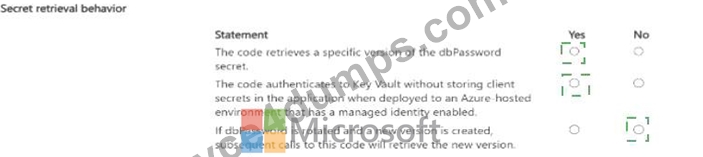
Explanation: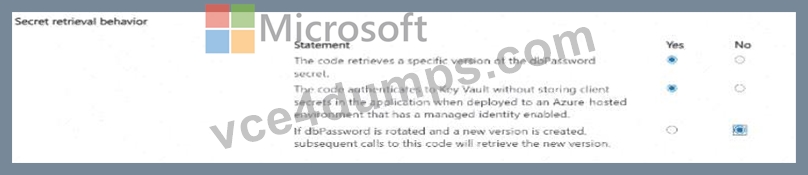
Verified answer: Yes; Yes; No.
Detailed Explanation: The get_secret call supplies an explicit version value, so it retrieves that particular version of dbPassword. DefaultAzureCredential can authenticate to Key Vault by using the Azure-hosted application's managed identity without embedding a client secret in the application. Because the code requests a fixed version, later secret rotation creates a newer version but subsequent executions of this exact code continue to request the specified old version. To follow the latest version automatically, the version parameter must be omitted.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Managed identities for Azure resources | Use Key Vault references for App Service and Functions
NEW QUESTION # 124
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
Answer: A
NEW QUESTION # 125
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Detailed Explanation: The objective is to reduce RU consumption from vector similarity queries. Microsoft guidance identifies vector numeric precision and vector-index selection as major cost and performance levers.
Using a lower supported vector precision can reduce storage and processing cost, while quantizedFlat and DiskANN are designed to reduce latency and RU consumption compared with flat search for appropriate data sizes. Strong consistency would increase resource cost rather than solve vector-search efficiency. A regular composite index is not a substitute for the vector index. Option B should be read as reducing vector numeric precision, not changing a generic "indexing precision" setting.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Cosmos DB | Optimize Cosmos DB vector search performance
NEW QUESTION # 126
......
Microsoft Certified professionals are often more sought after than their non-certified counterparts and are more likely to earn higher salaries and promotions. Moreover, cracking the Developing AI Cloud Solutions on Azure (AI-200) exam helps to ensure that you stay up to date with the latest trends and developments in the industry, making you more valuable assets to your organization.
AI-200 Valid Test Vce: https://www.vce4dumps.com/AI-200-valid-torrent.html