Außerdem sind jetzt einige Teile dieser EchteFrage Databricks-Generative-AI-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1eOhPE2keGt62XictKR_u24LkrjjWoug5
Die Schulungsunterlagen zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung von EchteFrage können Ihnen helfen, Ihren Traum zu realisieren, weil es alle Zertifizierungsantworten zur Databricks Databricks-Generative-AI-Engineer-Associate Prüfung hat. Mit EchteFrage können Sie sich ganz gut auf die Prüfung vorbereiten. Per unsere guten Schulungsunterlagen von guter Qualität können Sie sicher die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung bestehen und eine glänzende Zukunft haben.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design Applications | 14% | - Design and architect applications - Select appropriate models - Define functional requirements |
| Topic 2: Evaluation and Monitoring | 12% | - Monitor deployed applications - Evaluate model quality and performance |
| Topic 3: Governance | 8% | - Apply safety filters and guidelines - Manage permissions and logging |
| Topic 4: Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains - Implement prompt engineering |
| Topic 5: Assembling and Deploying Apps | 22% | - Package and deploy models - Build and deploy RAG pipelines - Use Vector Search |
| Topic 6: Data Preparation | 14% | - Prepare data for RAG applications - Manage data quality and chunking |
>> Databricks-Generative-AI-Engineer-Associate Lerntipps <<
Laut Umfragen haben die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung heutzutage hohe Konjunktur in IT-Zertifizierungen. Tatsächlich ist die Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung sehr wichtig. Und jetzt ist Databricks-Generative-AI-Engineer-Associate Prüfung öffentlich zertifiziert. Außerdem kann diese Prüfung Ihre ausgezeichnete IT-Fähigkeit beweisen. Aber es ist sehr schwer, Databricks Databricks-Generative-AI-Engineer-Associate Prüfung zu bestehen. Und die Schwierigkeit ist so groß wie ihre Bedeutung. Trotzt dieser Schwierigkeit sorgen Sie sich bitte nicht um den Erfolg, die Prüfung ablegen, weil EchteFrage Ihnen helfen kann, diese schwierige Databricks-Generative-AI-Engineer-Associate Prüfung zu bestehen.
26. Frage
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
Antwort: D
Begründung:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is to create an agent that has access to specific tools (option D).
Agent with SQL and Web Search Capabilities:
By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
Why This Approach Works:
SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
Why Other Options Are Less Suitable:
A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
27. Frage
A Generative AI Engineer has deployed a RAG application to production. Its Vector Search index is built from a Delta table that receives incremental updates every hour from an upstream ETL pipeline. The team wants the index to automatically reflect source-table changes without manual re-indexing and without changing the endpoint used by downstream applications.
Which approach should the engineer use?
Antwort: B
Begründung:
D identifies the index type designed to synchronize with a source Delta table. Delta Sync supports incremental maintenance, avoiding a custom process that repeatedly rebuilds the complete index or manually pushes every changed vector. A Direct Vector Access index transfers update responsibility to the application.
However, this question has a configuration ambiguity: Delta Sync also has a synchronization mode.
Continuous mode processes arriving changes automatically, while triggered mode requires an explicit synchronization request, which can be scheduled after ETL. If the existing index is already a triggered Delta Sync index, B is the relevant configuration change. D is therefore the intended architectural answer, with continuous synchronization or an automated trigger needed to deliver the requested operational behavior.
Databricks API documentation
28. Frage
A Generative AI Engineer I using the code below to test setting up a vector store: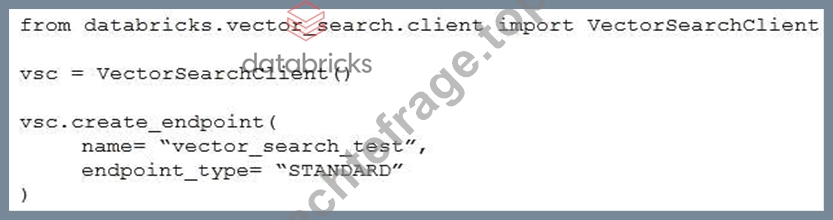
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Antwort: A
Begründung:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
29. Frage
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Antwort: D
30. Frage
A Generative Al Engineer is building a system that will answer questions on currently unfolding news topics.
As such, it pulls information from a variety of sources including articles and social media posts. They are concerned about toxic posts on social media causing toxic outputs from their system.
Which guardrail will limit toxic outputs?
Antwort: C
Begründung:
The system answers questions on unfolding news topics using articles and social media, with a concern about toxic outputs from toxic inputs. A guardrail must limit toxicity in the LLM's responses. Let's evaluate the options.
* Option A: Use only approved social media and news accounts to prevent unexpected toxic data from getting to the LLM
* Curating input sources (e.g., verified accounts) reduces exposure to toxic content at the data ingestion stage, directly limiting toxic outputs. This is a proactive guardrail aligned with data quality control.
* Databricks Reference:"Control input data quality to mitigate unwanted LLM behavior, such as toxicity"("Building LLM Applications with Databricks," 2023).
* Option B: Implement rate limiting
* Rate limiting controls request frequency, not content quality. It prevents overload but doesn't address toxicity in social media inputs or outputs.
* Databricks Reference: Rate limiting is for performance, not safety:"Use rate limits to manage compute load"("Generative AI Cookbook").
* Option C: Reduce the amount of context items the system will include in consideration for its response
* Reducing context might limit exposure to some toxic items but risks losing relevant information, and it doesn't specifically target toxicity. It's an indirect, imprecise fix.
* Databricks Reference: Context reduction is for efficiency, not safety:"Adjust context size based on performance needs"("Databricks Generative AI Engineer Guide").
* Option D: Log all LLM system responses and perform a batch toxicity analysis monthly
* Logging and analyzing responses is reactive, identifying toxicity after it occurs rather than preventing it. Monthly analysis doesn't limit real-time toxic outputs.
* Databricks Reference: Monitoring is for auditing, not prevention:"Log outputs for post-hoc analysis, but use input filters for safety"("Building LLM-Powered Applications").
Conclusion: Option A is the most effective guardrail, proactively filtering toxic inputs from unverified sources, which aligns with Databricks' emphasis on data quality as a primary safety mechanism for LLM systems.
31. Frage
......
Es ist ganz normal, vor der Prüfung Angst zu haben, besonders vor der schwierig Prüfung wie Databricks Databricks-Generative-AI-Engineer-Associate. Wir wissen, dass allein mit der Ermutigung können Ihnen nicht selbstbewusst machen. Deshalb bieten wir die praktische Prüfungssoftware, um Ihnen zu helfen, Databricks Databricks-Generative-AI-Engineer-Associate zu bestehen. Sie können zuerst die Demo der Databricks Databricks-Generative-AI-Engineer-Associate gratis probieren. Wir glauben, dass Sie bestimmt unsere Bemühungen und Professionellsein von der Demo empfinden!
Databricks-Generative-AI-Engineer-Associate Buch: https://www.echtefrage.top/Databricks-Generative-AI-Engineer-Associate-deutsch-pruefungen.html
Übrigens, Sie können die vollständige Version der EchteFrage Databricks-Generative-AI-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1eOhPE2keGt62XictKR_u24LkrjjWoug5