P.S. Free & New DOP-C02 dumps are available on Google Drive shared by DumpTorrent: https://drive.google.com/open?id=1TXlz29zGUtCu1N6UIBol3AklAlMEB0oA
The practice test is a convenient tool to identify weak points in the AWS Certified DevOps Engineer - Professional preparation. You can easily customize the level of difficulty of Amazon DOP-C02 Practice Test to suit your study tempo. Our web-based practice test is an ideal way to create an Amazon exam-like situation.
Amazon DOP-C02 (AWS Certified DevOps Engineer - Professional) Certification Exam is designed to test the skills and knowledge of DevOps professionals who work with the Amazon Web Services (AWS) platform. DOP-C02 Exam is aimed at experienced DevOps engineers who have a deep understanding of AWS services and are able to manage complex, multi-tier applications on the AWS platform.
>> Practice DOP-C02 Test Online <<
DumpTorrent is one of the leading platforms that has been helping AWS Certified DevOps Engineer - Professional (DOP-C02) exam candidates for many years. Over this long time period we have helped AWS Certified DevOps Engineer - Professional (DOP-C02) exam candidates in their preparation. They got help from DumpTorrent Amazon DOP-C02 Practice Questions and easily got success in the final Amazon DOP-C02 certification exam. You can also trust DumpTorrent AWS Certified DevOps Engineer - Professional (DOP-C02) exam dumps and start preparation with complete peace of mind and satisfaction.
The AWS Certified DevOps Engineer - Professional certification is particularly important for those who want to advance their careers in the field of DevOps. It is an industry-recognized certification that can greatly enhance the job prospects of professionals in this field. Companies are increasingly looking for professionals with AWS certifications, and the DOP-C02 Certification is one of the most valuable certifications in this regard.
NEW QUESTION # 164
A company deploys an application to Amazon EC2 instances. The application runs Amazon Linux 2 and uses AWS CodeDeploy. The application has the following file structure for its code repository: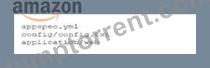
The appspec.yml file has the following contents in the files section: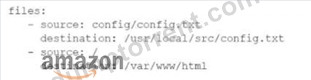
What will the result be for the deployment of the config.txt file?
Answer: D
Explanation:
Deployment of config.txt file based on the appspec.yml:
The appspec.yml file specifies that config/config.txt should be copied to /usr/local/src/config.txt.
The source: / directive in the appspec.yml indicates that the entire directory structure starting from the root of the application source should be copied to the specified destination, which is /var/www/html.
Result of the Deployment:
The config.txt file will be specifically deployed to /usr/local/src/config.txt as per the explicit file mapping.
The entire directory structure including application/web will be copied to /var/www/html, but this does not include config/config.txt since it has a specific destination defined.
Thus, the config.txt file will be deployed only to /usr/local/src/config.txt.
Therefore, the correct answer is:
C). The config.txt file will be deployed to only /usr/local/src/config.txt.
References:
AWS CodeDeploy AppSpec File Reference
AWS CodeDeploy Deployment Process
NEW QUESTION # 165
A company sells products through an ecommerce web application The company wants a dashboard that shows a pie chart of product transaction details. The company wants to integrate the dashboard With the companfs existing Amazon CloudWatch dashboards Which solution Will meet these requirements With the MOST operational effictency?
Answer: C
Explanation:
The correct answer is A.
A comprehensive and detailed explanation is:
Option A is correct because it meets the requirements with the most operational efficiency. Updating the ecommerce application to emit a JSON object to a CloudWatch log group for each processed transaction is a simple and cost-effective way to collect the data needed for the dashboard. Using CloudWatch Logs Insights to query the log group and to visualize the results in a pie chart format is also a convenient and integrated solution that leverages the existing CloudWatch dashboards. Attaching the results to the desired CloudWatch dashboard is straightforward and does not require any additional steps or services.
Option B is incorrect because it introduces unnecessary complexity and cost. Updating the ecommerce application to emit a JSON object to an Amazon S3 bucket for each processed transaction is a valid way to store the data, but it requires creating and managing an S3 bucket and its permissions. Using Amazon Athena to query the S3 bucket and to visualize the results in a pie chart format is also a valid way to analyze the data, but it incurs charges based on the amount of data scanned by each query. Exporting the results from Athena and attaching them to the desired CloudWatch dashboard is also an extra step that adds more overhead and latency.
Option C is incorrect because it uses AWS X-Ray for an inappropriate purpose. Updating the ecommerce application to use AWS X-Ray for instrumentation is a good practice for monitoring and tracing distributed applications, but it is not designed for aggregating product transaction details. Creating a new X-Ray subsegment and adding an annotation for each processed transaction is possible, but it would clutter the X-Ray service map and make it harder to debug performance issues. Using X-Ray traces to query the data and to visualize the results in a pie chart format is also possible, but it would require custom code and logic that are not supported by X-Ray natively. Attaching the results to the desired CloudWatch dashboard is also not supported by X-Ray directly, and would require additional steps or services.
Option D is incorrect because it introduces unnecessary complexity and cost. Updating the ecommerce application to emit a JSON object to a CloudWatch log group for each processed transaction is a simple and cost-effective way to collect the data needed for the dashboard, as in option A) However, creating an AWS Lambda function to aggregate and write the results to Amazon DynamoDB is redundant, as CloudWatch Logs Insights can already perform aggregation queries on log data. Creating a Lambda subscription filter for the log file is also redundant, as CloudWatch Logs Insights can already access log data directly. Attaching the results to the desired CloudWatch dashboard would also require additional steps or services, as DynamoDB does not support native integration with CloudWatch dashboards.
Reference:
CloudWatch Logs Insights
Amazon Athena
AWS X-Ray
AWS Lambda
Amazon DynamoDB
NEW QUESTION # 166
A company's application has an API that retrieves workload metrics. The company needs to audit, analyze, and visualize these metrics from the application to detect issues at scale.
Which combination of steps will meet these requirements? (Select THREE).
Answer: B,C,F
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
The recommended architecture to audit, analyze, and visualize application workload metrics at scale involves:
* UsingAmazon EventBridgeto scheduleAWS Lambdainvocations that call the application API and fetch metrics (Option A). The data is stored inAmazon S3, which is ideal for scalable, cost-effective storage of large datasets.
* Cataloging the stored data withAWS Glue crawlers, enabling schema discovery and making data queryable viaAmazon Athena(Option C).
* Visualizing the data by creatingAmazon QuickSight datasetsfrom Athena views and building dashboards for analysis (Option E).Option B and D introduce DynamoDB, which is less suitable for large-scale analytics and Athena querying. Option F suggests querying Athena via Lambda widgets in CloudWatch, which adds complexity without significant benefit over QuickSight.
Reference:
Serverless Analytics Architecture on AWS:"Use Lambda + S3 + Glue + Athena + QuickSight for scalable data ingestion, cataloging, querying, and visualization."(AWS Analytics Reference Architecture) AWS Glue Crawlers and Athena:"Glue crawlers catalog data stored in S3 and create Athena tables to enable SQL querying."(AWS Glue Documentation) Amazon QuickSight for Visualization:"QuickSight enables creating interactive dashboards from Athena query results."(Amazon QuickSight Overview)
NEW QUESTION # 167
A company is adopting AWS CodeDeploy to automate its application deployments for a Java-Apache Tomcat application with an Apache Webserver. The development team started with a proof of concept, created a deployment group for a developer environment, and performed functional tests within the application. After completion, the team will create additional deployment groups for staging and production.
The current log level is configured within the Apache settings, but the team wants to change this configuration dynamically when the deployment occurs, so that they can set different log level configurations depending on the deployment group without having a different application revision for each group.
How can these requirements be met with the LEAST management overhead and without requiring different script versions for each deployment group?
Answer: D
Explanation:
The following are the steps that the company can take to change the log level dynamically when the deployment occurs:
Create a script that uses the CodeDeploy environment variable DEPLOYMENT_GROUP_NAME to identify which deployment group the instance is part of.
Use this information to configure the log level settings.
Reference this script as part of the BeforeInstall lifecycle hook in the appspec.yml file.
The DEPLOYMENT_GROUP_NAME environment variable is automatically set by CodeDeploy when the deployment is triggered. This means that the script does not need to call the metadata service or the EC2 API to identify the deployment group.
This solution is the least complex and requires the least management overhead. It also does not require different script versions for each deployment group.
The following are the reasons why the other options are not correct:
Option A is incorrect because it would require tagging the Amazon EC2 instances, which would be a manual and time-consuming process.
Option C is incorrect because it would require creating a custom environment variable for each environment. This would be a complex and error-prone process.
Option D is incorrect because it would use the DEPLOYMENT_GROUP_ID environment variable. However, this variable is not automatically set by CodeDeploy, so the script would need to call the metadata service or the EC2 API to get the deployment group ID. This would add complexity and overhead to the solution.
NEW QUESTION # 168
A DevOps engineer notices that all Amazon EC2 instances running behind an Application Load Balancer in an Auto Scaling group are failing to respond to user requests. The EC2 instances are also failing target group HTTP health checks Upon inspection, the engineer notices the application process was not running in any EC2 instances. There are a significant number of out of memory messages in the system logs. The engineer needs to improve the resilience of the application to cope with a potential application memory leak. Monitoring and notifications should be enabled to alert when there is an issue Which combination of actions will meet these requirements? (Select TWO.)
Answer: D,E
Explanation:
Explanation
https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/metrics-collected-by-CloudWatch-agent.htm
NEW QUESTION # 169
......
Examcollection DOP-C02 Free Dumps: https://www.dumptorrent.com/DOP-C02-braindumps-torrent.html
BONUS!!! Download part of DumpTorrent DOP-C02 dumps for free: https://drive.google.com/open?id=1TXlz29zGUtCu1N6UIBol3AklAlMEB0oA