Wenn Sie finden, dass es ein Abenteur ist, sich mit den Prüfungsmaterialien zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von ZertSoft auf die Prüfung vorzubereiten. Das ganze Leben ist ein Abenteur. Diejenigen, die am weitesten gehen, sind meistens diejenigen, die Risiko tragen können. Die Prüfungsmaterialien zur Databricks Certified-Data-Engineer-Professional Prüfung von ZertSoft werden von den Kandidaten durch Praxis bewährt. ZertSoft hat den Kandidaten Erfolg gebracht. Es ist wichtig, Traum und Hoffnung zu haben. Am wichtigsten ist es, den Fuß auf den Boden zu setzen. Wenn Sie ZertSoft wählen, können Sie sicher Erfolg erlangen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 2: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 3: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 4: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 5: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 6: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 7: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 8: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 9: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
>> Certified-Data-Engineer-Professional Testking <<
Wenn Sie sich für die Schulungsprogramme zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung interessieren, können Sie im Internet teilweise die Demo zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung kostenlos als Probe herunterladen. Wir werden den Kunden einen einjährigen kostenlosen Update-Service bieten.
246. Frage
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.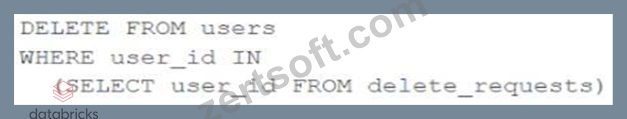
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Antwort: C
Begründung:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
247. Frage
A security analytics pipeline must enrich billions of raw connection logs with geolocation data.
The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events ( 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges ( 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
Antwort: C
Begründung:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute- force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
248. Frage
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
Antwort: A
Begründung:
In the Spark UI, the Stage's detail screen provides key metrics about each stage of a job, including the amount of data that has been spilled to disk. If you see a high number in the "Spill (Memory)" or "Spill (Disk)" columns, it's an indication that a partition is spilling to disk.
The Executor's log files can also provide valuable information about spill. If a task is spilling a lot of data, you'll see messages in the logs like "Spilling UnsafeExternalSorter to disk" or "Task memory spill". These messages indicate that the task ran out of memory and had to spill data to disk.
249. Frage
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed: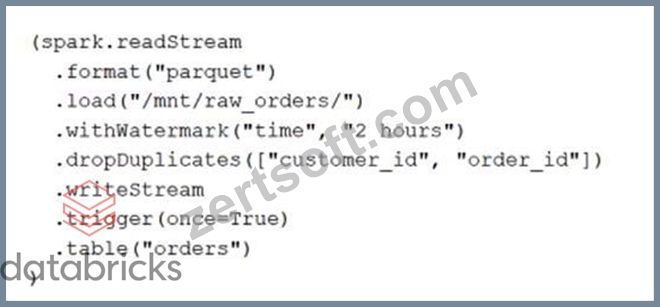
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Antwort: D
250. Frage
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?
Antwort: A
Begründung:
https://docs.databricks.com/en/clusters/cluster-config-best-practices.html
251. Frage
......
Machen Sie sich noch Sorgen um die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung? Warten Sie noch mühlos auf die neuesten Materialien zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung? ZertSoft hat neulich die neuesten Materialien zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung bearbeitet. Wollen Sie die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung bestehen? Bitte schicken Sie doch schnell die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung in den Warenkorb! Sie können kostenlos die Demo auf der Website ZertSoft.de herunterladen, um unsere Zuverlässigkeit zu bestätigen. Wir versprechen, dass wir Ihnen die gesammte Summe zurückerstatten werden, falls Sie mit unseren Prüfungsmaterialien in der Databricks Certified-Data-Engineer-Professional (Databricks Certified Data Engineer Professional) Zertifizierungsprüfung durchfallen.
Certified-Data-Engineer-Professional Fragenkatalog: https://www.zertsoft.com/Certified-Data-Engineer-Professional-pruefungsfragen.html