P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by 2Pass4sure: https://drive.google.com/open?id=1HfjvBtQ-De4juS4ZlGhj9as7ijgGLeEv
We guarantee that if you study our AI-300 guide dumps with dedication and enthusiasm step by step, you will desperately pass the exam without doubt. As the authoritative provider of AI-300 study materials, our pass rate is unmarched high as 98% to 100%. And we are always in pursuit of high pass rate of AI-300 practice quiz compared with our counterparts to gain more attention from potential customers.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement an MLOps infrastructure | - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Set up Azure Machine Learning workspace and compute targets |
| Topic 2: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning |
| Topic 3: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Conduct red teaming, adversarial testing, and content filtering |
| Topic 4: Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Manage API keys, rate limits, and responsible AI guardrails - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Topic 5: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput |
For the recognition of skills and knowledge, more career opportunities, professional development, and higher salary potential, the Microsoft AI-300 certification exam is the proven way to achieve these tasks quickly. Overall, we can say that with the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam you can gain a competitive edge in your job search and advance your career in the tech industry.
NEW QUESTION # 140
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow.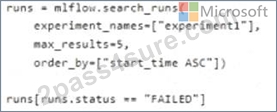
For each of the following statements, select Yes if the statement is true. Otherwise, select No.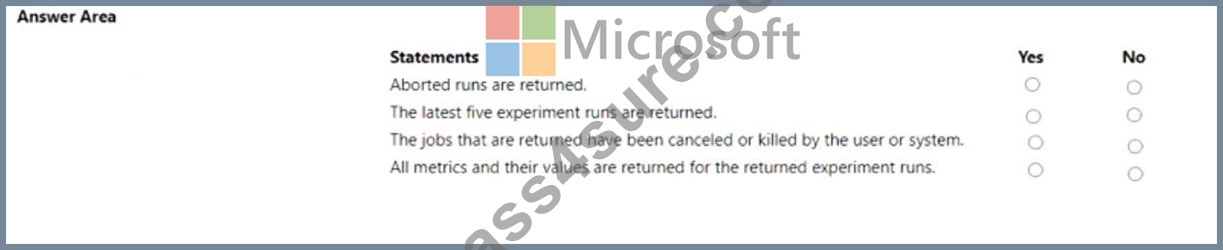
Answer:
Explanation: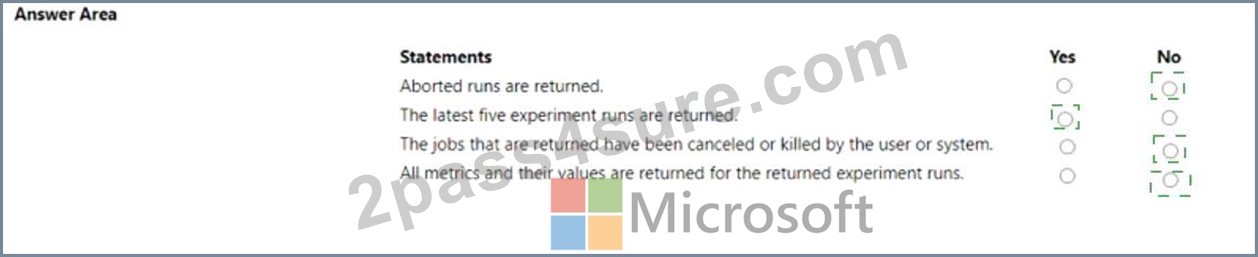
Explanation: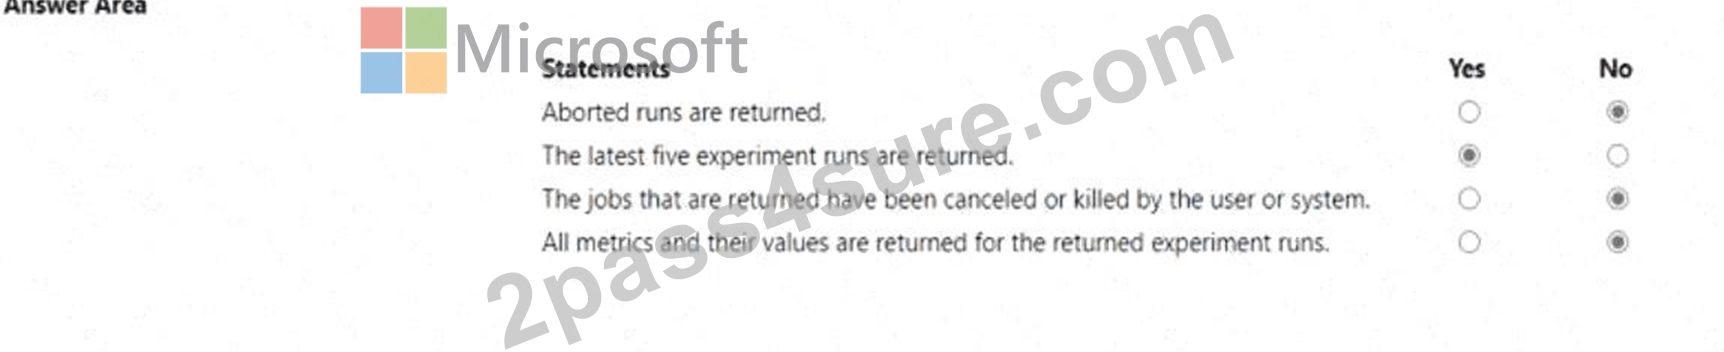
NEW QUESTION # 141
You are using Azure Machine Learning to monitor a trained and deployed model. You implement Event Grid to respond to Azure Machine Learning events.
Model performance has degraded due to model input data changes.
You need to trigger a remediation ML pipeline based on an Azure Machine Learning event.
Which event should you use?
Answer: A
NEW QUESTION # 142
A team is deploying machine learning models to a production inference endpoint in Azure Machine Learning.
The team requires a safe way to validate a new model version without disrupting existing users.
You need to recommend a deployment strategy for controlled testing of a new model version.
What should you configure?
Answer: D
Explanation:
A managed online endpoint can host multiple named deployments simultaneously, and you control what percentage of incoming traffic each deployment receives. With traffic splitting, you route a small percentage of live traffic to the new deployment while the majority continues to the proven existing model. You then monitor error rates, latency, and output quality for both deployments in real time under genuine production load. If the new model underperforms, you instantly route traffic back - no downtime, no user disruption. If it outperforms, you gradually increase its traffic share to 100%. Updating the registry version (option B) does not affect running deployments. A staging endpoint (option C) does not validate under real production load.
An evaluation script (option D) is a pre-deployment step. Traffic splitting is the blue/green and canary deployment pattern that Microsoft recommends for safe production rollouts.
Microsoft Learn Reference Topic: Perform safe rollout of new model deployments using traffic splitting - Azure Machine Learning
NEW QUESTION # 143
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend a solution to address Fabrikam Inc.'s limited rollback capability. Which deployment approach should you recommend?
Answer: A
Explanation:
Scenario:
Current Environment: Deployment is performed manually by data scientists, with limited rollback capability.
The correct deployment type to address this problem is Managed online endpoints with traffic splitting.
Native traffic control: Managed online endpoints naturally support native blue-green deployments under a single HTTP endpoint.
Granular traffic splitting: You can deploy a new model version (e.g., green) with 0% live traffic, safely test it, and then incrementally shift traffic from the old version (e.g., blue).Instant rollbacks:
If the new model shows bugs or degrades performance, you can immediately change the traffic percentage configuration back to 100% for the old deployment. This eliminates the risks of limited rollback capabilities.
No infrastructure overhead: Unlike setting up manual routing, Azure handles the underlying infrastructure and routing mechanisms in a turnkey fashion.
Incorrect:
[Not A]
VM-hosted REST APIs: This forces you to build, maintain, and configure your own custom load balancers and deployment scripts to handle routing and rollbacks, which increases operational risk and complexity.
[Not B]
Azure Kubernetes Service with blue-green switching: While it supports blue-green deployments, it requires you to manage complex Kubernetes infrastructure, service meshes, or ingress controllers manually to handle the traffic switching.
[Not D]
Batch endpoints: These are designed for long-running, asynchronous processing of large data batches rather than real-time requests where instant live-traffic rollback is required.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-safely-rollout-online-endpoints
NEW QUESTION # 144
-
A biomedical research company plans to enroll people in an experimental medical treatment trial.
You create and train a binary classification model to support selection and admission of patients to the trial.
The model includes the following features: Age, Gender, and Ethnicity.
The model returns different performance metrics for people from different ethnic groups.
You need to use Fairlearn to mitigate and minimize disparities for each category in the Ethnicity feature.
Which technique and constraint should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.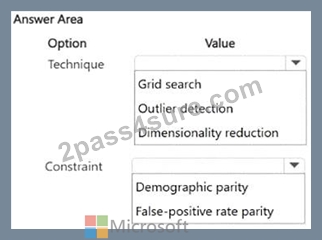
Answer:
Explanation: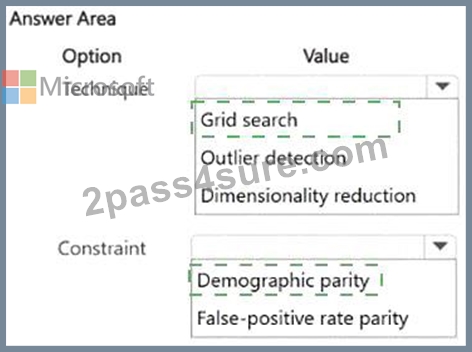
Explanation:
Technique: Grid search
Constraint: Demographic parity
The appropriate mitigation technique is GridSearch with a DemographicParity constraint. Fairlearn provides reduction-based mitigation algorithms that retrain a standard estimator using differently weighted training data while enforcing a specified fairness constraint. GridSearch is one of Fairlearn ' s reduction algorithms for binary classification and can search across candidate models representing different trade-offs between predictive performance and fairness.
The appropriate constraint is Demographic parity because the model determines whether individuals receive an opportunity-in this case, selection and admission to a medical trial . Microsoft categorizes decisions that extend or withhold opportunities or resources as allocation harms and specifically identifies demographic parity as a parity constraint intended to mitigate allocation disparities in binary classification.
Demographic parity seeks comparable rates of positive predictions across groups defined by the sensitive attribute. Here, Ethnicity is the sensitive feature, so the objective is to reduce disparities in selection rates between ethnic groups.
False-positive-rate parity has a different purpose: it specifically requires comparable false-positive rates across groups among cases whose true label is negative. The scenario does not identify unequal false-positive rates as the problem.
NEW QUESTION # 145
......
Although a lot of products are cheap, but the quality is poor, perhaps users have the same concern for our latest AI-300 exam preparation materials. Here, we solemnly promise to users that our AI-300 exam questions error rate is zero. Everything that appears in our products has been inspected by experts. In our AI-300 practice materials, users will not even find a small error, such as spelling errors or grammatical errors. It is believed that no one is willing to buy defective products, so, the AI-300 study guide has established a strict quality control system.
Reliable AI-300 Test Question: https://www.2pass4sure.com/Microsoft-Certified/AI-300-actual-exam-braindumps.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by 2Pass4sure: https://drive.google.com/open?id=1HfjvBtQ-De4juS4ZlGhj9as7ijgGLeEv