P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by ValidExam: https://drive.google.com/open?id=11KrRE0KXPqTVpK4ra2o4ZapCZC8J-KnO
The ValidExam team regularly updates the Databricks-Certified-Professional-Data-Engineer exam pdf format to make sure that applicants receive the most up-to-date Databricks Databricks-Certified-Professional-Data-Engineer exam questions. Additionally, our Databricks-Certified-Professional-Data-Engineer PDF is designed to be user-friendly and accessible on any smart device, which means that students can prepare for the Databricks-Certified-Professional-Data-Engineer from anywhere, at any time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Topic 2: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 3: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 4: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Topic 5: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Topic 6: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Topic 7: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Topic 8: Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Topic 9: Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
| Topic 10: Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
>> Databricks-Certified-Professional-Data-Engineer Valid Test Objectives <<
Rely on ValidExam’s easy Databricks-Certified-Professional-Data-Engineer Questions Answers that can give you first time success with 100% money back guarantee! Thousands of professional have already been benefited with the marvelous Databricks-Certified-Professional-Data-Engineer and have obtained their dream certification. There is no complication involved; the exam questions and answers are simple and rewarding for every candidate. ValidExam’s experts have employed their best efforts in creating the questions and answers; hence they are packed with the relevant and the most updated information you are looking for.
NEW QUESTION # 51
A data team is automating a daily multi-task ETL pipeline in Databricks. The pipeline includes a notebook for ingesting raw data, a Python wheel task for data transformation, and a SQL query to update aggregates. They want to trigger the pipeline programmatically and see previous runs in the GUI. They need to ensure tasks are retried on failure and stakeholders are notified by email if any task fails.
Which two approaches will meet these requirements? (Choose 2 answers)
Answer: C,D
Explanation:
Databricks Jobs supports defining multi-task workflows that include notebooks, SQL statements, and Python wheel tasks. These can be configured with retry policies, dependency chains, and failure notifications. The correct practice, as stated in the documentation, is to use the Jobs REST API (/jobs/create) or Databricks Asset Bundles to define multi-task jobs, and then trigger them programmatically using /jobs/run-now, CLI, or SDK. This allows the team to maintain full job history, handle retries automatically, and receive alerts via configured email notifications. Using /jobs/runs/submit creates one-off ad hoc runs without maintaining dependency visibility. Therefore, options B and C together satisfy the operational, automation, and governance requirements.
NEW QUESTION # 52
How to determine if a table is a managed table vs external table?
Answer: A
Explanation:
Explanation
The answer is Run SQL command DESCRIBE EXTENDED table_name and check type Example of External table Graphical user interface, text, application Description automatically generated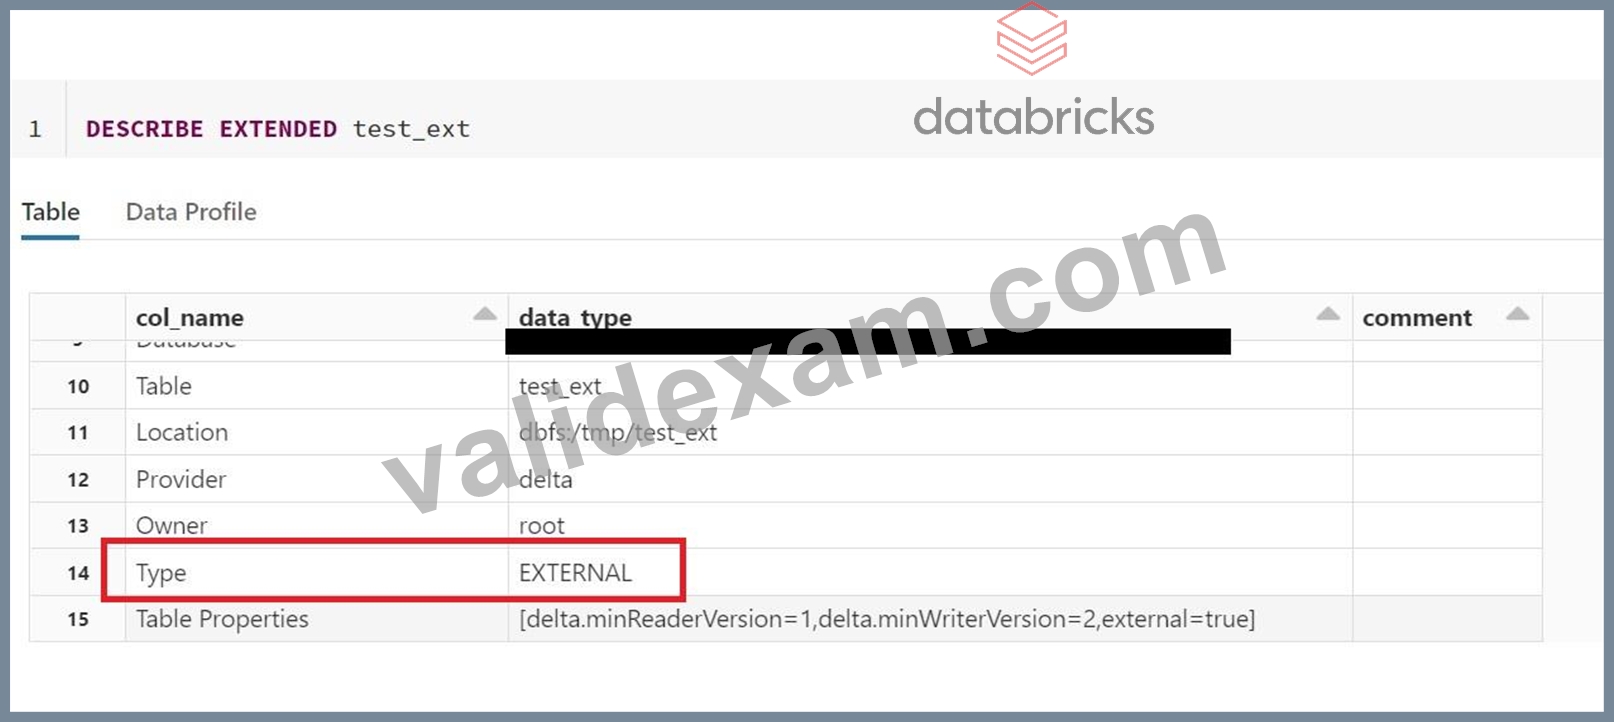
Example of managed table
Graphical user interface, text, application, Teams Description automatically generated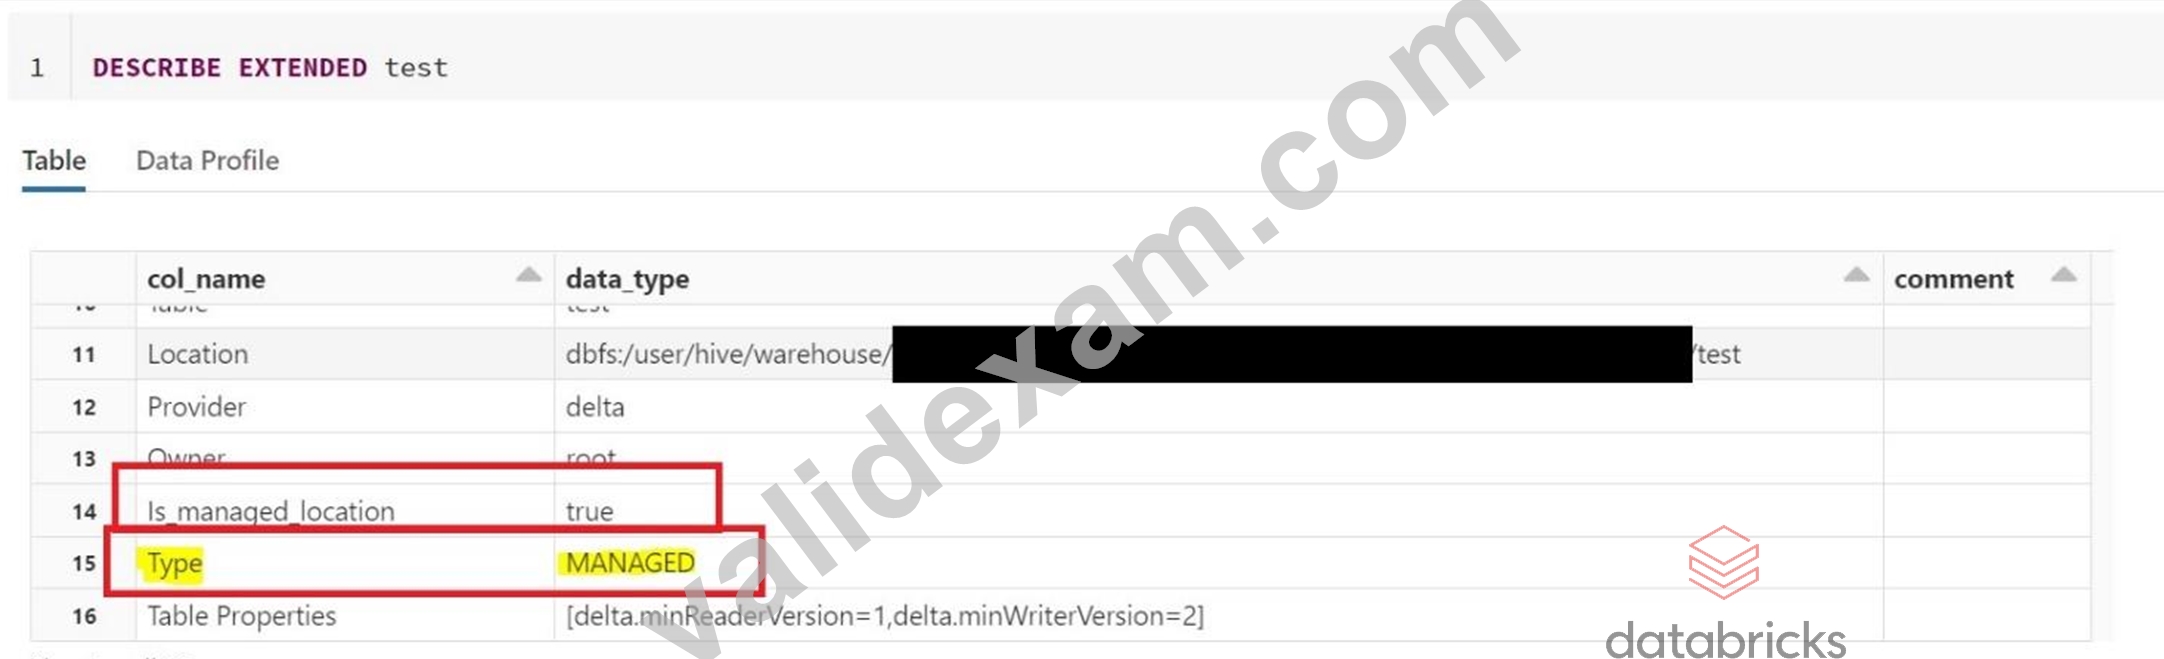
NEW QUESTION # 53
You are looking to process the data based on two variables, one to check if the department is supply chain and second to check if process flag is set to True
Answer: D
NEW QUESTION # 54
Which method can be used to determine the total wall-clock time it took to execute a query?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Query Profiler in Databricks SQL and notebooks provides a detailed breakdown of query performance metrics. The "Total wall-clock duration" metric directly represents the total elapsed time from query start to completion, including all execution, planning, and waiting stages. In contrast, "Aggregated task time" reflects the cumulative duration across all parallel tasks, which does not equal the total elapsed wall time since tasks often run concurrently. Using job duration from Spark UI can underestimate or overestimate runtime when queries span multiple jobs. Therefore, the Query Profiler's total wall-clock duration is the officially documented method to determine actual query execution time.
NEW QUESTION # 55
You had worked with the Data analysts team to set up a SQL Endpoint(SQL warehouse) point so they can easily query and analyze data in the gold layer, but once they started consuming the SQL Endpoint(SQL warehouse) you noticed that during the peak hours as the number of users increase you are seeing queries taking longer to finish, which of the following steps can be taken to resolve the issue?
*Please note Databricks recently renamed SQL endpoint to SQL warehouse.
Answer: B
Explanation:
Explanation
the answer is,
They can increase the maximum bound of the SQL endpoint's scaling range, when you increase the maximum bound you can add more clusters to the warehouse which can then run additional queries that are waiting in the queue to run, focus on the below explanation that talks about Scale-out.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: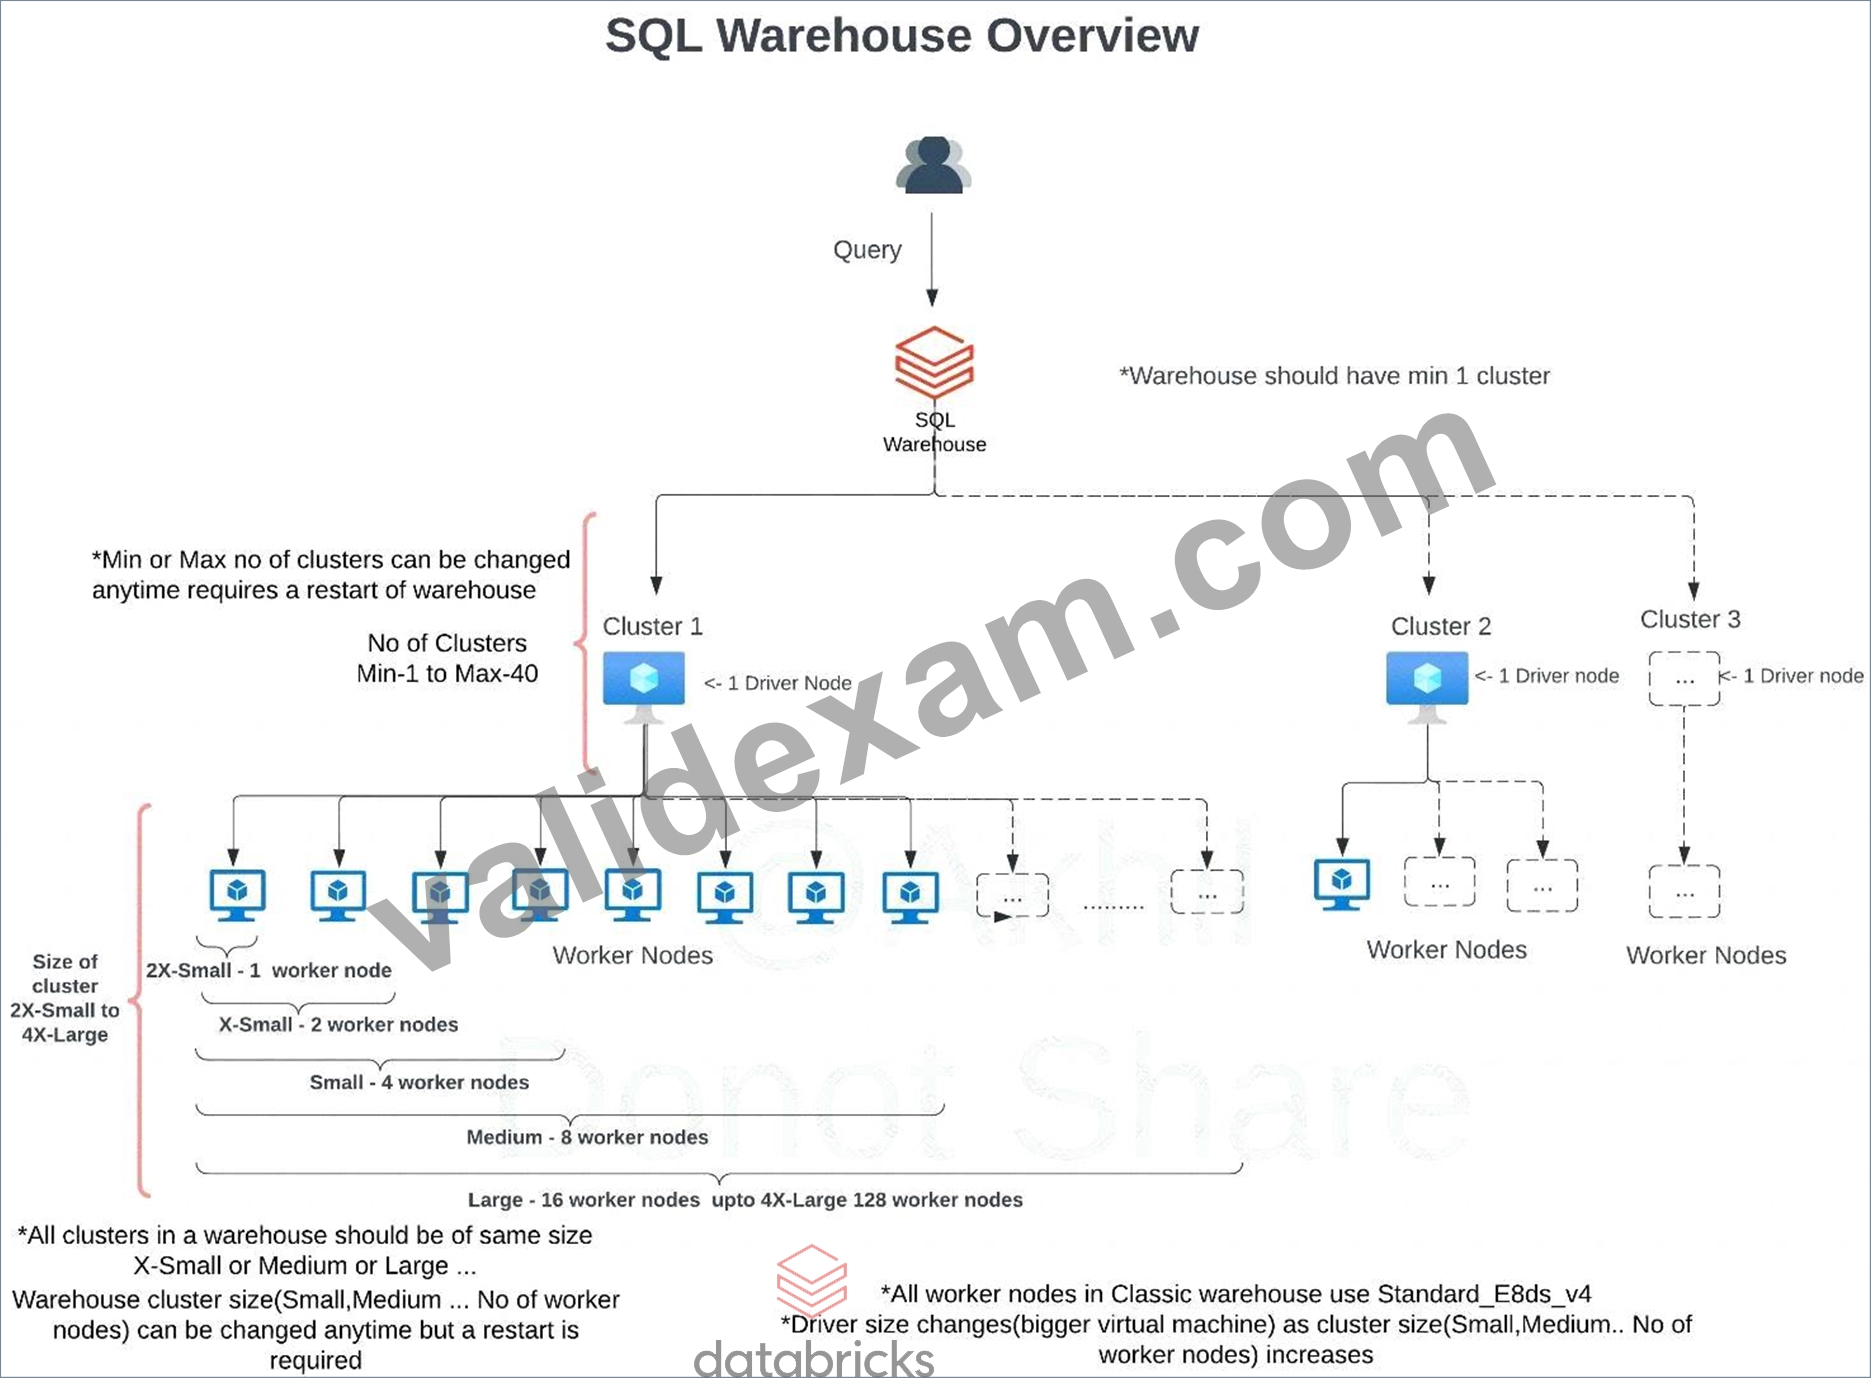
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.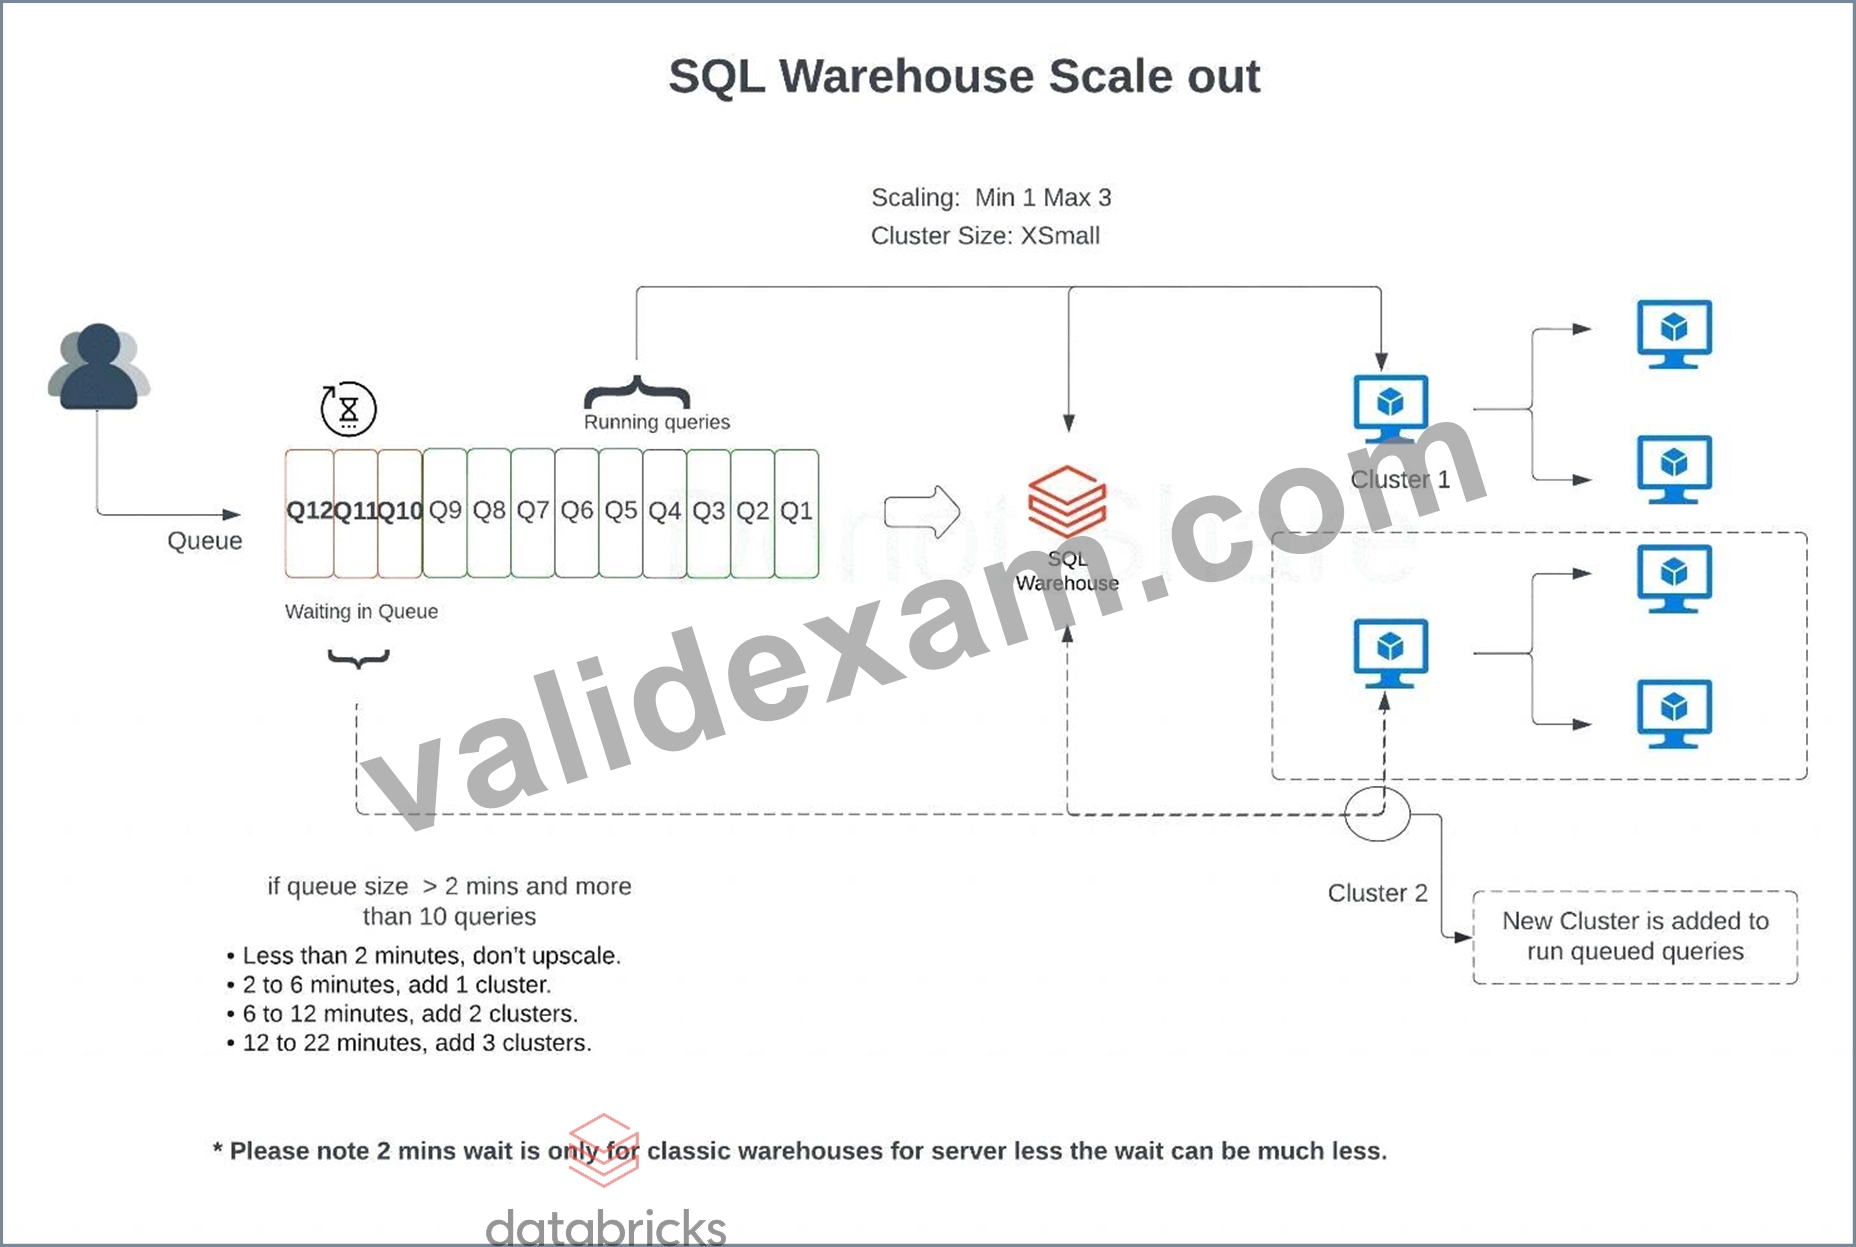
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.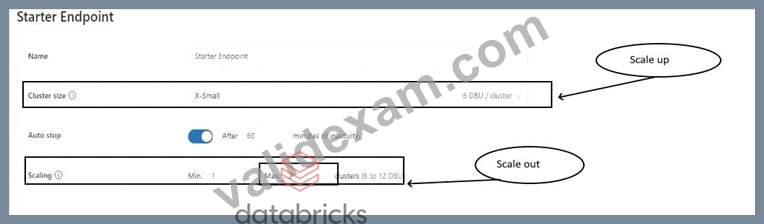
How do you know how many clusters you need(How to set Max cluster size)?
When you click on an existing warehouse and select the monitoring tab, you can see warehouse utilization information(see below), there are two graphs that provide important information on how the warehouse is being utilized, if you see queries are being queued that means your warehouse can benefit from additional clusters. Please review the additional DBU cost associated with adding clusters so you can take a well balanced decision between cost and performance.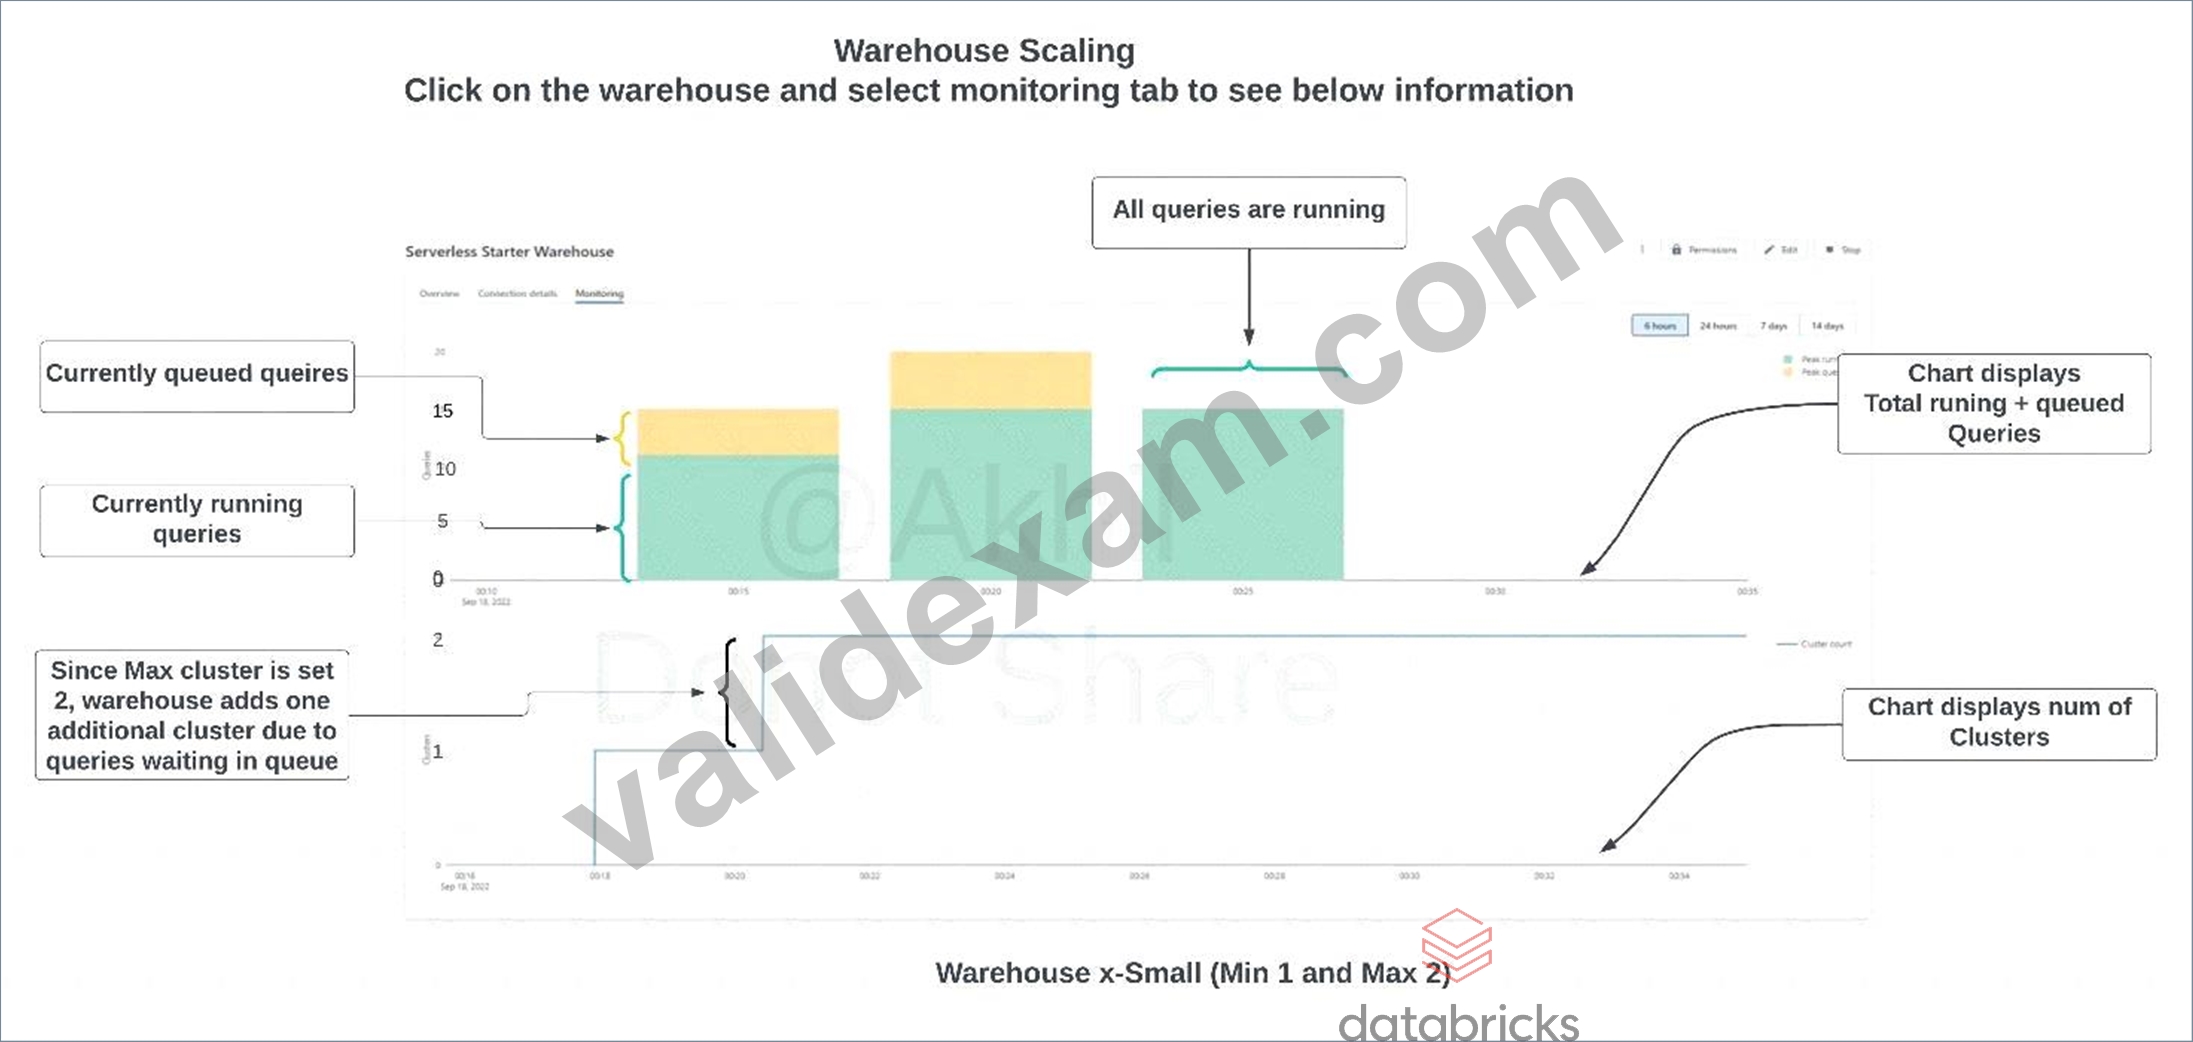
NEW QUESTION # 56
......
After we develop a new version, we will promptly notify you. At Databricks-Certified-Professional-Data-Engineer, you have access to the best resources in the industry. We guarantee that you absolutely don't need to spend extra money to buy other products. Databricks-Certified-Professional-Data-Engineer practice materials will definitely make you feel value for money. If you are really in doubt, you can use our trial version of our Databricks-Certified-Professional-Data-Engineer Exam Questions first. We believe that you will definitely make a decision immediately after use!
Databricks-Certified-Professional-Data-Engineer Reliable Dumps Ppt: https://www.validexam.com/Databricks-Certified-Professional-Data-Engineer-latest-dumps.html
What's more, part of that ValidExam Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=11KrRE0KXPqTVpK4ra2o4ZapCZC8J-KnO