P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by Pass4guide: https://drive.google.com/open?id=1DDu5NEFyXYKsQu7hV7fX7CU2Lb7lwXVD
Our DY0-001 practice questions are carfully compiled by our professional experts to be sold all over the world. So the content should be easy to be understood. The difficult questions of the DY0-001 exam materials will have vivid explanations. So you will have a better understanding after you carefully see the explanations. At the same time, our DY0-001 Real Exam just needs to cost you a few spare time. After about twenty to thirty hours’ practice, you can completely master all knowledge.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Certificate Validity Period: | 3 years |
| Available Languages: | Japanese, English |
| Exam Format: | Performance-Based Questions (PBQs), Multiple Choice |
| Exam Duration: | 165 minutes |
| Related Certifications: | CompTIA AI Essentials CompTIA Data+ |
| Exam Price: | $544 USD |
| Real Exam Qty: | Up to 90 |
| Passing Score: | Pass/Fail (no numerical score) |
| Recommended Training: | CompTIA CertMaster Learn for DataAI CompTIA Official Study Guide |
| Exam Registration: | Pearson VUE Scheduling CompTIA Official Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Online proctored or in-person at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended 5+ years of experience in data science, analytics, or related fields |
| Official Syllabus URL: | https://www.comptia.org/certifications/dataai |
>> Latest DY0-001 Mock Exam <<
For CompTIA DY0-001 certification test, are you ready? The exam comes in sight, but can you take the test with confidence? If you have not confidence to sail through your exam, here I will recommend the most excellent reference materials for you. The latest DY0-001 Certification Training dumps that can pass your exam in a short period of studying have appeared. The dumps are provided by Pass4guide.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 64
The most likely concern with a one-feature, machine-learning model is high error due to:
Answer: C
Explanation:
# A one-feature model is likely to be overly simplistic and may not capture the true complexity of the target variable. This leads to underfitting, which is associated with high bias - the model consistently misses the mark regardless of the data.
Why the other options are incorrect:
* B: High dimensionality is not a concern in this case - the model has too few features.
* C: Variance refers to overfitting - more common in overly complex models.
* D: Probability is a modeling technique, not a source of error.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"Models with insufficient features tend to underfit and exhibit high bias due to their inability to represent complex relationships."
* Bias-Variance Tradeoff - Data Science Textbook:"A high-bias model makes strong assumptions and is typically too simple to capture the underlying patterns in data."
NEW QUESTION # 65
Which of the following distributions would be best to use for hypothesis testing on a data set with 20 observations?
Answer: B
Explanation:
With only 20 observations and an unknown population variance, the t-distribution (with 𝑛 - 1 degrees of freedom) properly accounts for the extra uncertainty in the standard error when performing hypothesis tests.
NEW QUESTION # 66
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are shown.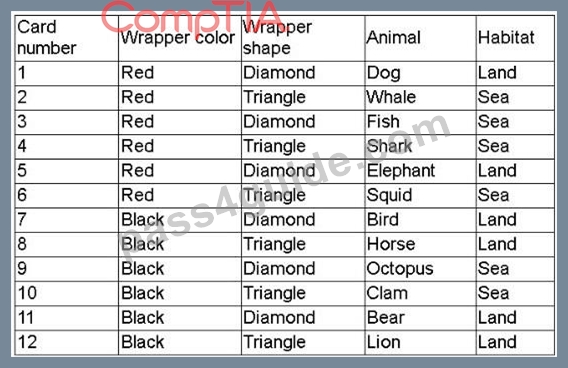
The data scientist is tasked with designing an initial model iteration to predict whether the animal on the card lives in the sea or on land, given the card's features: Wrapper color, Wrapper shape, and Animal.
Which of the following is the best way to accomplish this task?
Answer: B
Explanation:
# Decision trees are supervised classification models that can be used to predict a categorical target variable (e.
g., Habitat: Land or Sea) based on input features (e.g., Wrapper color, Wrapper shape, Animal type). They are interpretable, require minimal preprocessing, and are ideal for structured categorical data like this.
Why the other options are incorrect:
* A: ARIMA (AutoRegressive Integrated Moving Average) is used for time-series forecasting, not classification.
* B: Linear regression is used for predicting continuous numeric values, not categorical variables like
"Land" or "Sea".
* C: Association rules (like in market basket analysis) are used to discover relationships or co-occurrence among variables, not to build predictive models.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1 & 4.2:"Decision trees are powerful classifiers for categorical output variables and allow for interpretable models based on feature splits."
* Machine Learning Textbook, Chapter 6:"Decision trees are ideal for early-stage model prototyping when the output is categorical and the data structure is tabular."
NEW QUESTION # 67
A model's results show increasing explanatory value as additional independent variables are added to the model. Which of the following is the most appropriate statistic?
Answer: C
Explanation:
Adjusted R² accounts for the number of predictors in the model, only increasing when a new independent variable adds genuine explanatory power beyond what random chance would predict. In contrast, plain R² will always rise (or stay the same) as you add more variables, regardless of their true relevance.
NEW QUESTION # 68
A data scientist is building an inferential model with a single predictor variable. A scatter plot of the independent variable against the real-number dependent variable shows a strong relationship between them.
The predictor variable is normally distributed with very few outliers. Which of the following algorithms is the best fit for this model, given the data scientist wants the model to be easily interpreted?
Answer: B
Explanation:
The scenario provided describes a modeling problem with the following characteristics:
* A single continuous predictor variable (independent variable).
* A continuous real-number dependent variable.
* The relationship between the variables appears strong and linear, as observed from the scatter plot.
* The predictor variable is normally distributed with minimal outliers.
* The goal is to maintain interpretability in the model.
Based on the above, the most appropriate modeling technique is:
Linear Regression: This is a statistical method used to model the linear relationship between a continuous dependent variable and one or more independent variables. In simple linear regression, a straight line (y = mx
+ b) represents the relationship, where the slope and intercept can be easily interpreted. This method is preferred when the relationship is linear, the assumptions of normality and homoscedasticity are satisfied, and interpretability is required.
Why the other options are incorrect:
* A. Logistic Regression: This is used when the dependent variable is categorical (e.g., binary classification), not continuous. Therefore, not suitable for this case.
* B. Exponential Regression: Applied when the data shows an exponential growth or decay pattern, which is not implied here.
* D. Probit Regression: Similar to logistic regression but based on a normal cumulative distribution.
Used for categorical outcomes, not continuous variables.
Exact Extract and Official References:
* CompTIA DataX (DY0-001) Official Study Guide, Domain: Modeling, Analysis, and Outcomes:
"Linear regression is the most interpretable form of regression modeling. It assumes a linear relationship between independent and dependent variables and is ideal for inferential modeling when interpretability is important." (Section 3.1, Model Selection Criteria)
* Data Science Fundamentals, by CompTIA and DS Institute:
"Linear regression is a robust and interpretable statistical method used for modeling continuous outcomes. It provides coefficients which help in understanding the strength and direction of the relationship." (Chapter 4, Regression Techniques)
NEW QUESTION # 69
......
Regualer DY0-001 Update: https://www.pass4guide.com/DY0-001-exam-guide-torrent.html
2026 Latest Pass4guide DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1DDu5NEFyXYKsQu7hV7fX7CU2Lb7lwXVD