2026 Latest Actual4Labs SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1AMKVupXyl19wpDuUv7rC9qIn1kFd5O_c
There are Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions provided in Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF questions format which can be viewed on smartphones, laptops, and tablets. So, you can easily study and prepare for your Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam anywhere and anytime. You can also take a printout of these Snowflake PDF Questions for off-screen study.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Transformations vs. Actions - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Client-side vs. Server-side execution - Stored procedures and conditional logic |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Complex data pipelines - Using built-in functions - Window functions - Filtering, Aggregating, and Joining DataFrames |
| Topic 3: Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Debugging and explain plans - Caching strategies - Vectorized UDFs - Warehouse sizing for Snowpark - Query pushdown and optimization |
| Topic 4: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management - Reading and writing data - DataFrame creation and manipulation |
Most returned customers said that our SPS-C01 dumps pdf covers the big part of main content of the certification exam. Questions and answers from our SPS-C01 free download files are tested by our certified professionals and the accuracy of our questions are 100% guaranteed. Please check the free demo of SPS-C01 Braindumps before purchased and we will send you the download link of SPS-C01 real dumps after payment.
NEW QUESTION # 210
You have a Snowpark Python application that performs several data transformations. You need to implement error handling to catch exceptions during DataFrame operations and log them to a Snowflake table named 'error _ log'. You also need to ensure that if any exception occurs, the application continues to run and processes the remaining data. Which of the following approaches (or combination of approaches) would be MOST suitable?
Answer: A,C
Explanation:
Options B and C, when combined, provide the most robust error handling. Wrapping individual DataFrame operations in try-except blocks (B) allows you to catch specific exceptions and log them appropriately, preventing a single error from crashing the entire application. Implementing a UDF with error handling (C) encapsulates complex logic and allows you to return both processed data and error messages, making it easier to identify and address issues. A global try-except block (A) might catch errors, but it doesn't provide granular control or context. Relying solely on Snowflake's built-in mechanisms (D) is insufficient for custom error logging and continuing execution. While a Snowpark logging API (E) would be ideal, such an API doesn't currently exist and relies on an assumption.
NEW QUESTION # 211
You're working with Snowpark and have a DataFrame 'df containing a column 'json_data' with JSON strings. Some of these JSON strings are invalid. You need to parse the valid JSON strings and extract a field named 'product_id' from them. Invalid JSON strings should result in a 'NULL' value for the extracted 'product_id'. Which of the following approaches is the MOST robust and efficient way to achieve this?





Answer: D
Explanation:
Option B is the most robust and efficient. handles invalid JSON strings gracefully by returning 'NULL'. The other options have drawbacks: Option A will throw an error if the JSON is invalid. Option C involves a UDF, which can be slower than built-in functions. Option D assumes valid json and uses the native notation which will error with invalid JSON data. Option E uses Regex which is not recommended and can have perfomance impact as well as not robust
NEW QUESTION # 212
You have a complex Snowpark Python UDF that aggregates data from various sources and returns a dictionary containing several metrics (e.g., '{'average price': 12.50, 'total sales': 1000, 'customer count': 50}'). You need to operationalize this UDF and ensure proper data type handling for each metric. Which of the following is the MOST appropriate way to define the return type using the registration API?
Answer: A
Explanation:
Using a 'StructType' with 'StructField' for each metric is the most appropriate way to define the return type. This allows you to explicitly define the data type for each metric (e.g., 'FloatType' for 'average_price', 'Integer Type' for 'customer_count'), ensuring type safety and efficient data processing. 'VariantType' (Option A) would store the dictionary as a semi-structured data type, but you'd lose the benefits of explicit type definitions for each metric. 'MapType' (Option B) is more appropriate for representing a map with keys and values, not a fixed set of named metrics. Serializing to JSON (Option D) adds overhead and loses type information. 'ArrayType' (Option E) is not suitable for dictionaries. 'StructType' enforces a schema upon the returned data.
NEW QUESTION # 213
You have a Snowpark DataFrame 'df representing sales data with columns 'product_id', 'region', and 'sales_amount'. You want to calculate the total sales amount for each region. Which of the following Snowpark code snippets is the MOST efficient and correct way to achieve this?



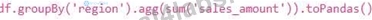

Answer: B
Explanation:
Option D is the most efficient and correct. 'df.groupBy('region')' groups the data by the 'region' column. agg(sum(col('sales_amount')).alias('total_sales'))' calculates the sum of the 'sales_amount' column for each region and aliases the result as 'total_sales'. Using explicitly is the recommended Snowpark practice. 'collect()' brings the entire result set to the client, which can be inefficient for large datasets. Using 'toPandas(Y works but defeats the purpose of Snowpark since it pulls all the data to the client before aggregation happens. Option C is syntactically incorrect as .alias(V is used incorrectly after and doesn't chain together. Options A and B are less performant because they transfer the data to the client side. Option E also works, but it's better to use string column name as it is recommended best practice.
NEW QUESTION # 214
Consider a Snowpark DataFrame with columns 'DEPARTMENT, 'SALARY , and 'YEAR. You want to find the average salary for each department over all years and then filter the departments to only include those where the average salary is greater than 100000. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





Answer: B
Explanation:
Options A, B, C, and D are technically valid but use 'avg' or 'col' instead of the recommended 'sf.mean' and 'sf.cor for Snowpark. Option E, is most efficient as it leverages Snowpark's functions ('sf.mean' and 'sf.col') correctly and splits the operation in two steps for clarity and potential optimization. 'col' can be used, 'sf.col' is the recommended way.
NEW QUESTION # 215
......
The SPS-C01 exam question offer a variety of learning modes for users to choose from, which can be used for multiple clients of computers and mobile phones to study online, as well as to print and print data for offline consolidation. For any candidate, choosing the SPS-C01 question torrent material is the key to passing the exam. Our study materials can fully meet all your needs: Avoid wasting your time and improve your learning efficiency. Spending little hours per day within one week, you can pass the exam easily. You will don't take any risks and losses if you purchase and learn our SPS-C01 Latest Exam Dumps, do you?
SPS-C01 Demo Test: https://www.actual4labs.com/Snowflake/SPS-C01-actual-exam-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Actual4Labs: https://drive.google.com/open?id=1AMKVupXyl19wpDuUv7rC9qIn1kFd5O_c