Certified-Data-Engineer-Professional Certified - Certified-Data-Engineer-Professional Download Fee

DOWNLOAD the newest PassLeader Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1IVqK-LCGNoyCMqnggaoIZrAtN7OdDNeB
If you're looking to advance your career, passing the Databricks Certified-Data-Engineer-Professional Certification Exam is crucial. As with any certification exam, success requires time and effort. While there are many online study materials available, not all of them are accurate or reliable. Many professionals struggle with managing their time and studying effectively, making it difficult to pass the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) Exam.
| Section | Objectives |
|---|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Compare streaming tables and materialized views
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Use control flow operators in pipeline components
- 6. Develop unit and integration tests for data processing code
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
|
>> Certified-Data-Engineer-Professional Certified <<
Certified-Data-Engineer-Professional Download Fee & New Certified-Data-Engineer-Professional Test Sample
One such trustworthy point about exam preparation material is that it first gains your trust, and then asks you to purchase it. Everyone can get help from PassLeader's free demo of Databricks Certified-Data-Engineer-Professional exam questions. Our Databricks Certified Data Engineer Professional exam questions never remain outdated! Take a look at our Free Databricks Certified-Data-Engineer-Professional Exam Questions And Answers to check how perfect they are for your exam preparation. Once you buy it, you will be able to get free updates for Databricks Certified Data Engineer Professional exam questions for up to 1 year.
Databricks Certified Data Engineer Professional Sample Questions (Q170-Q175):
NEW QUESTION # 170
Review the following error traceback:
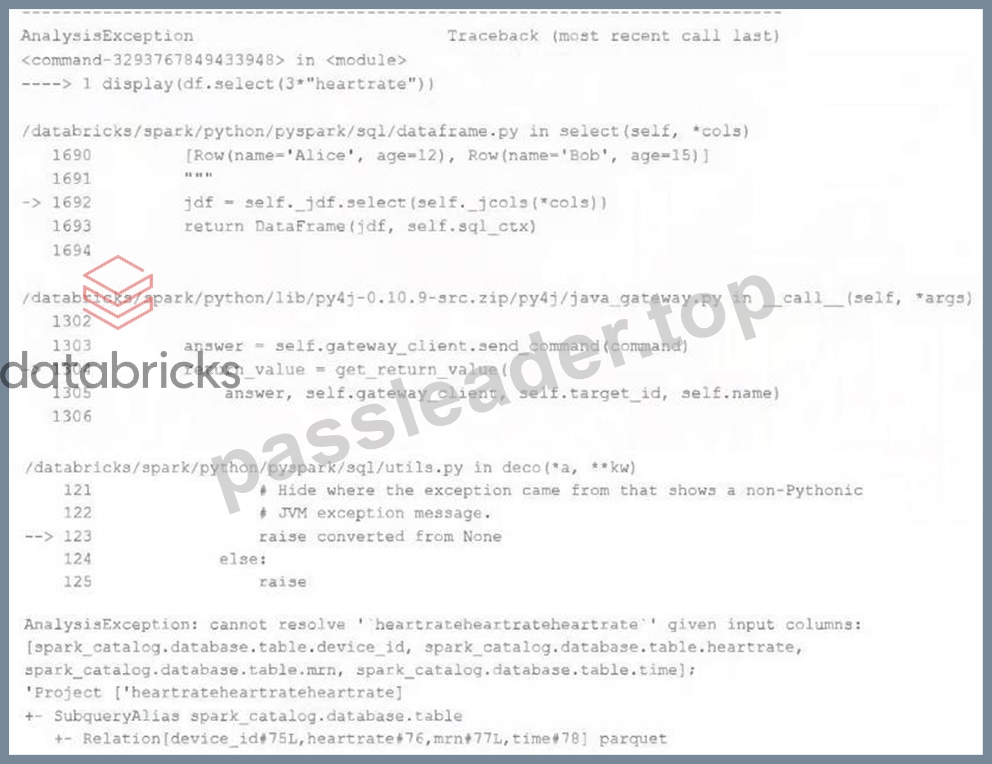
Which statement describes the error being raised?
- A. There is no column in the table named heartrateheartrateheartrate
- B. The code executed was PvSoark but was executed in a Scala notebook.
- C. There is a type error because a DataFrame object cannot be multiplied.
- D. There is a type error because a column object cannot be multiplied.
- E. There is a syntax error because the heartrate column is not correctly identified as a column.
Answer: A
Explanation:
https://sparkbyexamples.com/spark/spark-cannot-resolve-given-input-columns/
NEW QUESTION # 171
A platform team lead is responsible for automating the individual teams attribution towards SQL Warehouse usage. The requirement is to identify the SQL warehouse usage at the individual user's level and generate a daily report to be shared with an executive team that includes leaders from all business units. How should the platform lead generate an automated report that can be shared daily?
- A. Let the users run the SQL query and then directly report the usage to the executives. The ownership of the SQL warehouse usage will be with the individual teams.
- B. Use the system tables to capture the audit and billing usage data and create a dashboard with daily refresh schedules and shared with the executive team.
- C. Restrict users from running any SQL query unless they provide all the query details so that the attribution can be calculated and shared with the executive team.
- D. Use the system tables to capture the audit and billing usage data and share the queries with the executive team. This enables the executives to execute the query and see the latest results any time.
Answer: B
Explanation:
System tables provide authoritative audit and billing data needed for per-user SQL Warehouse attribution. Creating a dashboard with a scheduled daily refresh automates report generation and ensures executives receive consistent, up-to-date insights without needing to run queries themselves.
NEW QUESTION # 172
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
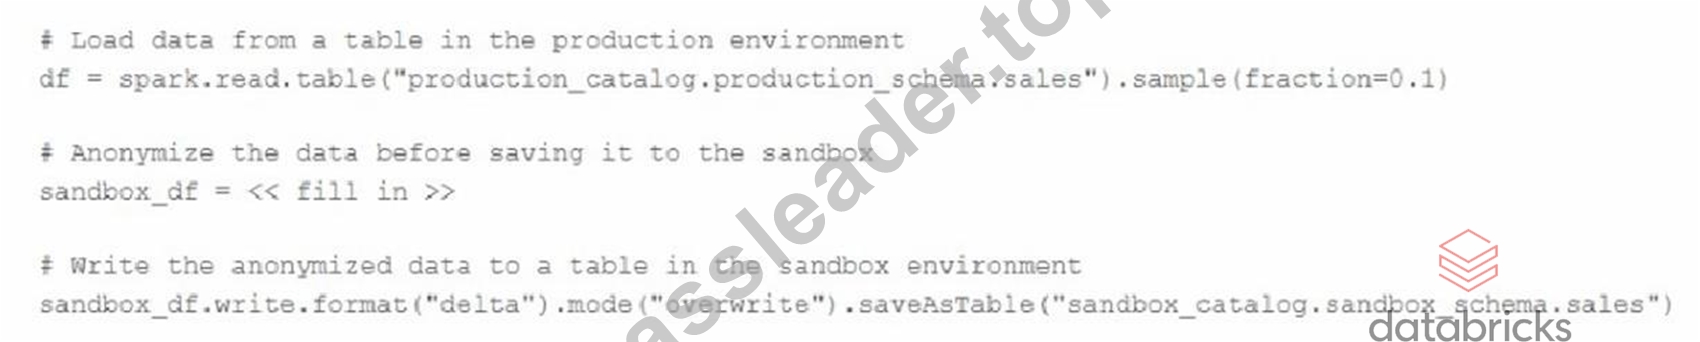
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("user_emai", F.expr("uuid()"))
- B. df.withColumn ("user_email", F.sha2 ("user_email"))
- C. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
- D. df.withColumn ("hashed_email", sha2 ("user_email"))
Answer: B
Explanation:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
NEW QUESTION # 173
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
- B. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- C. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
- D. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
Answer: C
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
NEW QUESTION # 174
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.adaptive.coalescePartitions.minPartitionNum
- B. spark.sql.files.maxPartitionBytes
- C. spark.sql.autoBroadcastJoinThreshold
- D. spark.sql.adaptive.advisoryPartitionSizeInBytes
- E. spark.sql.files.openCostInBytes
Answer: B
Explanation:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file- based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file.
NEW QUESTION # 175
......
Before you take the exam, you only need to spend 20 to 30 hours to practice, so you can schedule time to balance learning and other things. Of course, you care more about your passing rate. If you choose our Certified-Data-Engineer-Professional exam guide, under the guidance of our Certified-Data-Engineer-Professional exam torrent, we have the confidence to guarantee a passing rate of over 99%. Our Certified-Data-Engineer-Professional quiz prep is compiled by experts based on the latest changes in the teaching syllabus and theories and practices. So our Certified-Data-Engineer-Professional Quiz prep is quality-assured, focused, and has a high hit rate. The most important information is conveyed with the minimum number of questions, and you will not miss important knowledge. You can make full use of your usual piecemeal time to learn our Certified-Data-Engineer-Professional exam torrent. You will get the best results in the shortest time. Join our study and you will have the special experience.
Certified-Data-Engineer-Professional Download Fee: https://www.passleader.top/Databricks/Certified-Data-Engineer-Professional-exam-braindumps.html
- Valid Certified-Data-Engineer-Professional Test Objectives 😶 Certified-Data-Engineer-Professional Latest Study Guide 🐯 Certified-Data-Engineer-Professional Latest Examprep 💡 ▷ www.verifieddumps.com ◁ is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 😳Certified-Data-Engineer-Professional Real Exam
- Pdfvce Certified-Data-Engineer-Professional Web-Based Practice Tests Ⓜ The page for free download of ▷ Certified-Data-Engineer-Professional ◁ on ▛ www.pdfvce.com ▟ will open immediately 🔯Certified-Data-Engineer-Professional Accurate Test
- Certified-Data-Engineer-Professional Latest Exam Pdf 🦯 New Certified-Data-Engineer-Professional Exam Questions ✏ Free Certified-Data-Engineer-Professional Learning Cram 💘 Simply search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download on 《 www.troytecdumps.com 》 🎷Certified-Data-Engineer-Professional Valid Exam Materials
- 2026 Latest Certified-Data-Engineer-Professional Certified | Certified-Data-Engineer-Professional 100% Free Download Fee ☣ Search on ⏩ www.pdfvce.com ⏪ for ▷ Certified-Data-Engineer-Professional ◁ to obtain exam materials for free download 🎍Valid Certified-Data-Engineer-Professional Test Objectives
- Certified-Data-Engineer-Professional Latest Examprep 🧈 Exam Certified-Data-Engineer-Professional Tutorial 🌝 Certified-Data-Engineer-Professional Original Questions 🌎 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download exam materials for free through ⇛ www.testkingpass.com ⇚ ➡️Free Certified-Data-Engineer-Professional Learning Cram
- Certified-Data-Engineer-Professional New Braindumps Sheet 🔛 Certified-Data-Engineer-Professional Latest Test Cost ⚖ Exam Certified-Data-Engineer-Professional Tutorial 🍤 Search for 《 Certified-Data-Engineer-Professional 》 and obtain a free download on ⮆ www.pdfvce.com ⮄ ➡New Certified-Data-Engineer-Professional Test Blueprint
- Certified-Data-Engineer-Professional Real Exam 🍡 New Certified-Data-Engineer-Professional Test Blueprint 🥶 Free Certified-Data-Engineer-Professional Learning Cram ⭐ Search for [ Certified-Data-Engineer-Professional ] and easily obtain a free download on { www.dumpsquestion.com } 📎Certified-Data-Engineer-Professional Valid Exam Preparation
- The Benefits of Certified-Data-Engineer-Professional Certification 🤖 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on [ www.pdfvce.com ] 🧿Certified-Data-Engineer-Professional Reliable Test Labs
- Certified-Data-Engineer-Professional Certified - 100% Pass 2026 Certified-Data-Engineer-Professional: First-grade Databricks Certified Data Engineer Professional Download Fee 🤘 Copy URL ⮆ www.examdiscuss.com ⮄ open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🧦Certified-Data-Engineer-Professional Latest Examprep
- 100% Pass Quiz 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Accurate Certified ⏪ Search for ▷ Certified-Data-Engineer-Professional ◁ and easily obtain a free download on ▶ www.pdfvce.com ◀ 🍙New Certified-Data-Engineer-Professional Test Blueprint
- Features of Databricks Certified-Data-Engineer-Professional Dumps PDF Format 📬 Open website { www.prepawayete.com } and search for ➤ Certified-Data-Engineer-Professional ⮘ for free download 🚚Certified-Data-Engineer-Professional Latest Examprep
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PassLeader: https://drive.google.com/open?id=1IVqK-LCGNoyCMqnggaoIZrAtN7OdDNeB