DY0-001 Exam Questions Vce | Latest DY0-001 Test Notes

BTW, DOWNLOAD part of DumpsMaterials DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=1bygUGmmgc9Zzz7SbhxcVVr9lIfttZ7oK
Everything is difficult at beginning. When you are distressed about how to start your DY0-001 exam preparation, maybe to purchase our DY0-001 exam software is indispensable for your to first prepare for your DY0-001 exam. What we provide is what you want to attend DY0-001 Exam necessarily. You may hesitate whether to purchase our dump or not; don't worry, you can download our free demo of DY0-001 exam software. After you have tried our free demo, you will be sure to choose our DY0-001 exam software.
| Topic | Details |
|---|
| Topic 1 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| Topic 2 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 3 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 4 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 5 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
>> DY0-001 Exam Questions Vce <<
Latest DY0-001 Test Notes - DY0-001 Sample Questions Answers
The DY0-001 web-based practice exam requires no installation so you can start your preparation instantly right after you purchase. With thousands of satisfied customers around the globe, questions of the CompTIA DataAI Certification Exam (DY0-001) exam dumps are real so you can pass the CompTIA DY0-001 certification on the very first attempt. Hence, it reduces your chances of failure and you can save money and time as well.
CompTIA DataAI Certification Exam Sample Questions (Q20-Q25):
NEW QUESTION # 20
A data scientist is standardizing a large data set that contains website addresses. A specific string inside some of the web addresses needs to be extracted. Which of the following is the best method for extracting the desired string from the text data?
- A. Regular expressions
- B. Large language model
- C. Find and replace
- D. Named-entity recognition
Answer: A
NEW QUESTION # 21
A data scientist would like to model a complex phenomenon using a large data set composed of categorical, discrete, and continuous variables. After completing exploratory data analysis, the data scientist is reasonably certain that no linear relationship exists between the predictors and the target. Although the phenomenon is complex, the data scientist still wants to maintain the highest possible degree of interpretability in the final model. Which of the following algorithms best meets this objective?
- A. Artificial neural network
- B. Decision tree
- C. Multiple linear regression
- D. Random forest
Answer: B
Explanation:
# Decision trees offer excellent interpretability while handling complex, non-linear relationships and multiple variable types (categorical, discrete, continuous). They provide easy-to-understand visualizations and logic- based rules, making them ideal when transparency and insight are priorities.
Why other options are incorrect:
* A: Neural networks are powerful but are considered "black box" models, with low interpretability.
* C: Linear regression assumes a linear relationship, which contradicts the scenario.
* D: Random forests are ensembles of trees - more accurate, but less interpretable.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"Decision trees are interpretable models that support non-linear, multi-type data with logical branching."
-
NEW QUESTION # 22
A data scientist is using the following confusion matrix to assess model performance:
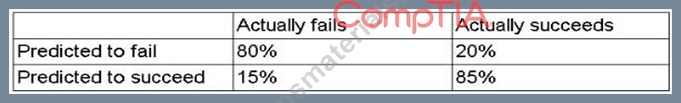
The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops. Every time the model is correct, the company saves an hour in planning and scheduling of maintenance work. Every time the model is wrong, the company loses four hours of delivery time for the truck. Which of the following is the net model impact for the company?
- A. 25 hours saved
- B. 25 hours lost
- C. 165 hours saved
- D. 165 hours lost
Answer: B
Explanation:
Treat each "predicted-to-fail" and "predicted-to-succeed" row as coming from 100 cases apiece (200 total).
NEW QUESTION # 23
The following graphic shows the results of an unsupervised, machine-learning clustering model:
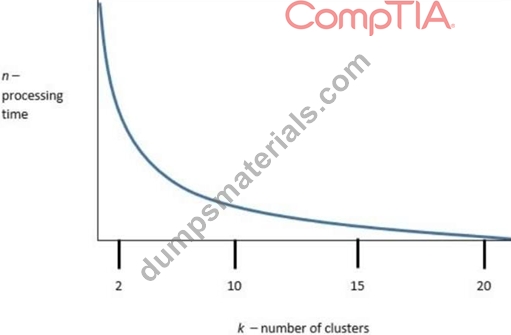
k is the number of clusters, and n is the processing time required to run the model. Which of the following is the best value of k to optimize both accuracy and processing requirements?
Answer: B
Explanation:
# The graph represents a classic "elbow curve," which is often used in clustering (e.g., k-means) to help determine the optimal number of clusters. The point where the curve starts to level off (the "elbow") reflects the best trade-off between model accuracy and processing efficiency.
In this graph, the elbow visually occurs around k = 10. Beyond that, the processing time continues to decrease, but the marginal gain in clustering quality (or drop in processing time) diminishes.
Why the other options are incorrect:
* A: k = 2 underfits the data - too few clusters.
* C & D: k = 15 or 20 provides minimal additional benefit in processing but may overcomplicate the model.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"The elbow method identifies the optimal number of clusters where the rate of improvement drops significantly."
-
NEW QUESTION # 24
SIMULATION
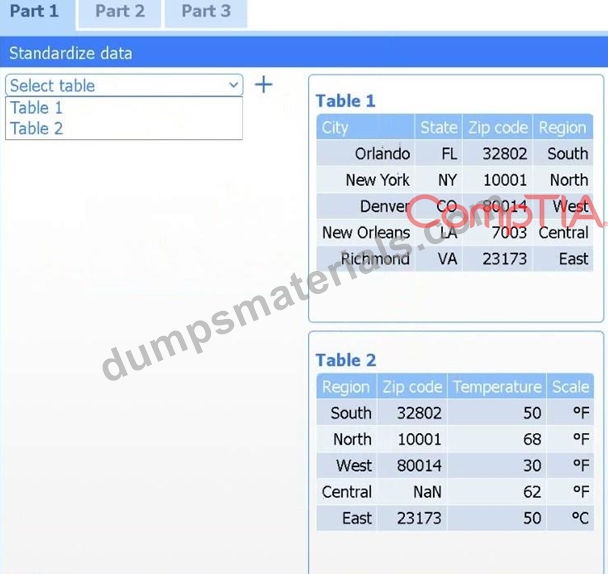
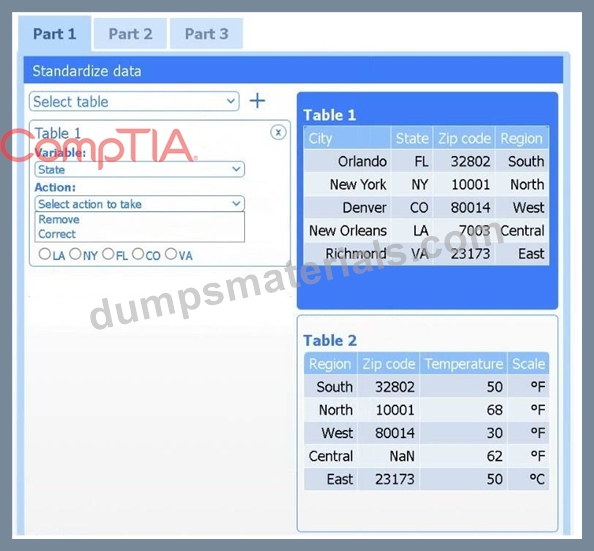
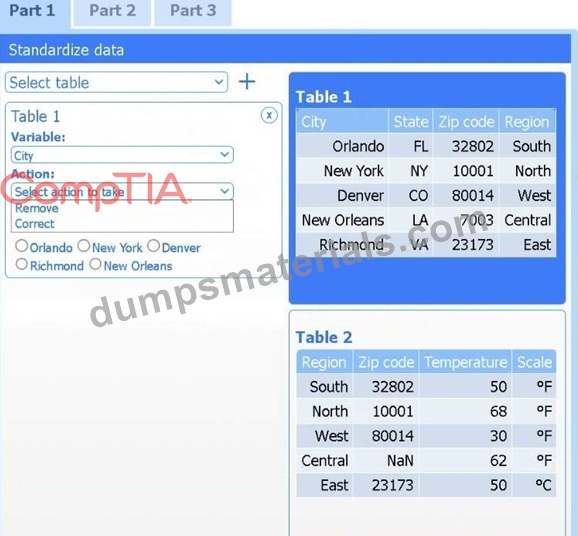
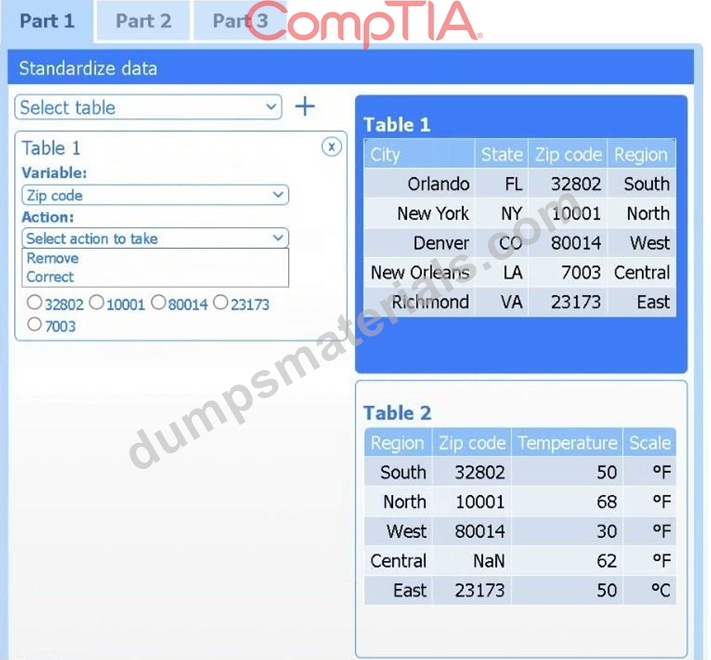
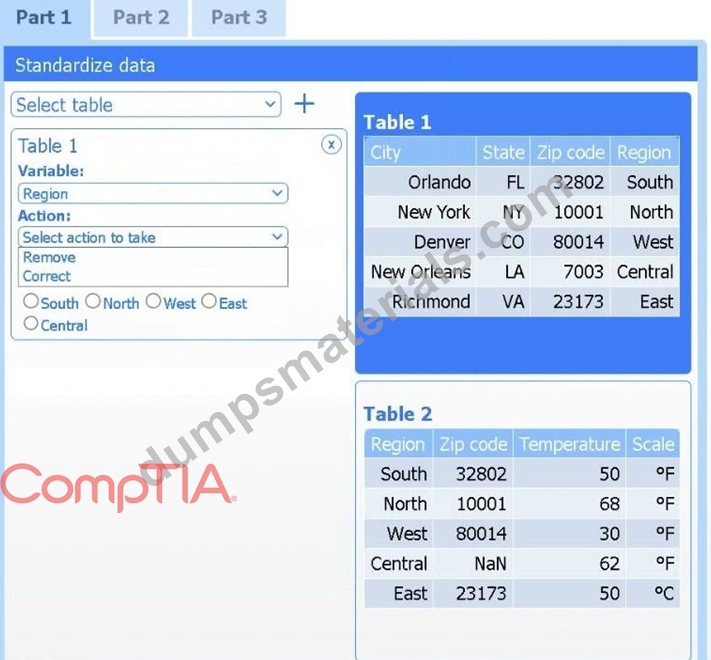
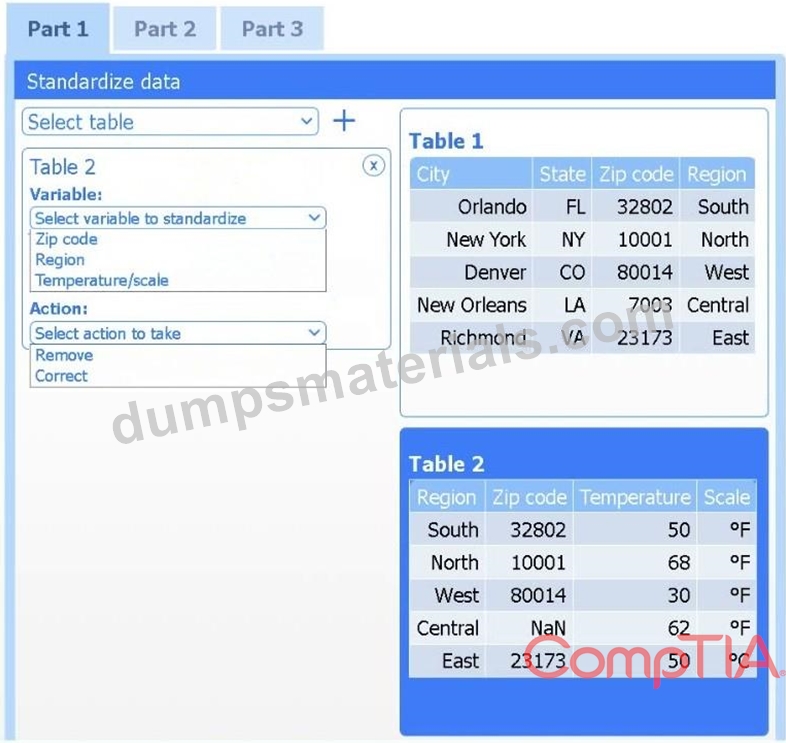
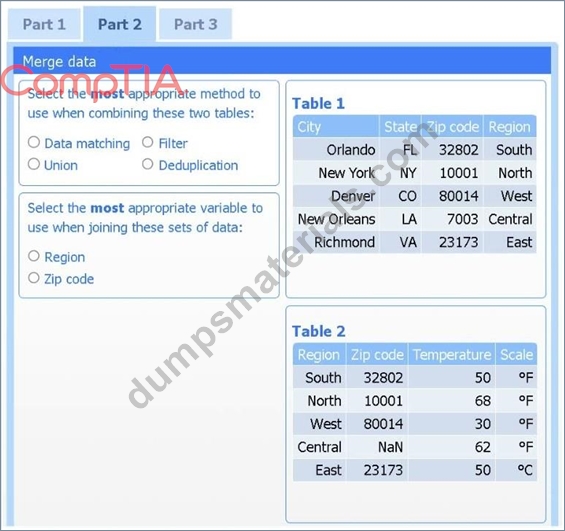
A client has gathered weather data on which regions have high temperatures. The client would like a visualization to gain a better understanding of the data.
INSTRUCTIONS
Part 1
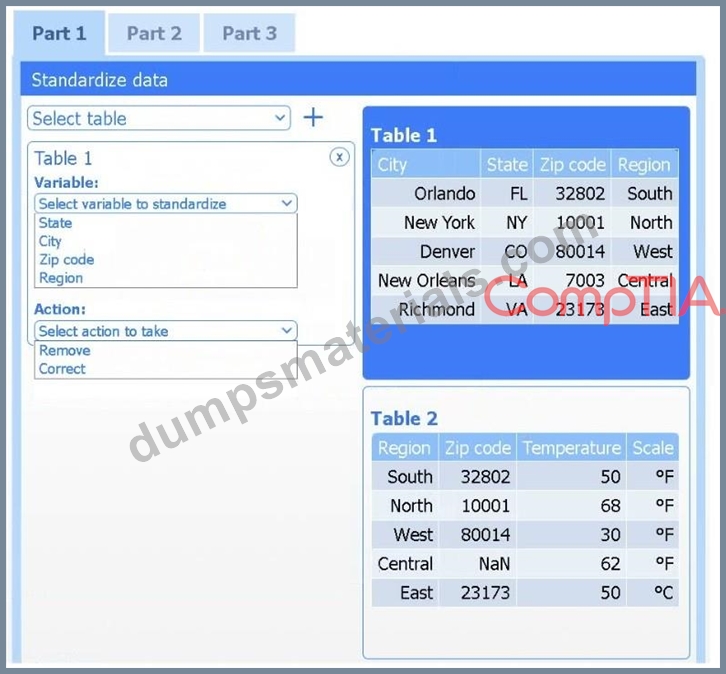
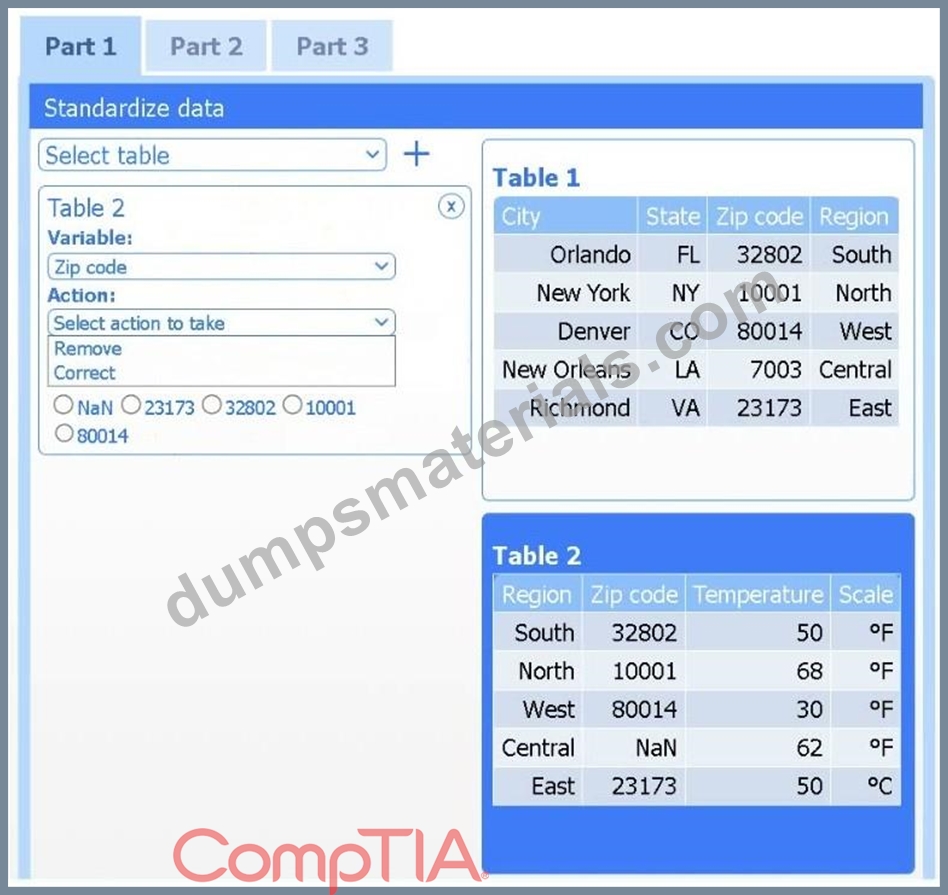
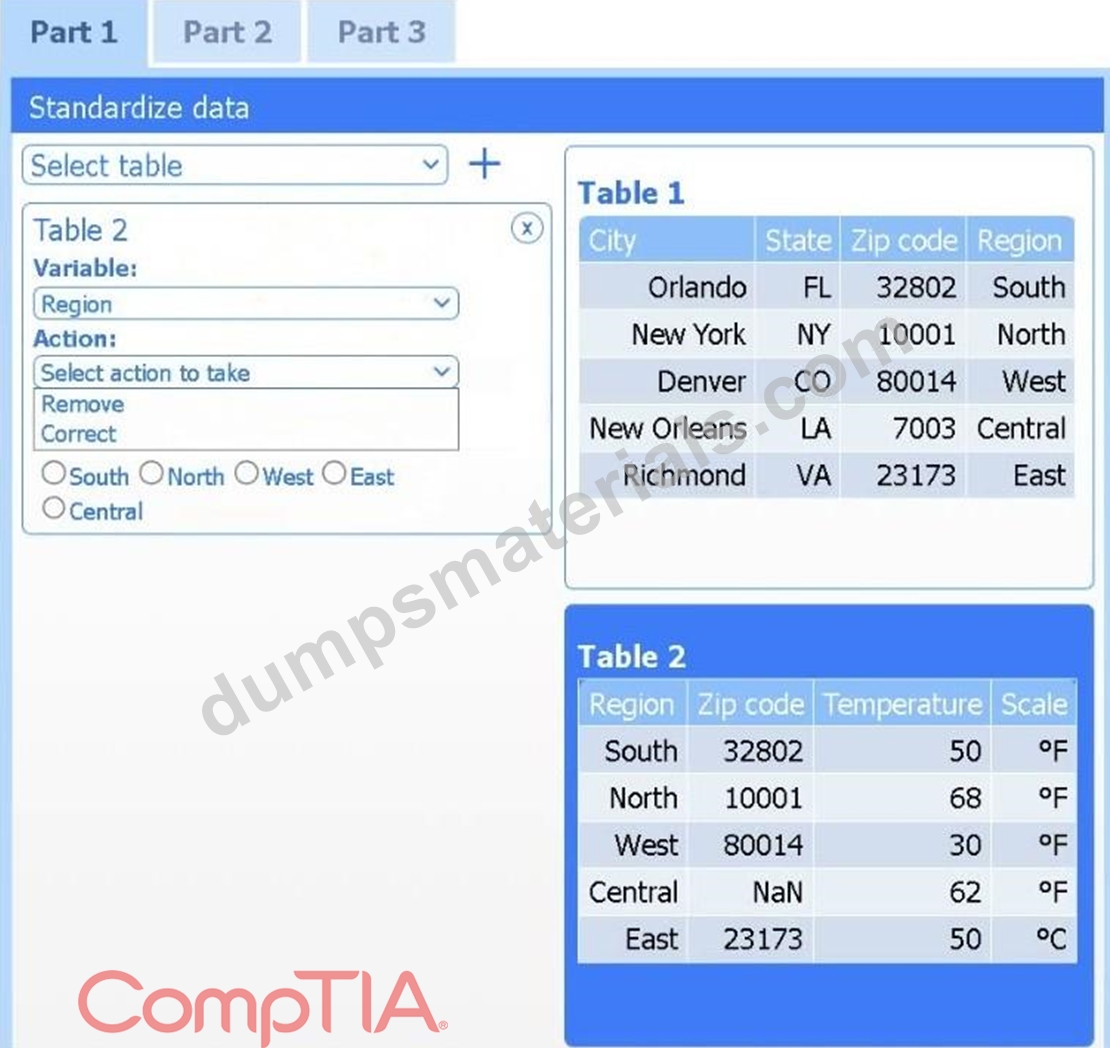
Review the charts provided and use the drop-down menu to select the most appropriate way to standardize the data.
Part 2
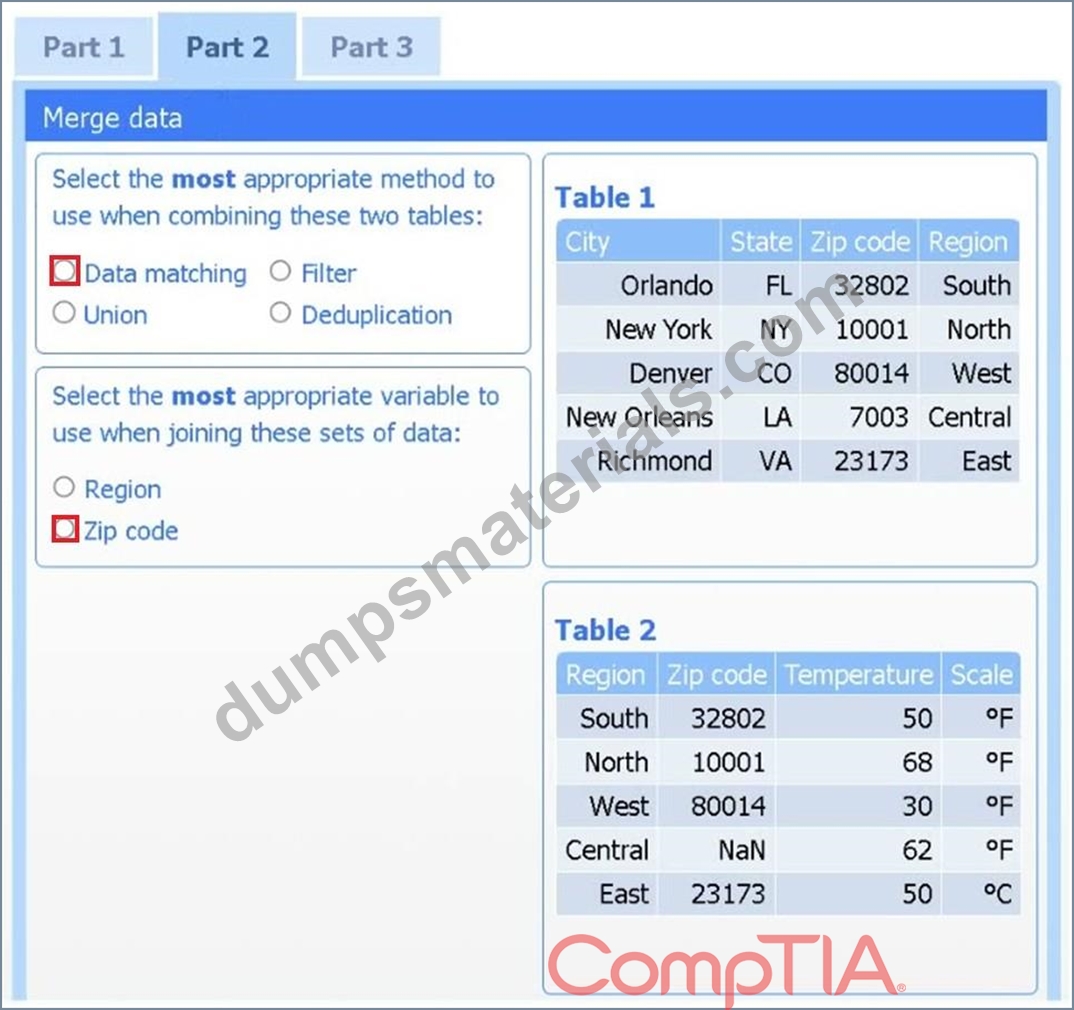
Answer the questions to determine how to create one data set.
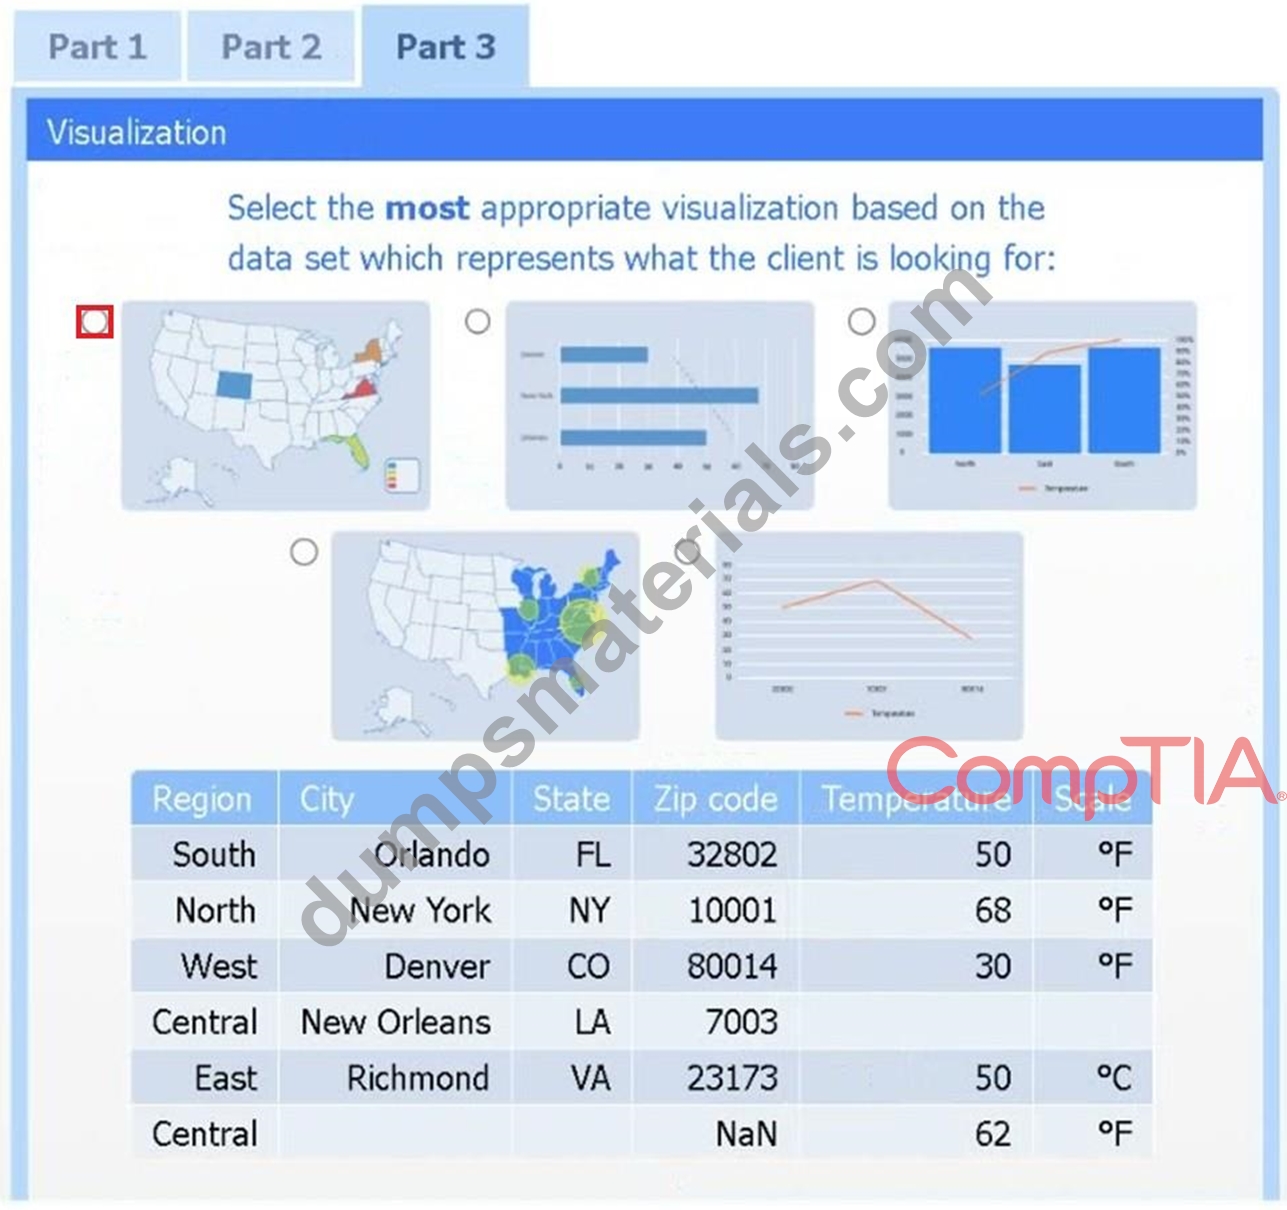
Part 3
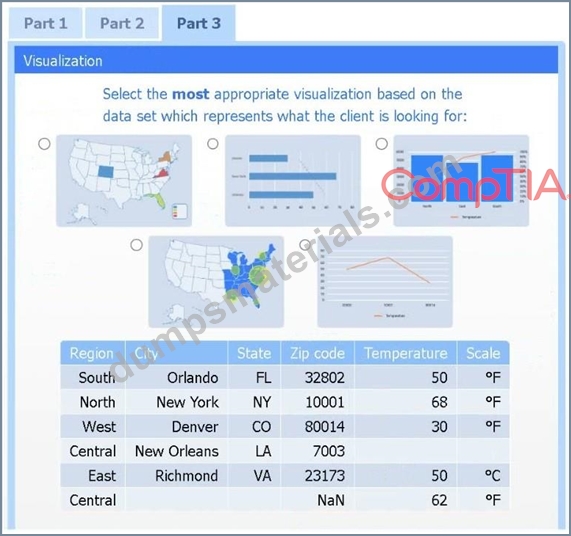
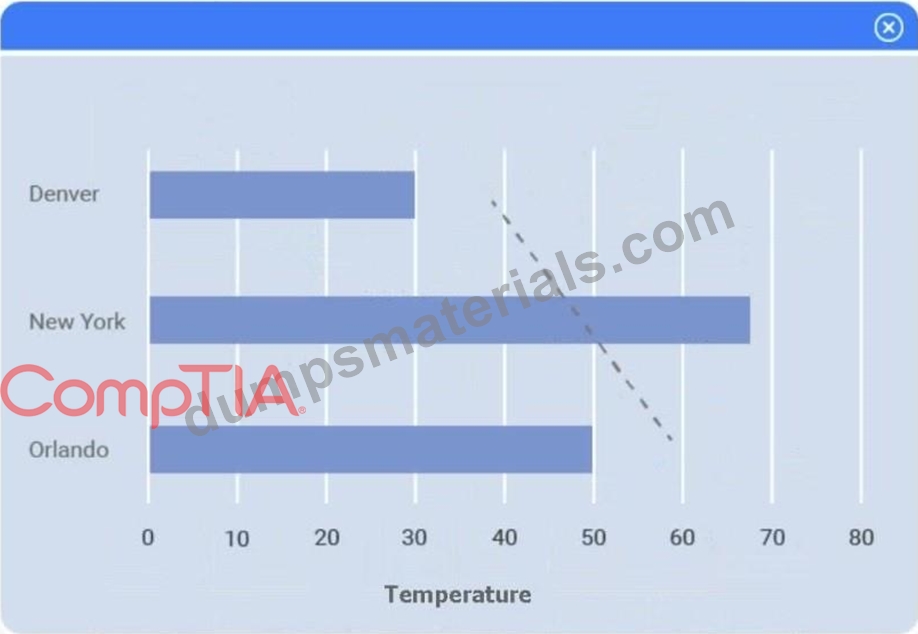
Select the most appropriate visualization based on the data set that represents what the client is looking for.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.
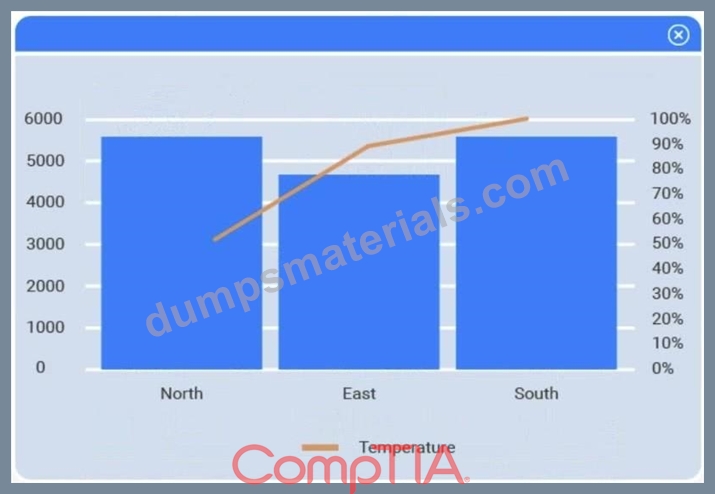
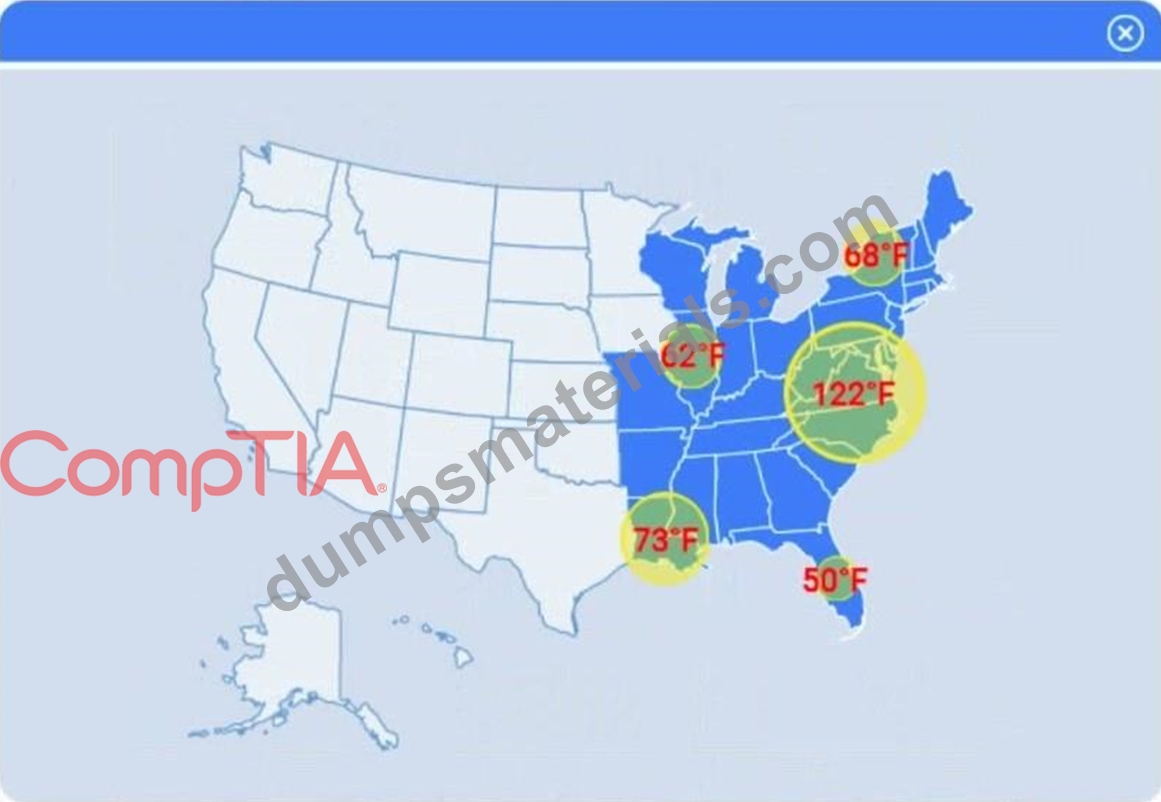
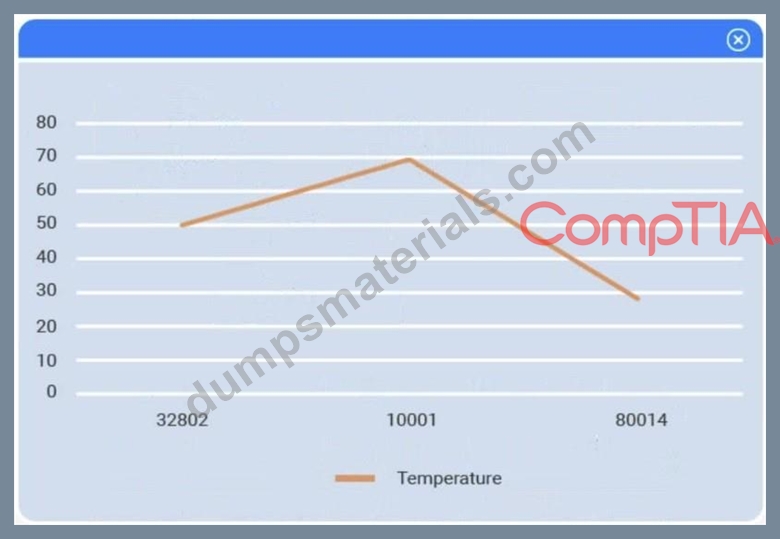
Answer:
Explanation:
Part 1
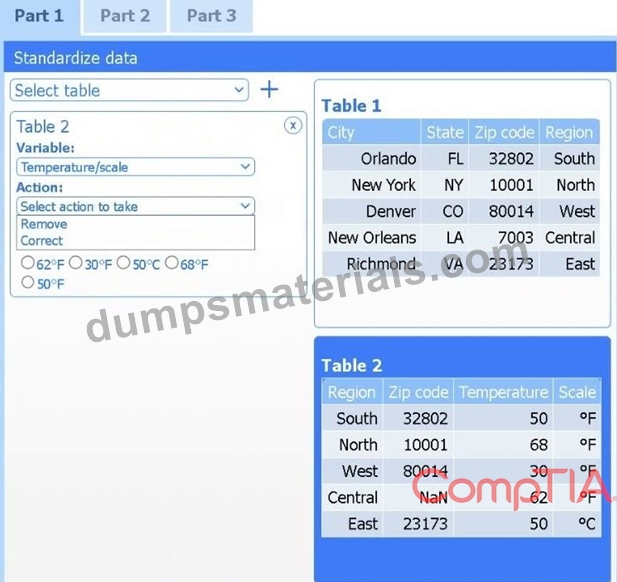
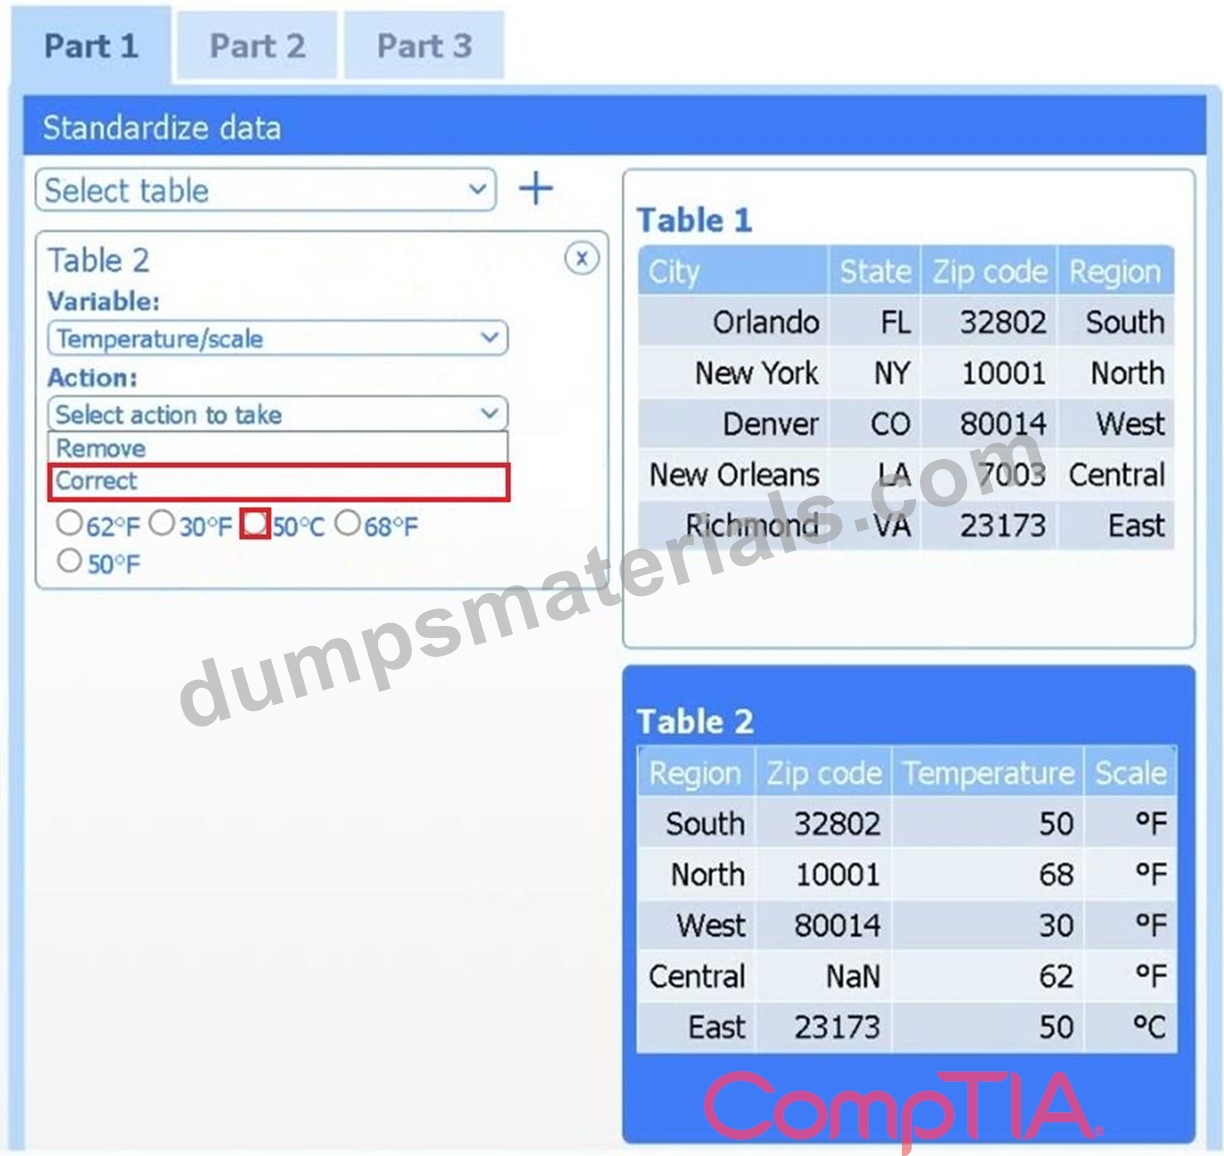
Select Table 2. Table 2 contains mixed temperature scales (°F and °C) that must be standardized before visualization.
Variable: Temperature/scale
Action: Correct
Value to correct: 50 °C
Part 2
Method: Data matching
Join variable: Zip code
You need to merge the two tables by aligning matching records, which is a data-matching (join) operation, and ZIP code is the shared, uniquely identifying field linking each region's weather reading to its city.
Part 3
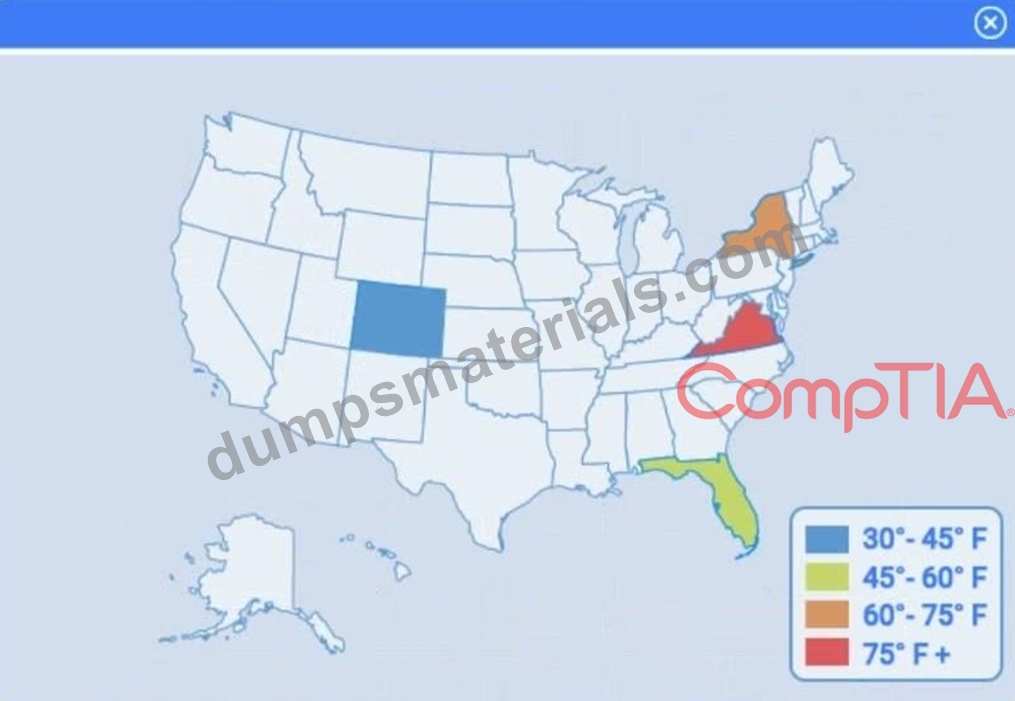
Choose the choropleth map (the first option).
A choropleth map best shows geographic variation in temperature by coloring each state (or region) according to its recorded value. This lets the client immediately see where the highest and lowest temperatures occur across the U.S. without distracting elements like bubble size or combined chart axes.
NEW QUESTION # 25
......
The reason why many people choose DumpsMaterials is that DumpsMaterials brings more convenience. IT elites of DumpsMaterials use their professional eye to search the latest DY0-001 certification training materials, which ensure the accuracy of our DY0-001 Exam Dumps. If you still worry, you can download DY0-001 free demo before purchase.
Latest DY0-001 Test Notes: https://www.dumpsmaterials.com/DY0-001-real-torrent.html
- DY0-001 Valid Test Duration 🅿 New DY0-001 Exam Simulator 🍗 Reliable DY0-001 Exam Tips 📺 Simply search for ▶ DY0-001 ◀ for free download on ▛ www.prep4sures.top ▟ 🌇New DY0-001 Exam Simulator
- Latest DY0-001 Exam Questions Vce, Latest DY0-001 Test Notes 😿 Open website 【 www.pdfvce.com 】 and search for 「 DY0-001 」 for free download 🛤DY0-001 Passing Score
- New DY0-001 Exam Simulator 🏜 Reliable DY0-001 Test Materials 🎻 Valid Dumps DY0-001 Sheet 🔑 Enter ⇛ www.vce4dumps.com ⇚ and search for ▛ DY0-001 ▟ to download for free 🏞Practice DY0-001 Exam Fee
- New DY0-001 Exam Simulator 🍂 Valid Dumps DY0-001 Sheet 🌘 Real DY0-001 Exam Answers 💼 Easily obtain 《 DY0-001 》 for free download through “ www.pdfvce.com ” 💂Valid Dumps DY0-001 Sheet
- DY0-001 Exam Tutorials 🌳 DY0-001 New Study Materials 🧣 Valid Dumps DY0-001 Sheet 🌘 Copy URL ( www.troytecdumps.com ) open and search for ➡ DY0-001 ️⬅️ to download for free 📧DY0-001 Passing Score
- DY0-001 Testing Center 🚝 Reliable DY0-001 Exam Tips 🧝 Certification DY0-001 Test Answers 🔐 Download ⇛ DY0-001 ⇚ for free by simply searching on ➥ www.pdfvce.com 🡄 🤖Test DY0-001 Dumps.zip
- Updated and Reliable CompTIA DY0-001 Exam Questions for Guaranteed Success 🦟 Search for ▷ DY0-001 ◁ and download exam materials for free through ▛ www.troytecdumps.com ▟ 🕸DY0-001 Testing Center
- DY0-001 Dumps For Pdfvce - Best 🧉 The page for free download of ⏩ DY0-001 ⏪ on ( www.pdfvce.com ) will open immediately 🕞DY0-001 Latest Test Braindumps
- 2026 Efficient DY0-001 Exam Questions Vce | 100% Free Latest DY0-001 Test Notes 🐘 Open website ▶ www.exam4labs.com ◀ and search for “ DY0-001 ” for free download ⏺Practice DY0-001 Exam Fee
- DY0-001 New Study Materials 🏹 Practice DY0-001 Exam Fee 🧘 Reliable DY0-001 Test Materials 🕛 Open 《 www.pdfvce.com 》 enter ➡ DY0-001 ️⬅️ and obtain a free download 🔝New DY0-001 Exam Simulator
- DY0-001 Exam Questions Vce – The Best Latest Test Notes for your CompTIA DY0-001 ➿ Open ➥ www.practicevce.com 🡄 enter ▶ DY0-001 ◀ and obtain a free download 💕DY0-001 Valid Test Duration
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by DumpsMaterials: https://drive.google.com/open?id=1bygUGmmgc9Zzz7SbhxcVVr9lIfttZ7oK