BTW, DOWNLOAD part of BootcampPDF DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=19-zaHHkICaxAh3eUssVI0zFMWkRtgqnI
However, the appearance of our DP-100 certification materials will solve your question and change your impression of DP-100 certification exam. You will find it is easy to pass the DP-100 certification exam. What’s more, contrary to most of the exam preparation materials available online, the DP-100 certification materials of DP-100 can be obtained at a reasonable price, and its quality and advantages exceed all similar products of our competitors. All our customers have successfully passed the exam. DP-100 certification materials will enable you to obtain the actual certification within days, and will be the best choice for your time and money.
| Section | Objectives |
|---|---|
| Topic 1: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 2: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Manage compute and data assets - Select appropriate Azure services for machine learning workloads |
| Topic 3: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 4: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 5: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
As is known to us, there are best sale and after-sale service of the DP-100 certification training materials all over the world in our company. Our company has employed many excellent experts and professors in the field in the past years, in order to design the best and most suitable DP-100 Latest Questions for all customers. More importantly, it is evident to all that the DP-100 training materials from our company have a high quality, and we can make sure the quality of our products will be higher than other study materials in the market.
NEW QUESTION # 96
You are creating a machine learning model in Python. The provided dataset contains several numerical columns and one text column. The text column represents a product's category. The product category will always be one of the following:
Bikes
Cars
Vans
Boats
You are building a regression model using the scikit-learn Python package.
You need to transform the text data to be compatible with the scikit-learn Python package.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.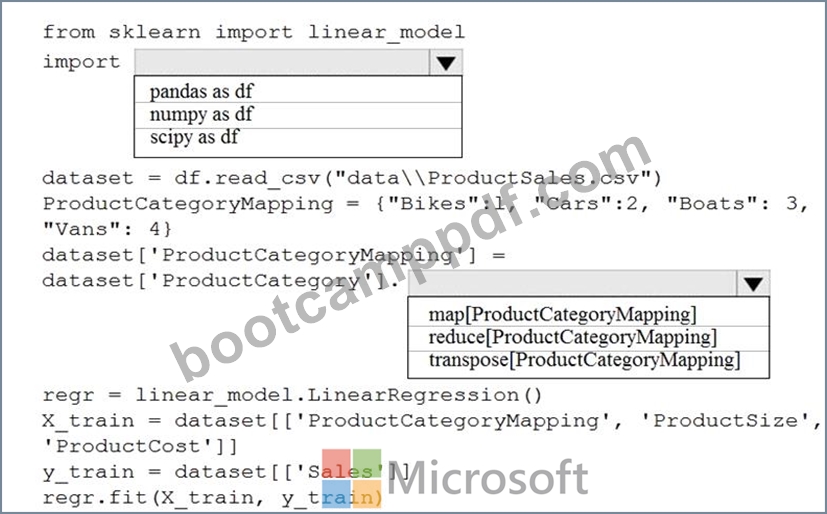
Answer:
Explanation: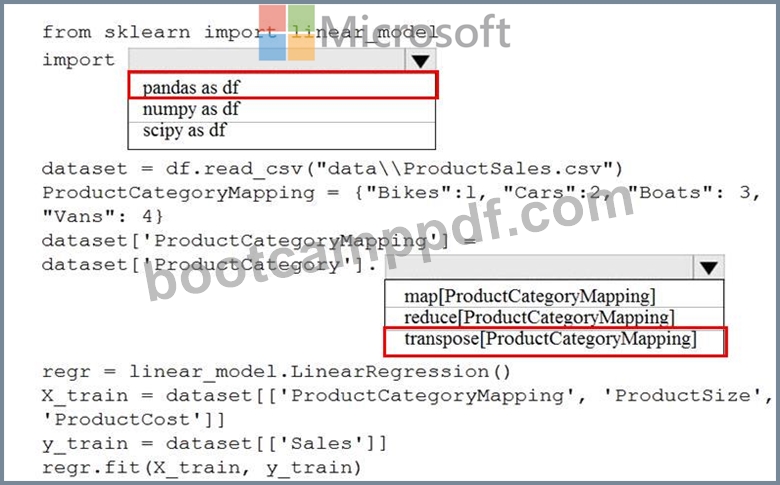
Explanation:
Box 1: pandas as df
Pandas takes data (like a CSV or TSV file, or a SQL database) and creates a Python object with rows and columns called data frame that looks very similar to table in a statistical software (think Excel or SPSS for example.
Box 2: transpose[ProductCategoryMapping]
Reshape the data from the pandas Series to columns.
Reference:
https://datascienceplus.com/linear-regression-in-python/
NEW QUESTION # 97
You have an Azure Machine Learning workspace and a data source file ./data/cc_data.csv in the local storage.
You plan to use Azure Machine Learning Python SDK v2 to store the content of the cc.data.csv file in a data asset named cc_data_asset in the workspace.
You write code to connect to the workspace and import all required libraries.
You need to complete the remaining code to ensure it will result in the cc_data_asset that contains the data from cc_data.csv.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.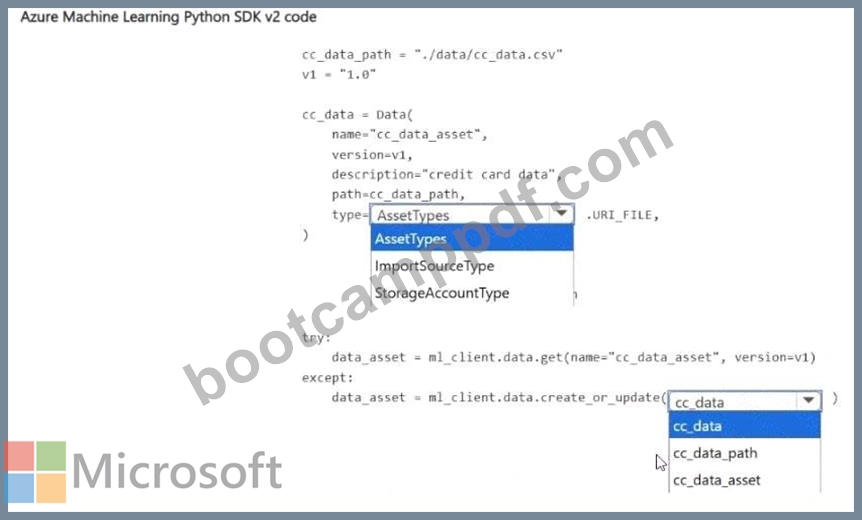
Answer:
Explanation: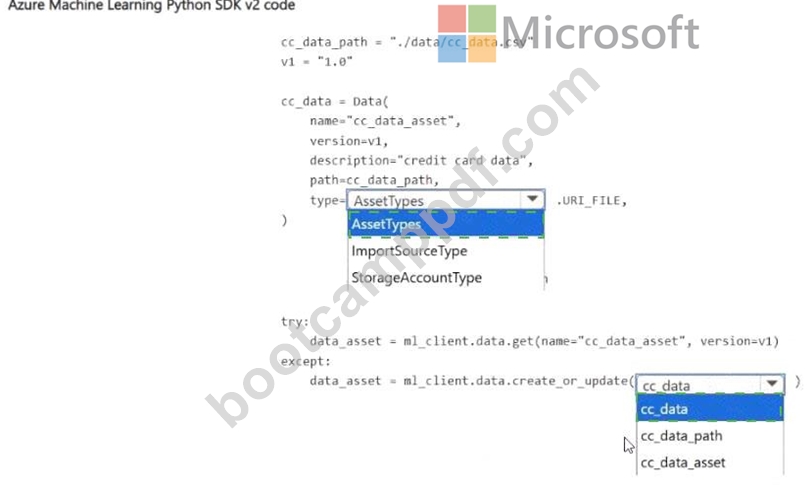
Explanation: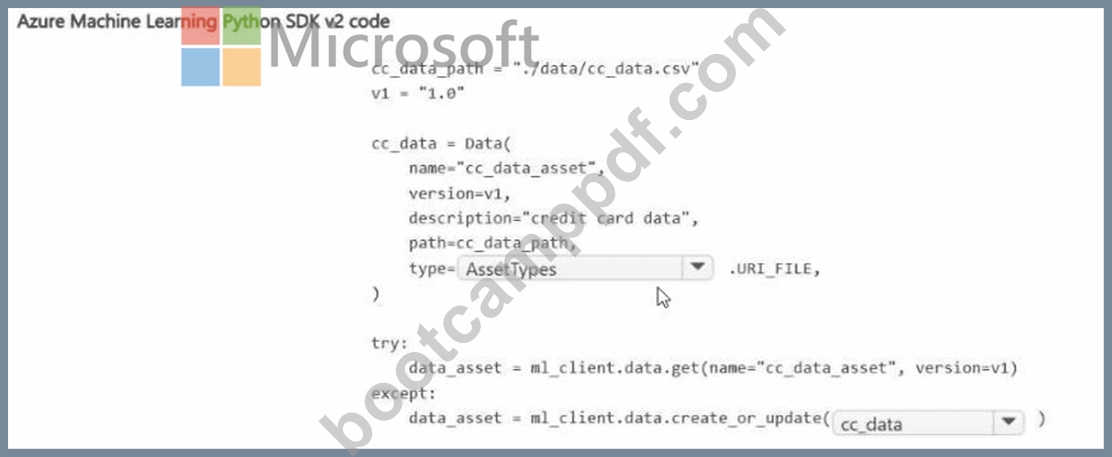
NEW QUESTION # 98
You have a Python data frame named salesData in the following format:
The data frame must be unpivoted to a long data format as follows:
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.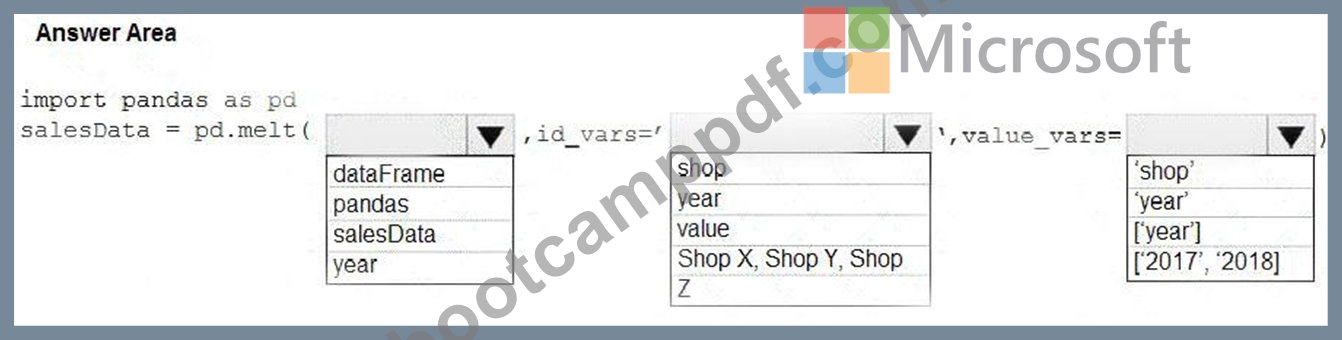
Answer:
Explanation: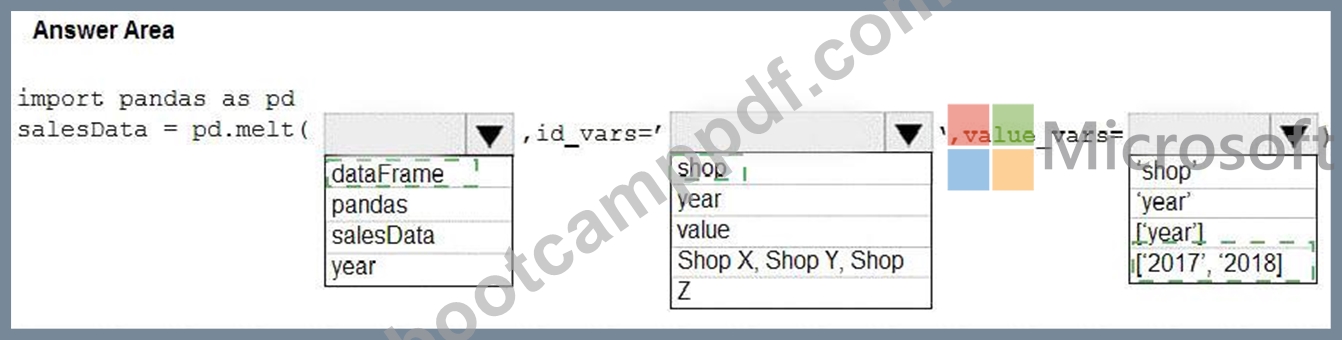
Explanation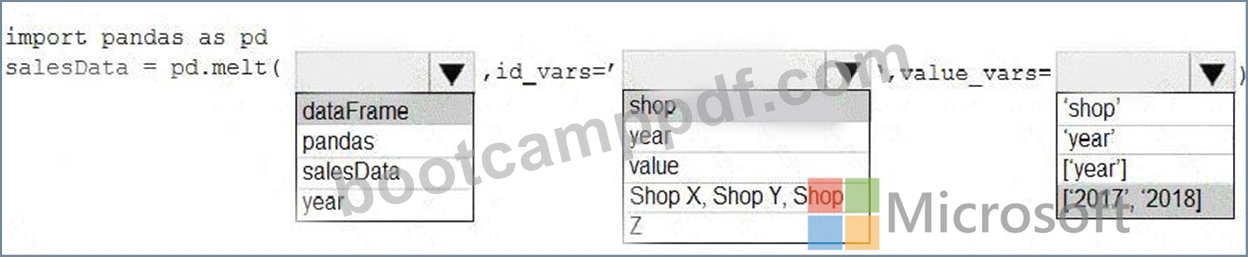
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
'B': {0: 1, 1: 3, 2: 5},
'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
NEW QUESTION # 99
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: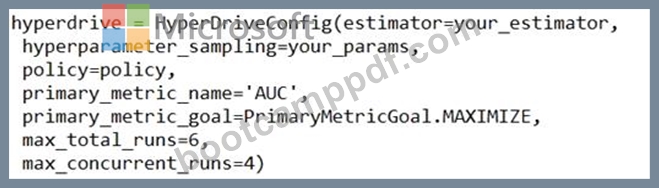
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: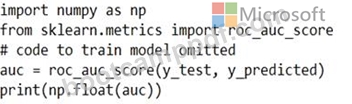
Does the solution meet the goal?
Answer: A
Explanation:
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 100
You register the following versions of a model.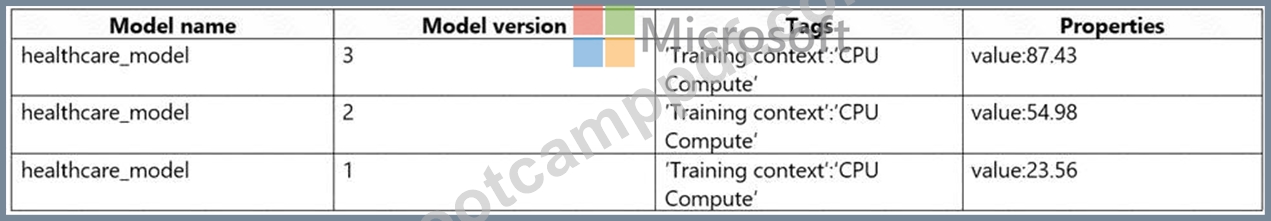
You use the Azure ML Python SDK to run a training experiment. You use a variable named run to reference the experiment run.
After the run has been submitted and completed, you run the following code: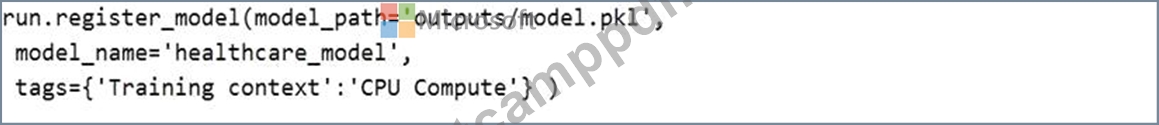
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.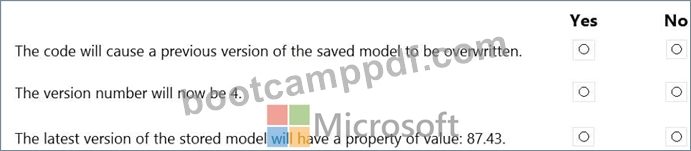
Answer:
Explanation: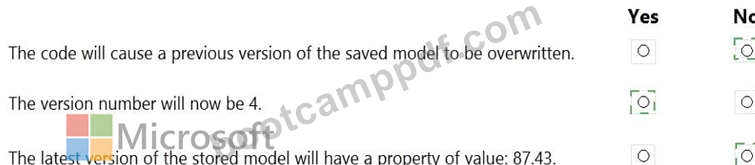
Explanation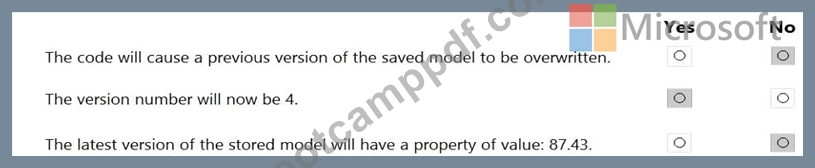
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-and-where
NEW QUESTION # 101
......
If you want to through the Microsoft DP-100 certification exam to make a stronger position in today's competitive IT industry, then you need the strong expertise knowledge and the accumulated efforts. And pass the Microsoft DP-100 exam is not easy. Perhaps through Microsoft DP-100 exam you can promote yourself to the IT industry. But it is not necessary to spend a lot of time and effort to learn the expertise. You can choose BootcampPDF's Microsoft DP-100 Exam Training materials. This is training product that specifically made for IT exam. With it you can pass the difficult Microsoft DP-100 exam effortlessly.
Latest DP-100 Test Guide: https://www.bootcamppdf.com/DP-100_exam-dumps.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by BootcampPDF: https://drive.google.com/open?id=19-zaHHkICaxAh3eUssVI0zFMWkRtgqnI