Databricks-Certified-Data-Analyst-Associate Reliable Exam Sample | Databricks-Certified-Data-Analyst-Associate Latest Test Simulator

P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by Exam4Docs: https://drive.google.com/open?id=1NxLtH5cPuonyptwqItXDG4DVB9HzNT5V
As is known to us, our company is professional brand established for compiling the Databricks-Certified-Data-Analyst-Associate exam materials for all candidates. The Databricks-Certified-Data-Analyst-Associate guide files from our company are designed by a lot of experts and professors of our company in the field. We can promise that the Databricks-Certified-Data-Analyst-Associate certification braindumps of our company have the absolute authority in the study materials market. We believe that the study materials designed by our company will be the most suitable choice for you. You can totally depend on the Databricks-Certified-Data-Analyst-Associate Guide files of our company when you are preparing for the exam.
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
>> Databricks-Certified-Data-Analyst-Associate Reliable Exam Sample <<
TOP Databricks-Certified-Data-Analyst-Associate Reliable Exam Sample: Databricks Certified Data Analyst Associate Exam - Latest Databricks Databricks-Certified-Data-Analyst-Associate Latest Test Simulator
The Databricks Databricks-Certified-Data-Analyst-Associate practice exam will be a great help because you are left with little time to prepare for the Databricks Databricks-Certified-Data-Analyst-Associate certification exam which you cannot waste to make time for the Databricks Databricks-Certified-Data-Analyst-Associate Exam Questions. Get the Databricks Databricks-Certified-Data-Analyst-Associate certification by preparing through Databricks Databricks-Certified-Data-Analyst-Associate exam questions that will help you pass the Databricks Databricks-Certified-Data-Analyst-Associate exam.
| Topic | Details |
|---|
| Topic 1 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 2 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 3 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 4 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 5 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
Databricks Certified Data Analyst Associate Exam Sample Questions (Q111-Q116):
NEW QUESTION # 111
A data analyst creates a Databricks SQL Query where the result set has the following schema:
region STRING
number_of_customer INT
When the analyst clicks on the "Add visualization" button on the SQL Editor page, which of the following types of visualizations will be selected by default?
- A. There is no default. The user must choose a visualization type.
- B. Violin Chart
- C. Histogram
- D. IBar Chart
- E. Line Chart
Answer: D
Explanation:
According to the Databricks SQL documentation, when a data analyst clicks on the "Add visualization" button on the SQL Editor page, the default visualization type is Bar Chart. This is because the result set has two columns: one of type STRING and one of type INT. The Bar Chart visualization automatically assigns the STRING column to the X-axis and the INT column to the Y-axis. The Bar Chart visualization is suitable for showing the distribution of a numeric variable across different categories. Reference: Visualization in Databricks SQL, Visualization types
NEW QUESTION # 112
A data analyst is using Databricks Unity Catalog. The datasets are tagged by sensitivity, and confidential data is marked with the tag key confidential. The data analyst needs to quickly find all tables tagged as confidential to review their access permissions in the Databricks workspace search bar.
Which search key text should the data analyst use to find these tables?
- A. tag=confidential
- B. tag:confidential
- C. confidential:true
- D. search tag = ' confidential '
Answer: B
Explanation:
The correct answer is C because the tag key is confidential, and Databricks workspace search uses the syntax tag: < tag_key > to search by tag key. Therefore, the correct search text is tag:confidential. Option A uses a Boolean-style syntax that is not the documented Databricks tag search syntax. Option B uses an equals sign, and Option D is not valid workspace search syntax.
Official documentation extract used: Databricks states that to search by tag key alone, use the syntax tag: < tag_key > .
NEW QUESTION # 113
Query History provides Databricks SQL users with a lot of benefits. A data analyst has been asked to share all of these benefits with their team as part of a training exercise. One of the benefit statements the analyst provided to their team is incorrect.
Which statement about Query History is incorrect?
- A. It can be used to debug queries.
- B. It can be used to view the query plan of queries that have run.
- C. It can be used to automate query execution on multiple warehouses (formerly endpoints).
- D. It can be used to troubleshoot slow running queries.
Answer: C
Explanation:
Query History in Databricks SQL is intended for reviewing executed queries, understanding their execution plans, and identifying performance issues or errors for debugging purposes. It allows users to analyze query duration, resources used, and potential bottlenecks. However, Query History does not provide any capability to automate the execution of queries across multiple warehouses; automation must be handled through jobs or external orchestration tools, not through the Query History feature itself.
NEW QUESTION # 114
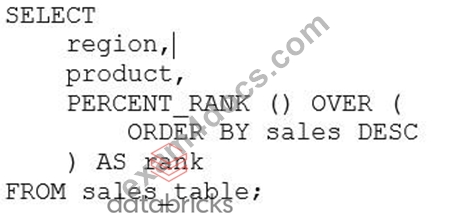
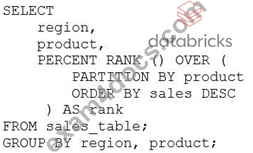
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales:
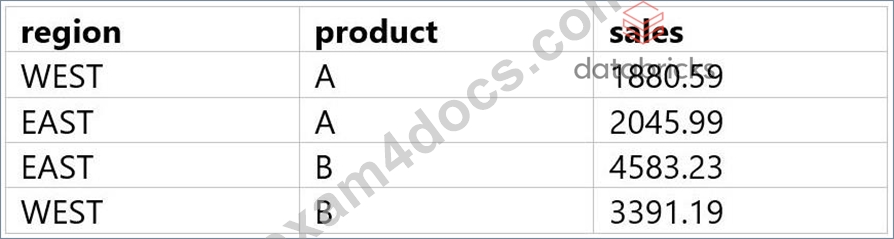
The result of the query should look like this:
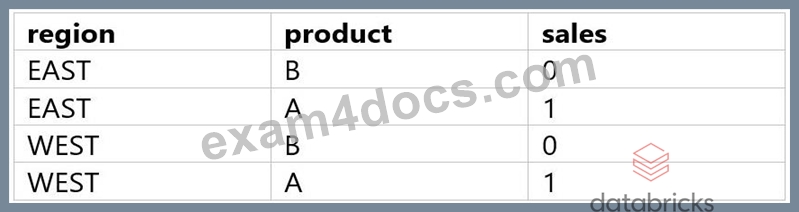
Which of the following queries will accomplish this task?
A)
B)
C)
- A. Option B
- B. Option D
- C. Option A
- D. Option C
Answer: A
Explanation:
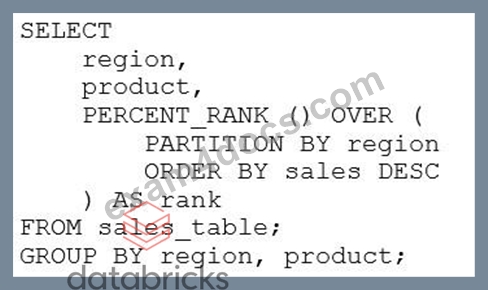
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
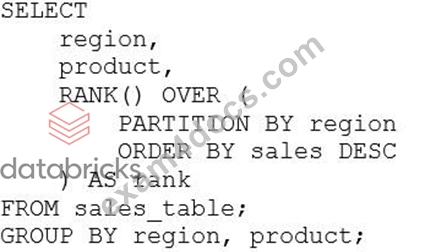
A) Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
C) Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function. The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
D) Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function. The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). Reference:
1: PERCENT_RANK (Transact-SQL)
2: Window functions in Databricks SQL
3: Databricks Certified Data Analyst Associate Exam Guide
NEW QUESTION # 115
After running DESCRIBE EXTENDED accounts.customers;, the following was returned:
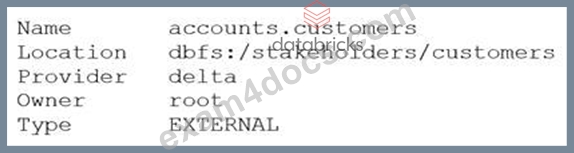
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
- A. Running SELECT * FROM accounts.customers will return all rows in the table.
- B. The accounts.customers table is removed from the metastore, and the underlying data files are deleted.
- C. Running SELECT * FROM delta. `dbfs:/stakeholders/customers` results in an error.
- D. All files with the .customers extension are deleted.
- E. The accounts.customers table is removed from the metastore, but the underlying data files are untouched.
Answer: E
Explanation:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders
/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. References: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
NEW QUESTION # 116
......
Databricks-Certified-Data-Analyst-Associate Latest Test Simulator: https://www.exam4docs.com/Databricks-Certified-Data-Analyst-Associate-study-questions.html
- Test Databricks-Certified-Data-Analyst-Associate Sample Online 🚖 Valid Databricks-Certified-Data-Analyst-Associate Exam Forum 🕶 Databricks-Certified-Data-Analyst-Associate Latest Exam Preparation 🎵 Open website ➠ www.verifieddumps.com 🠰 and search for 《 Databricks-Certified-Data-Analyst-Associate 》 for free download 😧Real Databricks-Certified-Data-Analyst-Associate Testing Environment
- Valid Braindumps Databricks-Certified-Data-Analyst-Associate Ppt 🎁 Download Databricks-Certified-Data-Analyst-Associate Pdf 👞 Valid Braindumps Databricks-Certified-Data-Analyst-Associate Ppt 🧘 Download ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ for free by simply searching on ➠ www.pdfvce.com 🠰 🤰Databricks-Certified-Data-Analyst-Associate Exams Torrent
- Databricks-Certified-Data-Analyst-Associate Test Study Guide 😤 Valid Databricks-Certified-Data-Analyst-Associate Exam Pass4sure 🎩 Download Databricks-Certified-Data-Analyst-Associate Pdf 🐐 Search on { www.examdiscuss.com } for ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ to obtain exam materials for free download 🤩Valid Databricks-Certified-Data-Analyst-Associate Exam Forum
- Free PDF Databricks - Databricks-Certified-Data-Analyst-Associate - Perfect Databricks Certified Data Analyst Associate Exam Reliable Exam Sample 🦔 ( www.pdfvce.com ) is best website to obtain ➤ Databricks-Certified-Data-Analyst-Associate ⮘ for free download 👨Download Databricks-Certified-Data-Analyst-Associate Pdf
- Valid Databricks-Certified-Data-Analyst-Associate Exam Forum 🔊 Valid Databricks-Certified-Data-Analyst-Associate Exam Pass4sure 🧰 Databricks-Certified-Data-Analyst-Associate Test Study Guide 🚎 ⏩ www.examcollectionpass.com ⏪ is best website to obtain 「 Databricks-Certified-Data-Analyst-Associate 」 for free download 🔢Databricks-Certified-Data-Analyst-Associate Latest Dumps Free
- Exam Databricks-Certified-Data-Analyst-Associate Discount 🦦 Download Databricks-Certified-Data-Analyst-Associate Pdf 🚮 Databricks-Certified-Data-Analyst-Associate Well Prep 🧵 Search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 on ▛ www.pdfvce.com ▟ immediately to obtain a free download 🕘Databricks-Certified-Data-Analyst-Associate Cost Effective Dumps
- Useful 100% Free Databricks-Certified-Data-Analyst-Associate – 100% Free Reliable Exam Sample | Databricks-Certified-Data-Analyst-Associate Latest Test Simulator 🦈 Simply search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ for free download on 【 www.verifieddumps.com 】 💯Real Databricks-Certified-Data-Analyst-Associate Testing Environment
- Useful 100% Free Databricks-Certified-Data-Analyst-Associate – 100% Free Reliable Exam Sample | Databricks-Certified-Data-Analyst-Associate Latest Test Simulator ⛪ Open 「 www.pdfvce.com 」 and search for ▛ Databricks-Certified-Data-Analyst-Associate ▟ to download exam materials for free 🌸Databricks-Certified-Data-Analyst-Associate Test Study Guide
- Databricks-Certified-Data-Analyst-Associate Well Prep ↕ Databricks-Certified-Data-Analyst-Associate Well Prep 🚥 Free Databricks-Certified-Data-Analyst-Associate Practice Exams 🍽 Download ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ for free by simply searching on ▶ www.torrentvce.com ◀ 🏴Databricks-Certified-Data-Analyst-Associate Test Study Guide
- Databricks-Certified-Data-Analyst-Associate Reliable Exam Sample | Latest Databricks-Certified-Data-Analyst-Associate Latest Test Simulator: Databricks Certified Data Analyst Associate Exam 100% Pass 🏎 Easily obtain free download of 《 Databricks-Certified-Data-Analyst-Associate 》 by searching on ⏩ www.pdfvce.com ⏪ ↘Databricks-Certified-Data-Analyst-Associate PDF
- 100% Pass Quiz 2026 Databricks High Pass-Rate Databricks-Certified-Data-Analyst-Associate Reliable Exam Sample 🍲 Search for ▶ Databricks-Certified-Data-Analyst-Associate ◀ and download exam materials for free through ⏩ www.vce4dumps.com ⏪ 🏪Databricks-Certified-Data-Analyst-Associate Latest Dumps Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.toprecepty.cz, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that Exam4Docs Databricks-Certified-Data-Analyst-Associate dumps now are free: https://drive.google.com/open?id=1NxLtH5cPuonyptwqItXDG4DVB9HzNT5V