Our DP-800 study tool can help you obtain the DP-800 certification and own a powerful weapon for your interview. Our DP-800 qualification test will help you gain recognition with true talents and better adapted to society. Now, I would like to give you a brief introduction in order to make you deepen your impression of our DP-800 test guides. Our DP-800 test guides have a higher standard of practice and are rich in content. If you are anxious about how to get DP-800 certification, considering purchasing our DP-800 study tool is a wise choice and you will not feel regretted. Our learning materials will successfully promote your acquisition of certification.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-800 Valid Test Practice <<
Closed cars will not improve, and when we are reviewing our qualifying DP-800 examinations, we should also pay attention to the overall layout of various qualifying examinations. For the convenience of users, our DP-800 learn materials will be timely updated information associated with the qualification of the home page. Our DP-800 Certification material get to the exam questions can help users in the first place. Users can learn the latest and latest test information through our DP-800 test preparation materials. What are you waiting for?
NEW QUESTION # 36
Hotspot Question
You have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL item named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.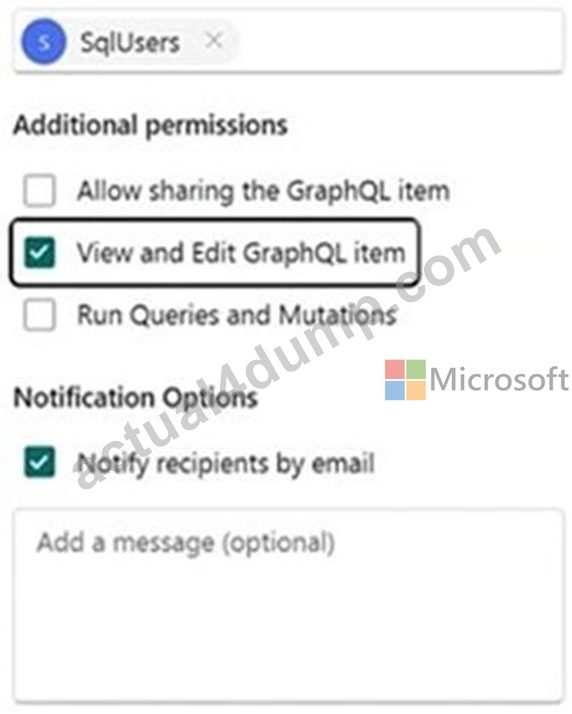
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.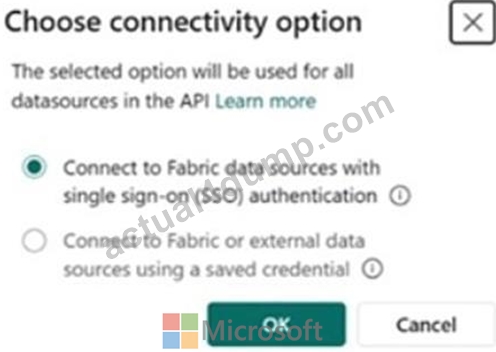
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.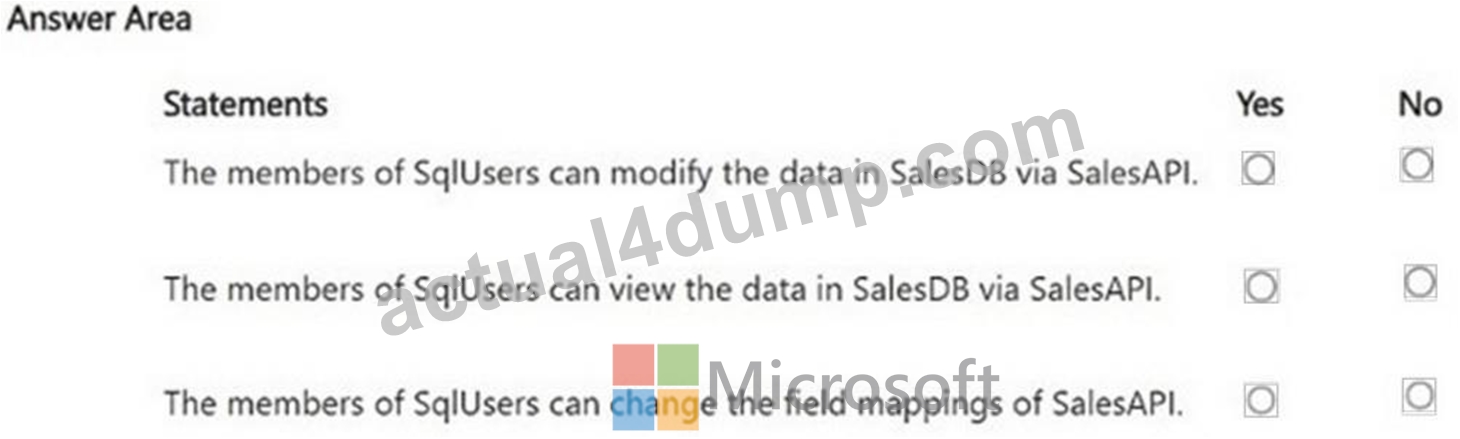
Answer:
Explanation: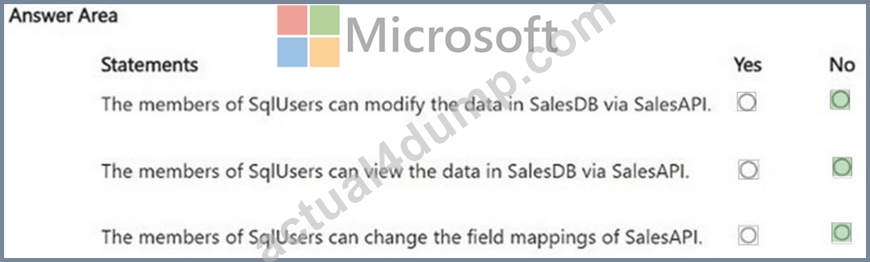
NEW QUESTION # 37
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1. DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1.
A company policy prohibits sharing customer Personally Identifiable Information (PII), secrets, and query result sets with any AI service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to Sales.Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
Answer: B
Explanation:
To use GitHub Copilot Chat effectively in this environment without exposing sensitive data, you should focus your prompts entirely on the schema and logic rather than the data itself.
Since Copilot Chat can "see" your open files, the best approach is to provide the table structures as DDL (Data Definition Language) statements or a simplified description.
Steps to generate the stored procedure:
Define the Schema: Open a new SQL file in your Codespace. Paste the CREATE TABLE scripts (without any data) for your two tables.
Prompt Copilot: Use the Chat view to request the procedure.
Example Prompt: "Based on the table definitions in my open file, write a T-SQL stored procedure that joins TableA and TableB on [Join Column]. Include logic to filter by [Parameter] and ensure no PII columns are included in the SELECT statement." Review for PII/Secrets: Before executing, manually verify that the generated code doesn't include hardcoded secrets or call PII columns you intended to omit.
Security Check: Because you are in a Codespace, ensure your .env files or connection strings are in your .gitignore so they aren't indexed by Copilot.
Reference:
https://github.com/orgs/community/discussions/141924
NEW QUESTION # 38
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: B
Explanation:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
NEW QUESTION # 39
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.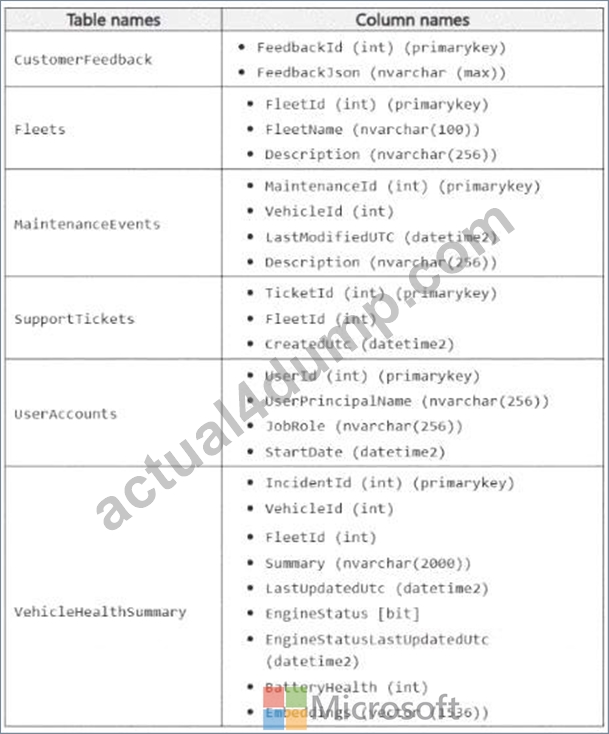
The FeedbackJson column has a full-text index and stores JSON documents in the following format.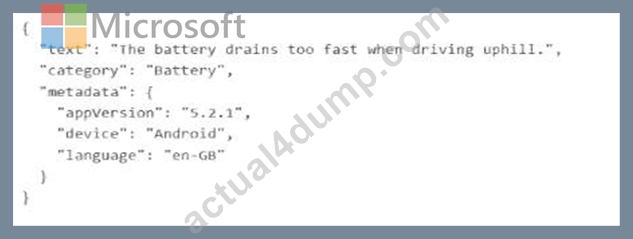
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
NEW QUESTION # 40
Hotspot Question
You have an Azure SQL managed instance that supports a gaming leaderboard API and contains a table named dbo.Leaderboard.
You plan to reduce write latency during peak events of dbo.Leaderboard.
You need to ensure that dbo.Leaderboard supports point lookups. The leaderboard information does NOT need to persist after a restart.
Which type of table and index should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.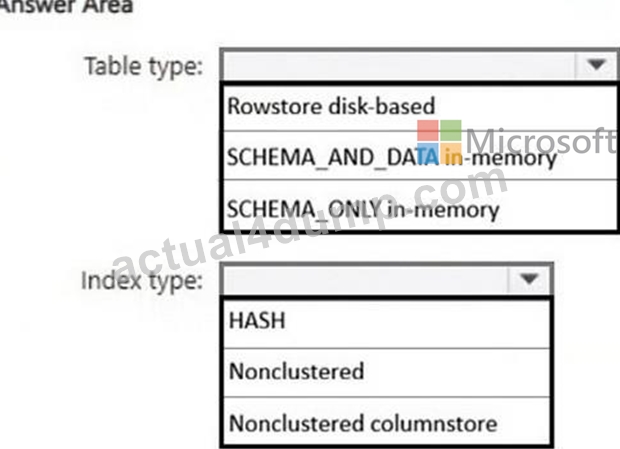
Answer:
Explanation: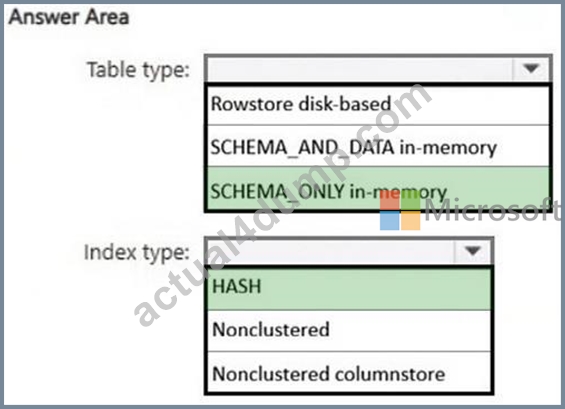
NEW QUESTION # 41
......
Our DP-800 prep torrent boosts the highest standards of technical accuracy and only use certificated subject matter and experts. We provide the latest and accurate DP-800 exam torrent to the client and the questions and the answers we provide are based on the real exam. We can promise to you the passing rate is high and about 98%-100%. Our DP-800 Test Braindumps also boosts high hit rate and can stimulate the exam to let you have a good preparation for the DP-800 exam. Your success is bound with our DP-800 exam questions.
DP-800 Exam Demo: https://www.actual4dump.com/Microsoft/DP-800-actualtests-dumps.html