進歩を遂げ、AI-200トレーニング資料の証明書を取得することは、当然のことながら、最新の最も正確な知識を指揮する最も専門的な専門家によるものです。それが、Developing AI Cloud Solutions on Azure試験準備が市場の大部分を占める理由です。それに、AI-200練習教材の利益を待つのではなく、支払い後すぐにダウンロードできるので、今すぐ成功への旅を始めましょう。
| Section | Objectives |
|---|---|
| Topic 1: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 4: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
CertJuken MicrosoftのAI-200試験問題集は完全な無制限のダンプが含まれていますから、CertJukenを利用したら気楽に試験に受かることができます。製品検定合格の証明書あるいは他の人気がある身分検定によって、CertJuken MicrosoftのAI-200試験トレーニング資料の長所を完璧に見せることができます。依頼だけでなく、指導のことも最高です。CertJuken MicrosoftのAI-200試験トレーニング資料に含まれている問題と解答を利用して、MicrosoftのAI-200認定試験に合格することができます。
質問 # 87
Drag and Drop Question
You are reviewing secret access patterns used by an AI application that retrieves credentials from Key Vault.
You need to evaluate the security impact of each implementation approach.
What is the outcome of each approach? To answer, move the appropriate outcomes to the correct implementations. You may use each outcome once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.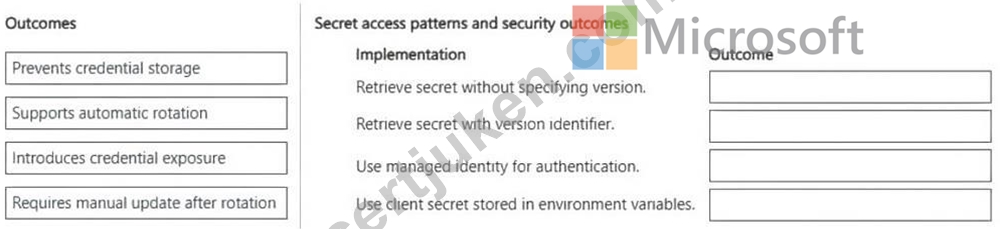
正解:
解説: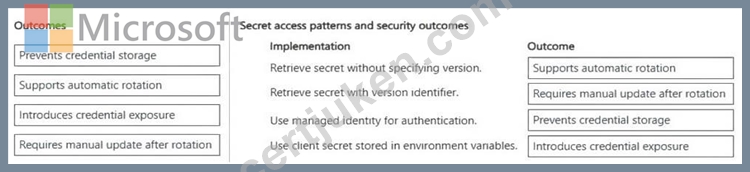
Explanation:
Box 1: Supports automatic rotation.
When an AI application retrieves a secret from Azure Key Vault without specifying a version, it always fetches the latest active version. This choice impacts your security and operations in the following ways:
Latest Version Fetch: The vault automatically serves the current active secret value.
No Code Changes: Your application reads the new credential immediately after rotation without a code redeployment.
Zero Downtime: Automated rotation pipelines can update the secret in Key Vault while the app seamlessly switches to the new token.
Box 2: Requires manual update after rotation
Using a specific version identifier when retrieving a secret from Key Vault means the application always requests one exact version of that secret. This choice requires manual update after rotation because the application code or configuration pins a specific version ID and will not fetch the new value when the secret rotates.
Box 3: Prevents credential storage
Prevents credential storage is the correct outcome of using managed identity for authentication.
No credentials to manage: Managed identities eliminate the need for developers to manage credentials entirely.
Automatic token handling: Azure automatically creates an identity for the application in Microsoft Entra ID and handles the service principal's lifecycle behind the scenes, ensuring that no secrets or connection strings are ever hardcoded or stored in configuration files.
Box 4: Introduces credential exposure
Introduces credential exposure and Requires manual update after rotation are the primary outcomes of storing a client secret in environment variables.
Storing clear-text secrets in environment variables poses a significant security risk. Any process, compromised dependency, or user with access to the execution environment (such as container details, application logs, or process dumps) can easily read them.
Reference:
https://medium.com/simform-engineering/building-automated-secret-rotation-using-azure-key-vault-and-net-01e0701f0a2e
https://www.varonis.com/blog/azure-managed-identities
質問 # 88
You provisioned an Azure Cosmos DB for NoSQL account named account1 with the default consistency level.
You plan to configure the consistency level on a per request basis. You plan to request Consistent Prefix consistency on a per-request basis.
You need to identify the resulting consistency level for read and write operations.
Which levels result from this configuration? To answer, select the appropriate options in the answer a rea.
NOTE: Each correct selection is worth one point.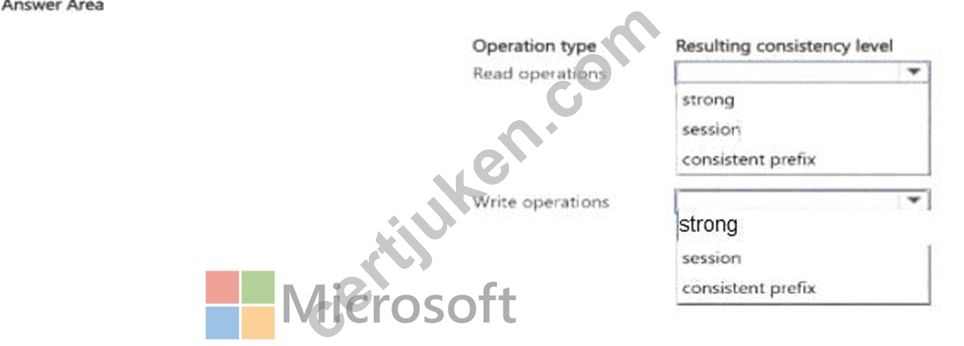
正解:
解説:
Explanation:
Verified answer: Read operations: Consistent Prefix. Write operations: Session (the account default remains effective for writes).
Detailed Explanation: Azure Cosmos DB allows a client or request to override consistency for reads.
Microsoft explicitly notes that such an override applies only to reads; it does not change how writes are committed and replicated under the account's configured consistency. Because a new account uses Session consistency by default, requesting Consistent Prefix affects the reads while the account continues to use its Session consistency behavior for writes. This distinction is the key point tested by the hotspot.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Manage Cosmos DB consistency levels | Cosmos DB consistency level choices
質問 # 89
You are designing a solution that will use two Azure Functions apps: App1 and App2. App1 is Windows based and will be deployed as code. App2 is Linux based and will be deployed as a container image.
Estimates show that the duration of the request processing for both apps will range from 1 to 10 minutes.
You plan to implement App1 and App2 by using the hosting plan to satisfy the following requirements:
* Request processing can complete within the estimated time range.
* The autoscaling behavior is event driven.
* The upper scaling limit is maximized.
You need to create the hosting plan for the implementation.
Which hosting plan should you create? To answer, move the appropriate hosting plans to the correct apps.
You may use each hosting plan once, more than once, or not at all. You may..
正解:
解説: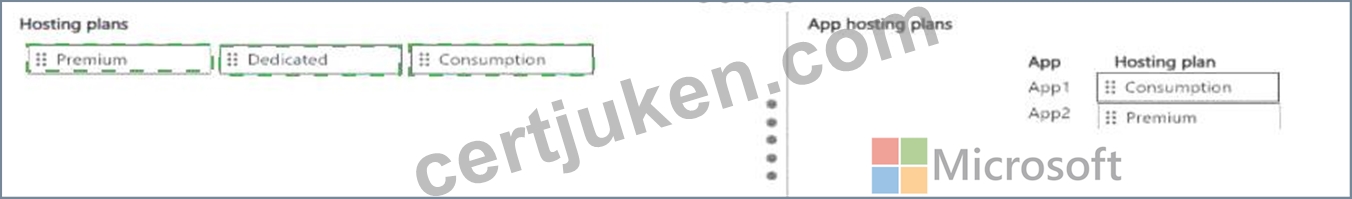
Explanation:
pp1: Consumption. App2: Premium.
Detailed Explanation: For App1, the Windows code-based Consumption plan satisfies event-driven autoscaling, allows execution up to the stated ten-minute range, and has the highest scaling ceiling among the listed event-driven choices for this workload. App2 is deployed as a Linux container image; among Premium, Dedicated, and Consumption, Premium is the event-driven plan that supports Linux containerized Functions and permits long-running execution. Dedicated hosting is not the requested event-driven autoscale model. The original Premium/Premium answer therefore did not maximize App1's upper scaling limit.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions scale and hosting
質問 # 90
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
正解:C
解説:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
質問 # 91
An application performs similarity search across 5 million embeddings stored in Azure Database for PostgreSQL with pgvector. Queries often filter by department before ranking by cosine distance.
P95 latency for vector similarity queries exceeds the SLA target. Monitoring shows sustained high CPU use during query execution.
You need to reduce P95 latency for filtered vector similarity queries.
What should you do?
正解:B
質問 # 92
......
AI-200試験ガイドには、高品質のサービスがあります。 24時間のオンラインサービスを提供しています。 AI-200試験問題の使用中に質問がある場合は、メールでお問い合わせください。 私たちMicrosoftは最大限の忍耐と態度で優れたアフターサービスを提供します。 そして、AI-200練習用トレントの使用中に発生する問題に対する詳細な解決策を提供します。 そして、AI-200の学習資料は、あなたの監督と批判を歓迎します。 私たちのAI-200学習教材の会社で、あなたはDeveloping AI Cloud Solutions on Azure成功の方向を見つけるでしょう。
AI-200受験記: https://www.certjuken.com/AI-200-exam.html