DY0-001一発合格 & DY0-001参考資料

さらに、Topexam DY0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1HUsSyEDadH7ZTjdX4l-EenJivgZzQaR9
市場の他の教育プラットフォームと比較して、Topexamはより信頼性が高く、非常に効率的です。これは、DY0-001試験に合格したい受験者に高い合格率DY0-001の教材を提供し、すべてのお客様が最初の試行でDY0-001試験に合格しています。ウェブサイトでDY0-001試験に合格するには、20〜30時間かかります。それは本当に他のことをするために多くの時間とエネルギーを節約するのを助けることができる非常に効率的な試験ツールです。
CompTIA DY0-001 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| トピック 2 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| トピック 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| トピック 4 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| トピック 5 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
>> DY0-001一発合格 <<
DY0-001参考資料、DY0-001復習教材
DY0-001試験の練習問題の核となる競争力は、ユーザーが見ることができるように、私たちには強力な専門家チームがあり、DY0-001学習資料はリアルタイムで更新されています。ユーザーフィードバックの推奨事項により、DY0-001ラーニングガイドには現在小さな問題があるという結論に達しました。残りの会社の開発計画では、サービスに対する認識を強化し、ユーザーがより満足できるようにします。 DY0-001の学習教材は、短期間の高額販売ではなく、お客様と長期にわたって維持したいと考えています。
CompTIA DataAI Certification Exam 認定 DY0-001 試験問題 (Q79-Q84):
質問 # 79
A data scientist trained a model for departments to share. The departments must access the model using HTTP requests. Which of the following approaches is appropriate?
- A. Create an endpoint.
- B. Use the File Transfer Protocol.
- C. Deploy containers.
- D. Utilize distributed computing.
正解:A
解説:
Exposing the model behind an HTTP endpoint (for example, a REST API) allows other departments to send requests and receive predictions directly over HTTP. The other options don't inherently provide a request-response interface for sharing a model.
質問 # 80
A data scientist is designing a real-time machine-learning model that classifies a user based on initial behavior. The run times of these models are provided in the following table:
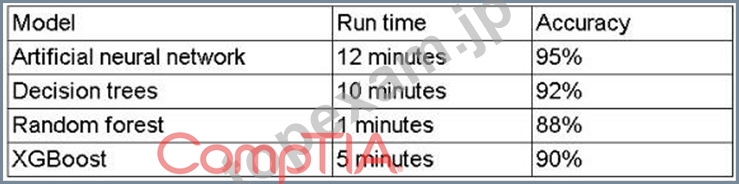
Which of the following models should the data scientist recommend for deployment?
- A. Random forest
- B. Decision trees
- C. Artificial neural network
- D. XGBoost
正解:A
解説:
For a real-time application, inference latency is critical. Although its accuracy (88%) is slightly lower than the others, the random forest's 1-minute run time is by far the fastest, making it the only model capable of meeting real-time responsiveness.
質問 # 81
Which of the following issues should a data scientist be most concerned about when generating a synthetic data set?
- A. The data set not being representative of the population
- B. The data set having insufficient row observations
- C. The data set having insufficient features
- D. The data set consuming too many resources
正解:A
解説:
If synthetic data don't accurately mirror the real-world distributions and relationships, any models trained on them will perform poorly in deployment. Representativeness is the critical concern when generating synthetic data.
質問 # 82
A data scientist needs to analyze a company's chemical businesses and is using the master database of the conglomerate company. Nothing in the data differentiates the data observations for the different businesses.
Which of the following is the most efficient way to identify the chemical businesses' observations?
- A. Perform analysis on all of the data and create a summary report on the results relevant to chemical operations.
- B. Ingest the data from all of the hard drives and perform exploratory data analysis to identify which business is responsible for chemical operations.
- C. Ingest data from the hard drive containing the most data and present sample results on the chemicaloperations.
- D. Consult with the business team to identify which sites are responsible for chemical operations and ingest only the relevant data for analysis.
正解:D
解説:
# The most efficient and practical approach is to consult the business stakeholders to understand which sites or data partitions relate to chemical operations. This avoids unnecessary processing of irrelevant data and aligns with the data science best practice of combining domain knowledge with technical methods.
Why the other options are incorrect:
* A: Ingesting all data without guidance is time- and resource-intensive.
* B: Analyzing all data indiscriminately can dilute the focus on chemical business specifics.
* D: Using the largest data set arbitrarily may not reflect chemical operations and lacks targeted relevance.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.1:"Collaboration with domain experts and stakeholders ensures the data scientist focuses on relevant sources and minimizes inefficiency in data preparation."
* CRISP-DM Model - Business Understanding Phase:"Clarifying project objectives with business input is key to aligning data selection with analytical goals."
-
質問 # 83
A team is building a spam detection system. The team wants a probability-based identification method without complex, in-depth training from the historical data set. Which of the following methods would best serve this purpose?
- A. Naive Bayes
- B. Logistic regression
- C. Linear regression
- D. Random forest
正解:A
解説:
# Naive Bayes is a probabilistic classification algorithm based on Bayes' theorem. It is lightweight, fast, and effective for text-based classification problems like spam detection. It also performs well with small or simple training sets.
Why the other options are incorrect:
* A: Logistic regression is also probabilistic but requires more feature preprocessing.
* B: Random forest is accurate but computationally heavier.
* D: Linear regression is for continuous targets - not suitable for classification.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1:"Naive Bayes classifiers are ideal for spam detection and similar applications due to their efficiency and probabilistic nature."
* Text Classification Techniques, Chapter 4:"Naive Bayes requires minimal training and works well with high-dimensional, sparse data such as email content."
質問 # 84
......
最近、CompTIA DY0-001試験に合格するのは重要な課題になっています。同時に、DY0-001資格認証を受け入れるのは傾向になります。DY0-001試験に参加したい、我々TopexamのDY0-001練習問題を参考しましょう。弊社は1年間の無料更新サービスを提供いたします。あなたがご使用になっているとき、何か質問がありましたらご遠慮なく弊社とご連絡ください。
DY0-001参考資料: https://www.topexam.jp/DY0-001_shiken.html
- 無料DY0-001一発合格 - 保証するCompTIA DY0-001 完璧な試験の成功DY0-001参考資料 🛐 ウェブサイト➡ www.it-passports.com ️⬅️を開き、☀ DY0-001 ️☀️を検索して無料でダウンロードしてくださいDY0-001受験資格
- 実際的なDY0-001一発合格試験-試験の準備方法-更新するDY0-001参考資料 ☂ ▛ www.goshiken.com ▟を開き、➤ DY0-001 ⮘を入力して、無料でダウンロードしてくださいDY0-001出題内容
- DY0-001試験の準備方法|効果的なDY0-001一発合格試験|ハイパスレートのCompTIA DataAI Certification Exam参考資料 🪐 ➽ www.mogiexam.com 🢪には無料の➤ DY0-001 ⮘問題集がありますDY0-001問題無料
- DY0-001全真模擬試験 ✔ DY0-001全真模擬試験 ⛑ DY0-001技術問題 ⛹ ウェブサイト《 www.goshiken.com 》から▷ DY0-001 ◁を開いて検索し、無料でダウンロードしてくださいDY0-001関連問題資料
- CompTIA DY0-001 Exam | DY0-001一発合格 - パスを助ける DY0-001: CompTIA DataAI Certification Exam 試験 🍽 ➽ www.japancert.com 🢪を開き、✔ DY0-001 ️✔️を入力して、無料でダウンロードしてくださいDY0-001問題トレーリング
- ユニークなDY0-001一発合格一回合格-信頼的なDY0-001参考資料 🔼 ⏩ www.goshiken.com ⏪の無料ダウンロード✔ DY0-001 ️✔️ページが開きますDY0-001技術問題
- DY0-001日本語解説集 💥 DY0-001日本語版参考書 🏵 DY0-001日本語版参考書 🤵 ▶ www.goshiken.com ◀は、➤ DY0-001 ⮘を無料でダウンロードするのに最適なサイトですDY0-001問題無料
- 実用的-最新のDY0-001一発合格試験-試験の準備方法DY0-001参考資料 ➡️ 最新▷ DY0-001 ◁問題集ファイルは➡ www.goshiken.com ️⬅️にて検索DY0-001関連問題資料
- DY0-001日本語解説集 🏟 DY0-001日本語版参考書 🗣 DY0-001模擬試験問題集 🐓 【 www.it-passports.com 】で▛ DY0-001 ▟を検索して、無料で簡単にダウンロードできますDY0-001関連問題資料
- 実用的-最新のDY0-001一発合格試験-試験の準備方法DY0-001参考資料 🍩 今すぐ▛ www.goshiken.com ▟を開き、▛ DY0-001 ▟を検索して無料でダウンロードしてくださいDY0-001日本語版参考書
- DY0-001学習教材 🛥 DY0-001模擬試験問題集 🚒 DY0-001専門知識内容 🤐 { www.jptestking.com }の無料ダウンロード[ DY0-001 ]ページが開きますDY0-001試験感想
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, pastebin.com, Disposable vapes
ちなみに、Topexam DY0-001の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1HUsSyEDadH7ZTjdX4l-EenJivgZzQaR9