P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1UIYfpUWEJVVBPP0BQnwrOFolV0xXIFhj
Our Databricks-Generative-AI-Engineer-Associate questions pdf is up to date, and we provide user-friendly Databricks-Generative-AI-Engineer-Associate practice test software for the Databricks-Generative-AI-Engineer-Associate exam. Moreover, we are also providing money back guarantee on all of Databricks-Generative-AI-Engineer-Associate test products. If the Databricks-Generative-AI-Engineer-Associate braindumps products fail to deliver as promised, then you can get your money back. The Databricks-Generative-AI-Engineer-Associate Sample Questions include all the files you need to prepare for the Databricks-Generative-AI-Engineer-Associate exam. With the help of the Databricks-Generative-AI-Engineer-Associate practice exam questions and test software, you will be able to feel the real Databricks-Generative-AI-Engineer-Associate exam scenario, and it will allow you to assess your skills.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Available Languages: | English |
| Exam Format: | Multiple select, Multiple choice |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 45-60 |
| Exam Price: | USD 200 |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> New Braindumps Databricks Databricks-Generative-AI-Engineer-Associate Book <<
To give you an idea about the top features of Actual4Cert Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam questions, a free demo of Actual4Cert Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam dumps is being offered free of cost. Just download Actual4Cert Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam questions demo and checks out the top features of Actual4Cert Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam dumps. If you feel that Actual4Cert Databricks Databricks-Generative-AI-Engineer-Associate exam questions work for you then buy the full and final Actual4Cert Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam dumps at an affordable price and start Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam preparation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 56
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
Answer: A
Explanation:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states: "For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses." This matches Option C's approach of finding answers and summarizing them.
Option D: Input: Customer reviews; Output: Classify review sentiment
This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context. It's more suited for feedback analysis than real-time customer service.
Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
NEW QUESTION # 57
A Generative AI Engineer is creating an agent-based LLM system for their favorite monster truck team. The system can answer text based questions about the monster truck team, lookup event dates via an API call, or query tables on the team's latest standings.
How could the Generative AI Engineer best design these capabilities into their system?
Answer: A
Explanation:
In this scenario, the Generative AI Engineer needs to design a system that can handle different types of queries about the monster truck team. The queries may involve text-based information, API lookups for event dates, or table queries for standings. The best solution is to implement a tool-based agent system .
Here's how option B works, and why it's the most appropriate answer:
* System Design Using Agent-Based Model : In modern agent-based LLM systems, you can design a system where the LLM (Large Language Model) acts as a central orchestrator. The model can " decide
" which tools to use based on the query. These tools can include API calls, table lookups, or natural language searches. The system should contain a system prompt that informs the LLM about the available tools.
* System Prompt Listing Tools : By creating a well-crafted system prompt , the LLM knows which tools are at its disposal. For instance, one tool may query an external API for event dates, another might look up standings in a database, and a third may involve searching a vector database for general text- based information. The agent will be responsible for calling the appropriate tool depending on the query.
* Agent Orchestration of Calls : The agent system is designed to execute a series of steps based on the incoming query. If a user asks for the next event date, the system will recognize this as a task that requires an API call. If the user asks about standings, the agent might query the appropriate table in the database. For text-based questions, it may call a search function over ingested data. The agent orchestrates this entire process, ensuring the LLM makes calls to the right resources dynamically.
* Generative AI Tools and Context : This is a standard architecture for integrating multiple functionalities into a system where each query requires different actions. The core design in option B is efficient because it keeps the system modular and dynamic by leveraging tools rather than overloading the LLM with static information in a system prompt (like option D).
* Why Other Options Are Less Suitable :
* A (RAG Architecture) : While relevant, simply ingesting PDFs into a vector store only helps with text-based retrieval. It wouldn't help with API lookups or table queries.
* C (Conditional Logic with RAG/API/TABLE) : Although this approach works, it relies heavily on manual text parsing and might introduce complexity when scaling the system.
* D (System Prompt with Event Dates and Standings) : Hardcoding dates and table information into a system prompt isn't scalable. As the standings or events change, the system would need constant updating, making it inefficient.
By bundling multiple tools into a single agent-based system (as in option B), the Generative AI Engineer can best handle the diverse requirements of this system.
NEW QUESTION # 58
A Generative Al Engineer is creating an LLM-based application. The documents for its retriever have been chunked to a maximum of 512 tokens each. The Generative Al Engineer knows that cost and latency are more important than quality for this application. They have several context length levels to choose from.
Which will fulfill their need?
Answer: C
Explanation:
When prioritizing cost and latency over quality in a Large Language Model (LLM)-based application, it is crucial to select a configuration that minimizes both computational resources and latency while still providing reasonable performance. Here's whyDis the best choice:
* Context length: The context length of 512 tokens aligns with the chunk size used for the documents (maximum of 512 tokens per chunk). This is sufficient for capturing the needed information and generating responses without unnecessary overhead.
* Smallest model size: The model with a size of 0.13GB is significantly smaller than the other options.
This small footprint ensures faster inference times and lower memory usage, which directly reduces both latency and cost.
* Embedding dimension: While the embedding dimension of 384 is smaller than the other options, it is still adequate for tasks where cost and speed are more important than precision and depth of understanding.
This setup achieves the desired balance between cost-efficiency and reasonable performance in a latency- sensitive, cost-conscious application.
NEW QUESTION # 59
A Generative Al Engineer is building a system that will answer questions on currently unfolding news topics.
As such, it pulls information from a variety of sources including articles and social media posts. They are concerned about toxic posts on social media causing toxic outputs from their system.
Which guardrail will limit toxic outputs?
Answer: A
Explanation:
The system answers questions on unfolding news topics using articles and social media, with a concern about toxic outputs from toxic inputs. A guardrail must limit toxicity in the LLM's responses. Let's evaluate the options.
* Option A: Use only approved social media and news accounts to prevent unexpected toxic data from getting to the LLM
* Curating input sources (e.g., verified accounts) reduces exposure to toxic content at the data ingestion stage, directly limiting toxic outputs. This is a proactive guardrail aligned with data quality control.
* Databricks Reference:"Control input data quality to mitigate unwanted LLM behavior, such as toxicity"("Building LLM Applications with Databricks," 2023).
* Option B: Implement rate limiting
* Rate limiting controls request frequency, not content quality. It prevents overload but doesn't address toxicity in social media inputs or outputs.
* Databricks Reference: Rate limiting is for performance, not safety:"Use rate limits to manage compute load"("Generative AI Cookbook").
* Option C: Reduce the amount of context items the system will include in consideration for its response
* Reducing context might limit exposure to some toxic items but risks losing relevant information, and it doesn't specifically target toxicity. It's an indirect, imprecise fix.
* Databricks Reference: Context reduction is for efficiency, not safety:"Adjust context size based on performance needs"("Databricks Generative AI Engineer Guide").
* Option D: Log all LLM system responses and perform a batch toxicity analysis monthly
* Logging and analyzing responses is reactive, identifying toxicity after it occurs rather than preventing it. Monthly analysis doesn't limit real-time toxic outputs.
* Databricks Reference: Monitoring is for auditing, not prevention:"Log outputs for post-hoc analysis, but use input filters for safety"("Building LLM-Powered Applications").
Conclusion: Option A is the most effective guardrail, proactively filtering toxic inputs from unverified sources, which aligns with Databricks' emphasis on data quality as a primary safety mechanism for LLM systems.
NEW QUESTION # 60
A Generative AI Engineer I using the code below to test setting up a vector store: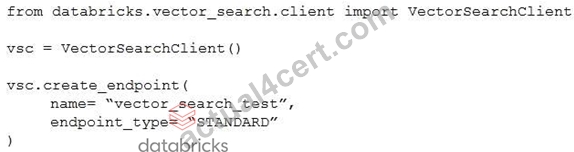
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 61
......
Databricks-Generative-AI-Engineer-Associate Reliable Study Guide: https://www.actual4cert.com/Databricks-Generative-AI-Engineer-Associate-real-questions.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1UIYfpUWEJVVBPP0BQnwrOFolV0xXIFhj