Databricks-Certified-Data-Engineer-Associate Latest Training, Databricks-Certified-Data-Engineer-Associate Latest Exam Papers

P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1ze-26_x0NeUKKtardrw9prTNM9Laxs1w
There are a lof of the advantages for you to buy our Databricks-Certified-Data-Engineer-Associate exam questions safely. First, our Databricks-Certified-Data-Engineer-Associate study braindumps are free from computer virus. You can download or install our Databricks-Certified-Data-Engineer-Associate study material without hesitation. Second, we will protect your private information. No other person or company will get your information from us. You won't get any telephone harassment or receiving junk E-mails after purchasing our Databricks-Certified-Data-Engineer-Associate training guide. You don't have to worry about anything with our Databricks-Certified-Data-Engineer-Associate learning quiz.
To become certified as a Databricks data engineer associate, individuals must pass a rigorous certification exam that tests their knowledge and understanding of Databricks technologies and their ability to apply them in practical situations. Databricks-Certified-Data-Engineer-Associate Exam is designed to be challenging and requires individuals to have a deep understanding of data engineering concepts and technologies. However, individuals who successfully pass the exam can enjoy the benefits of becoming a certified Databricks data engineer associate and take their careers to the next level in the field of data engineering.
>> Databricks-Certified-Data-Engineer-Associate Latest Training <<
Dumpkiller Databricks Databricks-Certified-Data-Engineer-Associate Desktop-based Practice Test Software
In addition to the advantages of high quality, our Databricks-Certified-Data-Engineer-Associate exam questions also provide various versions. In order to meet your personal habits, you can freely choose any version of our Databricks-Certified-Data-Engineer-Associate study materials within PDF, APP or PC version. Among them, the PDF version is most suitable for candidates who prefer paper materials, because it supports printing. And our PDF version of the Databricks-Certified-Data-Engineer-Associate training guide can be carried with you for it takes on place.
Databricks Databricks-Certified-Data-Engineer-Associate Exam Syllabus Topics:
| Topic | Details |
|---|
| Topic 1 | - ELT with Apache Spark: It focuses on extracting data, identifying the prefix, creating a view, duplicating rows, creating a new table, utilizing the dot, parsing JSON, and defining a SQL UDF. Moreover, the topic delves into describing the security model, identifying the location of a function, and identifying the PIVOT.
|
| Topic 2 | - Production Pipelines: It focuses on identifying the advantages of using multiple tasks in Jobs, a suitable scenario where predecessor task should be set up, CRON as an opportunity for scheduling opportunity, and how an alert can be sent via email. The topic also discusses setting up a predecessor task in Jobs, reviewing a task's execution history, and debugging a failed task. Lastly, it delves into setting up a retry policy in case of failure and creating an alert in the case of a failed task.
|
| Topic 3 | - Incremental Data Processing: In this topic questions about identifying Delta Lake, benefits of ACID transactions, a scenario to use an external table, location of a table, the benefits of Zordering, the kind of files, CTAS as a solution, the impact of ON VIOLATION DROP ROW and ON VIOLATION FAIL UPDATE, and the necessary component to create a new DLT pipeline. Moreover, the topic also discusses directory structure of Delta Lake files, generated column, adding a table comment, and the benefits of the MERGE command.
|
| Topic 4 | - Databricks Lakehouse Platform: This topic covers the relationship between the data lakehouse and the data warehouse, the improvement in data quality, comparing and contrasting silver and gold tables, elements of the Databricks Platform Architecture, and differentiating between all-purpose clusters and jobs clusters. Moreover, it identifies how cluster software is versioned, how clusters can be filtered, how to use multiple languages, how to run one notebook, how notebooks can be shared, Git operations, and limitations in Databricks Notebooks. Lastly, the topic describes how clusters are terminated, how to use multiple languages, and how Databricks Repos enables CI
- CD workflows.
|
| Topic 5 | - Data Governance: It identifies one of the four areas of data governance, Unity Catalog securables, and the cluster security modes. It also discusses how to create a UC-enabled all-purpose cluster and a DBSQL warehouse. The topic explains how to implement data object access control, create a DBSQL warehouse, and e a UC-enabled all-purpose cluster.
|
The Databricks Databricks-Certified-Data-Engineer-Associate Exam consists of 60 multiple-choice questions that must be completed in 90 minutes. The passing score for the exam is 70%, and candidates who pass the exam will receive a certificate that validates their knowledge and expertise in Databricks. Databricks Certified Data Engineer Associate Exam certification is recognized globally and is a valuable asset for data engineers who want to advance their careers and demonstrate their proficiency in Databricks.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q45-Q50):
NEW QUESTION # 45
A data engineer is using the Databricks OPTIMIZE command on a Delta table. What happens when OPTIMIZE is run twice on the same table with the same data?
- A. It changes the number of tuples per file significantly.
- B. It triggers a full liquid clustering process.
- C. It further reduces file sizes by re-clustering the data.
- D. It has no effect because it is idempotent.
Answer: D
Explanation:
The OPTIMIZE command is idempotent - running it again on the same Delta table with unchanged data has no additional effect, since the files are already compacted.
NEW QUESTION # 46
An organization has implemented a data pipeline in Databricks and needs to ensure it can scale automatically based on varying workloads without manual cluster management. The goal is to meet the company's Service Level Agreements (SLAs), which require high availability and minimal downtime, while Databricks automatically handles resource allocation and optimization.
Which approach fulfills these requirements?
- A. Use Serverless compute in Databricks to automatically scale and provision resources with minimal manual intervention
- B. Deploy job clusters with fixed configurations, dedicated to specific tasks, without automatic scaling
- C. Use spot instances to allocate resources dynamically while minimizing costs, with potential interruptions
- D. Use interactive clusters in Databricks, adjusting cluster sizes manually based on workload demands
Answer: A
Explanation:
Databricks documentation recommends serverless compute as the simplest and most reliable compute option when the workload is supported. Serverless compute is designed to automatically provision resources, scale with demand, reduce infrastructure management, and apply platform optimizations without requiring users to configure clusters manually. This directly supports the requirement for automatic scaling, reduced operational overhead, and better alignment with strict SLAs. Databricks also states that serverless compute is always available and scales according to workload, making it a strong fit for organizations seeking high availability and minimal downtime. Fixed-configuration job clusters in option B still require manual sizing decisions and do not meet the "no manual cluster management" requirement. Spot instances in option C may reduce costs but can be interrupted, which makes them a poor choice when reliability is a top requirement.
Interactive clusters in option D are intended more for development and exploration and still need manual management. Based on Databricks guidance, serverless compute is the correct choice.
=========
NEW QUESTION # 47
A data engineer needs to create a table in Databricks using data from a CSV file at location /path/to/csv.
They run the following command:
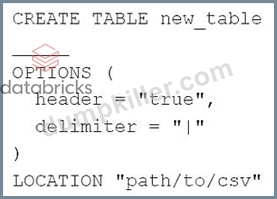
Which of the following lines of code fills in the above blank to successfully complete the task?
- A. USING DELTA
- B. None of these lines of code are needed to successfully complete the task
- C. USING CSV
- D. FROM CSV
- E. FROM "path/to/csv"
Answer: E
Explanation:
A data lakehouse is a new paradigm that can be used to simplify and unify siloed data architectures that are specialized for specific use cases. A data lakehouse combines the best of both data lakes and data warehouses, providing a single platform that supports diverse data types, open standards, low-cost storage, high-performance queries, ACID transactions, schema enforcement, and governance. A data lakehouse enables data engineers to build reliable and scalable data pipelines that can serve various downstream applications and users, such as data science, machine learning, analytics, and reporting. A data lakehouse leverages the power of Delta Lake, a storage layer that brings reliability and performance to data lakes. Reference: What is a data lakehouse?, Delta Lake, Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics
NEW QUESTION # 48
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
- A. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.
- B. All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.
- C. All datasets will be updated once and the pipeline will persist without any processing. The compute resources will persist but go unused.
- D. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will be deployed for the update and terminated when the pipeline is stopped.
- E. All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.
Answer: A
Explanation:
Explanation
In a Delta Live Table pipeline running in Continuous Pipeline Mode, when you click Start to update the pipeline, the following outcome is expected: All datasets defined using STREAMING LIVE TABLE and LIVE TABLE against Delta Lake table sources will be updated at set intervals. The compute resources will be deployed for the update process and will be active during the execution of the pipeline. The compute resources will be terminated when the pipeline is stopped or shut down. This mode allows for continuous and periodic updates to the datasets as new data arrives or changes in the underlying Delta Lake tables occur. The compute resources are provisioned and utilized during the update intervals to process the data and perform the necessary operations.
NEW QUESTION # 49
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
Answer: C
Explanation:
To allow a group to create tables in a schema with least privileges, they need:
- GRANT CREATE TABLE on the schema
- GRANT USE SCHEMA on the schema
- GRANT USE CATALOG on the parent catalog
This ensures proper access without granting unnecessary privileges like creating schemas or catalogs.
NEW QUESTION # 50
......
Databricks-Certified-Data-Engineer-Associate Latest Exam Papers: https://www.dumpkiller.com/Databricks-Certified-Data-Engineer-Associate_braindumps.html
- Free PDF Databricks-Certified-Data-Engineer-Associate - Databricks Certified Data Engineer Associate Exam –Professional Latest Training 🐹 Download 「 Databricks-Certified-Data-Engineer-Associate 」 for free by simply entering ☀ www.testkingpass.com ️☀️ website 🏂Databricks-Certified-Data-Engineer-Associate Valid Exam Cram
- The Best Databricks-Certified-Data-Engineer-Associate Latest Training - Complete Databricks-Certified-Data-Engineer-Associate Exam Tool Guarantee Purchasing Safety 👺 Search for ▷ Databricks-Certified-Data-Engineer-Associate ◁ on { www.pdfvce.com } immediately to obtain a free download 💐Databricks-Certified-Data-Engineer-Associate Mock Exam
- Test Databricks-Certified-Data-Engineer-Associate Tutorials 🦛 Verified Databricks-Certified-Data-Engineer-Associate Answers 🚴 Databricks-Certified-Data-Engineer-Associate Valid Study Notes 💺 Open [ www.exam4labs.com ] and search for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ to download exam materials for free 🌒Databricks-Certified-Data-Engineer-Associate Training Solutions
- Valid Test Databricks-Certified-Data-Engineer-Associate Bootcamp 💎 Databricks-Certified-Data-Engineer-Associate Mock Exam 🧤 Updated Databricks-Certified-Data-Engineer-Associate Test Cram 💜 Download ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ for free by simply entering ➤ www.pdfvce.com ⮘ website 📙Test Databricks-Certified-Data-Engineer-Associate Dumps
- Free PDF 2026 Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam Accurate Latest Training 🦺 Search on ☀ www.prep4away.com ️☀️ for ▛ Databricks-Certified-Data-Engineer-Associate ▟ to obtain exam materials for free download 👛Databricks-Certified-Data-Engineer-Associate Latest Test Fee
- Valid Databricks-Certified-Data-Engineer-Associate Exam Simulator 🎉 Test Databricks-Certified-Data-Engineer-Associate Dumps 🐖 Databricks-Certified-Data-Engineer-Associate Valid Exam Cram 🐖 Go to website ➠ www.pdfvce.com 🠰 open and search for ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ to download for free 🦧Databricks-Certified-Data-Engineer-Associate Reliable Dumps Book
- 100% Pass-Rate Databricks-Certified-Data-Engineer-Associate Latest Training - Pass Databricks-Certified-Data-Engineer-Associate Exam 😍 Search for ▶ Databricks-Certified-Data-Engineer-Associate ◀ and download it for free on ▷ www.practicevce.com ◁ website 📯VCE Databricks-Certified-Data-Engineer-Associate Dumps
- Databricks-Certified-Data-Engineer-Associate Valid Torrent ❓ PDF Databricks-Certified-Data-Engineer-Associate VCE 〰 Valid Databricks-Certified-Data-Engineer-Associate Exam Simulator 🍒 Open ➤ www.pdfvce.com ⮘ enter 「 Databricks-Certified-Data-Engineer-Associate 」 and obtain a free download 🔡Databricks-Certified-Data-Engineer-Associate Latest Study Materials
- Databricks-Certified-Data-Engineer-Associate Valid Torrent 🔻 Databricks-Certified-Data-Engineer-Associate Mock Exam 🍔 Databricks-Certified-Data-Engineer-Associate Latest Exam Test 🥒 Go to website [ www.dumpsquestion.com ] open and search for ▶ Databricks-Certified-Data-Engineer-Associate ◀ to download for free 🙈Databricks-Certified-Data-Engineer-Associate Latest Exam Test
- Latest Databricks-Certified-Data-Engineer-Associate Study Notes 👠 Databricks-Certified-Data-Engineer-Associate Valid Torrent ☀ Databricks-Certified-Data-Engineer-Associate Latest Exam Test 🏣 Search on [ www.pdfvce.com ] for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ to obtain exam materials for free download 🔊Databricks-Certified-Data-Engineer-Associate Training Solutions
- Databricks-Certified-Data-Engineer-Associate Valid Study Notes 🚊 Test Databricks-Certified-Data-Engineer-Associate Tutorials ♻ Databricks-Certified-Data-Engineer-Associate Latest Study Materials 🚂 Download { Databricks-Certified-Data-Engineer-Associate } for free by simply searching on ✔ www.troytecdumps.com ️✔️ 🤒Test Databricks-Certified-Data-Engineer-Associate Tutorials
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of Dumpkiller Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1ze-26_x0NeUKKtardrw9prTNM9Laxs1w