P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by PremiumVCEDump: https://drive.google.com/open?id=1mNl7oz3eLKdulcEwFfNfb-RlB09VDLGm
How can you pass your exam and get your certificate in a short time? Our DP-100 exam torrent will be your best choice to help you achieve your aim. According to customers’ needs, our product was revised by a lot of experts; the most functions of our Designing and Implementing a Data Science Solution on Azure exam dumps are to help customers save more time, and make customers relaxed. If you choose to use our DP-100 Test Quiz, you will find it is very easy for you to pass your exam in a short time. You just need to spend 20-30 hours on studying; you will have more free time to do other things.
| Schedule Exam | Pearson VUE |
| Books / Training | DP-100T01-A: Designing and Implementing a Data Science Solution on Azure |
| Number of Questions | 40-60 |
| Passing Score | 700 / 1000 |
| Duration | 120 mins |
| Exam Price | $165 (USD) |
>> DP-100 Exam Lab Questions <<
It is our biggest goal to try to get every candidate through the exam. Although the passing rate of our DP-100 simulating exam is nearly 100%, we can refund money in full if you are still worried that you may not pass the DP-100 exam. You don't need to worry about the complexity of the refund process at all, we've made it quite simple. And if you really want to pass the exam instead of refund, you can wait for our updates for we will update our DP-100 Study Guide for sure to make you pass the exam.
As for the exam format, there are usually about 40-60 multiple-choice, active screen, best answer, hot area, build lists, labs, mark review and other question styles. You are expected to complete them in 3 hours. The passing score is 700 out of 1000 maximum possible points. The test is available in the following languages: English, Japanese, Korean, and Chinese (Simplified). To schedule your test, you should first pay the registration fee of $165 and go to the Pearson VUE platform to create an account. Once you log in, choose the “Proctored Exams” section and enter ‘DP-100' as the exam code. Follow the prompts to complete registration. At this stage, you can choose to take your test offline or online. Notice, though, that if you don't succeed on the first try, you'll be required to pay the enrollment fee for the next attempt as well.
NEW QUESTION # 299
You plan to use automated machine learning to train a regression model. You have data that has features which have missing values, and categorical features with few distinct values.
You need to configure automated machine learning to automatically impute missing values and encode categorical features as part of the training task.
Which parameter and value pair should you use in the AutoMLConfig class?
Answer: D
Explanation:
Featurization str or FeaturizationConfig
Values: 'auto' / 'off' / FeaturizationConfig
Indicator for whether featurization step should be done automatically or not, or whether customized featurization should be used.
Column type is automatically detected. Based on the detected column type preprocessing/featurization is done as follows:
Categorical: Target encoding, one hot encoding, drop high cardinality categories, impute missing values.
Numeric: Impute missing values, cluster distance, weight of evidence.
DateTime: Several features such as day, seconds, minutes, hours etc.
Text: Bag of words, pre-trained Word embedding, text target encoding.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-automl-
client/azureml.train.automl.automlconfig.automlconfig
NEW QUESTION # 300
You publish a batch inferencing pipeline that will be used by a business application.
The application developers need to know which information should be submitted to and returned by the REST interface for the published pipeline.
You need to identify the information required in the REST request and returned as a response from the published pipeline.
Which values should you use in the REST request and to expect in the response? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.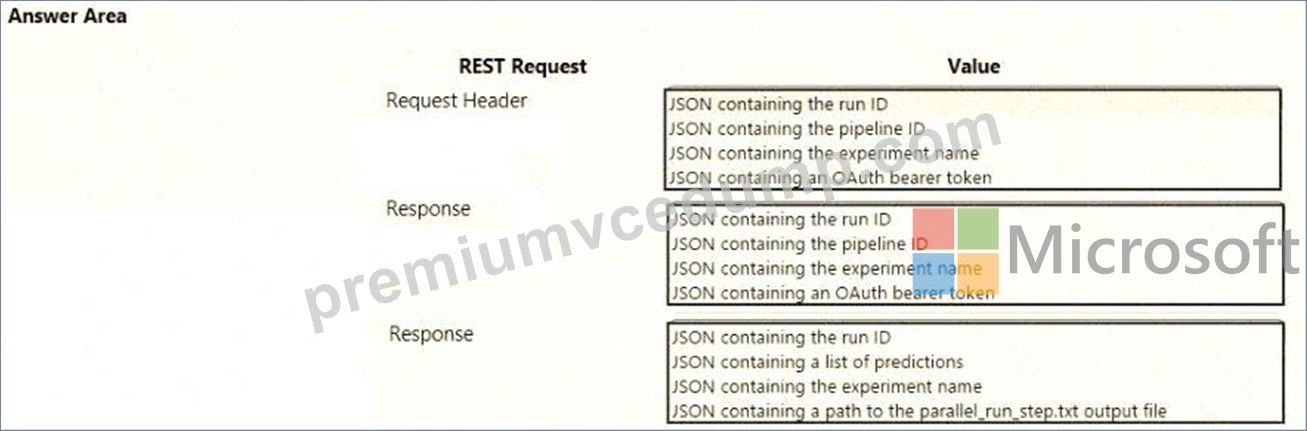
Answer:
Explanation: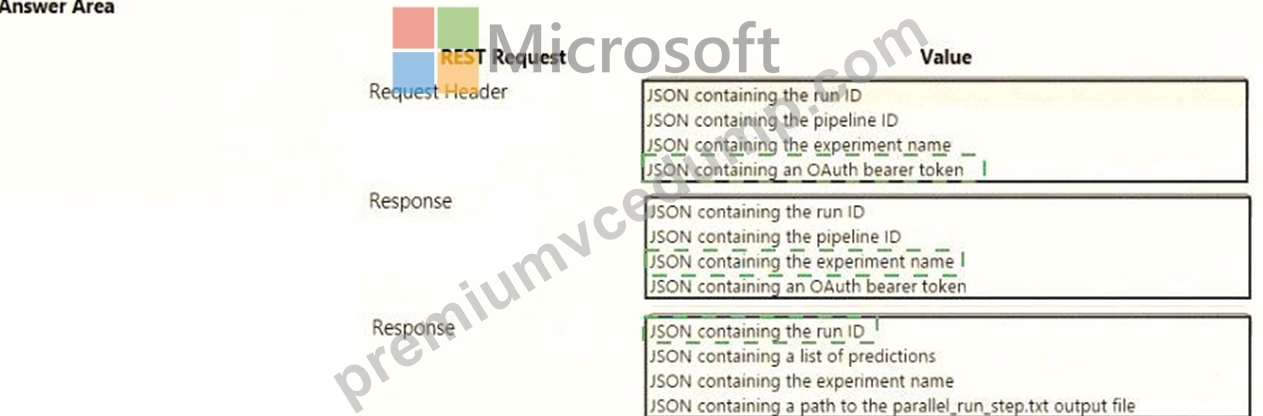
Explanation: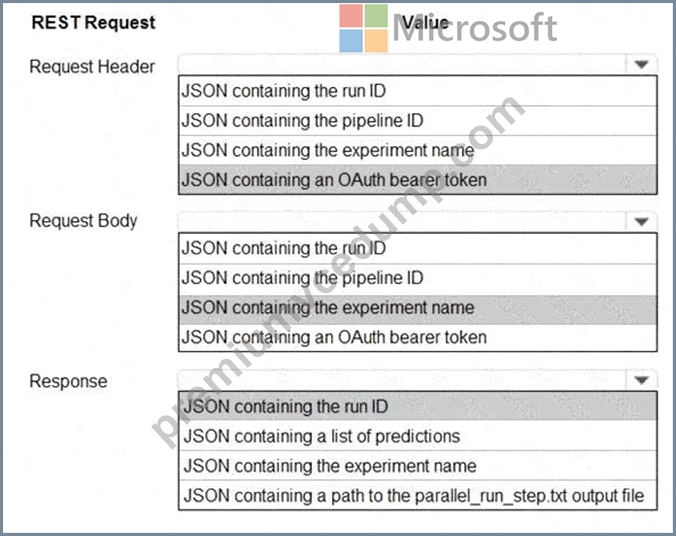
Box 1: JSON containing an OAuth bearer token
Specify your authentication header in the request.
To run the pipeline from the REST endpoint, you need an OAuth2 Bearer-type authentication header.
Box 2: JSON containing the experiment name
Add a JSON payload object that has the experiment name.
Example:
rest_endpoint = published_pipeline.endpoint
response = requests.post(rest_endpoint,
headers=auth_header,
json={"ExperimentName": "batch_scoring",
"ParameterAssignments": {"process_count_per_node": 6}})
run_id = response.json()["Id"]
Box 3: JSON containing the run ID
Make the request to trigger the run. Include code to access the Id key from the response dictionary to get the value of the run ID.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-pipeline-batch-scoring-classification
NEW QUESTION # 301
You create an Azure Machine Learning workspace. You train an MLflow-formatted regression model by using tabular structured data.
You must use a Responsible AI dashboard to assess the model.
You need to use the Azure Machine Learning studio UI to generate the Responsible AI dashboard.
What should you do first?
Answer: A
Explanation:
Responsible AI dashboards are linked to your registered models. To view your Responsible AI dashboard, go into your model registry and select the registered model you've generated a Responsible AI dashboard for. Then, select the Responsible AI tab to view a list of generated dashboards.
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-responsible-ai- dashboard?view=azureml-api-2
NEW QUESTION # 302
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.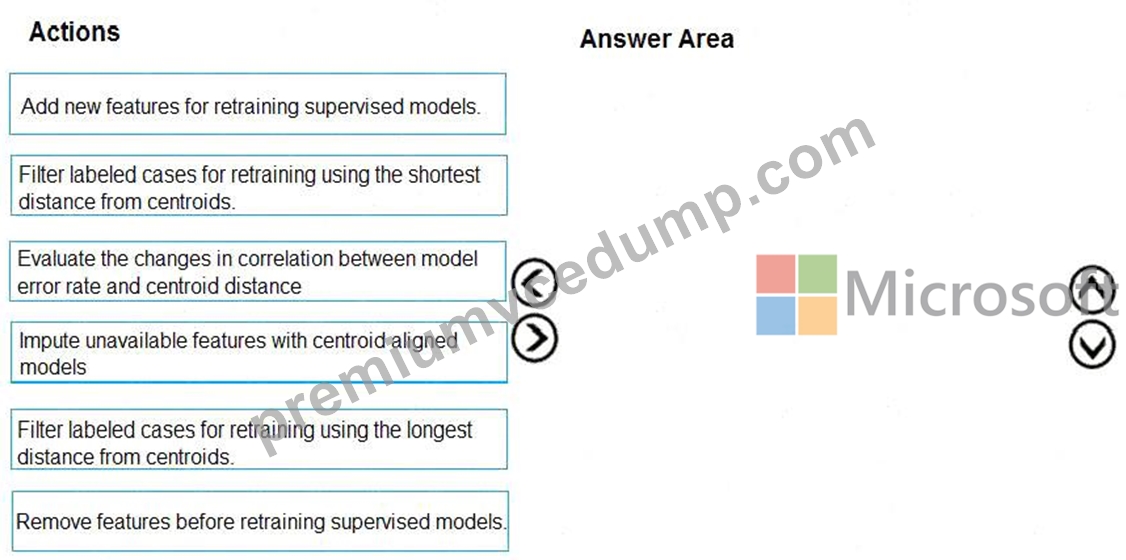
Answer:
Explanation: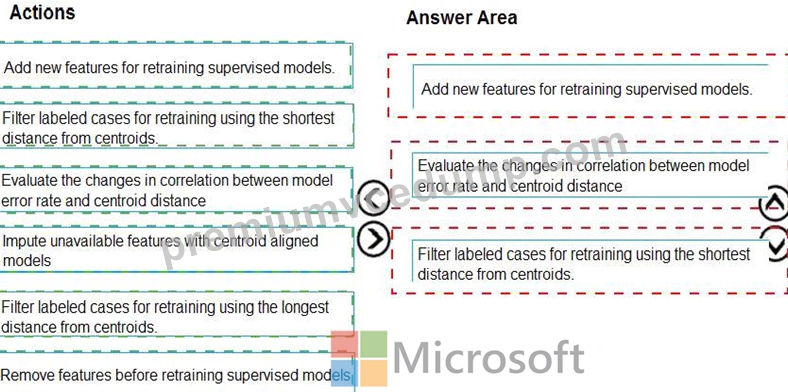
Explanation: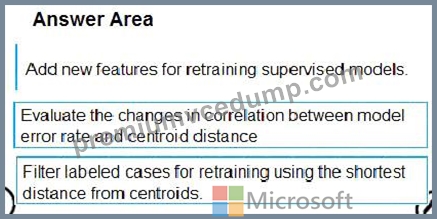
Scenario:
Experiments for local crowd sentiment models must combine local penalty detection data.
Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
Note: Evaluate the changed in correlation between model error rate and centroid distance In machine learning, a nearest centroid classifier or nearest prototype classifier is a classification model that assigns to observations the label of the class of training samples whose mean (centroid) is closest to the observation.
References:
https://en.wikipedia.org/wiki/Nearest_centroid_classifier
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/sweep-clustering
NEW QUESTION # 303
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1.csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,I
1,1,2,0
2,1,1,1
3,2,1,0
4,2,2,1
You run the following code: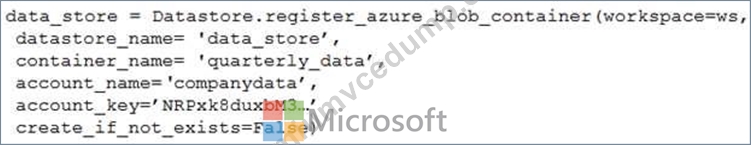
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code: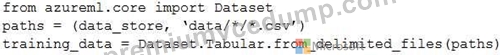
Does the solution meet the goal?
Answer: A
Explanation:
Define paths with two file paths instead.
Use Dataset.Tabular_from_delimeted as the data isn't cleansed.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 304
......
DP-100 Test Duration: https://www.premiumvcedump.com/Microsoft/valid-DP-100-premium-vce-exam-dumps.html
BTW, DOWNLOAD part of PremiumVCEDump DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1mNl7oz3eLKdulcEwFfNfb-RlB09VDLGm