合格率の高い高品質の最新のDP-750認定ガイド資料により、Pass4Testはどんどん成長しています。過去のデータに基づくと、最近のDP-750トレーニングガイドの合格率は最高99%〜100%です。多くのお客様は、DP-750試験ガイドを一度選択した後、クリアする試験があると、通常の顧客になり、私たちのことを考えます。そのため、宣伝のために多くの精霊を費やす必要はありませんが、研究とアフターサービスのみに力を入れています。 DP-750の学習質問で学習する限り、それが正しい選択であることがわかります。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
我々Pass4Testは最高のアフターサービスを提供いたします。MicrosoftのDP-750試験ソフトを買ったあなたは一年間の無料更新サービスを得られて、MicrosoftのDP-750の最新の問題集を了解して、試験の合格に自信を持つことができます。あなたはMicrosoftのDP-750試験に失敗したら、弊社は原因に関わらずあなたの経済の損失を減少するためにもらった費用を全額で返しています。
質問 # 41
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
正解:D
解説:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
質問 # 42
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.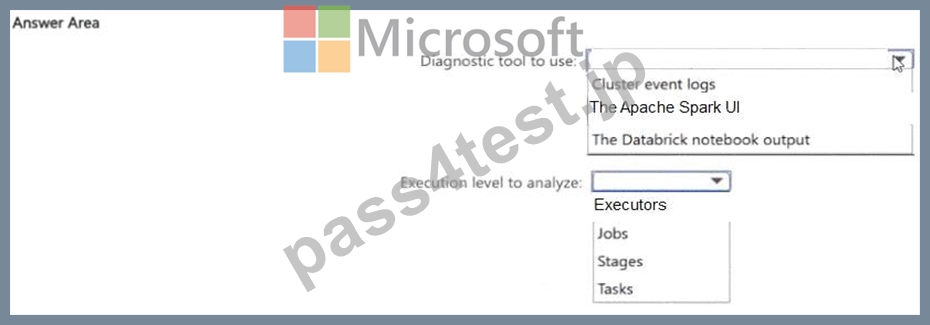
正解:
解説: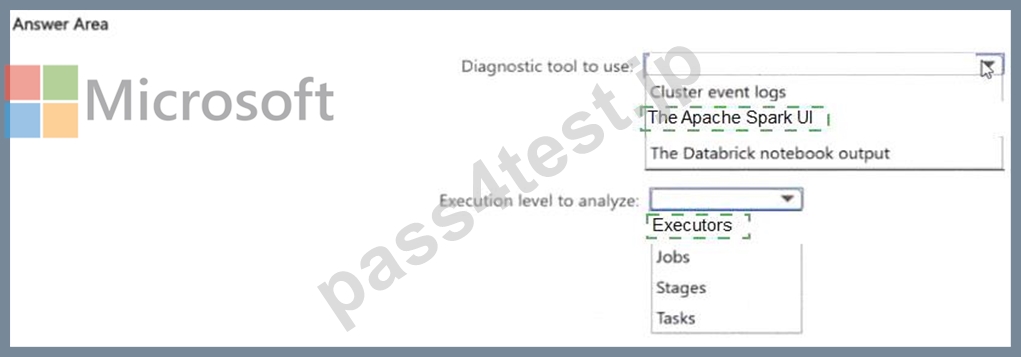
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
質問 # 43
Which Azure service is best integrated with Databricks Unity Catalog for centralized data governance?
正解:C
解説:
Microsoft Purview integrates with Unity Catalog to provide centralized data governance, classification, and lineage tracking. It helps organizations manage data compliance and discovery. Key Vault handles secrets, not governance. DevTest Labs is for testing environments.
Azure Automation is for workflow automation.
質問 # 44
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.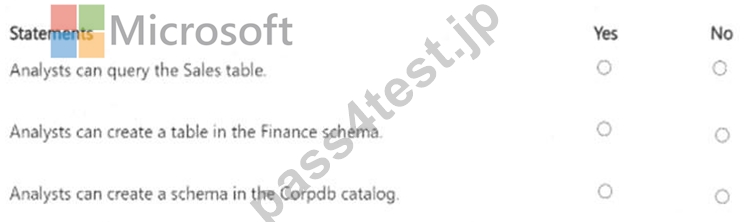
正解:
解説: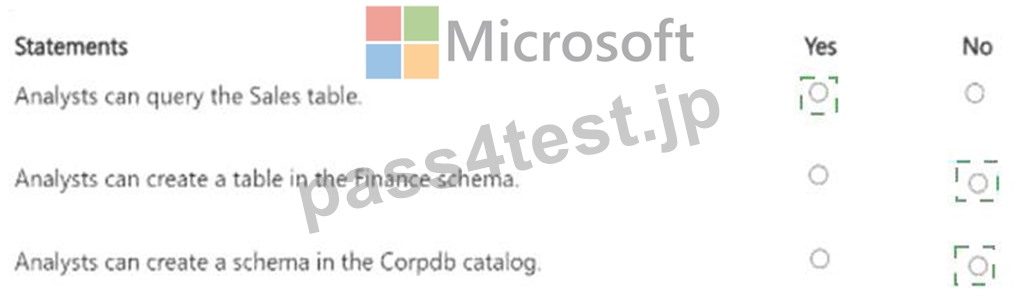
Explanation: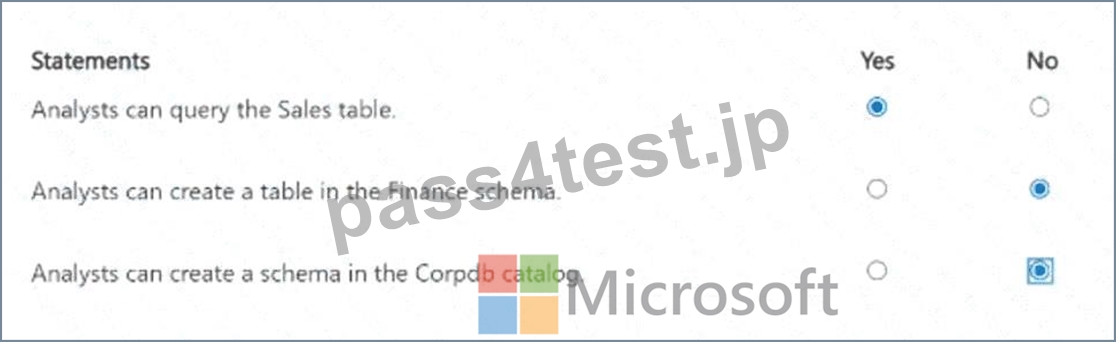
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
質問 # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.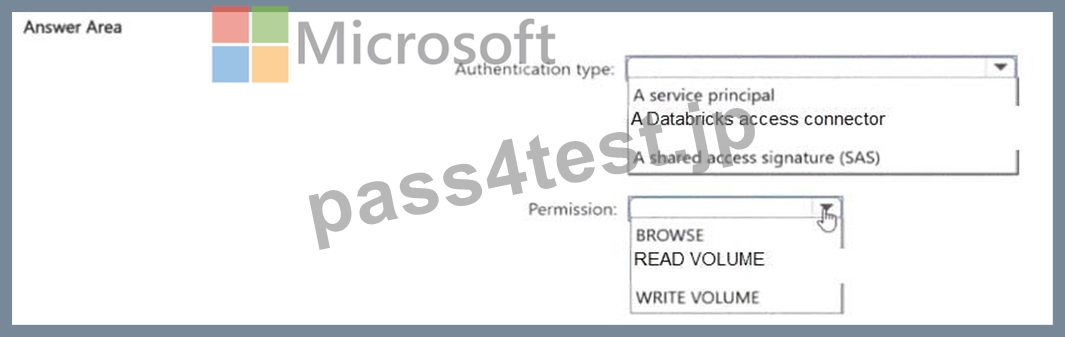
正解:
解説: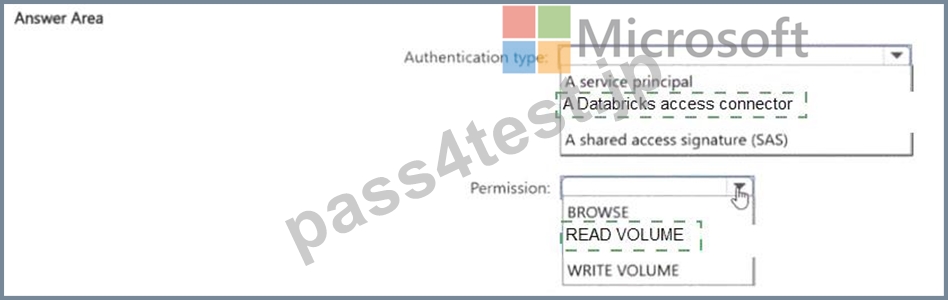
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
質問 # 46
......
DP-750認証試験に合格したいのは簡単ではなく、いい復習方法は必要です。我々はあなたに詳しい問題と答えがあるDP-750問題集を提供します。この問題集は我々の経験がある専門家たちによって開発されています。我々のすばらしいDP-750問題集はお客様の試験への成功を確保することができます。
DP-750模擬試験最新版: https://www.pass4test.jp/DP-750.html