Our DP-750 training materials are famous for high-quality, and we have a professional team to collect the first hand information for the exam. DP-750 learning materials of us also have high accurate, since we have the professionals check the exam dumps at times. We are strict with the answers and quality, we can ensure you that the DP-750 Learning Materials you get are the latest one we have. Moreover, we offer you free update for one year and the update version for the DP-750 exam dumps will be sent to your email automatically.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data ingestion
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
According to our investigation, the test syllabus of the DP-750 exam is changing every year. Some new knowledge will be added into the annual real exam. Some old knowledge will be deleted. So you must have a clear understanding of the test syllabus of the DP-750 study materials. Now, you can directly refer to our study materials. Our experts have carefully researched each part of the test syllabus of the DP-750 Study Materials. Then they compile new questions and answers of the study materials according to the new knowledge parts.
NEW QUESTION # 55
What improves join performance for small lookup tables?
Answer: D
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 56
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1 .table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: A
Explanation:
To load all rows from one table into the other while preserving existing data and minimizing processing effort, you should use the SQL INSERT INTO statement.
Preserves Data: INSERT INTO appends new rows to the target table without modifying or deleting the existing data.
Lowest Processing Effort: It performs a direct data append at the storage level. Unlike MERGE INTO, it does not scan the target table for matches, saving significant compute time and costs.
Delta Lake Optimization: Because these are Delta tables, appending data simply writes new parquet files and commits them to the transaction log, making the operation fast and efficient.
Reference:
https://medium.com/@gema.correa/handling-schema-evolution-and-schema-compensation-in-databricks-lessons-from-the-field-7af8d915beef
NEW QUESTION # 57
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.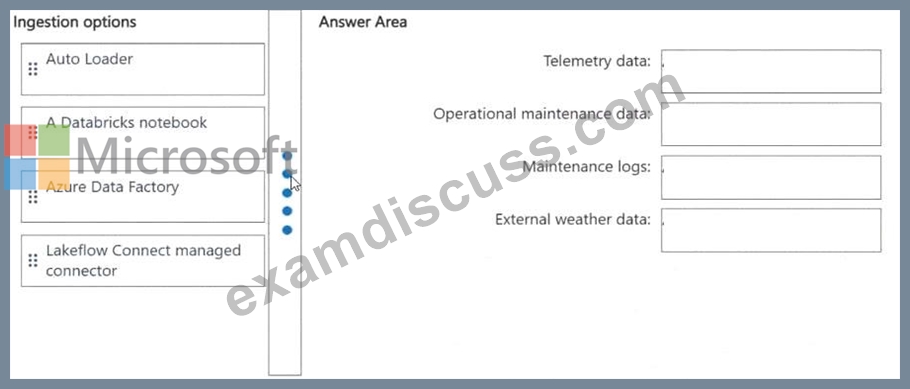
Answer:
Explanation: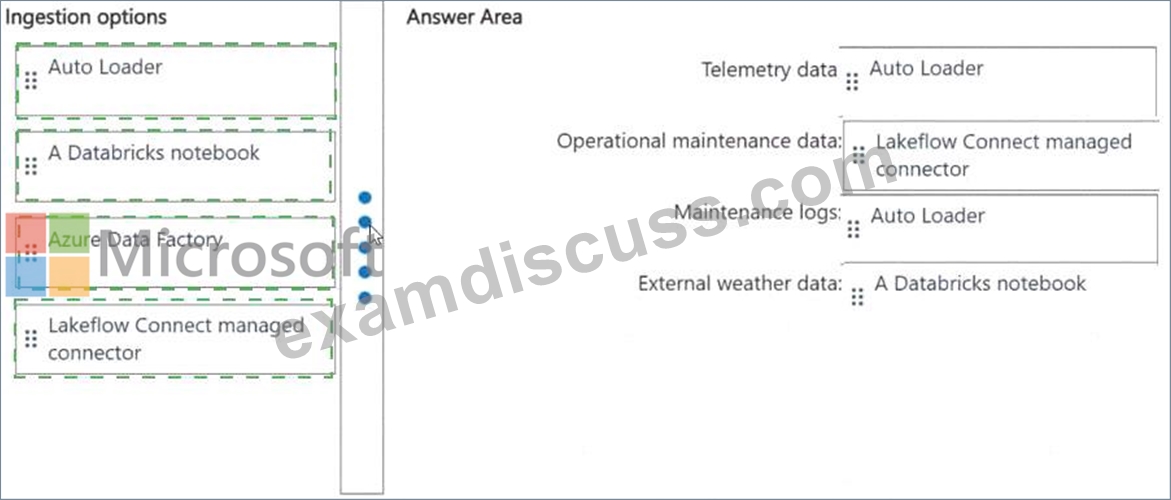
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 58
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 59
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: D
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 60
......
These Microsoft DP-750 exam questions have a high chance of coming in the actual DP-750 test. You have to memorize these DP-750 questions and you will pass the Microsoft DP-750 test with brilliant results. The price of Microsoft DP-750 updated exam dumps is affordable.
DP-750 Reliable Study Questions: https://www.examdiscuss.com/Microsoft/exam/DP-750/