P.S. Free & New DP-800 dumps are available on Google Drive shared by ExamsReviews: https://drive.google.com/open?id=15ANoAbOJ2fJlKNyrE1znd4mCoIcmz_S1
Thus, you can see how a single decision can bring a lot of positive and fruitful changes in your life. However, if you are thinking about what if you were not able to get the Microsoft DP-800 certification or pass the Developing AI-Enabled Database Solutions (DP-800) exam? Don't worry, you will find it easy to adjust to this new thing and get complete support from the ExamsReviews who offer Microsoft DP-800 Exam Questions and practice exams for the Microsoft DP-800 certification exam.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Available Languages: | English |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Exam Format: | Case studies, Multiple choice |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
Our DP-800 exam prepare is definitely better choice to help you go through the test. Will you feel that the product you have brought is not suitable for you? One trait of our DP-800 exam prepare is that you can freely download a demo to have a try. Because there are excellent free trial services provided by our DP-800 exam guides, our products will provide three demos that specially designed to help you pick the one you are satisfied. The key trait of our product is that we keep pace with the changes of syllabus and the latest circumstance to revise and update our DP-800 Study Materials, and we are available for one-year free updating to assure you of the reliability of our service.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 68
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project ieferences system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Add the Microsoft.SqlServer.Dacpacs.Mastet NuGet package to the project.
Does this meet the goal?
Answer: A
Explanation:
The package named Microsoft.SqlServer.Dacpacs.Master is the generic master system DACPAC package, but the question requires the correct system objects for Azure SQL Database . Microsoft's system-objects documentation distinguishes platform-specific system references, and for Azure SQL Database the correct package is the Azure-specific master DACPAC , not the generic master package.
So adding Microsoft.SqlServer.Dacpacs.Master does not meet the goal for an Azure SQL Database- targeted SDK-style project. The expected package is the Azure-specific one.
NEW QUESTION # 69
You have an Azure SQL database named SalesDB that contains a table named dbo.Articles.
dbo.Articles contains two million articles with embeddings. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARCH.
Users report that semantic search results do NOT reflect the updates until the following day.
You need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB.
Which embedding maintenance method should you implement?
Answer: C
Explanation:
This setup is a solid way to bridge the gap between your SQL updates and your vector index. By using CDC (Change Data Capture), you avoid the heavy lifting of scanning the entire table for changes, which keeps your database CPU overhead low.
To make this work efficiently within the Azure Functions app, you'll typically want to:
Batch the updates: Instead of triggering a function for every single row change, process small batches of CDC records to reduce the number of calls to your embedding model (like OpenAI).
Use an Upsert logic: In your function, ensure the code handles both new inserts and updates by overwriting the existing embedding for a specific Article ID in the database.
Implement a "Cool-down" or Timer: If the "frequent updates" happen in bursts, you can use an Azure Service Bus or Storage Queue between the CDC process and the Function to smooth out the processing load.
Reference:
https://fivetran.com/docs/connectors/databases/troubleshooting/log-based-cdc-impact
NEW QUESTION # 70
You need to meet the database performance requirements for maintenance data How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.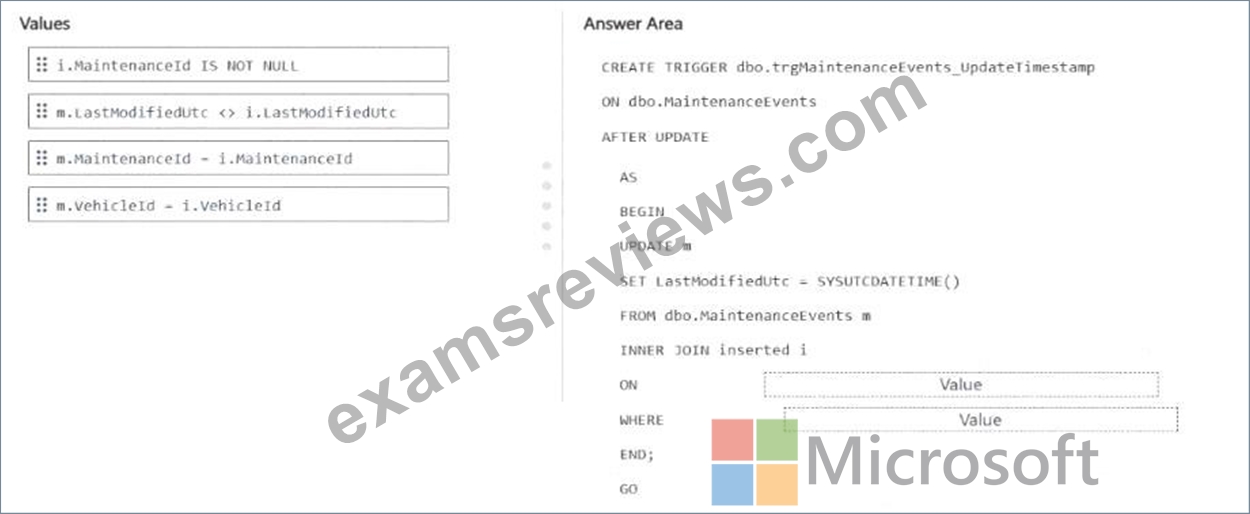
Answer:
Explanation: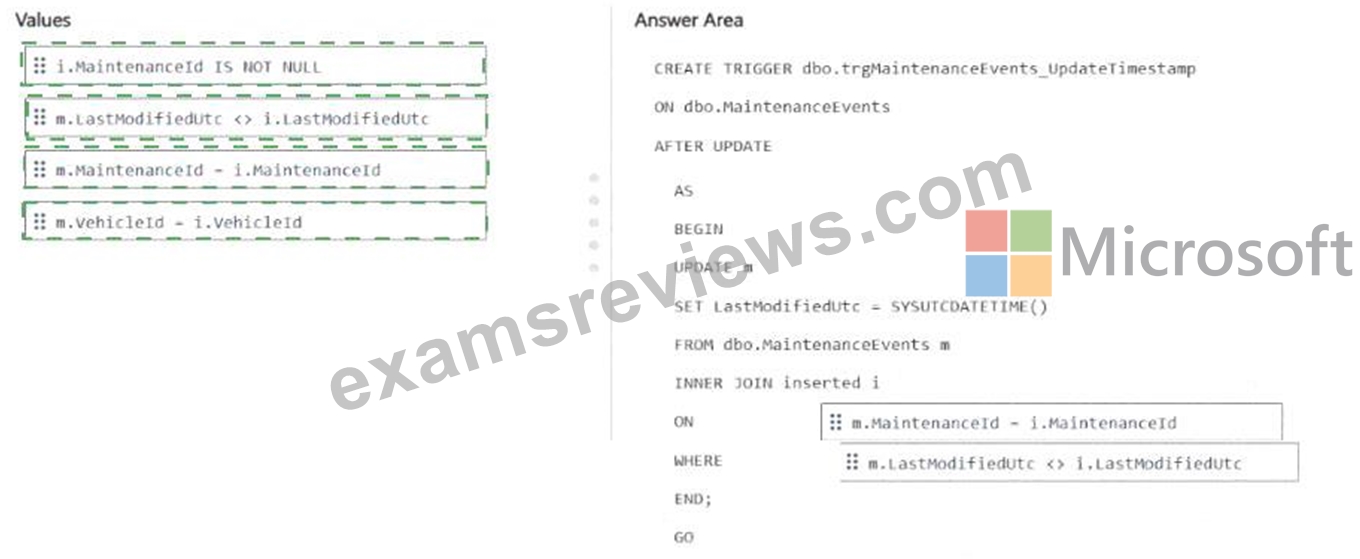
Explanation:
* ON # m.maintenanceId = i.maintenanceId
* WHERE # m.LastModifiedUtc < > i.LastModifiedUtc
The correct drag-and-drop completion is:
* ON m.maintenanceId = i.maintenanceId
* WHERE m.LastModifiedUtc < > i.LastModifiedUtc
This satisfies the requirement to ensure that when a row in MaintenanceEvents changes, the corresponding LastModifiedUtc value is updated to the current system time, while also helping avoid unnecessary repeat updates.
The inserted pseudo-table in a SQL Server AFTER UPDATE trigger contains the rows that were just updated.
To update the matching row in the base table correctly, the trigger must join the target table row to the corresponding row in inserted by the table's primary key. In this schema, MaintenanceId is the primary key for MaintenanceEvents, so the correct join is m.maintenanceId = i.maintenanceId . Joining on VehicleId would be incorrect because multiple maintenance rows could exist for the same vehicle, which could update unintended rows. Microsoft's trigger documentation explains that inserted and deleted are used to work with the affected rows and that multi-row logic should be based on proper key matching.
The WHERE m.LastModifiedUtc < > i.LastModifiedUtc predicate is used to prevent the trigger from re- updating rows where the timestamp already matches the value in inserted. That reduces redundant writes and supports the requirement to avoid recursive or repeated update behavior. In practice, this means the trigger updates only rows whose current stored timestamp differs from the just-updated version. This is the exam- appropriate pattern for a self-updating timestamp column in an AFTER UPDATE trigger.
NEW QUESTION # 71
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Answer: E
Explanation:
The correct answer is C because the current query uses VECTOR_DISTANCE( ' cosine ' , @query_vector, embedding) , which performs an exact vector distance calculation . Microsoft explicitly documents that VECTOR_DISTANCE does not use a vector index , even when one exists. Exact k-nearest-neighbor searches can require scanning large numbers of vectors and calculating distances row by row, which explains the observed CPU spikes and increased semantic-search latency during peak load.
A vector index on products.embedding is specifically designed to accelerate nearest-neighbor search, and VECTOR_SEARCH is the Transact-SQL function that can use that approximate nearest-neighbor index when the index metric matches the query metric. Using METRIC = ' cosine ' preserves the same similarity metric currently used by App1 while reducing the amount of computation required.
The other choices are incorrect:
* A normalizes vectors but does not replace the expensive exact search with indexed ANN retrieval.
* B replaces semantic vector search with lexical full-text search and changes the feature's behavior.
* D a standard nonclustered B-tree index cannot accelerate vector-distance operations.
* E converting embeddings to VARBINARY(8000) removes native vector semantics and does not solve the performance problem.
Therefore, the exam-aligned solution is create a vector index and use VECTOR_SEARCH with cosine distance .
NEW QUESTION # 72
You need to meet the development requirements for the FeedbackJson column How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.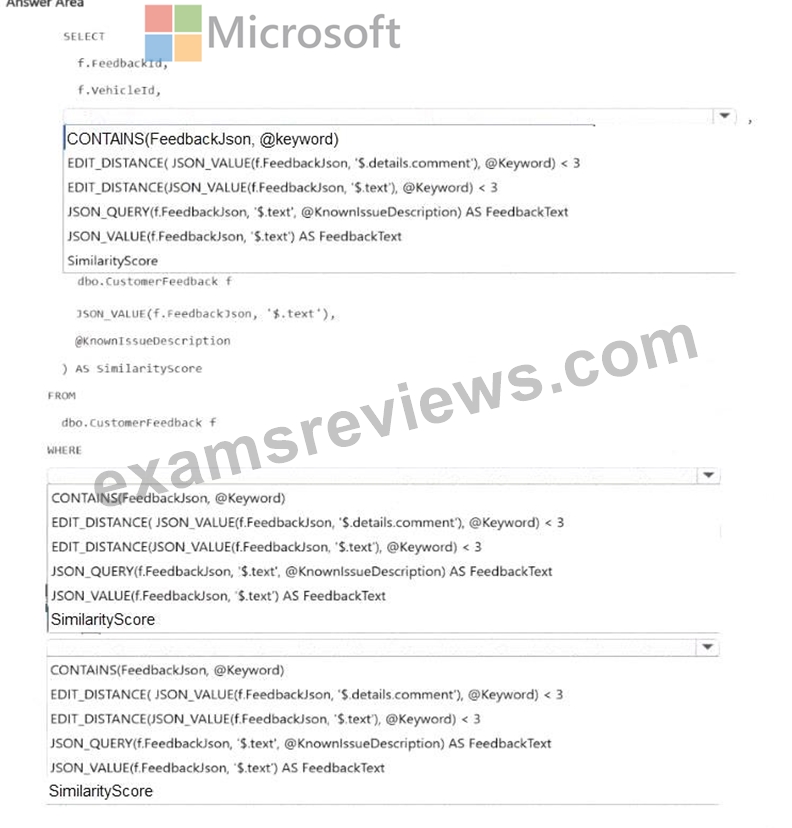
Answer:
Explanation: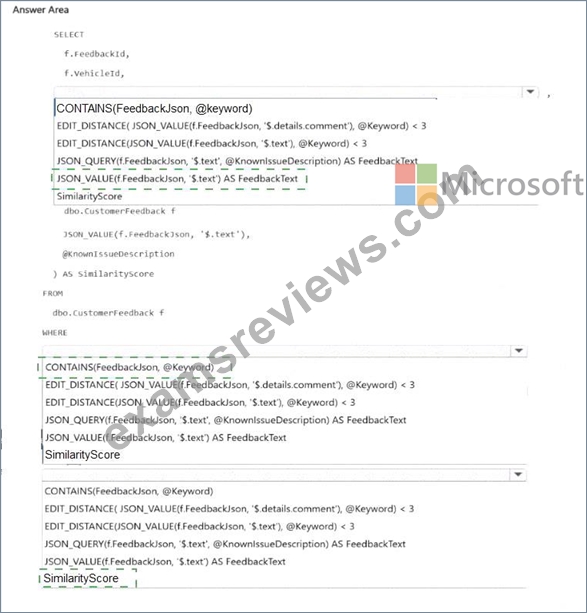
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document , the correct expression is JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText . Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array .
Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword , the best choice is CONTAINS (FeedbackJson, @Keyword) . The scenario explicitly states that FeedbackJson already has a full-text index
, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first , the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 73
......
Valid DP-800 Test Prep: https://www.examsreviews.com/DP-800-pass4sure-exam-review.html
BTW, DOWNLOAD part of ExamsReviews DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=15ANoAbOJ2fJlKNyrE1znd4mCoIcmz_S1