BONUS!!! Download part of ExamDumpsVCE AI-300 dumps for free: https://drive.google.com/open?id=1SAPg3S4xVuyNV3uEi93sGrrXRl0m5ueP
The Microsoft AI-300 certification exam is one of the top-rated career booster certifications in the market. This Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification offers a great opportunity for Microsoft aspirants to validate their skills and knowledge. By doing this they can gain several personal and professional benefits. These AI-300 Certification benefits help them not only prove their expertise but also enable them to gain multiple career opportunities in the highly competitive market.
| Section | Objectives |
|---|---|
| Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries |
| Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Implement cost management and scaling strategies for GenAI workloads |
| Implement machine learning model lifecycle and operations | - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning - Monitor model performance, data drift, and operational health |
| Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding |
>> AI-300 Latest Exam Format <<
With the complete collection of Microsoft practice questions and answers, our website offers you the most reliable AI-300 vce files for your exam preparation. In the AI-300 actual test we have compiled real questions and answers so that you can prepare and pas exam in your first attempt. You can also check the demo of AI-300 Dumps PDF before you decide to buy it.
NEW QUESTION # 164
-
You use Azure Machine Learning to deploy a model as a real-time web service.
You need to create an entry script for the service that ensures that the model is loaded when the service starts and is used to score new data as it is received.
Which functions should you include in the script? To answer, drag the appropriate functions to the correct actions. Each function may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.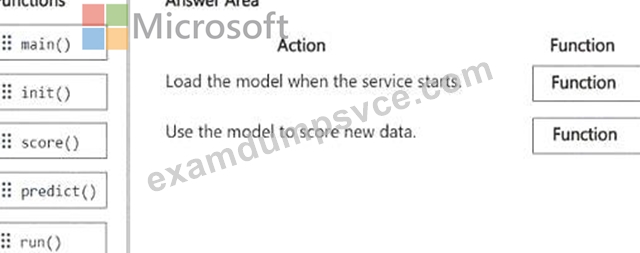
Answer:
Explanation: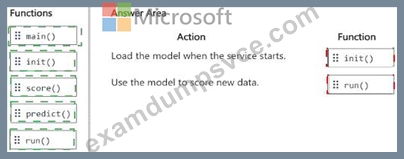
Explanation:
Load the model when the service starts: init()
Use the model to score new data: run()
Azure Machine Learning scoring scripts for online endpoints use two required entry-point functions: init() and run() . Microsoft explicitly states that the scoring script specified for an online deployment must contain both functions.
The init() function is invoked when the inference container is initialized or started, typically immediately after a deployment is created or updated. It is intended for one-time initialization tasks such as locating the registered model through AZUREML_MODEL_DIR, deserializing the model, and storing it in memory.
Loading the model once during initialization avoids repeatedly loading it for every inference request, which reduces latency and processing overhead.
The run() function is called each time the endpoint receives an inference request. It accepts the incoming request data, transforms or parses the input as required, invokes the loaded model ' s prediction logic, and returns the scoring result. Microsoft describes run() as the function that performs the actual scoring or prediction for each endpoint invocation.
main(), score(), and predict() may exist inside application code or model libraries, but they are not the required Azure Machine Learning scoring-script entry points.
NEW QUESTION # 165
You have an Azure Machine Learning workspace.
You plan to set up logging and tracking experiments by using MLflow Tracking.
You need to log the accuracy as a numerical value and the training loss as a plot.
How should you complete the commands? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.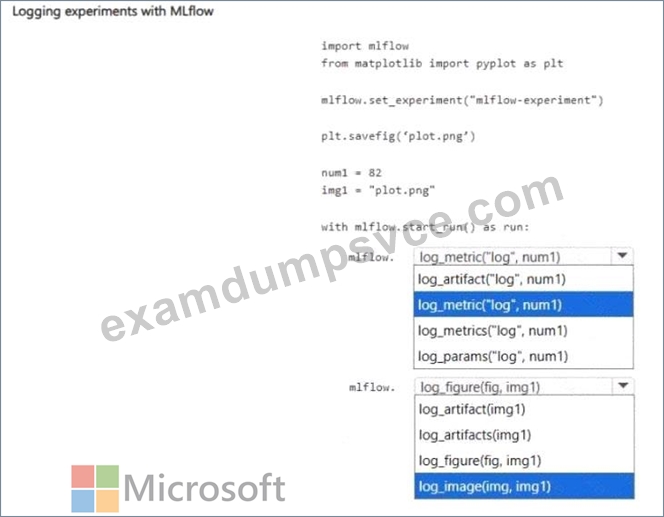
Answer:
Explanation: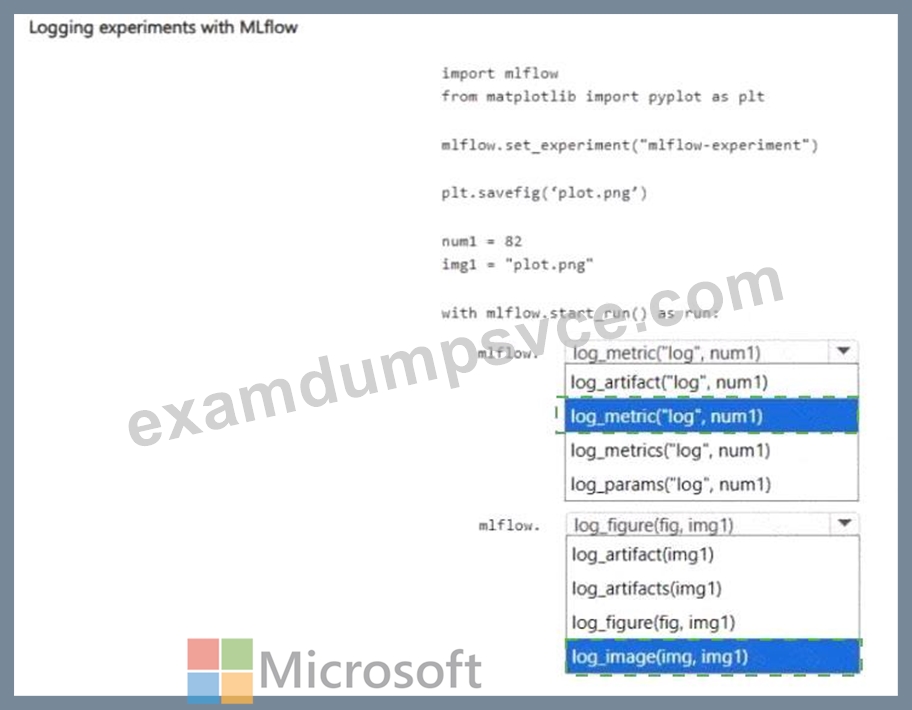
Explanation: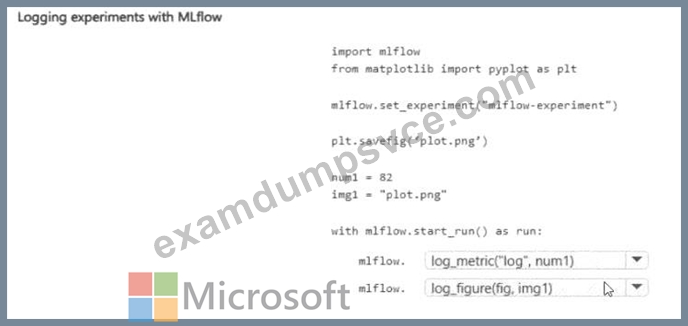
NEW QUESTION # 166
Hotspot Question
A team retrains a machine learning model on a weekly basis by using updated training data.
The team must be able to rerun any previous experiment by using the exact data that was available at the time it was originally run. The solution must preserve historical versions of the data without duplicating training scripts.
You need to manage the data so that experiments can be reproduced reliably.
Which workspace actions should you perform? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.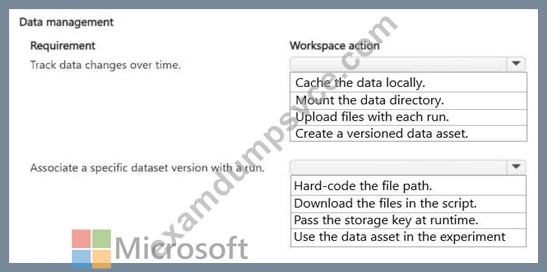
Answer:
Explanation:
Explanation:
Box 1: Create a versioned dataset
Track data changes over time.
Creating a versioned dataset in your machine learning workspace configuration is the correct and industry-standard way to solve this.
Versioned datasets allow you to decouple your training scripts from your data state. This approach satisfies all your constraints without duplicating code or creating messy infrastructure.
Enables Reproducibility: Every time you run a training job, you log the specific dataset version used (e.g., v1, v2, v3). To rerun a historical experiment, you simply call that specific version identifier.
Prevents Code Duplication: Your training scripts remain identical. They accept a dataset version as an input parameter rather than pointing to hardcoded file paths.
Tracks Weekly Updates: When the weekly data refresh occurs, you register the new data as v+1 in the workspace registry, keeping a clean chronological ledger.
Box 2: Use the data asset in the experiment
Associate a specific dataset version with a run.
To best associate a specific dataset version with a run in the workspace, you should use the data asset in the experiment.
Automatic Lineage: Registering data as a versioned data asset automatically tracks which exact version was used in which specific run.
Exact Reproducibility: You can look back at any historical run and instantly identify or retrieve the precise data state used at that moment.
No Script Duplication: Your training scripts remain decoupled from the data, satisfying your requirement to preserve history without changing code.
Incorrect:
[Pass the storage key at runtime]
Passing a storage key at runtime only connects the run to a storage location, not a specific, immutable version of the data at a frozen point in time.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-version-track-datasets
NEW QUESTION # 167
Hotspot Question
A biomedical research company plans to enroll people in an experimental medical treatment trial.
You create and train a binary classification model to support selection and admission of patients to the trial. The model includes the following features: Age, Gender, and Ethnicity.
The model returns different performance metrics for people from different ethnic groups.
You need to use Fairlearn to mitigate and minimize disparities for each category in the Ethnicity feature.
Which technique and constraint should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.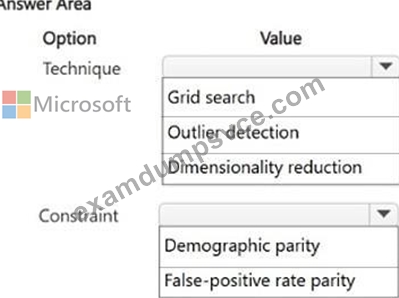
Answer:
Explanation: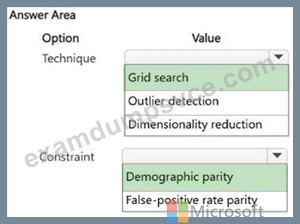
NEW QUESTION # 168
You are training machine learning models in Azure Machine Learning. You use Hyperdrive to tune the hyperparameters.
In previous model training and tuning runs, many models showed similar performance.
You need to select an early termination policy that meets the following requirements:
* Accounts for the performance of all previous runs when evaluating the current run.
* Avoids comparing the current run with only the best performing run to date.
Which two early termination policies should you use? Each correct answer presents part of the solution.
Answer: B,D
Explanation:
Median stopping and Truncation selection both evaluate a run relative to the broader population of training runs rather than comparing it only against the single best run.
The Median Stopping Policy calculates running averages of the primary metric across all runs . At an evaluation interval, a run can be terminated when its best primary-metric performance is worse than the median of the running averages across the population. Microsoft explicitly defines this policy as being based on running averages of the primary metric of all runs.
The Truncation Selection Policy periodically ranks runs by their primary metric and terminates a configured percentage of the lowest-performing runs . For example, a 20-percent truncation policy terminates runs falling within the lowest 20 percent at the applicable evaluation interval. It therefore compares each candidate with the population of comparable runs rather than only the current leader.
Bandit is specifically unsuitable because it uses an allowable slack relative to the best-performing run , which directly violates the requirement. The Default behavior applies no early termination policy and allows runs to execute to completion.
Study Guide Reference: Implement machine learning model lifecycle and operations - automated hyperparameter tuning, early termination policies, Median Stopping Policy, Truncation Selection Policy, and efficient experiment execution.
NEW QUESTION # 169
......
Without doubt, our AI-300 practice dumps keep up with the latest information and contain the most valued key points that will show up in the real AI-300 exam. Meanwhile, we can give you accurate and instant suggestion for our customer services know every detail of our AI-300 Exam Questions. And they are pleased to give guide for 24 hours online. You can get assistant by them as long as you made your inquire.
AI-300 Actual Exams: https://www.examdumpsvce.com/AI-300-valid-exam-dumps.html
BONUS!!! Download part of ExamDumpsVCE AI-300 dumps for free: https://drive.google.com/open?id=1SAPg3S4xVuyNV3uEi93sGrrXRl0m5ueP