DEA-C02 PDF Guide - DEA-C02 New Test Bootcamp

P.S. Free 2026 Snowflake DEA-C02 dumps are available on Google Drive shared by TestsDumps: https://drive.google.com/open?id=10g_cd-vO6HQcQAYBntX20er7uLrOhr_U
The DEA-C02 would assist applicants in preparing for the Snowflake DEA-C02 exam successfully in one go DEA-C02 would provide DEA-C02 candidates with accurate and real SnowPro Advanced: Data Engineer (DEA-C02) (DEA-C02) Dumps which are necessary to clear the DEA-C02 test quickly. Students will feel at ease since the content they are provided with is organized rather than dispersed.
| Section | Weight | Objectives |
|---|
| Topic 1: Security and Governance | 15% | - Access Control
- 1. GRANT and REVOKE operations
- 2. Role hierarchy and ownership
- 3. Role-based access control (RBAC)
- Governance and Compliance
- 1. Data retention policies
- 2. Access history and auditing
- 3. Row access policies
- 4. Object tagging
- Data Security
- 1. External tokenization
- 2. Data masking and tokenization
- 3. Row-level security policies
- 4. Column-level security
|
| Topic 2: Data Transformation with Snowflake | 30% | - SQL Transformations
- 1. Complex JOINs and set operations
- 2. Window functions advanced usage
- 3. Working with semi-structured data (VARIANT)
- 4. Data type conversions and handling
- Snowflake Scripting
- 1. Dynamic SQL
- 2. Error handling
- 3. Procedures and control flow
- Data Processing Patterns
- 1. Zero-copy cloning for ETL
- 2. MERGE, UPDATE, DELETE operations
- 3. Time travel and change data capture
|
| Topic 3: Performance Optimization | 15% | - Query Optimization
- 1. Query profiling and analysis
- 2. Avoiding common performance pitfalls
- 3. Query result caching
- 4. Indexing strategies with clustering
- Warehouse Performance
- 1. Resource monitors
- 2. Warehouse scaling policies
- 3. Multi-cluster warehouses
- 4. Warehouse sizing and selection
- Data Optimization
- 1. Materialized views
- 2. Data cache management
- 3. Search optimization service
|
| Topic 4: Data Ingestion and Consumption | 20% | - Bulk Loading and Unloading
- 1. Data loading performance optimization
- 2. Handling staged files
- 3. File format options (CSV, JSON, Parquet, AVRO)
- 4. COPY INTO command options and best practices
- Data Unloading
- 1. Partitioning unloading data
- 2. Data export best practices
- 3. Unloading to internal and external stages
- Continuous Data Loading
- 1. Snowpipe configuration and usage
- 2. Automating data loading with tasks
- 3. Real-time data ingestion patterns
|
| Topic 5: Data Architecture and Processing | 20% | - Data Storage Architecture
- 1. Hybrid Tables concepts
- 2. Table types (Permanent, Transient, Temporary)
- 3. Micro-partitioning and clustering
- Data Modeling for Performance
- 1. Dimension handling
- 2. Star and snowflake schemas
- 3. Slowly changing dimensions (SCD)
- Data Pipeline Design
- 1. Stream and task patterns
- 2. Data scheduling and orchestration
- 3. Pipeline monitoring and error handling
|
>> DEA-C02 PDF Guide <<
DEA-C02 New Test Bootcamp, DEA-C02 Discount
If moving up in the fast-paced technological world is your objective, TestsDumps is here to help. The excellent Snowflake DEA-C02 practice exam from TestsDumps can help you realize your goal of passing the Snowflake DEA-C02 Certification Exam on your very first attempt. Most people find it difficult to find excellent Snowflake DEA-C02 exam dumps that can help them prepare for the actual Snowflake DEA-C02 exam.
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q333-Q338):
NEW QUESTION # 333
You are developing a JavaScript stored procedure in Snowflake using Snowpark to perform a complex data transformation. This transformation involves multiple steps: filtering, joining with another table, and aggregating data'. You need to ensure that the stored procedure is resilient to failures and can be easily debugged. Which of the following practices would contribute to the robustness and debuggability of your stored procedure? (Select all that apply)
- A. Directly manipulating the Snowflake metadata (e.g., table schemas) within the stored procedure for dynamic schema evolution.
- B. Using Snowpark's logging capabilities to record intermediate results and error messages at various stages of the transformation.
- C. Relying solely on try-catch blocks within the stored procedure to handle all potential exceptions.
- D. Breaking down the complex transformation into smaller, modular functions within the stored procedure and testing each function independently.
- E. Passing the 'snowflake' binding as an argument to each modular function to facilitate logging and SQL execution within those functions.
Answer: B,D,E
Explanation:
Options B, C, and D are correct. Logging intermediate results allows you to track the flow of data and identify the point of failure. Modularizing the code and testing individual functions makes debugging easier. Passing the 'snowflake' binding allows each module to log and execute SQL. Option A is insufficient, complex error requires more granular logging. Option E is dangerous and should be avoided as metadata changes should ideally be performed outside of transformation stored procedure and should be managed by orchestration tools.
NEW QUESTION # 334
A daily process loads data into a Snowflake table named 'TRANSACTIONS using a COPY INTO statement. The table is clustered on 'TRANSACTION DATE'. Over time, you observe a significant degradation in query performance when querying data within specific date ranges. Analyzing the 'SYSTEM$CLUSTERING INFORMATION' function output for the 'TRANSACTIONS' table reveals a low 'effective clustering_ratio' and a high 'average_overlaps'. Which combination of actions below would BEST address the performance degradation and improve query efficiency?
- A. Drop the current clustered table and create a new table with partition by clauses
- B. Create a new table with the desired clustering and load data using 'CREATE TABLE AS SELECT statement.
- C. Recluster the table using 'ALTER TABLE TRANSACTIONS RECLUSTER$ and adjust the virtual warehouse size to maximize resource allocation during the recluster operation.
- D. Implement a data maintenance schedule that regularly reclusters the table using 'ALTER TABLE TRANSACTIONS RECLUSTER;' during off-peak hours and monitor the 'SYSTEM$CLUSTERING INFORMATION' function periodically.
- E. Drop the existing clustering key on 'TRANSACTION_DATE, then recreate it with a different clustering key such as 'HASH(TRANSACTION_ID)'.
Answer: C,D
Explanation:
A low 'effective_clustering_ratio' and high 'average_overlaps' indicate that the data is not well-clustered, leading to inefficient query performance. Reclustering the table (A) reorganizes the data based on the clustering key, improving clustering. Creating a schedule (D) ensures that the table remains well-clustered over time. Dropping the clustering key and recreating it with a hash on (B) is unlikely to improve performance for date-range queries. Creating new table via 'CREATE TABLE AS SELECT statement is not the right way. In addition, 'Partition By' clause doesn't exist in Snowflake.
NEW QUESTION # 335
You are using Snowpark Python to perform data transformation on a large dataset stored in a Snowflake table named customer transactions'. This table contains columns such as 'customer id', 'transaction date', 'transaction amount', and product_category'. Your task is to identify customers who have made transactions in more than one product category within the last 30 days. Which of the following Snowpark Python snippets is the most efficient way to achieve this, minimizing data shuffling and maximizing query performance?
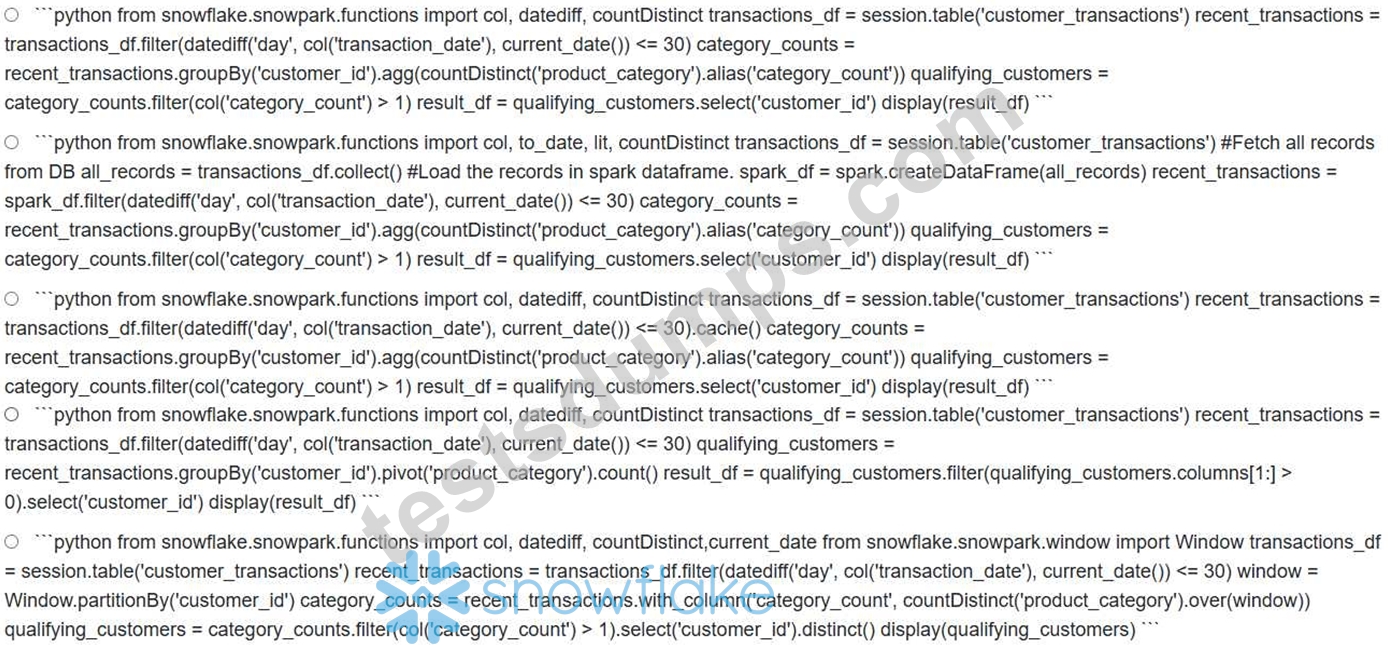
- A. Option A
- B. Option B
- C. Option C
- D. Option E
- E. Option D
Answer: D
Explanation:
Option E is the most efficient. It filters the transactions within the last 30 days, uses a window function to calculate the distinct count of product categories per customer, and then filters to identify customers with more than one category. The use of window functions allows the aggregation to happen within Snowflake, minimizing data transfer and leveraging Snowflake's processing power. distinct at the end makes it unique.
NEW QUESTION # 336
You are tasked with designing a data pipeline to load data from an Azure Blob Storage container into Snowflake using an external stage. The data is in CSV format, compressed using GZIP. The container contains millions of small CSV files. To optimize the data loading process and minimize cost, which of the following strategies would you implement, considering both stage configuration and COPY INTO options? Choose TWO that apply.
- A. Consolidate the small CSV files in the Azure Blob Storage container into larger files before loading them into Snowflake. This reduces the overhead of processing numerous small files.
- B. Leverage Snowflake's Snowpipe with a REST API endpoint to trigger data loads whenever new files are available in the Azure Blob Storage container.
- C. Use the 'MATCH BY COLUMN NAME = CASE INSENSITIVE option with a copy transformation in the 'COPY INTO' statement to ensure that the column order in the CSV files doesn't affect the data load.
- D. Use the 'VALIDATION MODE = RETURN ERRORS option in the 'COPY INTO' statement to identify and correct any data quality issues during the load. This ensures that only clean data is loaded into Snowflake.
- E. Create a pipe object with 'AUTO INGEST = TRUE to automatically ingest new files as they are added to the Azure Blob Storage container. This ensures near real-time data ingestion.
Answer: A,B
Explanation:
Consolidating small files into larger files (option E) significantly improves COPY INTO performance by reducing overhead. Using Snowpipe with a REST API endpoint (option C) allows for efficient, triggered data loading. 'VALIDATION MODE (option A) is useful for data quality but doesn't directly address optimization for millions of small files. 'AUTO INGEST (option B) is specific to AWS S3 and Google Cloud Storage, not Azure Blob Storage event notifications. Column matching (option D) addresses schema flexibility, not optimization.
NEW QUESTION # 337
You are responsible for monitoring the performance of a Snowflake data pipeline that loads data from S3 into a Snowflake table named 'SALES DATA. You notice that the COPY INTO command consistently takes longer than expected. You want to implement telemetry to proactively identify the root cause of the performance degradation. Which of the following methods, used together, provide the MOST comprehensive telemetry data for troubleshooting the COPY INTO performance?
- A. Query the 'COPY_HISTORY view and the view in 'ACCOUNT_USAG Also, check the S3 bucket for throttling errors.
- B. Use Snowflake's partner connect integrations to monitor the virtual warehouse resource consumption and query the 'VALIDATE function to ensure data quality before loading.
- C. Query the 'COPY HISTORY view in the 'INFORMATION SCHEMA' and monitor CPU utilization of the virtual warehouse using the Snowflake web I-Jl.
- D. Query the ' LOAD_HISTORY function and monitor the network latency between S3 and Snowflake using an external monitoring tool.
- E. Query the 'COPY HISTORY view in the 'INFORMATION SCHEMA' and enable Snowflake's query profiling for the COPY INTO statement.
Answer: A,E
Explanation:
To comprehensively troubleshoot COPY INTO performance, you need data on the copy operation itself (COPY HISTORY), overall account and data validation. The COPY_HISTORY view provides details about each COPY INTO execution, including the file size, load time, and any errors encountered. Query profiling offers detailed insight into the internal operations of the COPY INTO command, revealing bottlenecks. Monitoring S3 for throttling ensures that the data source isn't limiting performance. Using helps correlate storage growth with load times. LOAD_HISTORY doesn't exist, 'VALIDATE function is for data validation not performance. While warehouse CPU utilization is useful, it doesn't provide the specific details needed to diagnose COPY INTO issues. External network monitoring is also less relevant than checking for S3 throttling and analyzing Snowflake's internal telemetry data.
NEW QUESTION # 338
......
Preparing for SnowPro Advanced: Data Engineer (DEA-C02) (DEA-C02) exam can be a challenging task, especially when you're already juggling multiple responsibilities. People who don't study with updated Snowflake DEA-C02 practice questions fail the test and lose their resources. If you don't want to end up in this unfortunate situation, you must prepare with actual and Updated DEA-C02 Dumps of TestsDumps. At TestsDumps, we believe that one size does not fit all when it comes to Snowflake DEA-C02 exam preparation. Our team of experts has years of experience in providing Snowflake DEA-C02 exam preparation materials that help you reach your full potential.
DEA-C02 New Test Bootcamp: https://www.testsdumps.com/DEA-C02_real-exam-dumps.html
- DEA-C02 Free Practice 🤦 DEA-C02 Cert 👽 DEA-C02 Exam Certification Cost 🚋 Enter ( www.prep4away.com ) and search for ⏩ DEA-C02 ⏪ to download for free 🎷New DEA-C02 Exam Question
- Professional Snowflake DEA-C02 PDF Guide and Reliable DEA-C02 New Test Bootcamp 🍜 Search for ▷ DEA-C02 ◁ on ➤ www.pdfvce.com ⮘ immediately to obtain a free download 🎨Study Materials DEA-C02 Review
- 100% Pass Quiz 2026 Perfect Snowflake DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) PDF Guide 👲 Download [ DEA-C02 ] for free by simply searching on ( www.vceengine.com ) 📚New DEA-C02 Test Questions
- Snowflake DEA-C02 Exam | DEA-C02 PDF Guide - Official Pass Certify DEA-C02 New Test Bootcamp 🏬 Copy URL “ www.pdfvce.com ” open and search for ➡ DEA-C02 ️⬅️ to download for free 🍘New DEA-C02 Exam Question
- 100% Pass Snowflake - Efficient DEA-C02 PDF Guide 🥱 Go to website “ www.prepawaypdf.com ” open and search for ⮆ DEA-C02 ⮄ to download for free 🗼Test DEA-C02 Sample Questions
- 100% Pass Quiz 2026 Perfect Snowflake DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) PDF Guide 🚣 Open 「 www.pdfvce.com 」 enter ✔ DEA-C02 ️✔️ and obtain a free download 📏New DEA-C02 Test Questions
- 100% Pass Quiz 2026 Perfect Snowflake DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) PDF Guide 🍋 Open website { www.pdfdumps.com } and search for ➥ DEA-C02 🡄 for free download 📽Valid Dumps DEA-C02 Pdf
- 100% Pass Quiz Authoritative DEA-C02 - SnowPro Advanced: Data Engineer (DEA-C02) PDF Guide ⚛ Search for ➤ DEA-C02 ⮘ and download it for free immediately on ⏩ www.pdfvce.com ⏪ 💦New DEA-C02 Exam Question
- Training DEA-C02 Pdf 🔒 DEA-C02 Reliable Test Vce 🎏 Exam DEA-C02 Dumps 🍄 Search for ➥ DEA-C02 🡄 and download it for free immediately on ⮆ www.prepawayexam.com ⮄ 💡New DEA-C02 Exam Discount
- Passing SnowPro Advanced: Data Engineer (DEA-C02) actual test, valid DEA-C02 test braindump 🐹 Search for ⏩ DEA-C02 ⏪ and easily obtain a free download on 《 www.pdfvce.com 》 🌟DEA-C02 Practice Test Online
- DEA-C02 Practice Test Online 🦺 New DEA-C02 Exam Question 🦨 DEA-C02 Reliable Test Vce 🐥 Copy URL ➽ www.examcollectionpass.com 🢪 open and search for ✔ DEA-C02 ️✔️ to download for free 😣Exam DEA-C02 Details
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, www.stes.tyc.edu.tw, www.4shared.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Snowflake DEA-C02 dumps are available on Google Drive shared by TestsDumps: https://drive.google.com/open?id=10g_cd-vO6HQcQAYBntX20er7uLrOhr_U