P.S. Free 2026 Microsoft AI-200 dumps are available on Google Drive shared by PassSureExam: https://drive.google.com/open?id=1KO1tbgqI2DUiLVyY4QYXbkWUa_h5nsxY
In the era of information, everything around us is changing all the time, so do the AI-200 exam. But you don’t need to worry it. We take our candidates’ future into consideration and pay attention to the development of our AI-200 study training materials constantly. Free renewal is provided for you for one year after purchase, so the AI-200 Latest Questions won’t be outdated. The latest AI-200 latest questions will be sent to you email, so please check then, and just feel free to contact with us if you have any problem. Our reliable AI-200 exam material will help pass the exam smoothly.
| Section | Objectives |
|---|---|
| Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI |
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
>> Reliable AI-200 Test Duration <<
Since our company’s establishment, we have devoted mass manpower, materials and financial resources into AI-200 exam materials and until now, we have a bold idea that we will definitely introduce our AI-200 study materials to the whole world and make all people that seek fortune and better opportunities have access to realize their life value. Our AI-200 Practice Questions, therefore, is bound to help you pass though the AI-200 exam and win a better future.
NEW QUESTION # 116
You are developing an Azure Functions app.
All functions in the app meet the following requirements:
Run until either a successful run or until 10 run attempts occur.
Ensure that there are at least 20 seconds between attempts for up to 15 minutes.
You need to configure the host.json file.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.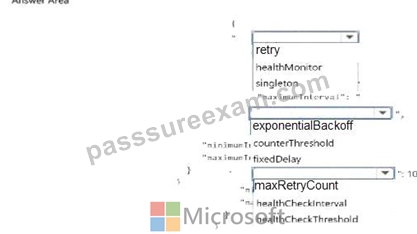
Answer:
Explanation: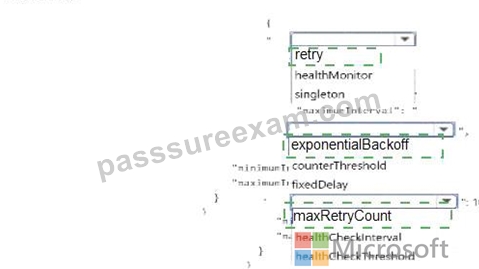
Explanation: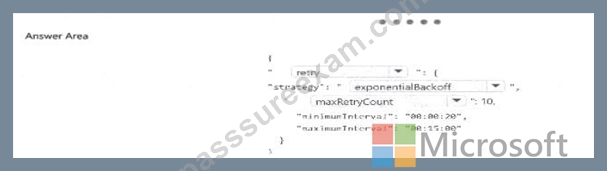
NEW QUESTION # 117
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.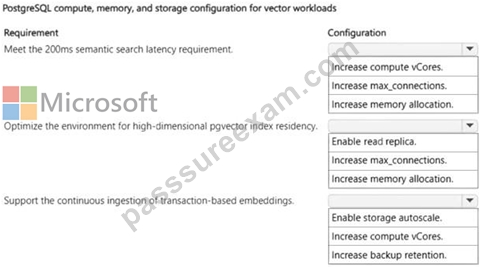
Answer:
Explanation:
Explanation:
Box 1: Increase compute vCores
Technical requirements, Performance: Semantic search latency must remain under 200 milliseconds at peak load.
To reduce semantic search latency under 200 milliseconds at peak load, the best action is to Increase compute vCores.
Vector similarity search and semantic retrieval are highly CPU-intensive operations. The math behind vector distance calculations (such as Cosine similarity, Dot Product, or Euclidean distance) relies heavily on mathematical operations executed per query. When a system experiences peak load, compute vCores easily become the primary bottleneck. Adding more vCores directly increases parallel processing capacity, dramatically shortening the execution time of similarity calculations and keeping retrieval latency within the required 200 ms SLA.
Box 2: Increase memory allocation
The best action is to increase memory allocation.
High-dimensional vector indexes (such as HNSW or IVFFlat managed by the pgvector extension) are highly resource-intensive and rely heavily on RAM. To maintain fast vector similarity searches and avoid high-latency disk operations, the entire vector index must fit into memory (RAM residency). Scaling up the database instance's memory directly expands the PostgreSQL shared buffers and cache, ensuring the high-dimensional index remains resident in RAM for rapid semantic retrieval.
Box 3: Enable storage autoscale
Enable storage autoscale is the best action to support the continuous ingestion of transaction- based embeddings.
Continuous Ingestion Demands Dynamic Space: Continuous transaction processing causes vector databases (such as Azure Database for PostgreSQL with pgvector or Azure SQL Database) to expand constantly over time.
Preventing Ingestion Failures: If storage reaches capacity limits, the database switches into a read-only state. This immediately fails and halts all incoming real-time embedding write operations. Enabling storage autoscale allows the environment to dynamically provision storage on the fly without downtime.
Reference:
https://dl.acm.org/doi/10.1145/3695053.3731013
https://learn.microsoft.com/en-us/training/paths/develop-ai-solutions-azure-database-postgresql/
https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
NEW QUESTION # 118
Hotspot Question
You are developing several microservices to run on Azure Container Apps. External HTTP ingress traffic has been enabled for the microservices.
A deployed microservice must be updated to allow users to test new features. You have the following requirements:
- Enable and maintain a single URL for the updated microservice to
provide to test users.
- Update the microservice that corresponds to the current microservice
version.
You need to configure Azure Container Apps.
Which features should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.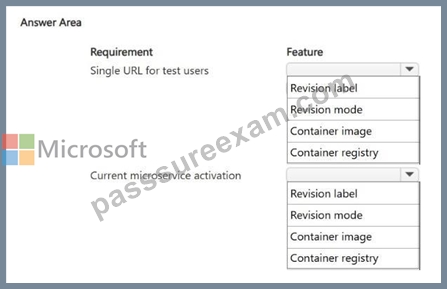
Answer:
Explanation: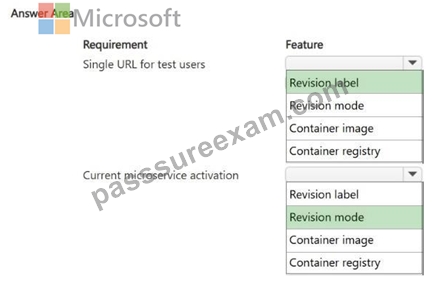
Explanation:
Box 1: Revision label
You should use the revision labels feature in Azure Container Apps. This feature allows you to assign a dedicated, permanent URL to a specific version (or revision) of your microservice.
Box 2: Revision mode
The application's Revision mode must be configured to Multiple. This allows the existing (current) microservice version to remain active and serve production traffic concurrently while you spin up the updated revision for the test users to access safely.
Reference:
https://learn.microsoft.com/en-us/azure/container-apps/microservices
NEW QUESTION # 119
Hotspot Question
You plan to develop an Azure Functions app with an HTTP trigger.
The app must support the following functionality:
- Event-driven scaling
- Ability to use custom Linux images for function execution
You need to identify the app's hosting plan and the maximum amount of time that the app function can take to respond to incoming requests.
Which configuration setting values should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.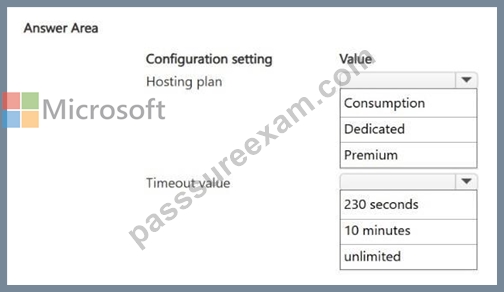
Answer:
Explanation: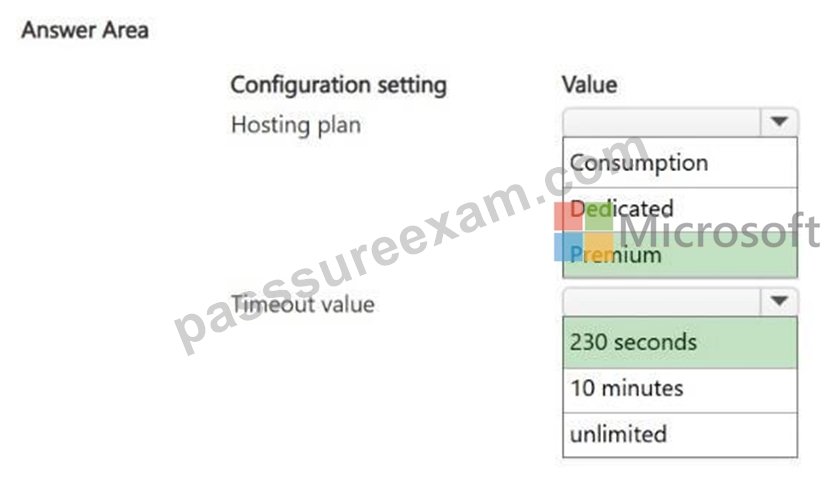
Explanation:
Box 1: Premium
To fulfill your requirements, you should use the Azure Functions Premium plan (also known as the Elastic Premium plan).
Event-Driven Scaling: It features dynamic, automatic scale-out driven by the Azure scale controller. It can scale down to zero instances when idle, ensuring you only pay for active compute time.
Custom Linux Images: Unlike the base Consumption plan, the Premium plan allows you to deploy and run your functions inside a custom Linux container image. This lets you bring your own custom OS dependencies, specialized tools, or specific runtime environments.
Box 2: 230 seconds
The correct maximum timeout value to use for an HTTP-triggered function is 230 seconds.
Azure Load Balancer Limit: Regardless of the specific Azure Functions hosting plan or timeout configurations you set in host.json, the Azure Functions Scale and Hosting documentation states that an HTTP-triggered function has a hard limit of 230 seconds to respond to a request.
Idle Timeout: This constraint is strictly enforced due to the default idle timeout of the underlying Azure Load Balancer. If your function runs longer than 230 seconds without returning a response, the connection will be dropped, resulting in a timeout error.
Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-deployment-technologies
https://learn.microsoft.com/en-us/azure/azure-functions/functions-scale
NEW QUESTION # 120
You are developing an AI-powered API that retrieves connection strings and API keys from Azure Key Vault.
You must configure a solution that provides the following security functionality:
* The API must authenticate to Key Vault without storing credentials in any application configuration files
* The identity used by the API must have only the minimum permissions necessary to read secrets.
* The configuration must minimize the blast radius if an identity or credential is compromised.
You need to implement a secure access strategy for the API.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
Detailed Explanation: The API should use a system-assigned managed identity so no application credential is stored or rotated by the development team. That identity should receive only the permission needed to read secret values: Key Vault Secrets User at the vault scope is materially narrower than Key Vault Administrator at subscription scope. Storing a secret value in App Configuration would violate the requirement to protect secrets and increases exposure. The corrected pair therefore implements both credential-free authentication and least-privilege authorization with a limited blast radius.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Azure Key Vault RBAC guide | Managed identities for Azure resources
NEW QUESTION # 121
......
All these three AI-200 exam questions formats are easy to use and compatible with all devices, operating systems, and web browsers. Just choose the best AI-200 exam questions format and start Microsoft AI-200 exam preparation without wasting further time. As far as the price of Developing AI Cloud Solutions on Azure exam practice test questions is concerned, these exam practice test questions are being offered at a discounted price. Get benefits from AI-200 Exam Questions at discounted prices and download them quickly. Best of luck in AI-200 exam and career!!!
New AI-200 Test Sample: https://www.passsureexam.com/AI-200-pass4sure-exam-dumps.html
P.S. Free 2026 Microsoft AI-200 dumps are available on Google Drive shared by PassSureExam: https://drive.google.com/open?id=1KO1tbgqI2DUiLVyY4QYXbkWUa_h5nsxY