What's more, part of that FreePdfDump AI-300 dumps now are free: https://drive.google.com/open?id=1DL2eVNlyRTUXbmUjkK1UADGQIYGmC5Fa
About the dynamic change of our AI-300 guide quiz, they will send the updates to your mailbox according to the trend of the exam. Besides, we understand you may encounter many problems such as payment or downloading AI-300 practice materials and so on, contact with us, we will be there. Our employees are diligent to deal with your need and willing to do their part 24/7. They always treat customers with courtesy and respect to satisfy your need on our AI-300 Exam Dumps.
| Section | Objectives |
|---|---|
| Topic 1: Operationalizing machine learning solutions | - Deployment and monitoring
|
| Topic 2: Implement secure and scalable AI systems | - Security and governance
|
| Topic 3: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Topic 4: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
>> Interactive AI-300 Practice Exam <<
You can try the free demo version of any Microsoft AI-300 exam dumps format before buying. For your satisfaction, FreePdfDump gives you a free demo download facility. You can test the features and then place an order. So, these real and updated Microsoft dumps are essential to pass the AI-300 Exam on the first try.
NEW QUESTION # 148
An organization maintains separate Azure Machine Learning workspaces for development and production.
Both environments must use the same validated assets without duplicating them.
Assets must be shared across workspaces while maintaining centralized governance and version control.
You need to enable reuse of assets across workspaces without copying them.
What should you do?
Answer: B
Explanation:
To share validated assets between development and production workspaces while maintaining centralized governance and version control, you should use Azure Machine Learning Registries.
Microsoft Learn
Unlike standard workspaces, registries are workspace-agnostic. They act as a central catalog that decouples assets from individual environments, allowing you to "promote" a model or environment from Dev to Prod without manual duplication or data drift.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-machine-learning-registries- mlops
NEW QUESTION # 149
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.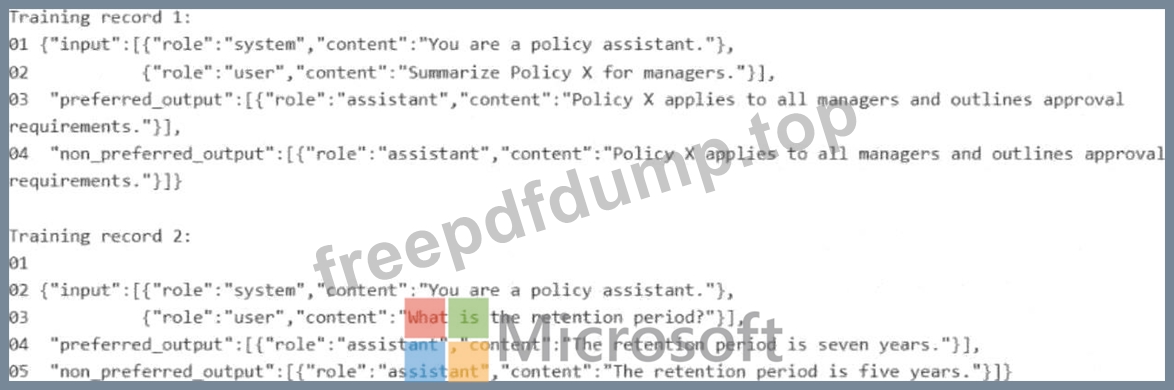
For each of the following statements, select Yes if the statement is true. Otherwise, select No . NOTE: Each correct selection is worth one point.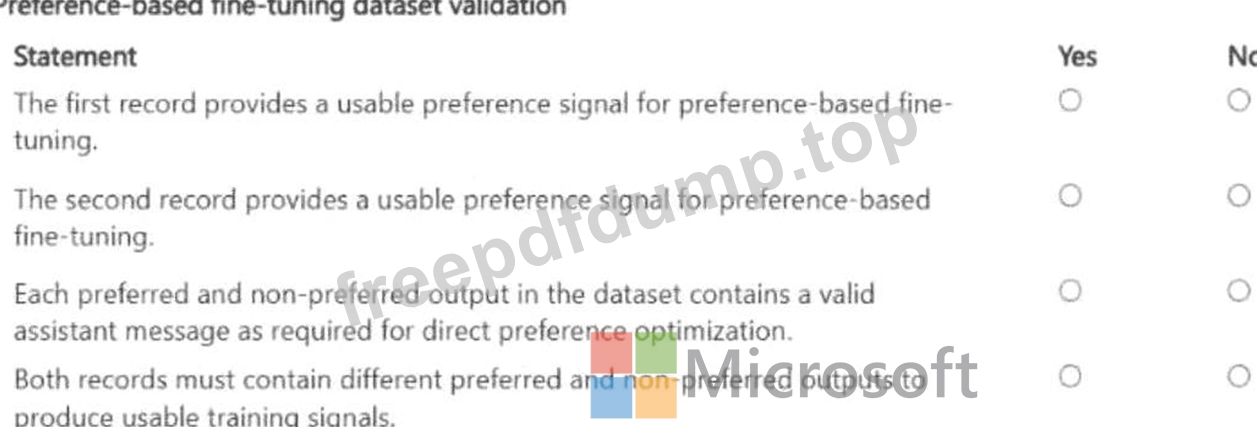
Answer:
Explanation: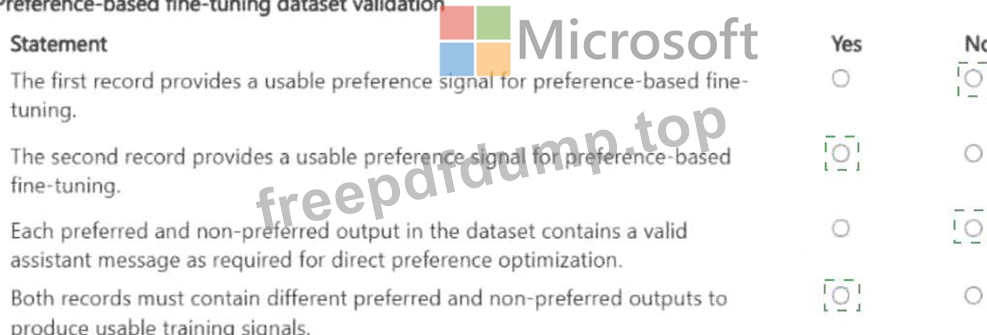
Explanation:
Preference comparison data with chosen versus rejected response pairs is the input format for Direct Preference Optimization (DPO) or RLHF-style fine-tuning - an advanced fine-tuning technique available in Microsoft Foundry. A valid DPO dataset record must have three fields: a prompt as the input, a chosen field containing the preferred response, and a rejected field containing the less preferred response. The file must be in JSONL format with UTF-8 encoding, where each line represents one complete preference pair. When evaluating statements about this dataset, mark True if the dataset contains all three required fields and chosen responses represent higher-quality outputs than rejected ones. Mark False if the format is incompatible with DPO requirements, if the required rejected field is missing, or if the chosen and rejected responses appear to be of equivalent quality with no clear preference signal.
Microsoft Learn Reference Topic: Advanced fine-tuning with preference data in Microsoft Foundry - DPO dataset format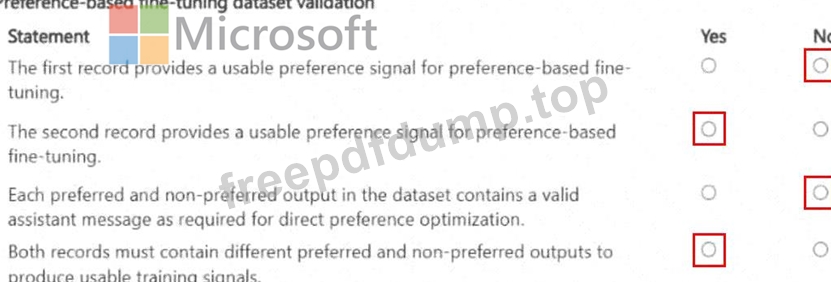
NEW QUESTION # 150
You create a multi-class image classification model with automated machine learning in Azure Machine Learning.
You need to prepare labeled image data as input for model training in the form of an Azure Machine Learning tabular dataset.
Which data format should you use?
Answer: C
Explanation:
Azure Machine Learning, you should use the JSON Lines (.jsonl) format.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-prepare-datasets-for-automl-images?view=azureml-api-2
NEW QUESTION # 151
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to refine a GPT-5 model so that its performance and behavior align with the technical and business requirements of Fabrikam Inc.
Which two Foundry strategies should you apply? Each correct answer presents a complete solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Scenario, Technical Requirements:
Improve RAG-based solution output quality.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Business Requirements:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
The two Foundry strategies that would be most useful in this scenario are Evaluations and Supervised fine-tuning.
Evaluations: This strategy is critical for improving RAG-based solution output quality. It provides systemic measurement to test how changes to your data, prompts, or retrieval chunks impact the accuracy, relevance, and groundedness of the model's answers before moving to more complex methods.
Supervised fine-tuning: This strategy directly satisfies the requirement to apply advanced fine- tuning techniques only when prompt engineering is insufficient. It allows you to deeply customize the model's behavior and conversational tone to fit your specific analytics interface requirements.
Incorrect:
Guardrails: While valuable for safety and compliance, guardrails focus on enforcing hard operational boundaries (e.g., blocking toxic content or preventing data leaks). They do not optimize RAG output quality or provide advanced behavioral updates when prompt engineering fails.
Synthetic data generation: While helpful for bootstrapping training datasets when real-world data is scarce, it is an data-preparation step rather than a core model refinement strategy designed to iteratively solve prompt engineering limitations or build conversational systems.
Reference:
https://medium.com/@hugoparreao/context-engineering-what-really-improves-the-performance-of-llms-0c0e3ed45c98
NEW QUESTION # 152
Hotspot Question
You monitor an Azure Machine Learning classification training experiment named train_classification on Azure Notebooks.
You must store a table named table as an artifact in Azure Machine Learning Studio during model training.
You need to collect and list the metrics by using MLflow.
How should you complete the code segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.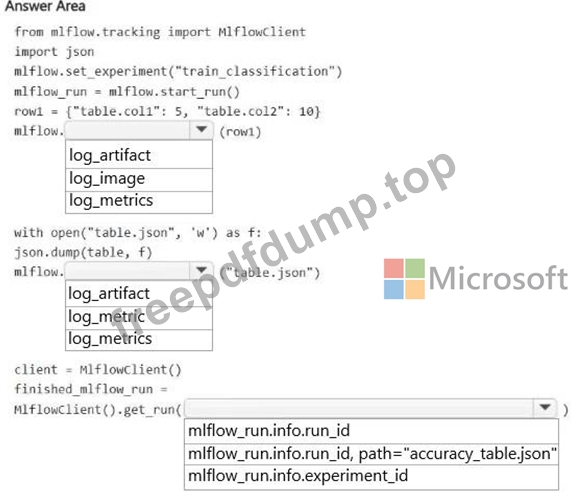
Answer:
Explanation: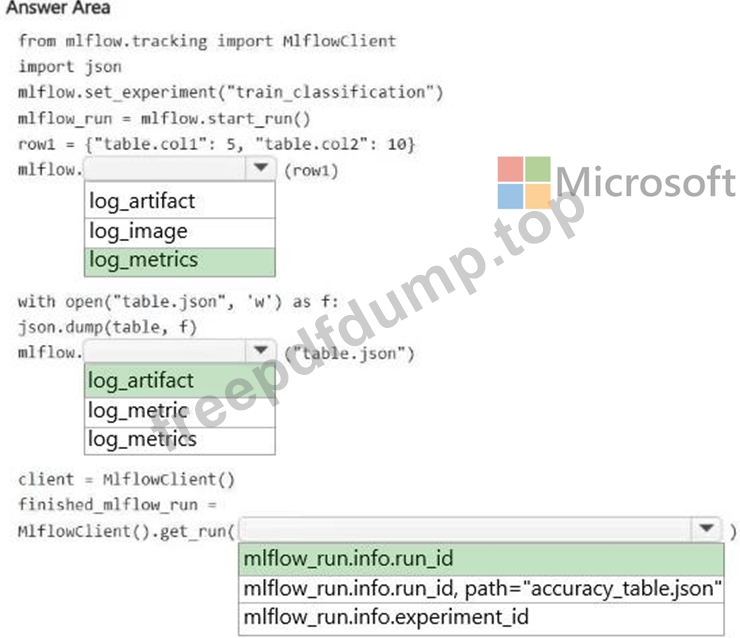
Explanation:
Box 1: log_metrics
Log Metrics dictionary
The dictionary row1 contains key-value pairs representing metrics. The mlflow.log_metrics() function is used to log multiple metrics simultaneously.
Box 2: log_artifact
Save Table Artifact
The code writes a JSON file locally and needs to upload it to the experiment run. The mlflow.log_artifact() function logs a local file or directory as an artifact in Azure Machine Learning Studio.
Box 3: mlflow_run.info.run_id
Retrieve Run ID
To fetch the finalized run data using the MlflowClient, you need to pass the unique run ID string.
This identifier is accessed via the active run object using mlflow_run.info.run_id. Note that you also need to use the instantiated client object variable instead of the class name MlflowClient to call the method correctly.
Reference:
https://levelup.gitconnected.com/mlops-mastering-mlflow-unlocking-efficient-model-management-and-experiment-tracking-d9d0e71cc697
NEW QUESTION # 153
......
The FreePdfDump is the top-rated website that offers real Operationalizing Machine Learning and Generative AI Solutions AI-300 exam dumps to prepare for the Microsoft AI-300 test. FreePdfDump has made these latest AI-300 practice test questions with the cooperation of the world's highly experienced professionals. Countless AI-300 Exam candidates have used these latest AI-300 exam dumps to prepare for the Microsoft AI-300 certification exam and they all got success with brilliant results.
Exam AI-300 Flashcards: https://www.freepdfdump.top/AI-300-valid-torrent.html
BTW, DOWNLOAD part of FreePdfDump AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1DL2eVNlyRTUXbmUjkK1UADGQIYGmC5Fa