無料でクラウドストレージから最新のFast2test Databricks-Certified-Professional-Data-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=12CWU92nghYtJUIefz-X5MLwwWIodKH1J
今の競争が激しい社会にあたり、あなたは努力して所有したいことがあります。IT職員にとって、Databricks-Certified-Professional-Data-Engineer試験認定書はあなたの実力を証明できる重要なツールです。だから、Databricks Databricks-Certified-Professional-Data-Engineer試験に合格する必要があります。それで、弊社の質高いDatabricks-Certified-Professional-Data-Engineer試験資料を薦めさせてください。
| Section | Objectives |
|---|---|
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Cost optimization and performance tuning - Implement Unity Catalog governance and access control |
| Data Modeling and Storage | - Design scalable data lakehouse architectures - Delta Lake table design and optimization - Schema evolution and data partitioning strategies |
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks |
| Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling |
>> Databricks Databricks-Certified-Professional-Data-Engineer入門知識 <<
これらすべてのDatabricks-Certified-Professional-Data-Engineer学習教材で、あなたの成功は100%保証されます。さらに、無料のデモがあります。無料のデモでは、練習資料の内容について証明された経験に基づいた推測を提供します。この試験について決心している限り、その職業は疑う余地がないことを理解できます。そして、彼らの職業はDatabricks-Certified-Professional-Data-Engineerトレーニング準備で徹底的に表現されています。彼らはDatabricks-Certified-Professional-Data-Engineer試験の本当の知識をつかみ、忘れられない経験をするのに非常に役立ちます。この小さなメリットをお見逃しなく。
質問 # 168
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: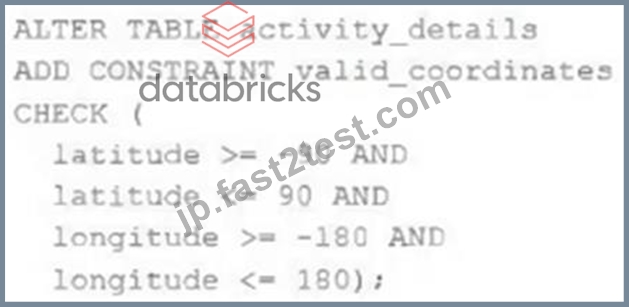
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
正解:D
解説:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
質問 # 169
One of the queries in the Databricks SQL Dashboard takes a long time to refresh, which of the be-low steps can be taken to identify the root cause of this issue?
正解:A
解説:
Explanation
The answer is, Use Query History, to view queries and select query, and check the query profile to see time spent in each step.
Here is the view of the query profile, for more info use the link
https://docs.microsoft.com/en-us/azure/databricks/sql/admin/query-profile As you can see here Databricks SQL query profile is much different to Spark UI and provides much more clear information on how time is being spent on different queries and time it spent on each step.
Graphical user interface, application Description automatically generated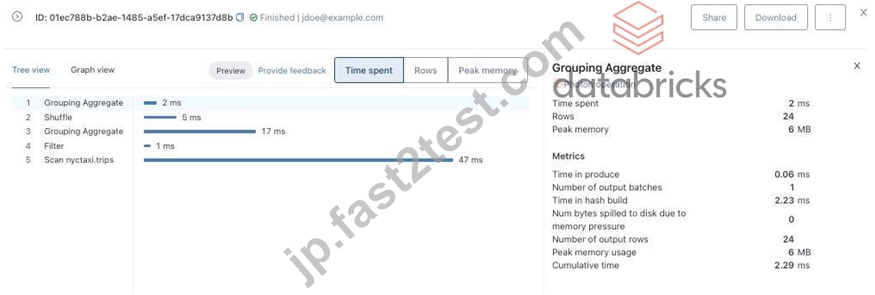
質問 # 170
You were asked to create a notebook that can take department as a parameter and process the data accordingly, which is the following statements result in storing the notebook parameter into a py-thon variable
正解:B
解説:
Explanation
The answer is department = dbutils.widget.get("department")
Refer to additional documentation here
https://docs.databricks.com/notebooks/widgets.html
質問 # 171
Which of the following SQL statements can replace python variables in Databricks SQL code, when the notebook is set in SQL mode?
1.%python
2.table_name = "sales"
3.schema_name = "bronze"
4.
5.%sql
6.SELECT * FROM ____________________
正解:A
解説:
Explanation
The answer is, SELECT * FROM ${schema_name}.${table_name}
%python
table_name = "sales"
schema_name = "bronze"
%sql
SELECT * FROM ${schema_name}.${table_name}
${python variable} -> Python variables in Databricks SQL code
質問 # 172
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFramedf. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFramedfhas the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: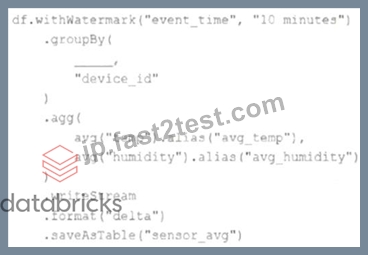
Choose the response that correctly fills in the blank within the code block to complete this task.
正解:E
解説:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "WINDOW" section.https://www.databricks.com/blog/2017/05/08/event-time-aggregation- watermarking-apache-sparks-structured-streaming.html
質問 # 173
......
IT業種が新しい業種で、経済発展を促進するチェーンですから、極めて重要な存在ということを我々は良く知っています。IT認証はIT業種での競争な手段の一つです。認証に受かったらあなたは各方面でよく向上させます。でも、受かることが難しいですから、トレーニングツールを利用するのを勧めます。トレーニング資料を選びたいのなら、Fast2testのDatabricksのDatabricks-Certified-Professional-Data-Engineer試験トレーニング資料は最高の選択です。この資料の成功率が100パーセントに達して、あなたが試験に合格することを保証します。
Databricks-Certified-Professional-Data-Engineer日本語版テキスト内容: https://jp.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
P.S. Fast2testがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=12CWU92nghYtJUIefz-X5MLwwWIodKH1J