The company is preparing for the test candidates to prepare the DP-750 exam guide professional brand, designed to be the most effective and easiest way to help users through their want to get the test DP-750 certification and obtain the relevant certification. In comparison with similar educational products, our training materials are of superior quality and reasonable price, so our company has become the top enterprise in the international market. Our DP-750 practice materials have been well received by the users, mainly reflected in the following advantages.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
>> Reliable DP-750 Exam Registration <<
Although it is not an easy thing for most people to pass the exam, therefore, they can provide you with efficient and convenience learning platform, so that you can obtain as many certificates as possible in the shortest time. We provide all candidates with DP-750 test torrent that is compiled by experts who have good knowledge of exam, and they are very experience in compile study materials. Not only that, our team checks the update every day, in order to keep the latest information of DP-750 latest question. Once we have latest version, we will send it to your mailbox as soon as possible.
NEW QUESTION # 59
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
Answer: C
Explanation:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
NEW QUESTION # 60
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 61
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.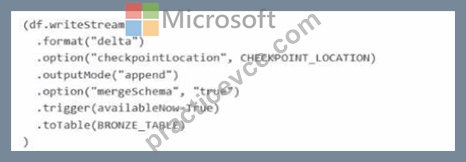
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.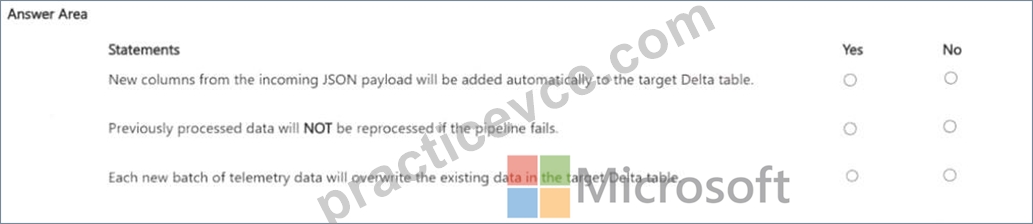
Answer:
Explanation: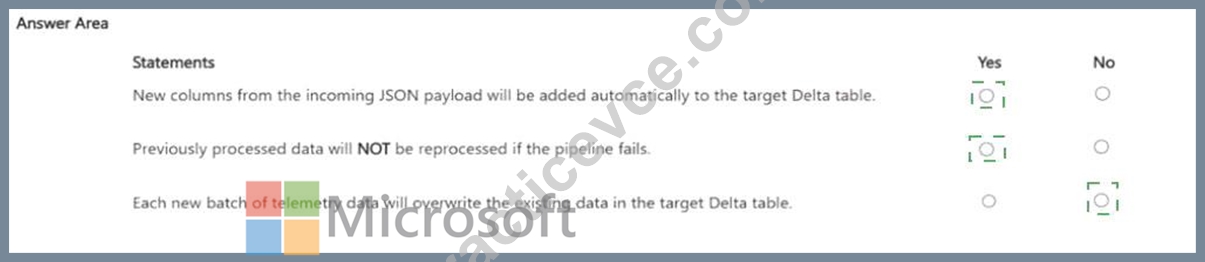
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 62
You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
What should you do?
Answer: B
Explanation:
Lakeflow Jobs provides native orchestration for multi-task Databricks workflows. Separate ingestion, cleansing, and curation tasks can be connected through explicit dependencies, ensuring that each stage starts only after its required upstream work succeeds. Each task can also have independent retry, notification, timeout, and compute settings, directly addressing the pipeline's resiliency requirements. Azure Data Factory could orchestrate notebooks, but it introduces another service when Lakeflow Jobs already provides the required functionality. A single notebook makes failures harder to isolate and can force successful stages to be rerun. Independently scheduled jobs rely on timing assumptions rather than actual task completion and can fail when an upstream stage runs longer than expected. Explicit Lakeflow Jobs dependencies provide reliable execution order and centralized monitoring. Microsoft Learn
NEW QUESTION # 63
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: A
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 64
......
The pass rate for DP-750 learning materials is 98.75%, and you can pass the exam successfully by using the DP-750 exam dumps of us. We also pass guarantee and money back guarantee if you fail to pass the exam, and the refund money will be returned to your payment account. The DP-750 Learning Materials are famous for their high-quality, and if you choose, they can not only improve your ability in the process of learning but also help you get the certificate successfully. Choose us, and you will never regret.
Exam DP-750 Questions Fee: https://www.practicevce.com/Microsoft/DP-750-practice-exam-dumps.html