Many companies' executives have a job content that purchasing Certified-Data-Engineer-Professional valid exam collection PDF help their engineers to pass exam and obtain a useful certificate. It is not only improving the qualification of engineers personal but also showing the qualification of companies. If they choose right Certified-Data-Engineer-Professional valid exam collection PDF they will save a lot of exam cost and dumps fee for companies. Our products will be excellent choice with high passing rate.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
>> Certified-Data-Engineer-Professional Reliable Test Objectives <<
Databricks certification Certified-Data-Engineer-Professional exams has become more and more popular in the fiercely competitive IT industry. Although more and more people sign up to attend this examination of, the official did not reduce its difficulty and it is still difficult to pass the exam. After all, this is an authoritative test to inspect the computer professional knowledge and information technology ability. In order to pass the Databricks Certification Certified-Data-Engineer-Professional Exam, generally, many people need to spend a lot of time and effort to review.
NEW QUESTION # 38
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team: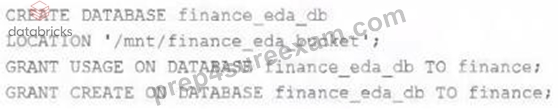
After the database was successfully created and permissions configured, a member of the finance team runs the following code: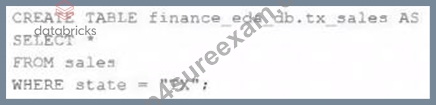
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
Answer: D
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 39
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API.
They need to list all jobs, identify a failed job, and rerun it. Which sequence of API actions should the data engineer perform?
Answer: B
Explanation:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
NEW QUESTION # 40
A security analytics pipeline must enrich billions of raw connection logs with geolocation data.
The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events ( 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges ( 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
Answer: D
Explanation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute- force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
NEW QUESTION # 41
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
Answer: C
Explanation:
In Databricks, owning a catalog or schema does not automatically grant access to the tables within it. Table-level permissions are separate, so even the schema or catalog owner must be explicitly granted privileges on individual tables or use the ability to grant themselves access.
NEW QUESTION # 42
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
Answer: C
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 43
......
Based on high-quality products, our Certified-Data-Engineer-Professional guide torrent has high quality to guarantee your test pass rate, which can achieve 98% to 100%. Certified-Data-Engineer-Professional study tool is updated online by our experienced experts, and then sent to the user. And we provide free updates of Certified-Data-Engineer-Professional training material for one year after your payment. The data of our Certified-Data-Engineer-Professional Exam Torrent is forward-looking and can grasp hot topics to help users master the latest knowledge. And you can also free download the demo of Certified-Data-Engineer-Professional exam questions to have a check.
PDF Certified-Data-Engineer-Professional Cram Exam: https://www.prep4sureexam.com/Certified-Data-Engineer-Professional-dumps-torrent.html