Pass Guaranteed Quiz 2026 Databricks Databricks-Generative-AI-Engineer-Associate: Databricks Certified Generative AI Engineer Associate–High-quality Valid Exam Preparation

2026 Latest Test4Engine Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1ey5oTzcK4ab4T8J71onMB_eFcsWp1uBC
Test4Engine Databricks Databricks-Generative-AI-Engineer-Associate Practice Test give you the opportunity to practice for the Databricks Databricks-Generative-AI-Engineer-Associate new exam questions. By using Databricks Practice Test, you can get the ideal possibility to know the actual Databricks Certified Generative AI Engineer Associate exam, as they follow the same interface as the real exam. This way, you can become more confident and comfortable while taking the actual exam.
Databricks Databricks-Generative-AI-Engineer-Associate Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
|---|
| Exam Number: | Generative AI Engineer Associate |
|---|
| Exam Format: | Multiple Select, Multiple Choice |
|---|
| Real Exam Qty: | 45 |
|---|
| Exam Duration: | 90 minutes |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Passing Score: | Scaled Score (approx. 70%) |
|---|
| Available Languages: | English, Portuguese (Brazil), Korean, Japanese |
|---|
| Exam Price: | $200 USD |
|---|
| Related Certifications: | Databricks Certified Data Engineer Associate
Databricks Certified Machine Learning Associate |
|---|
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
|---|
| Exam Way: | Online (Proctored) or Test Center |
|---|
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
|---|
>> Valid Exam Databricks-Generative-AI-Engineer-Associate Preparation <<
Efficient and Convenient Preparation with Test4Engine's Updated Databricks Databricks-Generative-AI-Engineer-Associate Exam Dumps
“There is no royal road to learning.” Learning in the eyes of most people is a difficult thing. People are often not motivated and but have a fear of learning. However, the arrival of Databricks-Generative-AI-Engineer-Associate study materials will make you no longer afraid of learning. Databricks-Generative-AI-Engineer-Associate study material provides you with a brand-new learning method that lets you get rid of heavy schoolbags, lose boring textbooks, and let you master all the important knowledge in the process of making a question. Please believe that with Databricks-Generative-AI-Engineer-Associate Study Materials, you will fall in love with learning.
| Topic | Details |
|---|
| Topic 1 | - Assembling and Deploying Applications: In this topic, Generative AI Engineers get knowledge about coding a chain using a pyfunc mode, coding a simple chain using langchain, and coding a simple chain according to requirements. Additionally, the topic focuses on basic elements needed to create a RAG application. Lastly, the topic addresses sub-topics about registering the model to Unity Catalog using MLflow.
|
| Topic 2 | - Evaluation and Monitoring: This topic is all about selecting an LLM choice and key metrics. Moreover, Generative AI Engineers learn about evaluating model performance. Lastly, the topic includes sub-topics about inference logging and usage of Databricks features.
|
| Topic 3 | - Application Development: In this topic, Generative AI Engineers learn about tools needed to extract data, Langchain
- similar tools, and assessing responses to identify common issues. Moreover, the topic includes questions about adjusting an LLM's response, LLM guardrails, and the best LLM based on the attributes of the application.
|
| Topic 4 | - Design Applications: The topic focuses on designing a prompt that elicits a specifically formatted response. It also focuses on selecting model tasks to accomplish a given business requirement. Lastly, the topic covers chain components for a desired model input and output.
|
| Topic 5 | - Data Preparation: Generative AI Engineers covers a chunking strategy for a given document structure and model constraints. The topic also focuses on filter extraneous content in source documents. Lastly, Generative AI Engineers also learn about extracting document content from provided source data and format.
|
Databricks Certified Generative AI Engineer Associate Sample Questions (Q27-Q32):
NEW QUESTION # 27
A Generative AI Engineer I using the code below to test setting up a vector store:
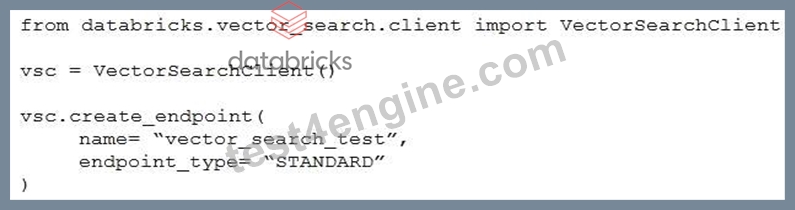
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
- A. vsc.create_direct_access_index()
- B. vsc.create_delta_sync_index()
- C. vsc.get_index()
- D. vsc.similarity_search()
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 28
A Generative AI Engineer is building a multi-turn chat app with LangGraph on Databricks. The app must persist chat history-messages, roles, timestamps, and session IDs-for many concurrent users, support SQL queries, and stay governed in Unity Catalog. The engineer also wants ACID guarantees, low-latency reads and writes, and an easy way to sync chat data into Delta tables for analytics and model training.
Which approach fits these requirements?
- A. Use Lakebase with a chat_history table wired to a Postgres-backed LangGraph checkpoint/memory component and enable synchronization from Lakebase into Delta tables.
- B. Use a custom in-memory LangGraph state store running on the Databricks cluster driver, and periodically snapshot the state to JSON files in DBFS.
- C. Write each turn from a custom LangGraph node directly into a Delta table with Spark append, then query history via Spark SQL on every request.
- D. Store conversation history in MLflow runs and retrieve it via the MLflow Tracking API inside LangGraph nodes.
Answer: A
Explanation:
Lakebase provides a Postgres database suited to transactional application state, including concurrent chat- history reads and writes. A Postgres-backed LangGraph checkpoint or memory component can persist conversation state across requests and application restarts. SQL support and transactional guarantees address the application's operational requirements. Databricks also documents registering Lakebase databases in Unity Catalog and feeding Lakebase changes into Delta tables for downstream analytics. These integrations require appropriate configuration and permissions; they are not automatic simply because a table exists.
MLflow runs are intended for experiment and application tracking rather than serving as a low-latency conversation database. Per-turn Spark writes introduce unnecessary processing overhead, while driver- memory storage with periodic snapshots risks losing recent conversation state. Databricks documentation
NEW QUESTION # 29
Which of the following statements accurately identifies differences between the evaluation phase and the monitoring phase in the Generative AI application lifecycle within Databricks?
- A. The evaluation phase ensures the agent's responses comply with business rules in production, whereas the monitoring phase is focused on SLA and performance metrics.
- B. The evaluation phase logs and traces live API calls in production, while the monitoring phase runs metrics on inference tables containing those traces.
- C. The evaluation phase uses Mosaic AI Agent Evaluation and an evaluation dataset to assess an agent's performance metrics and traces, while the monitoring phase relies on inference tables as source data for creating a metrics profile.
- D. The evaluation phase uses all inference history to assess agent performance and readiness for production, while the monitoring phase uses only new inference-table records to monitor performance.
Answer: C
Explanation:
A best describes the dataset-based evaluation and inference-table-based monitoring workflow referenced in the question. Evaluation runs an application against selected test cases, collects traces, and calculates metrics to compare versions or detect regressions. Production monitoring examines real usage over time to identify operational or quality problems. Evaluation does not require all historical inference records, and monitoring is not limited to latency or service-level metrics; it can also assess response quality and policy adherence.
Option B incorrectly treats production tracing as the defining evaluation activity. Current MLflow 3 monitoring can apply scorers directly to production traces, so inference-table metrics profiles are one documented monitoring architecture rather than a universal requirement for every modern Databricks deployment. Evaluation documentation , monitoring documentation
NEW QUESTION # 30
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
- A. Embed authentication credentials within the agent's code to access the required resources.
- B. Define resource dependencies while logging the agent and deploy it with the Agent Framework.
- C. Set appropriate permissions on the Model Serving endpoint for the agent, as these permissions will be used when connecting to other resources.
- D. Log the authentication token while logging the agent; this token will be automatically used for authentication.
Answer: B
Explanation:
For agents deployed through Model Serving, Databricks supports automatic authentication passthrough for declared resources. The engineer records the agent's dependencies through the resources parameter when logging the model. During deployment, Databricks checks the deployer's access, creates a service principal for the agent model version, grants the required resource access, and supplies short-lived credentials.
Credential rotation is handled automatically. Supported dependencies include Vector Search indexes, SQL warehouses, and Unity Catalog functions. This approach avoids embedding secrets in source code or recording authentication tokens as model artifacts. Permissions on the serving endpoint govern access to that endpoint; they do not independently establish all downstream resource permissions. All required dependencies, including relevant underlying resources, must be declared correctly. Databricks documentation
NEW QUESTION # 31
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email:
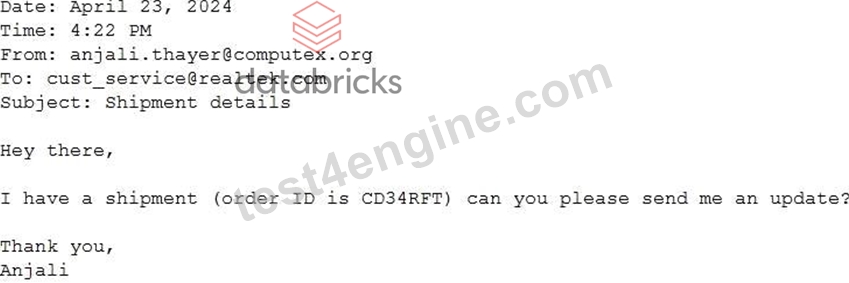
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
- A. You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.
- B. You will receive customer emails and need to extract date, sender email, and order ID. You should return the date, sender email, and order ID information in JSON format.
- C. You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in a human-readable format.
- D. You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.
Here's an example: {"date": "April 16, 2024", "sender_email": "sarah.lee925@gmail.com", "order_id":
"RE987D"}
Answer: D
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 32
......
Databricks-Generative-AI-Engineer-Associate Exam Study Solutions: https://www.test4engine.com/Databricks-Generative-AI-Engineer-Associate_exam-latest-braindumps.html
- Databricks-Generative-AI-Engineer-Associate Reliable Exam Cost 🏋 Databricks-Generative-AI-Engineer-Associate Reliable Exam Cost ↘ Reliable Databricks-Generative-AI-Engineer-Associate Test Notes 🕑 Search on ➡ www.verifieddumps.com ️⬅️ for 【 Databricks-Generative-AI-Engineer-Associate 】 to obtain exam materials for free download ◀Databricks-Generative-AI-Engineer-Associate Practice Online
- The Best Databricks-Generative-AI-Engineer-Associate - Valid Exam Databricks Certified Generative AI Engineer Associate Preparation 🚒 ⏩ www.pdfvce.com ⏪ is best website to obtain ☀ Databricks-Generative-AI-Engineer-Associate ️☀️ for free download 🖤Exam Databricks-Generative-AI-Engineer-Associate Cram Questions
- Exam Databricks-Generative-AI-Engineer-Associate Cram Questions 😧 Databricks-Generative-AI-Engineer-Associate Latest Exam Fee 🦜 Databricks-Generative-AI-Engineer-Associate Technical Training 🏓 Search on ☀ www.pass4test.com ️☀️ for [ Databricks-Generative-AI-Engineer-Associate ] to obtain exam materials for free download ⭐Training Databricks-Generative-AI-Engineer-Associate Materials
- Databricks-Generative-AI-Engineer-Associate Practice Online 🎴 Databricks-Generative-AI-Engineer-Associate Exam Course 🛤 Test Databricks-Generative-AI-Engineer-Associate Simulator Fee 👉 Immediately open ☀ www.pdfvce.com ️☀️ and search for ➥ Databricks-Generative-AI-Engineer-Associate 🡄 to obtain a free download 🧭Exam Databricks-Generative-AI-Engineer-Associate Cram Questions
- Three Convenient Formats for Databricks Databricks-Generative-AI-Engineer-Associate Practice Test Questions 🔂 Search for ⏩ Databricks-Generative-AI-Engineer-Associate ⏪ and download it for free immediately on ➡ www.troytecdumps.com ️⬅️ ➖Databricks-Generative-AI-Engineer-Associate Exam Questions And Answers
- Reliable Databricks-Generative-AI-Engineer-Associate Test Answers 🥿 Databricks-Generative-AI-Engineer-Associate Exam Course 🚮 Valid Databricks-Generative-AI-Engineer-Associate Test Labs 🦥 Search for ➤ Databricks-Generative-AI-Engineer-Associate ⮘ and obtain a free download on ⏩ www.pdfvce.com ⏪ 🚑Databricks-Generative-AI-Engineer-Associate Accurate Answers
- Most Databricks-Generative-AI-Engineer-Associate Reliable Questions 😃 Exam Databricks-Generative-AI-Engineer-Associate Cram Questions 😂 Databricks-Generative-AI-Engineer-Associate Accurate Answers 📔 Search for ✔ Databricks-Generative-AI-Engineer-Associate ️✔️ and download it for free on ➠ www.practicevce.com 🠰 website 💯Most Databricks-Generative-AI-Engineer-Associate Reliable Questions
- Databricks-Generative-AI-Engineer-Associate Latest Exam Fee 🦄 Databricks-Generative-AI-Engineer-Associate Reliable Exam Cost 🐓 Valid Databricks-Generative-AI-Engineer-Associate Test Review 🐹 Easily obtain ➽ Databricks-Generative-AI-Engineer-Associate 🢪 for free download through ▛ www.pdfvce.com ▟ 🤢Reliable Databricks-Generative-AI-Engineer-Associate Test Answers
- Test Databricks-Generative-AI-Engineer-Associate Simulator Fee 🦢 Databricks-Generative-AI-Engineer-Associate Exam Questions And Answers ⏫ Databricks-Generative-AI-Engineer-Associate Exam Course 🍉 Enter ▷ www.exam4labs.com ◁ and search for 【 Databricks-Generative-AI-Engineer-Associate 】 to download for free 🕶Reliable Databricks-Generative-AI-Engineer-Associate Test Notes
- 2026 Valid Exam Databricks-Generative-AI-Engineer-Associate Preparation | Pass-Sure 100% Free Databricks Certified Generative AI Engineer Associate Exam Study Solutions 🆎 Open { www.pdfvce.com } enter ➡ Databricks-Generative-AI-Engineer-Associate ️⬅️ and obtain a free download 🧟Most Databricks-Generative-AI-Engineer-Associate Reliable Questions
- Databricks-Generative-AI-Engineer-Associate Latest Exam Fee ⬆ Databricks-Generative-AI-Engineer-Associate Exam Course 🚥 Exam Databricks-Generative-AI-Engineer-Associate Cram Questions 📀 Immediately open 【 www.vce4dumps.com 】 and search for ☀ Databricks-Generative-AI-Engineer-Associate ️☀️ to obtain a free download 🦍Databricks-Generative-AI-Engineer-Associate Technical Training
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest Test4Engine Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1ey5oTzcK4ab4T8J71onMB_eFcsWp1uBC