Pass Guaranteed DEA-C02 - SnowPro Advanced: Data Engineer (DEA-C02) Fantastic Exam Lab Questions

P.S. Free & New DEA-C02 dumps are available on Google Drive shared by Exam4Labs: https://drive.google.com/open?id=1ksD4o0Eq2BRvqd4sQWOKKETT-aLHxjRU
These real and updated Snowflake DEA-C02 dumps are essential to pass the DEA-C02 exam on the first try. Don't waste further time and money, get real Snowflake DEA-C02 pdf questions and practice test software, and start DEA-C02 Test Preparation today. Exam4Labs will also provide you with up to 365 days of free exam questions updates.
| Section | Weight | Objectives |
|---|
| Data Architecture and Processing | 20% | - Data Modeling for Performance
- 1. Star and snowflake schemas
- 2. Slowly changing dimensions (SCD)
- 3. Dimension handling
- Data Storage Architecture
- 1. Table types (Permanent, Transient, Temporary)
- 2. Hybrid Tables concepts
- 3. Micro-partitioning and clustering
- Data Pipeline Design
- 1. Stream and task patterns
- 2. Pipeline monitoring and error handling
- 3. Data scheduling and orchestration
|
| Security and Governance | 15% | - Data Security
- 1. Row-level security policies
- 2. External tokenization
- 3. Column-level security
- 4. Data masking and tokenization
- Access Control
- 1. Role-based access control (RBAC)
- 2. GRANT and REVOKE operations
- 3. Role hierarchy and ownership
- Governance and Compliance
- 1. Data retention policies
- 2. Access history and auditing
- 3. Row access policies
- 4. Object tagging
|
| Data Ingestion and Consumption | 20% | - Bulk Loading and Unloading
- 1. Data loading performance optimization
- 2. COPY INTO command options and best practices
- 3. File format options (CSV, JSON, Parquet, AVRO)
- 4. Handling staged files
- Continuous Data Loading
- 1. Automating data loading with tasks
- 2. Real-time data ingestion patterns
- 3. Snowpipe configuration and usage
- Data Unloading
- 1. Data export best practices
- 2. Unloading to internal and external stages
- 3. Partitioning unloading data
|
| Performance Optimization | 15% | - Data Optimization
- 1. Data cache management
- 2. Materialized views
- 3. Search optimization service
- Query Optimization
- 1. Query result caching
- 2. Query profiling and analysis
- 3. Indexing strategies with clustering
- 4. Avoiding common performance pitfalls
- Warehouse Performance
- 1. Warehouse scaling policies
- 2. Warehouse sizing and selection
- 3. Resource monitors
- 4. Multi-cluster warehouses
|
| Data Transformation with Snowflake | 30% | - Data Processing Patterns
- 1. MERGE, UPDATE, DELETE operations
- 2. Zero-copy cloning for ETL
- 3. Time travel and change data capture
- SQL Transformations
- 1. Window functions advanced usage
- 2. Working with semi-structured data (VARIANT)
- 3. Data type conversions and handling
- 4. Complex JOINs and set operations
- Snowflake Scripting
- 1. Procedures and control flow
- 2. Error handling
- 3. Dynamic SQL
|
>> Exam DEA-C02 Lab Questions <<
Valid DEA-C02 Exam Experience | DEA-C02 Reliable Exam Camp
Our to-the-point and trustworthy Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Exam Questions in three formats for the SnowPro Advanced: Data Engineer (DEA-C02) (DEA-C02) certification exam will surely assist you to qualify for Snowflake DEA-C02 certification. Do not underestimate the value of our Snowflake DEA-C02 Exam Dumps because it is the make-or-break point of your career. Therefore, make the most of this opportunity of getting these superb exam questions for the Financials in Snowflake DEA-C02 certification exam.
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q223-Q228):
NEW QUESTION # 223
You have a table 'EMPLOYEE DATA' containing Personally Identifiable Information (PII), including 'salary' and 'email'. You need to implement column-level security such that: 1) The 'salary' column is only visible to users in the 'FINANCE ROLE. 2) The 'email' column is masked with a SHA256 hash for all users except those in the 'HR ROLE. You create the following masking policies:
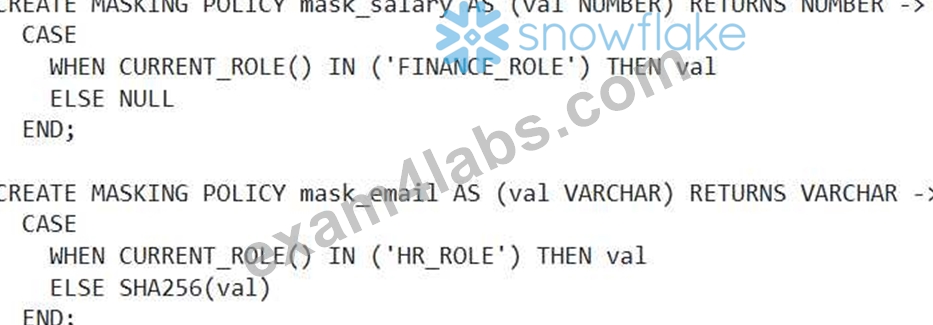
Which of the following SQL statements correctly applies these masking policies to the 'EMPLOYEE DATA table?
- A. ALTER TABLE EMPLOYEE_DATA MODIFY COLUMN salary SET MASKING POLICY = mask_salary; ALTER TABLE EMPLOYEE_DATA MODIFY COLUMN email SET MASKING POLICY = mask email;
- B. ALTER TABLE EMPLOYEE_DATAALTER COLUMN salary SET MASKING POLICY mask_salary; ALTER TABLE EMPLOYEE_DATAALTER COLUMN email SET MASKING POLICY mask email;
- C. ALTER TABLE EMPLOYEE_DATAAPPLY MASKING POLICY mask_salary ON COLUMN salary; ALTER TABLE EMPLOYEE_DATAAPPLY MASKING POLICY mask email ON COLUMN email;
- D. CREATE OR REPLACE TAG employee_data.salary VALUE 'mask_salary'; CREATE OR REPLACE TAG employee_data.email VALUE 'mask_email';
- E. ALTER TABLE EMPLOYEE_DATA MODIFY COLUMN salary SET MASKING POLICY mask_salary; ALTER TABLE EMPLOYEE_DATA MODIFY COLUMN email SET MASKING POLICY mask email;
Answer: B
Explanation:
The correct syntax for applying a masking policy to a column is 'ALTER TABLE ALTER COLUMN SET MASKING POLICY MODIFY COLUMN' is used for changing data types or constraints, not applying masking policies. The sign after 'SET MASKING POLICY is incorrect syntax. There's no 'APPLY MASKING POLICY command in Snowflake.
NEW QUESTION # 224
You are configuring a Snowflake Data Clean Room for two healthcare providers, 'ProviderA' and 'ProviderB', to analyze patient overlap without revealing Personally Identifiable Information (PII). Both providers have patient data in their respective Snowflake accounts, including a 'PATIENT ID' column that uniquely identifies each patient. You need to create a secure join that allows the providers to determine the number of shared patients while protecting the raw 'PATIENT ID' values. Which of the following approaches is the most secure and efficient way to achieve this using Snowflake features? Select TWO options.
- A. Leverage Snowflake's differential privacy features to add noise to the patient ID data, share the modified dataset and perform a JOIN.
- B. Create a hash of the 'PATIENT_ID' column in both ProviderA's and ProviderB's accounts using a consistent hashing algorithm (e.g., SHA256) and a secret salt known only to both providers. Share the hashed values through a secure view and perform a JOIN operation on the hashed values.
- C. Share the raw 'PATIENT_ID' columns between ProviderA and ProviderB using secure data sharing, and then perform a JOIN operation in either ProviderA's or ProviderB's account.
- D. Utilize Snowflake's Secure Aggregate functions (e.g., APPROX_COUNT_DISTINCT) on the 'PATIENT_ID' column without sharing the underlying data. Each provider calculates the approximate distinct count of patient IDs, and the results are compared to estimate the overlap.
- E. Implement tokenization of the 'PATIENT_ID' column in both ProviderA's and ProviderB's accounts. Share the tokenized values through a secure view and perform a JOIN operation on the tokens. Use a third party to deanonymize the tokens afterwards.
Answer: B,E
Explanation:
Options B and C represents valid approach. B provides good utility and is consistent. C does the same using a third-party service, which also works. Option A exposes the raw PII data which is not acceptable. Option D only gets an approximate, not an exact figure. While useful, the other solutions are much better. Option E is incorrect, it sounds good, but is not real. Therefore the correct answer is B and C.
NEW QUESTION # 225
You have a 'SALES table and a 'PRODUCTS table. The 'SALES table contains daily sales transactions, including 'SALE DATE , 'PRODUCT ID', and 'QUANTITY. The 'PRODUCTS table contains 'PRODUCT and 'CATEGORY. You need to create a materialized view to track the total quantity sold per category daily, optimized for fast query performance. You anticipate frequent updates to the 'SALES table but infrequent changes to the 'PRODUCTS table. Which of the following strategies would provide the MOST efficient materialized view implementation, considering both data freshness and query performance?
- A. Create a standard materialized view that joins 'SALES' and 'PRODUCTS' , grouping by 'SALE DATE and 'CATEGORY without any specific clustering key.
- B. Create a standard materialized view that joins 'SALES' and 'PRODUCTS' , grouping by 'SALE_DATE and 'CATEGORY, and defining a clustering key on 'SALE DATE.
- C. Create a standard materialized view that joins 'SALES' and 'PRODUCTS' , grouping by 'SALE_DATE and 'CATEGORY, and defining a clustering key on ' CATEGORY.
- D. Create two materialized views: one for daily sales by product and another joining the first with 'PRODUCTS' to aggregate by category. Cluster the first view by 'SALE DATE' and the second by 'CATEGORY'.
- E. Create a standard materialized view that joins 'SALES' and 'PRODUCTS' , grouping by 'SALE_DATE and 'CATEGORY, and defining a clustering key on 'SALE DATE' and 'CATEGORY.
Answer: B
Explanation:
Option B is most efficient. Clustering the materialized view on 'SALE_DATE will significantly improve query performance when filtering or grouping by date, which is a common operation in time-series data. Although frequent updates will affect the maintenance costs of the materialized view, querying on date will be very efficient. Option A is less efficient due to the lack of clustering. Option C may not be the best choice if filtering/grouping primarily occurs on date. Option D is also good, but Option B is better if most of the query filter is on SALE DATE. Option E introduces complexity and two refreshes may create a delay in data available.
NEW QUESTION # 226
You are tasked with calculating the daily moving average of sales for each product category in your Snowflake data warehouse using Snowpark Python. You need to handle cases where there might be missing sales data for certain days. You have the following sales data available in a table named with columns: (DATE), (VARCHAR), and 'sales_amount' (NUMBER). Which of the following Snowpark Python code snippets correctly calculates the 7-day moving average of sales amount per product category, filling in missing sales days with 0, and handles potential division by zero?
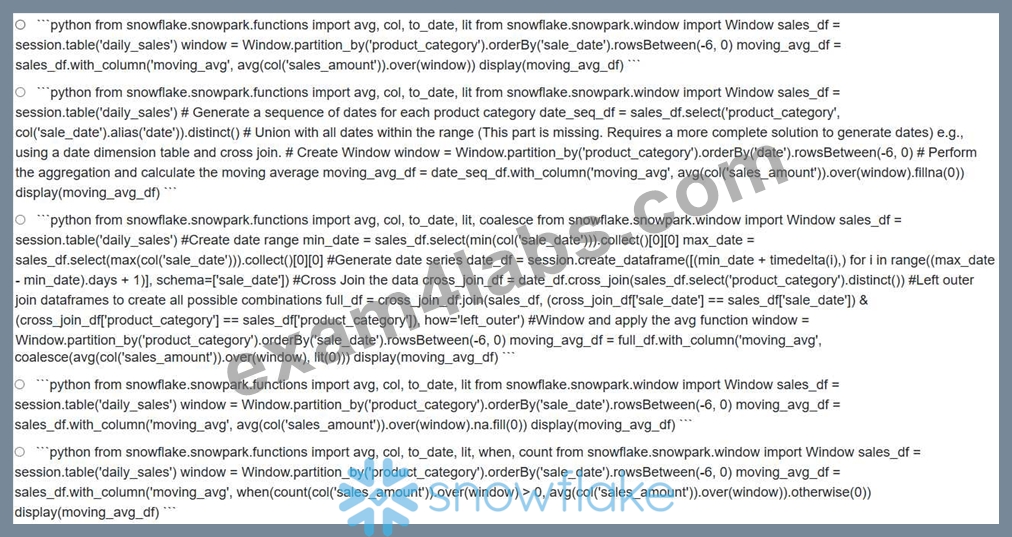
- A. Option C
- B. Option D
- C. Option E
- D. Option B
- E. Option A
Answer: A
Explanation:
Option C correctly addresses the problem by first generating a date series to account for missing dates. The solution then does cross join to generate the data, followed by the window aggregation and coalesce, which correctly uses the avg window operation filling zero for the null values.
NEW QUESTION # 227
A Snowflake table 'PRODUCT REVIEWS' is being ingested into from an external system. You have a stream 'PRODUCT REVIEWS STREAM' defined on this table to capture changes. Due to a bug in the ingestion process, incorrect data was loaded for a specific period. You need to correct the data'. Which of the following SQL statements, when executed against the 'PRODUCT REVIEWS STREAM' , will return the number of rows that were inserted, updated, and deleted during that period?
Answer: A
Explanation:
Option D is correct: The query 'SELECT METADATA$ACTION, count( ) FROM GROUP BY METADATA$ACTION$ will correctly return the number of rows for each action (INSERT, UPDATE, DELETE) within the stream. Options A, B, and C will give a total of only a single action type and E would give the total number of records in the stream regardless of action, failing to provide granular count per action.
NEW QUESTION # 228
......
Attending training institution or having Snowflake online training classes may be a good choice for candidates. But for people who have no time and energy to prepare for DEA-C02 practice exam, training calss will make them tired and exhausted. The most effective way for them to pass DEA-C02 Actual Test is choosing best study materials that you will find in Exam4Labs.
Valid DEA-C02 Exam Experience: https://www.exam4labs.com/DEA-C02-practice-torrent.html
- DEA-C02 Valid Exam Voucher 🧩 DEA-C02 Mock Exams 🗾 DEA-C02 Study Material 🍦 Open ▛ www.troytecdumps.com ▟ and search for ( DEA-C02 ) to download exam materials for free 🥇DEA-C02 Test Valid
- Trustable Exam DEA-C02 Lab Questions Provide Prefect Assistance in DEA-C02 Preparation 🪐 Download “ DEA-C02 ” for free by simply searching on ➽ www.pdfvce.com 🢪 🛐Valid Real DEA-C02 Exam
- 2026 DEA-C02 – 100% Free Exam Lab Questions | Updated Valid DEA-C02 Exam Experience 🔃 Enter ➤ www.examcollectionpass.com ⮘ and search for ▷ DEA-C02 ◁ to download for free 🛃DEA-C02 Vce Torrent
- Quiz DEA-C02 SnowPro Advanced: Data Engineer (DEA-C02) Realistic Exam Lab Questions 🐁 Search for “ DEA-C02 ” and obtain a free download on ▷ www.pdfvce.com ◁ 🌏Latest DEA-C02 Study Plan
- DEA-C02 Instant Download 😆 Valid Real DEA-C02 Exam 👇 DEA-C02 Best Preparation Materials 🥮 Enter ➤ www.prepawayete.com ⮘ and search for ⏩ DEA-C02 ⏪ to download for free 🔌DEA-C02 Simulation Questions
- 2026 DEA-C02 – 100% Free Exam Lab Questions | Updated Valid DEA-C02 Exam Experience 🔓 Immediately open ➡ www.pdfvce.com ️⬅️ and search for “ DEA-C02 ” to obtain a free download 🧲DEA-C02 Valid Exam Objectives
- Quiz DEA-C02 SnowPro Advanced: Data Engineer (DEA-C02) Realistic Exam Lab Questions 🤨 Immediately open 【 www.vce4dumps.com 】 and search for ( DEA-C02 ) to obtain a free download 🎢DEA-C02 Valid Dumps Questions
- Valid Braindumps DEA-C02 Book 🤦 Valid DEA-C02 Dumps 🥽 DEA-C02 Test Valid 🩱 Search for ▷ DEA-C02 ◁ and easily obtain a free download on ▶ www.pdfvce.com ◀ 🏉DEA-C02 Mock Exams
- Snowflake DEA-C02 Practice Test For Supreme Achievement 2026 📦 Search for 「 DEA-C02 」 and download exam materials for free through ➠ www.exam4labs.com 🠰 🧳DEA-C02 Study Material
- DEA-C02 Exam Overviews 🦼 Valid Braindumps DEA-C02 Book 🆒 DEA-C02 Exam Overviews 🦠 Go to website ⇛ www.pdfvce.com ⇚ open and search for { DEA-C02 } to download for free 😌DEA-C02 Instant Download
- DEA-C02 Vce Torrent ⭐ DEA-C02 Exam Overviews 👡 Valid Real DEA-C02 Exam 🏀 Search for ⇛ DEA-C02 ⇚ and download it for free on ☀ www.practicevce.com ️☀️ website 🤴DEA-C02 Exam Overviews
- giphy.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of Exam4Labs DEA-C02 dumps from Cloud Storage: https://drive.google.com/open?id=1ksD4o0Eq2BRvqd4sQWOKKETT-aLHxjRU




