We all known that most candidates will worry about the quality of our product, In order to guarantee quality of our study materials, all workers of our company are working together, just for a common goal, to produce a high-quality product; it is our Databricks-Certified-Professional-Data-Engineer exam questions. If you purchase our Databricks-Certified-Professional-Data-Engineer Guide Torrent, we can guarantee that we will provide you with quality products, reasonable price and professional after sales service. I think our Databricks-Certified-Professional-Data-Engineer test torrent will be a better choice for you than other study materials.
Passing the Databricks Certified Professional Data Engineer exam is a valuable achievement for data professionals who work with the Databricks platform. Databricks Certified Professional Data Engineer Exam certification demonstrates that candidates have the skills and knowledge needed to perform data engineering tasks effectively using Databricks. It also provides a competitive advantage in the job market, as employers are increasingly looking for candidates with data engineering certifications.
Databricks Certified Professional Data Engineer exam is a certification program offered by Databricks, a unified data analytics platform that provides a collaborative workspace for data science teams. Databricks Certified Professional Data Engineer Exam certification program is designed for data professionals who want to demonstrate their knowledge and skills in building reliable, scalable, and performant data pipelines using Databricks.
>> Latest Databricks-Certified-Professional-Data-Engineer Exam Pattern <<
It is a common sense that in terms of a kind of Databricks-Certified-Professional-Data-Engineer test torrent, the pass rate would be the best advertisement, since only the pass rate can be the most powerful evidence to show whether the Databricks-Certified-Professional-Data-Engineer guide torrent is effective and useful or not. We are so proud to tell you that according to the statistics from the feedback of all of our customers, the pass rate of our Databricks-Certified-Professional-Data-Engineer Exam Questions among our customers who prepared for the exam under the guidance of our Databricks-Certified-Professional-Data-Engineer test torrent has reached as high as 98%to 100%.
The DCPDE certification is an excellent way for data professionals to demonstrate their expertise in the Databricks platform. Databricks Certified Professional Data Engineer Exam certification is recognized globally and is highly valued by employers looking for data professionals with expertise in Databricks. The DCPDE certification provides professionals with the opportunity to enhance their career prospects and increase their earning potential.
NEW QUESTION # 191
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.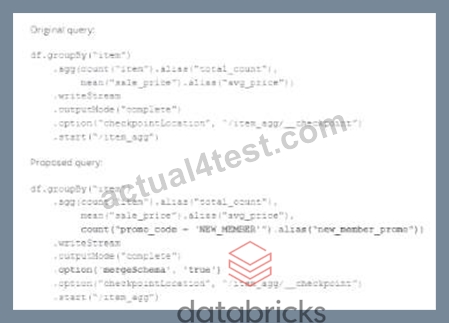
Which step must also be completed to put the proposed query into production?
Answer: B
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
References:
* Databricks documentation on Structured Streaming: https://docs.databricks.com/spark/latest/structured- streaming/index.html
* Databricks documentation on streaming checkpoints: https://docs.databricks.com/spark/latest/structured- streaming/production.html#checkpointing
NEW QUESTION # 192
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: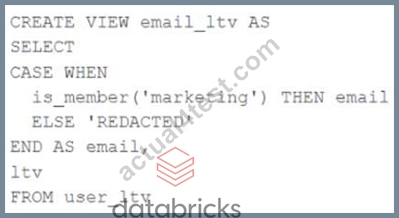
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Answer: D
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 193
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Answer: C
Explanation:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.
Databricks documentation on access control and permissions for notebooks within the workspace (https://docs.databricks.com/security/access-control/workspace-acl.html).
NEW QUESTION # 194
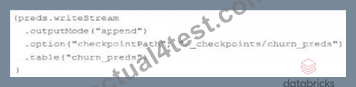
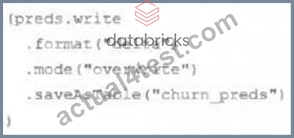
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".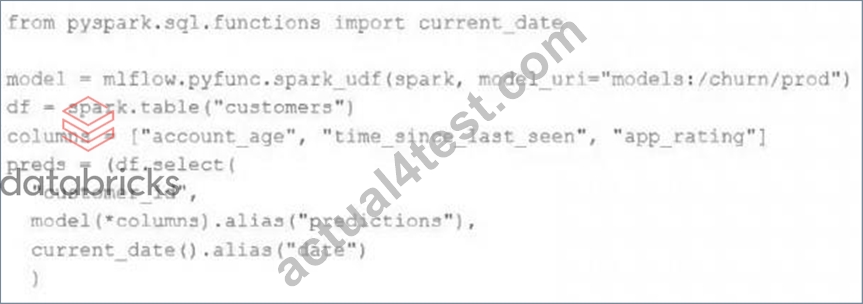
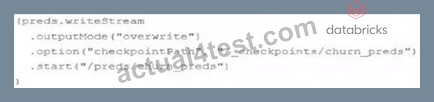
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Answer: A
Explanation:
Explanation
This is the correct answer because it will save the predictions to a Delta Lake table with the ability to compare all predictions across time. The code uses the mergeInto method to perform an upsert operation, which means it will insert new records or update existing records based on the customer_id and date columns. This way, the table will always contain the latest predictions for each customer and date, and also keep the history of previous predictions. The code also uses a new job cluster to run the job, which will minimize the compute costs as it will be created and terminated for each run. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 195
The following table consists of items found in user carts within an e-commerce website.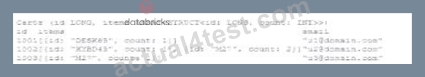
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.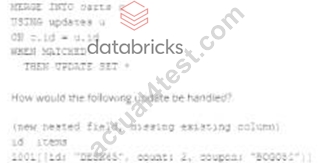
How would the following update be handled?
Answer: A
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
:
Databricks documentation on schema evolution in Delta Lake: https://docs.databricks.com/delta/delta-batch.
html#schema-evolution
NEW QUESTION # 196
......
Databricks-Certified-Professional-Data-Engineer Reliable Learning Materials: https://www.actual4test.com/Databricks-Certified-Professional-Data-Engineer_examcollection.html