BTW, DOWNLOAD part of DumpsKing Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1__bgfee8ndDDavh3yVERd5VmNvMjiB31
If you buy our Databricks-Certified-Professional-Data-Engineer study materials, then you can enjoy free updates for one year. After you start learning, I hope you can set a fixed time to check emails. If the content of the Databricks-Certified-Professional-Data-Engineer practice guide or system is updated, we will send updated information to your e-mail address. Of course, you can also consult our e-mail on the status of the product updates. I hope we can work together to make you better use our Databricks-Certified-Professional-Data-Engineer simulating exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Performance and health monitoring - Setting up alerts and notifications |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
| Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
>> Reliable Databricks-Certified-Professional-Data-Engineer Test Pattern <<
To be successful in a professional exam like the Databricks Databricks-Certified-Professional-Data-Engineer exam, you must know the criteria to pass it. You should know the type of Databricks Certified Professional Data Engineer Exam questions, the pattern of the Databricks Certified Professional Data Engineer Exam exam, and the time limit to complete the Databricks-Certified-Professional-Data-Engineer Exam. All these factors help you pass the Databricks Databricks-Certified-Professional-Data-Engineer exam. DumpsKing is your reliable partner in getting your Databricks-Certified-Professional-Data-Engineer certification. The Databricks Databricks-Certified-Professional-Data-Engineer exam dumps help you achieve your professional goals.
NEW QUESTION # 38
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.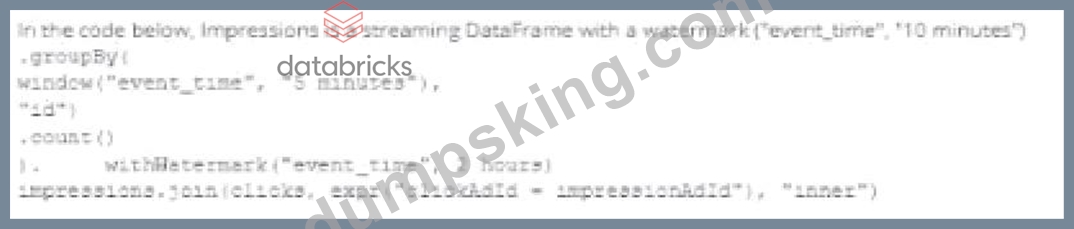
Which solution would improve the performance?




Answer: B
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 39
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
Answer: B
Explanation:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter1. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter. For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
The other options are not correct, because:
* Option A is incorrect because spark.conf.get("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The spark.conf API is used to get or set Spark configuration properties, not notebook parameters2.
* Option B is incorrect because input() is not a valid way to get a parameter passed through the Databricks Jobs API. The input() function is used to get user input from the standard input stream, not from the API request3.
* Option C is incorrect because sys.argv1 is not a valid way to get a parameter passed through the Databricks Jobs API. The sys.argv list is used to get the command-line arguments passed to a Python script, not to a notebook4.
* Option D is incorrect because dbutils.notebooks.getParam("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The dbutils.notebooks API is used to get or set notebook parameters when running a notebook as a job or as a subnotebook, not when passing parameters through the API5.
References: Widgets, Spark Configuration, input(), sys.argv, Notebooks
NEW QUESTION # 40
Which of the following two options are supported in identifying the arrival of new files, and incre-mental data from Cloud object storage using Auto Loader?
Answer: E
Explanation:
Explanation
The answer is A, Directory listing, File notifications
Directory listing: Auto Loader identifies new files by listing the input directory.
File notification: Auto Loader can automatically set up a notification service and queue service that subscribe to file events from the input directory.
Choosing between file notification and directory listing modes | Databricks on AWS
NEW QUESTION # 41
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: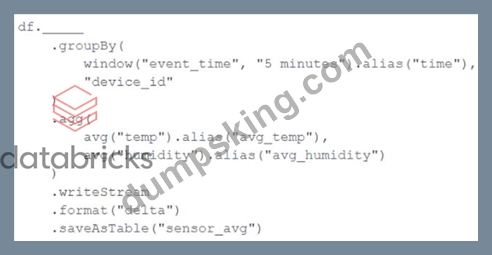
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: D
Explanation:
The correct answer is A. withWatermark("event_time", "10 minutes"). This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming. Reference:
Watermarking: https://docs.databricks.com/spark/latest/structured-streaming/watermarks.html Windowed aggregations: https://docs.databricks.com/spark/latest/structured-streaming/window-operations.html
NEW QUESTION # 42
Which statement characterizes the general programming model used by Spark Structured Streaming?
Answer: B
Explanation:
Explanation
This is the correct answer because it characterizes the general programming model used by Spark Structured Streaming, which is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model, where users can express their streaming computation using the same Dataset/DataFrame API as they would use for static data. The Spark SQL engine will take care of running the streaming query incrementally and continuously and updating the final result as streaming data continues to arrive. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Overview" section.
NEW QUESTION # 43
......
The Databricks-Certified-Professional-Data-Engineer quiz torrent we provide is compiled by experts with profound experiences according to the latest development in the theory and the practice so they are of great value. Please firstly try out our product before you decide to buy our product. It is worthy for you to buy our Databricks-Certified-Professional-Data-Engineer Exam Preparation not only because it can help you pass the Databricks-Certified-Professional-Data-Engineer exam successfully but also because it saves your time and energy. Your satisfactions are our aim of the service and please take it easy to buy our Databricks-Certified-Professional-Data-Engineer quiz torrent.
Latest Databricks-Certified-Professional-Data-Engineer Test Question: https://www.dumpsking.com/Databricks-Certified-Professional-Data-Engineer-testking-dumps.html
P.S. Free & New Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1__bgfee8ndDDavh3yVERd5VmNvMjiB31