P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by ITExamDownload: https://drive.google.com/open?id=1dpidPAmaVRpAfA034Q9wVzQfGCYfHXyN
The DP-750 mock exam setup can be configured to a particular style and arrive at unique questions. ITExamDownload DP-750 practice exam software went through real-world testing with feedback from more than 90,000 global professionals before reaching its latest form. Our Microsoft DP-750 Practice Test software is suitable for computer users with a Windows operating system. ITExamDownload Microsoft DP-750 practice exam support team cooperates with users to tie up any issues with the correct equipment.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
ITExamDownload is driven by the ambition of making you succeed. Our Microsoft DP-750 study material offers you high-quality training material and helps you have a good knowledge of the DP-750 actual test. The team members of ITExamDownload work with a passion to guarantee your success and make you prosperous. We provide the DP-750 Test Engine with self-assessment features for enhanced progress.
NEW QUESTION # 74
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
NEW QUESTION # 75
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Hotspot Question
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.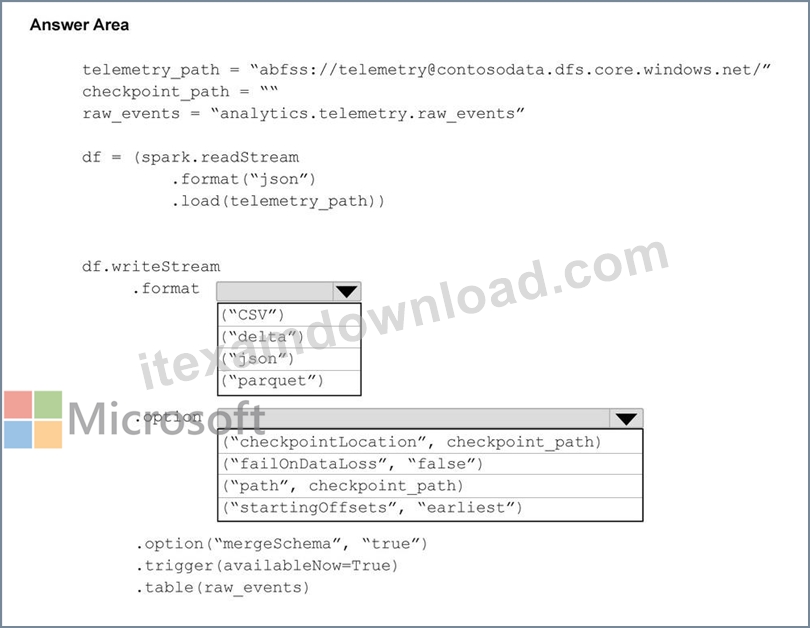
Answer:
Explanation:
NEW QUESTION # 76
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
Answer: A
Explanation:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
NEW QUESTION # 77
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1, metastore1 contains a catalog named catalog1.
You need to create a new schema named schema2 that meets the following requirements:
- Is contained in catalog1
- Uses abfss://container@storageaccount.dfs.core.windows.net/data as
the managed location
Which SQL statement should you execute?
Answer: A
Explanation:
To create a new schema with a specific managed location in Azure Databricks Unity Catalog, use the CREATE SCHEMA command.
CREATE SCHEMA catalog_name.schema_name
MANAGED LOCATION 'abfss://container@storageaccount.dfs.core.windows.net/data'; Catalog Name: Replace catalog_name with your existing catalog.
Schema Name: Replace schema_name with your desired new schema name.Quotes: The storage path must be enclosed in single quotes.
Privileges: You must have CREATE SCHEMA privileges on the parent catalog and ownership (or adequate permissions) on the external location.
Reference:
https://dev.to/encorepartners/creating-your-first-catalog-schema-and-tables-in-databricks-20p3
NEW QUESTION # 78
Which Azure service is best integrated with Databricks Unity Catalog for centralized data governance?
Answer: D
Explanation:
Microsoft Purview integrates with Unity Catalog to provide centralized data governance, classification, and lineage tracking. It helps organizations manage data compliance and discovery. Key Vault handles secrets, not governance. DevTest Labs is for testing environments.
Azure Automation is for workflow automation.
NEW QUESTION # 79
......
Our exam questions just need students to spend 20 to 30 hours practicing on the platform which provides simulation problems, can let them have the confidence to pass the DP-750 exam, so little time great convenience for some workers. It must be your best tool to pass your exam and achieve your target. We provide free download and tryout before your purchase and if you fail in the exam we will refund you in full immediately at one time. Purchasing our DP-750 Guide Torrent can help you pass the exam and it costs little time and energy.
PDF DP-750 VCE: https://www.itexamdownload.com/DP-750-valid-questions.html
What's more, part of that ITExamDownload DP-750 dumps now are free: https://drive.google.com/open?id=1dpidPAmaVRpAfA034Q9wVzQfGCYfHXyN