Latest Certified-Data-Engineer-Professional Test Dumps | Free Certified-Data-Engineer-Professional Test Questions

If you want to make progress and mark your name in your circumstances, you should never boggle at difficulties. As far as we know, many customers are depressed by the exam ahead of them, afraid of they may fail it unexpectedly. Our Certified-Data-Engineer-Professional exam torrents can pacify your worries and even help you successfully pass it. The shortage of necessary knowledge of the exam may make you waver, while the abundance of our Certified-Data-Engineer-Professional Study Materials can boost your confidence increasingly.
| Section | Objectives |
|---|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
>> Latest Certified-Data-Engineer-Professional Test Dumps <<
Develop Your Abilities and Obtain Databricks Certified-Data-Engineer-Professional Certification Without Difficulty
To take a good control of your life, this Certified-Data-Engineer-Professional exam is valuable with high recognition certificate. Actually getting a meaningful certificate by passing related Certified-Data-Engineer-Professional exam is also becoming more and more popular. So finding the perfect practice materials is pivotal for it. You may be constrained by a number of factors like lack of processional skills, time or money to deal with the practice exam ahead of you. While our Certified-Data-Engineer-Professional Study Materials can help you eliminate all those worries one by one.
Databricks Certified Data Engineer Professional Sample Questions (Q240-Q245):
NEW QUESTION # 240
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
- A. Iterating through a stored secret and printing each character will display secret contents in plain text.
- B. The Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials.
- C. Because the SHA256 hash is used to obfuscate stored secrets, reversing this hash will display the value in plain text.
- D. Account administrators can see all secrets in plain text by logging on to the Databricks Accounts console.
- E. Secrets are stored in an administrators-only table within the Hive Metastore; database administrators have permission to query this table by default.
Answer: B
Explanation:
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text. Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets.
NEW QUESTION # 241
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
- A. Use Repos to checkout the dev-2.3.9 branch and auto-resolve conflicts with the current branch
- B. Use Repos to make a pull request use the Databricks REST API to update the current branch to dev-2.3.9
- C. Use Repos to merge the current branch and the dev-2.3.9 branch, then make a pull request to sync with the remote repository
- D. Merge all changes back to the main branch in the remote Git repository and clone the repo again
- E. Use Repos to pull changes from the remote Git repository and select the dev-2.3.9 branch.
Answer: E
Explanation:
This is the correct answer because it will allow the developer to update their local repository with the latest changes from the remote repository and switch to the desired branch. Pulling changes will not affect the current branch or create any conflicts, as it will only fetch the changes and not merge them. Selecting the dev-2.3.9 branch from the dropdown will checkout that branch and display its contents in the notebook.
NEW QUESTION # 242
A data engineer is using Structured Streaming to read in transaction data from a bronze Delta table. It was discovered that the data has quality issues where sometimes the transaction value is negative, and when that occurs, the rows need to be routed to a separate quarantine table. They have low latency requirements for the good data since it is used by downstream systems, but the bad data will only be analyzed periodically and has no production dependencies. The quarantine job needs to be implemented so that it cannot affect the production processes that depend on the good data, and the cost of the job needs to be minimized. How should the quarantine process be implemented in order to satisfy these requirements?
- A. The streaming job for the good data needs to be modified to filter out records with a transaction value less than 0 before writing, and should not share compute with other processes. The streaming job for the quarantine data needs to filter out records with a transaction value greater than or equal to 0 before writing, and should be implemented on a separate small cluster and only run once a day to minimize cost.
- B. The existing streaming job for the good data should be updated to incorporate the quarantining of the bad data. Inside a foreachBatch function, the dataframe should be filtered so that records with a transaction value greater than or equal to 0 are written to the good data table and records with a transaction value less than 0 are written to a quarantine table. Try/Catch can be added around the writes in the foreachBatch function so that the stream can't fail.
- C. The existing streaming job for the good data should be updated to incorporate the quarantining of the bad data. A new boolean column called "quarantine" should be added to the dataframe, and its value should be set to true if the transaction value is less than 0 and false if the transaction value is greater than or equal to 0. Processing and storing all the data together will save costs.
- D. The streaming job for the good data needs to be modified to filter out records with a transaction value less than 0 before writing. The streaming job for the quarantine data needs to filter out records with a transaction value greater than or equal to 0 before writing. Both should run as separate streams on the same cluster to minimize cost.
Answer: A
Explanation:
Separating the quarantine processing from the low-latency production stream ensures the good- data pipeline cannot be slowed down or destabilized by quarantine writes or failures. Filtering out negative values in the production stream preserves latency and reliability for downstream systems. Running the quarantine stream on a small, independent cluster on a daily schedule minimizes cost while still capturing the bad records for periodic analysis, and it fully isolates quarantine operations from production dependencies.
NEW QUESTION # 243
A Delta Lake table was created with the below query:
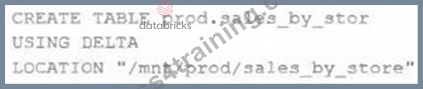
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. The table name change is recorded in the Delta transaction log.
- B. A new Delta transaction log Is created for the renamed table.
- C. All related files and metadata are dropped and recreated in a single ACID transaction.
- D. The table reference in the metastore is updated and all data files are moved.
- E. The table reference in the metastore is updated and no data is changed.
Answer: E
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 244
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
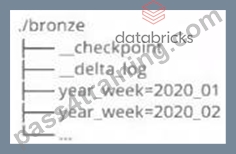
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. No; only one stream can write to a Delta Lake table.
- B. Yes; both of the streams can share a single checkpoint directory.
- C. No; Delta Lake manages streaming checkpoints in the transaction log.
- D. Yes; Delta Lake supports infinite concurrent writers.
- E. No; each of the streams needs to have its own checkpoint directory.
Answer: E
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 245
......
As the famous saying goes, time is life. Time is so important to everyone because we have to use our limited time to do many things. Especially for candidates to take the Certified-Data-Engineer-Professional exam, time is very precious. They must grasp every minute and every second to prepare for it. From the point of view of all the candidates, our Certified-Data-Engineer-Professional training quiz give full consideration to this problem. And we can claim that if you study our Certified-Data-Engineer-Professional study materials for 20 to 30 hours, you can pass the exam for sure.
Free Certified-Data-Engineer-Professional Test Questions: https://www.pass4training.com/Certified-Data-Engineer-Professional-pass-exam-training.html
- Unparalleled Databricks Latest Certified-Data-Engineer-Professional Test Dumps With Interarctive Test Engine - The Best Free Certified-Data-Engineer-Professional Test Questions 🌏 Search for ☀ Certified-Data-Engineer-Professional ️☀️ on { www.troytecdumps.com } immediately to obtain a free download 🤮Book Certified-Data-Engineer-Professional Free
- Pdf Certified-Data-Engineer-Professional Exam Dump 🧍 Latest Certified-Data-Engineer-Professional Test Camp 🐉 Cert Certified-Data-Engineer-Professional Exam 👹 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download it for free on 「 www.pdfvce.com 」 website 🐁Exam Certified-Data-Engineer-Professional Pass4sure
- Exam Certified-Data-Engineer-Professional Topic 🧉 Free Certified-Data-Engineer-Professional Brain Dumps 🦀 Certified-Data-Engineer-Professional Relevant Questions 🔋 Search for [ Certified-Data-Engineer-Professional ] and easily obtain a free download on ☀ www.practicevce.com ️☀️ 🐋Certified-Data-Engineer-Professional Real Dump
- Unparalleled Databricks Latest Certified-Data-Engineer-Professional Test Dumps With Interarctive Test Engine - The Best Free Certified-Data-Engineer-Professional Test Questions 📋 Download ▷ Certified-Data-Engineer-Professional ◁ for free by simply entering “ www.pdfvce.com ” website 🏞Exam Certified-Data-Engineer-Professional Pass4sure
- Book Certified-Data-Engineer-Professional Free 🔗 Certified-Data-Engineer-Professional Real Dump 🥾 Certified-Data-Engineer-Professional Interactive Course 🎦 The page for free download of ▶ Certified-Data-Engineer-Professional ◀ on ▛ www.pdfdumps.com ▟ will open immediately 🧲New Certified-Data-Engineer-Professional Dumps Book
- Cert Certified-Data-Engineer-Professional Exam 🧇 Free Certified-Data-Engineer-Professional Brain Dumps 💃 Certified-Data-Engineer-Professional Certification Materials 🧂 Enter ➠ www.pdfvce.com 🠰 and search for ➠ Certified-Data-Engineer-Professional 🠰 to download for free 👗Certified-Data-Engineer-Professional Valid Test Preparation
- Certified-Data-Engineer-Professional Certification Practice 🏖 Free Certified-Data-Engineer-Professional Brain Dumps 🍀 Certified-Data-Engineer-Professional Real Dump 🔉 Go to website ▛ www.examdiscuss.com ▟ open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 📍Certified-Data-Engineer-Professional Exam Assessment
- Certified-Data-Engineer-Professional Certification Practice 🥱 Book Certified-Data-Engineer-Professional Free 🦌 VCE Certified-Data-Engineer-Professional Dumps 🧡 Open ➥ www.pdfvce.com 🡄 enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 🔱Certified-Data-Engineer-Professional Exam Assessment
- 100% Pass Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –High-quality Latest Test Dumps 🌋 Open ▶ www.practicevce.com ◀ enter ☀ Certified-Data-Engineer-Professional ️☀️ and obtain a free download 💷Certified-Data-Engineer-Professional Authorized Certification
- Certified-Data-Engineer-Professional Certification Practice 🆘 Certified-Data-Engineer-Professional Interactive Course 🌄 Certified-Data-Engineer-Professional Exam Assessment 🌊 Simply search for 「 Certified-Data-Engineer-Professional 」 for free download on 「 www.pdfvce.com 」 🌊Exam Certified-Data-Engineer-Professional Study Solutions
- Free Certified-Data-Engineer-Professional Brain Dumps 🌴 Certified-Data-Engineer-Professional Valid Test Camp 📱 Certified-Data-Engineer-Professional Certification Practice 🍀 Enter ⇛ www.dumpsmaterials.com ⇚ and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 💘Certified-Data-Engineer-Professional Valid Test Preparation
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes