BONUS!!! Download part of DumpsTorrent MLA-C01 dumps for free: https://drive.google.com/open?id=1sq_27-2C8nlo2J769QAi6fKyv62vsBsb
For candidates who want to enter a better company through getting the certificate, passing the exam becomes important. MLA-C01 study guide of us will help you pass the exam successfully. With the skilled experts to compile and verify, the MLA-C01 exam dumps are high-quality and accuracy, therefore you can use MLA-C01 Exam Questions And Answers at ease. What’s more, we offer you free update for one year after purchasing. That is to say, you can get the latest version in the following year for free.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Latest MLA-C01 Test Testking <<
After you purchase our MLA-C01 study materials, we will provide one-year free update for you. Within one year, we will send the latest version to your mailbox with no charge if we have a new version of MLA-C01 learning materials. We will also provide some discount for your updating after a year if you are satisfied with our MLA-C01 Exam Questions. And if you find that your version of the MLA-C01 practice guide is over one year, you can enjoy 50% discount if you buy it again.
NEW QUESTION # 226
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model's performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model's final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.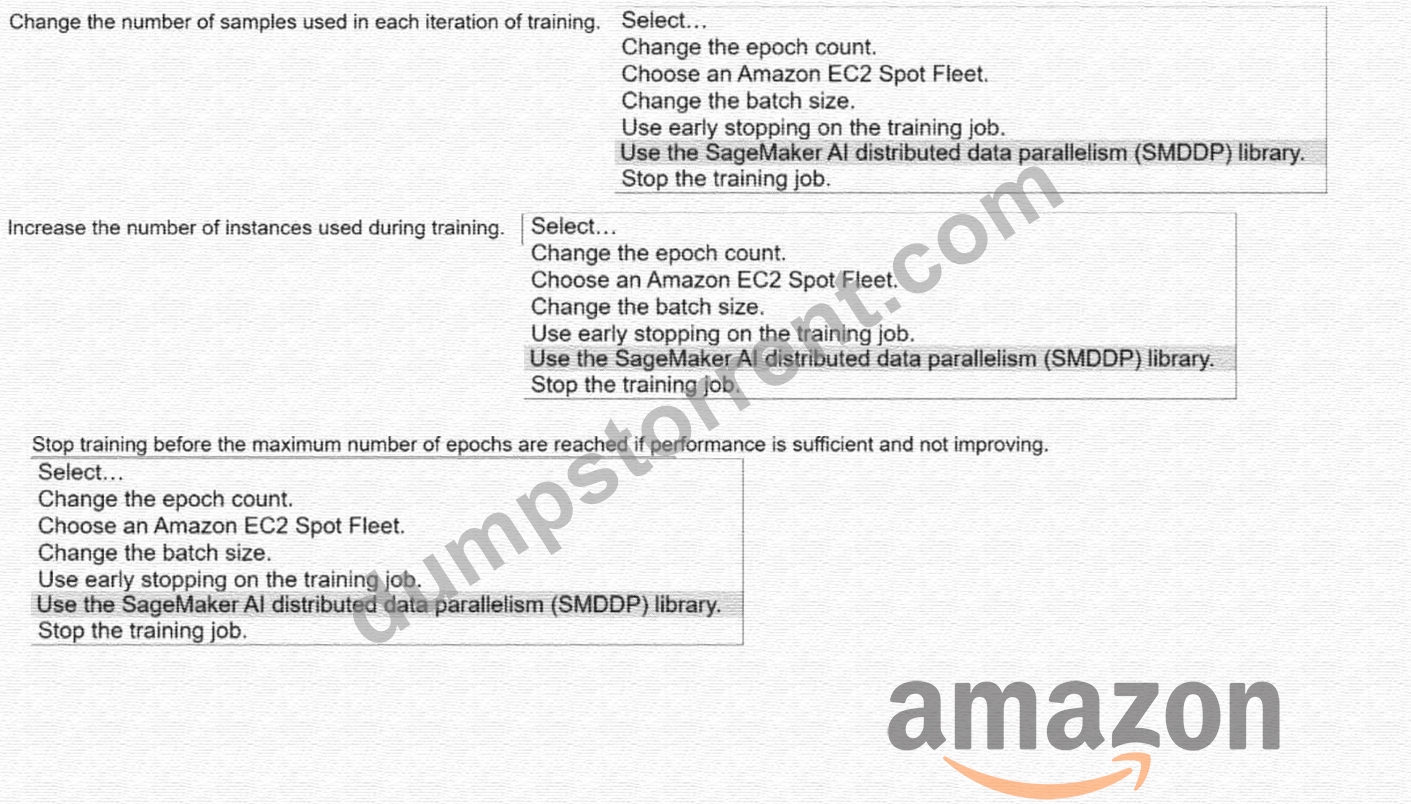
Answer:
Explanation: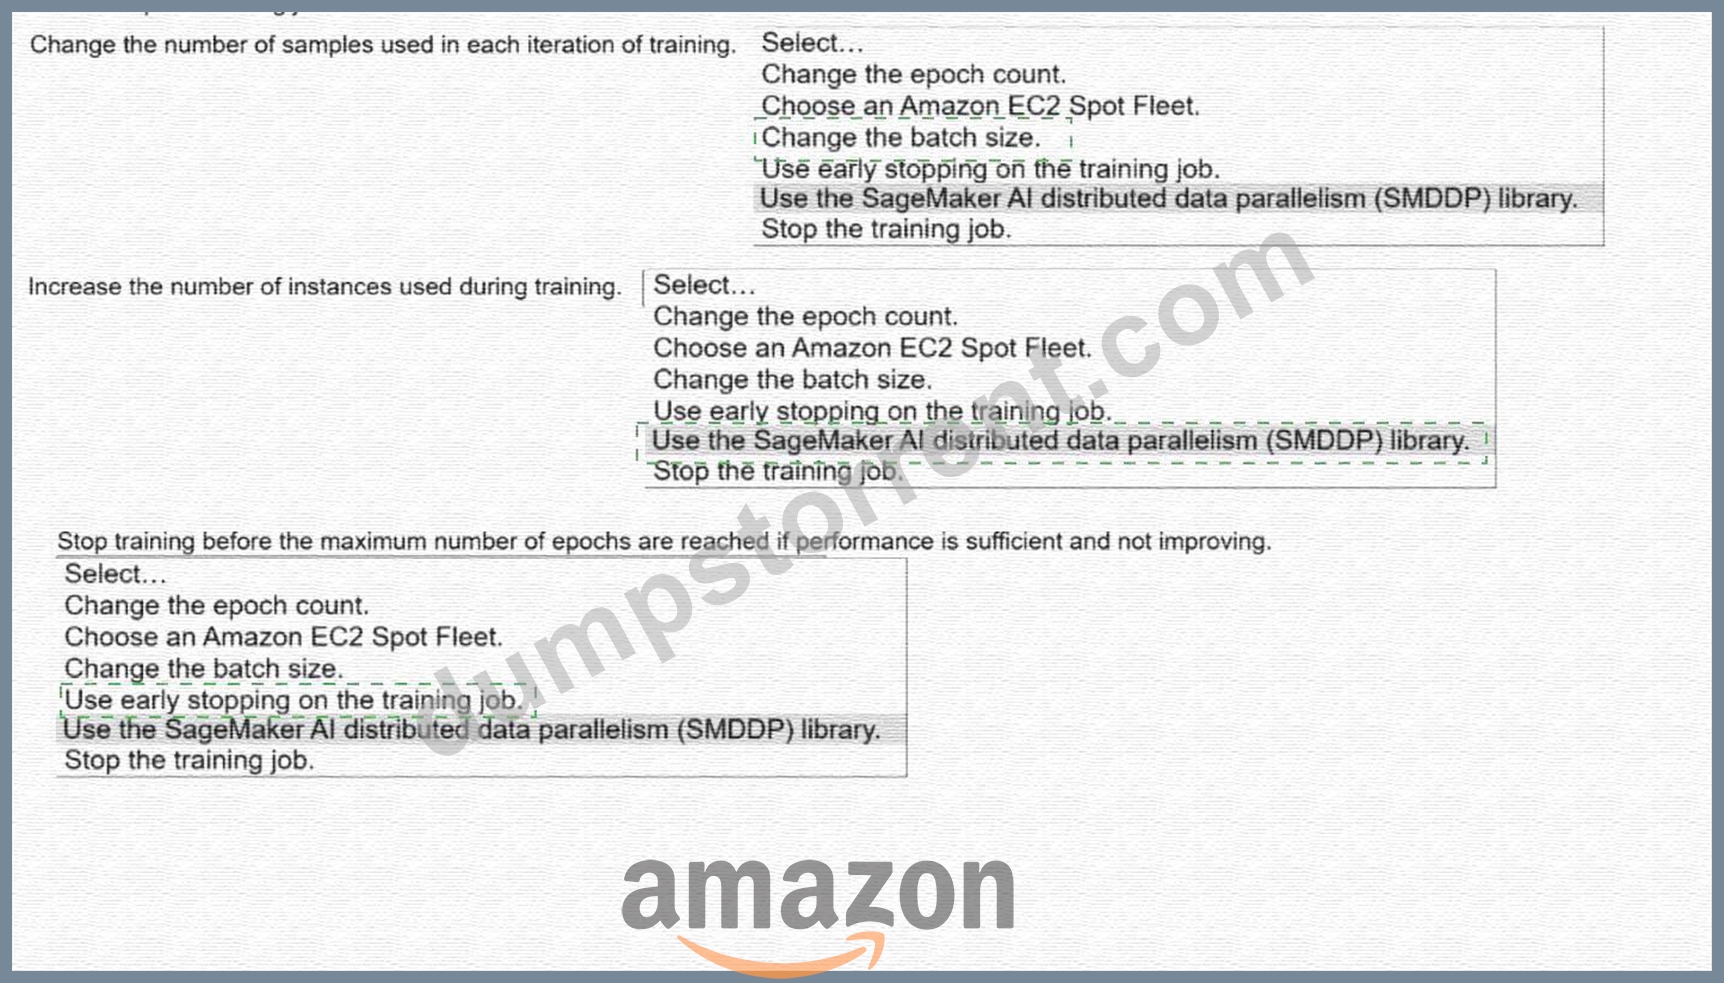
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
NEW QUESTION # 227
A hospital wants to predict patient outcomes for the coming year An ML engineer must improve several existing ML models that currently perform poorly.
Select the correct regularization method from the following list to improve each model Select each regularization method one time, more than one time, or not at all. (Select THREE.)
* L1 regularization
* L2 regularization
* Early stopping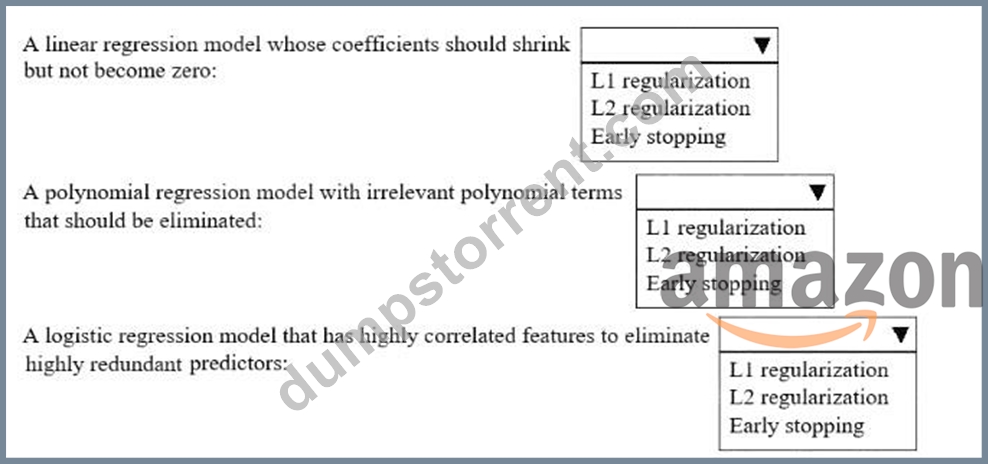
Answer:
Explanation: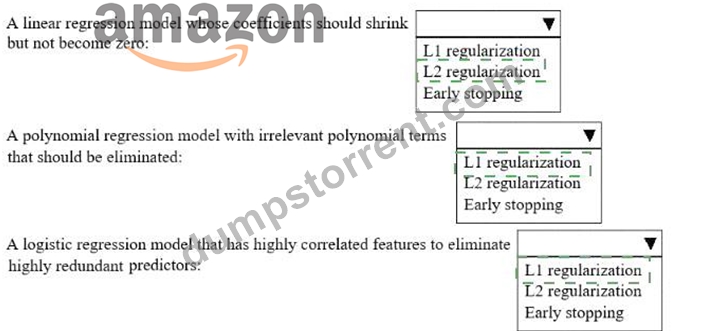
Explanation:
Linear regression model whose coefficients should shrink but not become zero The answer: L2 regularization AWS says L2 produces smaller overall weight values and is the right fit when coefficients should be reduced without being forced to zero.
Polynomial regression model with irrelevant polynomial terms that should be eliminated The answer: L1 regularization AWS says L1 reduces the number of features used by pushing small weights to zero, which matches elimination of irrelevant terms.
Logistic regression model that has highly correlated features to eliminate highly redundant predictors The answer: L1 regularization This is the nuanced one. AWS says L2 stabilizes weights when there is high correlation between features, but because the question explicitly says eliminate highly redundant predictors, L1 is the better match since it creates sparsity and removes predictors by zeroing coefficients.
NEW QUESTION # 228
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.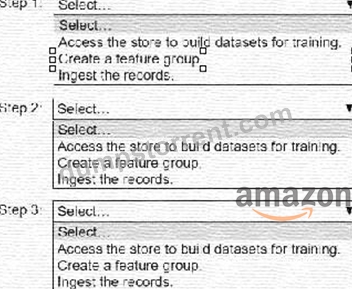
Answer:
Explanation: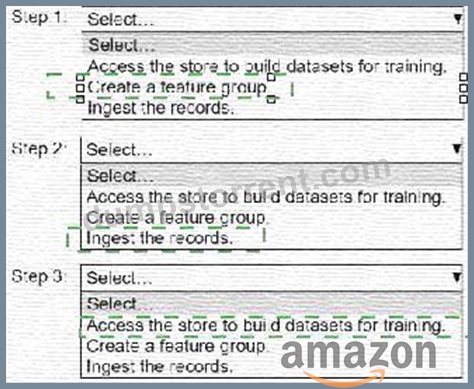
Explanation: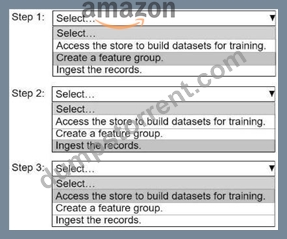
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 229
An ML engineer needs to run intensive model training jobs each month that can take 48-72 hours. The jobs can be interrupted and resumed. The engineer has a fixed budget and needs the most cost-effective compute option.
Which solution will meet these requirements?
Answer: D
Explanation:
Amazon EC2 Spot Instances provide unused compute capacity at discounts of up to 90%. AWS documentation strongly recommends Spot Instances for interruptible workloads such as long-running ML training jobs that can resume from checkpoints.
By enabling automatic checkpointing, SageMaker saves model state periodically to Amazon S3. If the Spot Instance is interrupted, training can resume with minimal loss of progress.
Reserved Instances and Savings Plans require long-term commitment and are not as cost-effective for sporadic workloads. On-Demand Instances are the most expensive option.
Therefore, Option D is the most cost-effective solution.
NEW QUESTION # 230
An ML engineer is using an Amazon SageMaker AI shadow test to evaluate a new model that is hosted on a SageMaker AI endpoint. The shadow test requires significant GPU resources for high performance. The production variant currently runs on a less powerful instance type.
The ML engineer needs to configure the shadow test to use a higher performance instance type for a shadow variant. The solution must not affect the instance type of the production variant.
Which solution will meet these requirements?
Answer: D
Explanation:
Amazon SageMaker AI shadow testing enables ML engineers to evaluate new model versions by sending a copy of live production traffic to a shadow variant without affecting production inference responses. AWS documentation specifies that shadow variants are configured separately from production variants and can use different instance types, including higher-performance GPU instances.
The correct approach is to create a new endpoint configuration using the CreateEndpointConfig API. This configuration includes the existing production variant and a separate ShadowProductionVariants list. The shadow variant can be assigned a larger instance type to meet GPU performance requirements while leaving the production variant unchanged. After creating the configuration, the engineer deploys it using the CreateEndpoint action.
Option A is incorrect because production variant configurations cannot be directly modified to include shadow variants. Option B is incorrect because shadow variants are not defined as standard production variants; defining two production variants would route traffic differently and could affect production behavior. Option C introduces unnecessary complexity and deviates from SageMaker's built-in shadow testing functionality.
AWS explicitly documents that shadow variants are designed to isolate testing resources, support different instance types, and ensure zero impact on production inference. Therefore, Option D is the correct and AWS- recommended solution.
NEW QUESTION # 231
......
Many platforms are offering "DumpsTorrent" study material for the Amazon MLA-C01 certification exam. But most of them are not valid and people who study with them fail in the AWS Certified Machine Learning Engineer - Associate (MLA-C01) Exam and lose their resources. "DumpsTorrent" offers actual Amazon MLA-C01 Exam Questions that will help you pass the exam on the first try and save your money. These MLA-C01 questions are compiled under the guidance of thousands of professionals from around the world.
MLA-C01 Reliable Exam Labs: https://www.dumpstorrent.com/MLA-C01-exam-dumps-torrent.html
BTW, DOWNLOAD part of DumpsTorrent MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1sq_27-2C8nlo2J769QAi6fKyv62vsBsb