DY0-001資料 -保證高通過率

P.S. NewDumps在Google Drive上分享了免費的、最新的DY0-001考試題庫:https://drive.google.com/open?id=1CgA_vcpkAHMZ01IzFX0VTBlZTIgLcNJi
如果你有夢想就去捍衛它。高爾基曾說過,信仰是一個偉大的情感,是一種創造的力量。我的夢想是成為一個最頂級的的IT專家,如果想就這樣努力達到我夢想的彼岸,我想那對我來說是遙遙無期的努力,成功可以走捷徑,只要你選擇得當,我利用了NewDumps CompTIA的DY0-001考試培訓資料訓資料,才順利通過 CompTIA的DY0-001考試認證,NewDumps CompTIA的DY0-001考試培訓資料是性價非常高的培訓資料,如果你和我一樣,也有一個IT夢,那就來找NewDumps CompTIA的DY0-001考試培訓資料,它會幫助你實現你的夢想。
CompTIA DY0-001 考試大綱:
| 主題 | 簡介 |
|---|
| 主題 1 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| 主題 2 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| 主題 3 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| 主題 4 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| 主題 5 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
>> DY0-001資料 <<
最新版的DY0-001資料,全面覆蓋DY0-001考試知識點
人生舞臺的大幕隨時都可能拉開,關鍵是你願意表演,還是選擇躲避,能把在面前行走的機會抓住的人,十有八九都是成功的。所以你必須抓住NewDumps這個機會,讓你隨時可以展現你的技能,NewDumps CompTIA的DY0-001考試培訓資料就是你通過認證的最有效的方法,有了這個認證,你將在你人生的藍圖上隨意揮灑,實現你的夢想,走向成功。要做就做一個勇往直前的人,那樣的人生才有意義。
最新的 CompTIA Data+ DY0-001 免費考試真題 (Q41-Q46):
問題 #41
A data scientist is analyzing a data set with categorical features and would like to make those features more useful when building a model. Which of the following data transformation techniques should the data scientist use? (Choose two.)
- A. Pivoting
- B. Linearization
- C. Scaling
- D. Normalization
- E. One-hot encoding
- F. Label encoding
答案:E,F
解題說明:
# Categorical variables must be transformed into numerical form for most machine learning models. Two standard approaches:
* One-hot encoding: Converts each category into a separate binary column (useful for nominal variables).
* Label encoding: Converts categories into integers (useful for ordinal or tree-based models).
Why other options are incorrect:
* A & E: Normalization and scaling are used for continuous variables, not categorical.
* C: Linearization refers to transforming relationships, not categorical conversion.
* F: Pivoting rearranges data structure but doesn't encode categories.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"Label encoding and one-hot encoding are common transformations applied to categorical variables to enable model compatibility."
-
問題 #42
Which of the following belong in a presentation to the senior management team and/or C-suite executives?
(Choose two.)
- A. High-level results
- B. Full literature reviews
- C. Code snippets
- D. Detailed explanations of statistical tests
- E. Final recommendations
- F. Security keys and login information
答案:A,E
解題說明:
# Senior executives and the C-suite are primarily interested in decision-support insights rather than technical or academic depth. Thus, appropriate content includes:
* C. Final recommendations: Executives need clear actions or decisions.
* D. High-level results: Summarized performance, trends, or KPIs without technical jargon.
Why the other options are incorrect:
* A: Literature reviews are too detailed and academic.
* B: Code is technical and not relevant to business strategy.
* E: Statistical tests may overwhelm a non-technical audience.
* F: Sharing security keys violates cybersecurity protocols.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.5 (Communication & Visualization):
"Executive presentations should include concise, actionable insights and high-level summaries to support strategic decision-making."
* Harvard Business Review - Data Storytelling:"Executives value clear insights, visual summaries, and recommendations. Avoid technical deep dives unless specifically requested."
-
問題 #43
A data scientist is using the following confusion matrix to assess model performance:
Actually Fails
Actually Succeeds
Predicted to Fail
80%
20%
Predicted to Succeed
15%
85%

The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops.
Every time the model is correct, the company saves 1 hour in planning and scheduling.
Every time the model is wrong, the company loses 4 hours of delivery time.
Which of the following is the net model impact for the company?
- A. 165 hours saved
- B. 25 hours saved
- C. 25 hours lost
- D. 165 hours lost
答案:A
解題說明:
First, we assume 100 trucks (or 100 predictions), as the percentages are easiest to scale on a base of 100.
Using the confusion matrix:
* True Positives (Predicted Fail & Actually Fails): 80 trucks - correct # +1 hr each = +80 hrs
* False Positives (Predicted Fail & Actually Succeeds): 20 trucks - incorrect # -4 hrs each = -80 hrs
* False Negatives (Predicted Succeed & Actually Fails): 15 trucks - incorrect # -4 hrs each = -60 hrs
* True Negatives (Predicted Succeed & Actually Succeeds): 85 trucks - correct # +1 hr each = +85 hrs Now calculate net hours:
Total gain: 80 hrs (TP) + 85 hrs (TN) = +165 hrs
Total loss: 80 hrs (FP) + 60 hrs (FN) = -140 hrs
Net Impact: 165 - 140 = +25 hours saved
So the correct answer is:
B : (25 hours saved)
However, based on the table provided (which appears to be normalized as percentages), the values apply to a total of 100 predictions. Let's recalculate carefully and validate.
Breakdown:
* TP = 80% # 80 × +1 hr = +80 hrs
* FP = 20% # 20 × -4 hrs = -80 hrs
* FN = 15% # 15 × -4 hrs = -60 hrs
* TN = 85% # 85 × +1 hr = +85 hrs
Total hours = +80 + 85 - 80 - 60 = +25 hrs
Final answer: B. 25 hours saved
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.3:"Business cost/benefit analysis based on confusion matrix performance is critical for evaluating model ROI."
問題 #44
A data scientist is designing a real-time machine-learning model that classifies a user based on initial behavior. The run times of these models are provided in the following table:
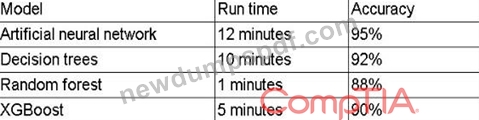
Which of the following models should the data scientist recommend for deployment?
- A. XGBoost
- B. Artificial neural network
- C. Random forest
- D. Decision trees
答案:C
解題說明:
For a real-time application, inference latency is critical. Although its accuracy (88%) is slightly lower than the others, the random forest's 1-minute run time is by far the fastest, making it the only model capable of meeting real-time responsiveness.
問題 #45
Which of the following is the naive assumption in Bayes' rule?
- A. Independence
- B. Homoskedasticity
- C. Normal distribution
- D. Uniform distribution
答案:A
解題說明:
Naive Bayes assumes that all predictor variables are conditionally independent of each other given the class label, dramatically simplifying the joint probability calculation in Bayes' rule.
問題 #46
......
你可以先在網上免費下載NewDumps提供的關於CompTIA DY0-001 認證考試的部分考試練習題和答案,作為嘗試來檢驗我們的品質。只要你選擇購買NewDumps的產品,NewDumps就會盡全力幫助你一次性通過CompTIA DY0-001 認證考試。
DY0-001證照指南: https://www.newdumpspdf.com/DY0-001-exam-new-dumps.html
- DY0-001考試題庫 👑 DY0-001在線題庫 🎩 DY0-001考試內容 🥉 複製網址➤ www.pdfexamdumps.com ⮘打開並搜索⇛ DY0-001 ⇚免費下載DY0-001題庫最新資訊
- 最新的DY0-001資料和最新的CompTIA認證培訓 - 高通過率的CompTIA CompTIA DataAI Certification Exam 🤙 到➠ www.newdumpspdf.com 🠰搜索⏩ DY0-001 ⏪輕鬆取得免費下載DY0-001權威考題
- DY0-001在線題庫 💑 DY0-001題庫最新資訊 🌠 DY0-001題庫最新資訊 🪂 免費下載⮆ DY0-001 ⮄只需進入▷ www.vcesoft.com ◁網站DY0-001題庫資訊
- DY0-001證照指南 📽 DY0-001最新考古題 📋 DY0-001考試題庫 📥 ➡ www.newdumpspdf.com ️⬅️上搜索▷ DY0-001 ◁輕鬆獲取免費下載DY0-001題庫最新資訊
- 快速下載DY0-001資料和資格考試中的領導者和優秀的DY0-001:CompTIA DataAI Certification Exam 👲 在「 tw.fast2test.com 」上搜索➤ DY0-001 ⮘並獲取免費下載DY0-001考試大綱
- DY0-001考試大綱 🙋 DY0-001最新考古題 ⏯ DY0-001考題套裝 🛒 到➠ www.newdumpspdf.com 🠰搜尋✔ DY0-001 ️✔️以獲取免費下載考試資料DY0-001考試大綱
- 高質量的CompTIA DY0-001資料是行業領先材料&免費PDF DY0-001證照指南 🍉 打開網站[ www.kaoguti.com ]搜索( DY0-001 )免費下載DY0-001更新
- 選擇DY0-001資料讓您簡單快速解決CompTIA DataAI Certification Exam考試 👺 ➤ www.newdumpspdf.com ⮘上的➥ DY0-001 🡄免費下載只需搜尋DY0-001資料
- DY0-001软件版 🧆 DY0-001在線題庫 ☁ DY0-001考題套裝 🎅 開啟✔ tw.fast2test.com ️✔️輸入【 DY0-001 】並獲取免費下載DY0-001考試題庫
- 完美的DY0-001資料和資格考試和神奇DY0-001中的領先提供者:CompTIA DataAI Certification Exam 🤚 打開☀ www.newdumpspdf.com ️☀️搜尋{ DY0-001 }以免費下載考試資料DY0-001資料
- 覆蓋全面的DY0-001資料 |第一次嘗試輕鬆學習並通過考試和最佳的DY0-001證照指南 🦯 立即到➤ www.newdumpspdf.com ⮘上搜索➥ DY0-001 🡄以獲取免費下載DY0-001最新考古題
- tooter.in, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, zenwriting.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.ted.com, giphy.com, Disposable vapes
BONUS!!! 免費下載NewDumps DY0-001考試題庫的完整版:https://drive.google.com/open?id=1CgA_vcpkAHMZ01IzFX0VTBlZTIgLcNJi