Databricks-Certified-Data-Engineer-Professionalソフトウエア、Databricks-Certified-Data-Engineer-Professional資格認証攻略

P.S.TopexamがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=12lsknpWAC08AQYFHLzfRrDbH9DGkFujp
Databricks-Certified-Data-Engineer-Professional準備試験では、国内および海外の専門家と学者を取り入れた専門家のチームを集めて、関連する試験銀行の調査と設計を行い、受験者がDatabricks-Certified-Data-Engineer-Professional試験に合格するのを支援します。ほとんどの専門家は長年プロの分野で勉強しており、Databricks-Certified-Data-Engineer-Professional練習問題で多くの経験を蓄積しています。当社は才能の選択にかなり慎重であり、夢のDatabricks-Certified-Data-Engineer-Professional認定の取得を支援するために、専門知識とスキルを備えた従業員を常に雇用しています。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion and Processing | - Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
|
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
- Data governance concepts (Unity Catalog basics)
|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Data Modeling and Transformation | - Dimensional modeling concepts
- Performance optimization techniques
- Spark SQL transformations
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Delta Lake transactions and ACID properties
- Time travel and versioning
|
>> Databricks-Certified-Data-Engineer-Professionalソフトウエア <<
Databricks Databricks-Certified-Data-Engineer-Professional資格認証攻略、Databricks-Certified-Data-Engineer-Professional難易度
私はあなたがDatabricks-Certified-Data-Engineer-Professional試験に合格したいことを知っています。 私たちのDatabricks-Certified-Data-Engineer-Professional学習教材は、多くの人が試験に合格するのを助け、あなたを助けようと思います。私たちのDatabricks-Certified-Data-Engineer-Professional学習教材の99%の合格率は高いです。また、あなたの自分の努力が必要です。 そして、私たちのDatabricks-Certified-Data-Engineer-Professional試験問題を利用すれば、あなたは絶対試験に合格できます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q57-Q62):
質問 # 57
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from user. They then modify their code to the following (leaving all other variables unchanged).
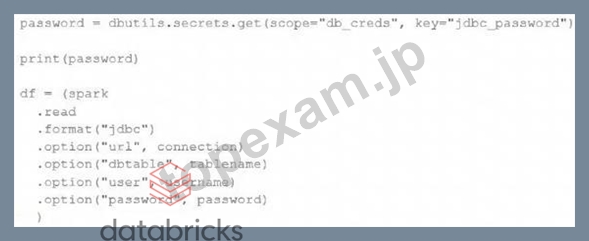
Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- C. The connection to the external table will fail; the string "redacted" will be printed.
- D. The connection to the external table will succeed; the string value of password will be printed in plain text.
- E. The connection to the external table will succeed; the string "redacted" will be printed.
正解:E
解説:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
質問 # 58
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. Delta Lake statistics are only collected on the first 4 columns in a table.
- B. Delta Lake statistics are not optimized for free text fields with high cardinality.
- C. ZORDER ON review will need to be run to see performance gains.
- D. Text data cannot be stored with Delta Lake.
- E. The Delta log creates a term matrix for free text fields to support selective filtering.
正解:B
解説:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
質問 # 59
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:

Proposed query:

Which step must also be completed to put the proposed query into production?
- A. Specify a new checkpointlocation
- B. Remove .option (mergeSchema', true') from the streaming write
- C. Register the data in the "/item_agg" directory to the Hive metastore
- D. Increase the shuffle partitions to account for additional aggregates
- E. Run REFRESH TABLE delta, /item_agg'
正解:A
解説:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
質問 # 60
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When tables are created, make sure that the external keyword is used in the create table statement.
- B. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- C. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- D. Whenever a table is being created, make sure that the location keyword is used.
- E. Whenever a database is being created, make sure that the location keyword is used Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
正解:D
解説:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
質問 # 61
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.

Which solution would improve the performance?
正解:D
解説:
When joining a stream of advertisement impressions with a stream of user clicks, you want to Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
質問 # 62
......
まだDatabricks-Certified-Data-Engineer-Professional試験に昼夜を問わず滞在していますか? 答えが「はい」の場合は、TopexamのDatabricks-Certified-Data-Engineer-Professional試験資料を試してください。 私たちDatabricksは、最も正確で有用な情報を含むコンテンツだけでなく、最も迅速で最も効率的なアシスタントを提供するアフターサービスについても専門的です。 当社のDatabricks-Certified-Data-Engineer-Professional練習トレントを20〜30時間使用すると、Databricks-Certified-Data-Engineer-Professional試験に参加する準備が整い、期待されるDatabricks Certified Data Engineer Professional Examスコアを達成できると主張できます。
Databricks-Certified-Data-Engineer-Professional資格認証攻略: https://www.topexam.jp/Databricks-Certified-Data-Engineer-Professional_shiken.html
- Databricks-Certified-Data-Engineer-Professional学習範囲 🚐 Databricks-Certified-Data-Engineer-Professional学習資料 🧩 Databricks-Certified-Data-Engineer-Professional受験料 ⏹ Open Webサイト「 www.passtest.jp 」検索☀ Databricks-Certified-Data-Engineer-Professional ️☀️無料ダウンロードDatabricks-Certified-Data-Engineer-Professional日本語受験教科書
- 実用的-一番優秀なDatabricks-Certified-Data-Engineer-Professionalソフトウエア試験-試験の準備方法Databricks-Certified-Data-Engineer-Professional資格認証攻略 🎽 【 www.goshiken.com 】を開き、⏩ Databricks-Certified-Data-Engineer-Professional ⏪を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional最新な問題集
- Databricks-Certified-Data-Engineer-Professional関連日本語内容 🔒 Databricks-Certified-Data-Engineer-Professional模擬問題 😦 Databricks-Certified-Data-Engineer-Professional認証試験 👓 時間限定無料で使える▷ Databricks-Certified-Data-Engineer-Professional ◁の試験問題は“ www.mogiexam.com ”サイトで検索Databricks-Certified-Data-Engineer-Professional合格記
- 検証するDatabricks-Certified-Data-Engineer-Professional|更新するDatabricks-Certified-Data-Engineer-Professionalソフトウエア試験|試験の準備方法Databricks Certified Data Engineer Professional Exam資格認証攻略 ✨ “ www.goshiken.com ”は、➤ Databricks-Certified-Data-Engineer-Professional ⮘を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional受験料
- Databricks-Certified-Data-Engineer-Professional日本語受験教科書 ❗ Databricks-Certified-Data-Engineer-Professional日本語受験教科書 🍔 Databricks-Certified-Data-Engineer-Professional関連日本語内容 🎦 最新✔ Databricks-Certified-Data-Engineer-Professional ️✔️問題集ファイルは▶ jp.fast2test.com ◀にて検索Databricks-Certified-Data-Engineer-Professional合格記
- 試験の準備方法-有効的なDatabricks-Certified-Data-Engineer-Professionalソフトウエア試験-最高のDatabricks-Certified-Data-Engineer-Professional資格認証攻略 🐥 検索するだけで⇛ www.goshiken.com ⇚から《 Databricks-Certified-Data-Engineer-Professional 》を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional学習範囲
- Databricks-Certified-Data-Engineer-Professional合格記 ⛲ Databricks-Certified-Data-Engineer-Professional模擬問題 ℹ Databricks-Certified-Data-Engineer-Professional認証試験 🏉 「 www.passtest.jp 」で☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Engineer-Professional認定試験トレーリング
- Databricks-Certified-Data-Engineer-Professional科目対策 🚅 Databricks-Certified-Data-Engineer-Professional最新な問題集 🤳 Databricks-Certified-Data-Engineer-Professional模擬問題 📩 【 www.goshiken.com 】から《 Databricks-Certified-Data-Engineer-Professional 》を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語受験教科書
- 素敵なDatabricks-Certified-Data-Engineer-Professionalソフトウエア試験-試験の準備方法-100%合格率のDatabricks-Certified-Data-Engineer-Professional資格認証攻略 🦒 ▛ www.passtest.jp ▟で☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Engineer-Professional科目対策
- Databricks-Certified-Data-Engineer-Professional学習資料 🏞 Databricks-Certified-Data-Engineer-Professional合格記 😾 Databricks-Certified-Data-Engineer-Professional科目対策 🌋 サイト“ www.goshiken.com ”で⮆ Databricks-Certified-Data-Engineer-Professional ⮄問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional認定試験トレーリング
- 更新するDatabricks-Certified-Data-Engineer-Professional|ハイパスレートのDatabricks-Certified-Data-Engineer-Professionalソフトウエア試験|試験の準備方法Databricks Certified Data Engineer Professional Exam資格認証攻略 🏘 「 www.it-passports.com 」に移動し、⏩ Databricks-Certified-Data-Engineer-Professional ⏪を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional最新な問題集
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, scalar.usc.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Topexam Databricks-Certified-Data-Engineer-Professionalダンプの一部を無料でダウンロード:https://drive.google.com/open?id=12lsknpWAC08AQYFHLzfRrDbH9DGkFujp


