DP-700 Reliable Exam Pattern, DP-700 Accurate Study Material

P.S. Free 2026 Microsoft DP-700 dumps are available on Google Drive shared by ITExamSimulator: https://drive.google.com/open?id=12u_f2YVuOKQ2bv1eLLp8hQ2MajNF2zJK
The former customers who bought DP-700 training materials in our company all are impressed by the help as well as our after-sales services. That is true. We offer the most considerate after-sales services on our DP-700 exam questions for you 24/7 with the help of patient staff and employees. They are all professional and enthusiastic to offer help. All the actions on our DP-700 Study Guide aim to mitigate the loss of you and in contrast, help you get the desirable outcome.
| Section | Weight | Objectives |
|---|
| Topic 1: Implement and manage an analytics solution | 30–35% | - Configure workspace settings
- 1. Configure Dataflows Gen2 settings
- 2. Configure Spark workspace settings
- 3. Configure OneLake workspace settings
- 4. Configure domain workspace settings
- 5. Configure Microsoft Fabric workspace settings
- Manage data lifecycle and governance
- 1. Manage data access and security
- 2. Implement data retention and archiving
- 3. Implement data governance with Microsoft Purview
- Manage data storage
- 1. Implement data mirroring
- 2. Create and manage OneLake shortcuts
- 3. Choose appropriate data stores
|
| Topic 2: Ingest and transform data | 30–35% | - Ingest data
- 1. Ingest data using Dataflows Gen2
- 2. Ingest data using Eventstreams
- 3. Ingest data using pipelines
- Orchestrate data operations
- 1. Orchestrate with notebooks and pipelines
- 2. Implement schedules and triggers
- 3. Use parameters and dynamic expressions
- Design and implement data loading patterns
- 1. Prepare data for dimensional models
- 2. Design streaming data loading patterns
- 3. Design full and incremental data loads
- Transform data
- 1. Transform data using KQL
- 2. Clean, denormalize, and aggregate data
- 3. Transform data using SQL
- 4. Transform data using PySpark
|
| Topic 3: Monitor and optimize an analytics solution | 30–35% | - Optimize performance
- 1. Optimize Spark and query performance
- 2. Optimize storage efficiency
- 3. Optimize pipelines and data flows
- 4. Optimize Lakehouse and data warehouse performance
- Monitor analytics solutions
- 1. Configure alerts and notifications
- 2. Monitor data ingestion and transformation
- 3. Monitor Fabric items and activities
- 4. Monitor semantic model refreshes
- Troubleshoot issues
- 1. Identify and resolve pipeline errors
- 2. Identify and resolve Dataflow errors
- 3. Identify and resolve storage and query errors
- 4. Identify and resolve notebook and Spark errors
|
>> DP-700 Reliable Exam Pattern <<
DP-700 Accurate Study Material | Exam Dumps DP-700 Free
our DP-700 exam questions beckon exam candidates around the world with our attractive characters. Our experts made significant contribution to their excellence. So we can say bluntly that our DP-700 simulating exam is the best. Our effort in building the content of our DP-700 Study Materials lead to the development of learning guide and strengthen their perfection. To add up your interests and simplify some difficult points, our experts try their best to design our study material and help you understand the learning guide better.
Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric Sample Questions (Q135-Q140):
NEW QUESTION # 135
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
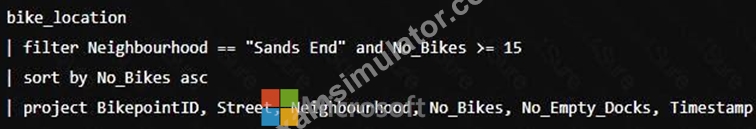
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment:
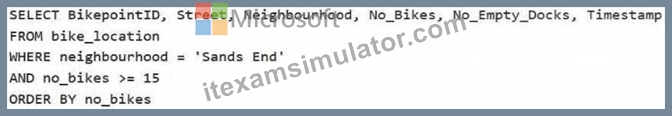
Does this meet the goal?
Answer: B
Explanation:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like:
NEW QUESTION # 136
You have a Fabric warehouse named DW1 that loads data by using a data pipeline named Pipeline1. Pipeline1 uses a Copy data activity with a dynamic SQL source. Pipeline1 is scheduled to run every 15 minutes.
You discover that Pipeline1 keeps failing.
You need to identify which SQL query was executed when the pipeline failed.
What should you do?
- A. From Real-time hub, select Fabric events, and then review the details of Microsoft.Fabric.
ItemReadFailed. - B. From Real-time hub, select Fabric events, and then review the details of Microsoft. Fabric.
ItemUpdateFailed. - C. From Monitoring hub, select the latest failed run of Pipeline1, and then view the input JSON.
- D. From Monitoring hub, select the latest failed run of Pipeline1, and then view the output JSON.
Answer: C
Explanation:
The input JSON contains the configuration details and parameters passed to the Copy data activity during execution, including the dynamically generated SQL query.
Viewing the input JSON for the failed pipeline run provides direct insight into what query was executed at the time of failure.
NEW QUESTION # 137
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
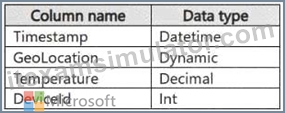
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
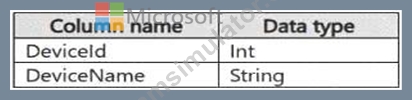
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
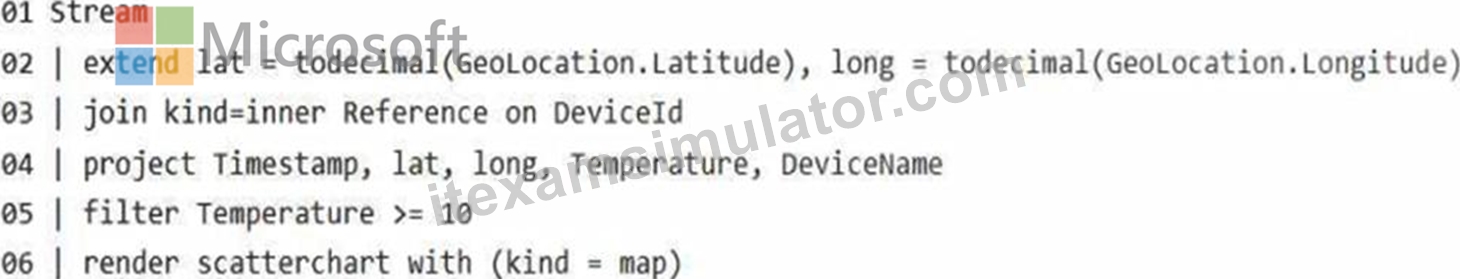
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
Answer: B
Explanation:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time.
It does not improve query performance.
NEW QUESTION # 138
You have three users named User1, User2, and User3.
You have the Fabric workspaces shown in the following table.
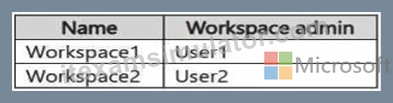
You have a security group named Group1 that contains User1 and User3.
The Fabric admin creates the domains shown in the following table.
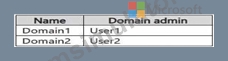
User1 creates a new workspace named Workspace3.
You add Group1 to the default domain of Domain1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
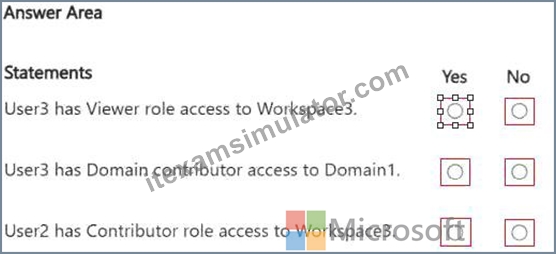
Answer:
Explanation:
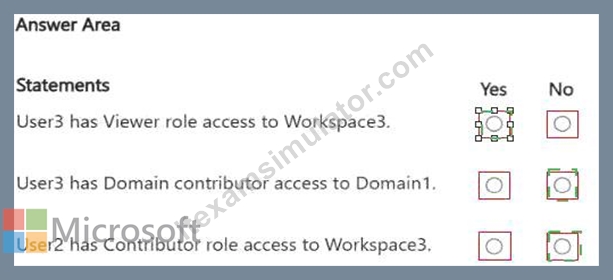
Explanation:
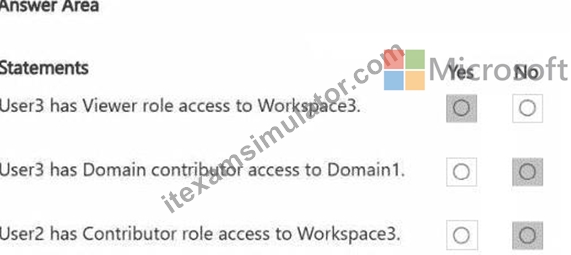
NEW QUESTION # 139
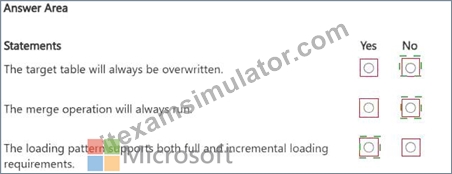
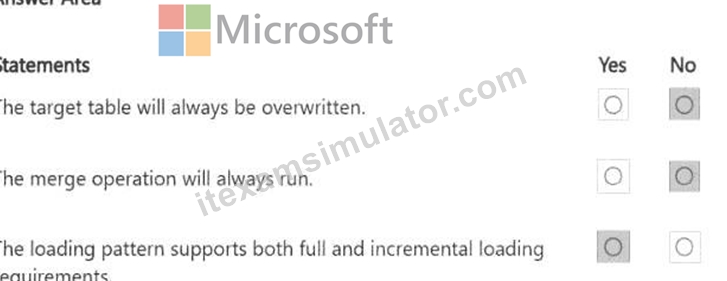
HOTSPOT
You are building a data loading pattern for Fabric notebook workloads.
You have the following code segment:
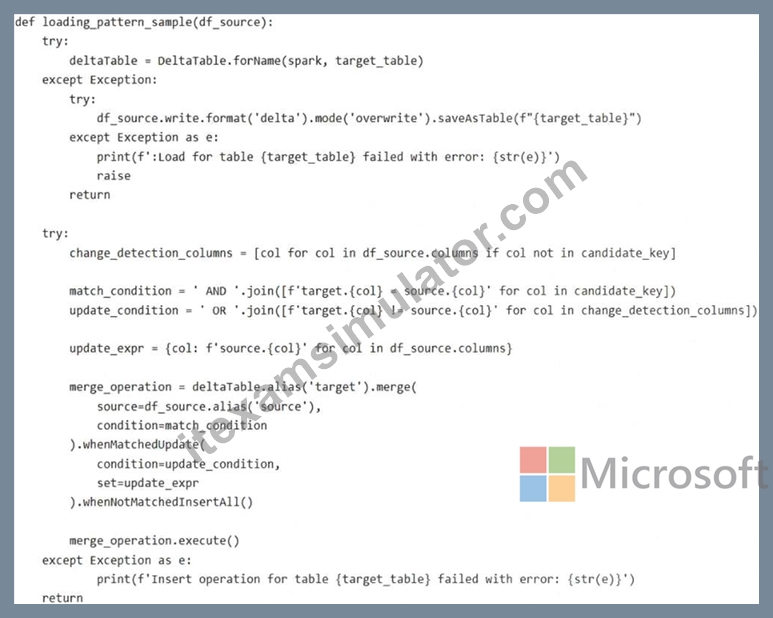
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
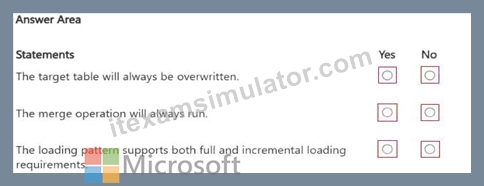
Answer:
Explanation:
Explanation:
NEW QUESTION # 140
......
Along with DP-700 self-evaluation exams, Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) dumps PDF is also available at ITExamSimulator. These DP-700 questions can be used for quick DP-700 exam preparation. Our DP-700 dumps PDF format works on a range of Smart devices, such as laptops, tablets, and smartphones. Since Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) questions PDF are easily accessible, you can easily prepare for the test without time and place constraints. You can also print this format of ITExamSimulator's Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam dumps to prepare off-screen and on the go.
DP-700 Accurate Study Material: https://www.itexamsimulator.com/DP-700-brain-dumps.html
- Latest Updated DP-700 Reliable Exam Pattern Supply you Valuable Accurate Study Material for DP-700: Implementing Data Engineering Solutions Using Microsoft Fabric to Prepare easily 🥫 【 www.exam4labs.com 】 is best website to obtain ( DP-700 ) for free download 😹DP-700 Valid Mock Test
- Get Valid DP-700 Reliable Exam Pattern and Excellent DP-700 Accurate Study Material 🎢 Search for 《 DP-700 》 and download exam materials for free through ⇛ www.pdfvce.com ⇚ 📎DP-700 Valid Test Format
- 2026 DP-700 Reliable Exam Pattern | The Best 100% Free DP-700 Accurate Study Material 🤚 Download ➽ DP-700 🢪 for free by simply entering ( www.examdiscuss.com ) website 🥰Authentic DP-700 Exam Questions
- Microsoft DP-700 Exam Dumps Offers Exam Passing Money Back Guarantee 💍 Search for ➽ DP-700 🢪 and easily obtain a free download on ⮆ www.pdfvce.com ⮄ ✊Certification DP-700 Dumps
- Latest Updated DP-700 Reliable Exam Pattern Supply you Valuable Accurate Study Material for DP-700: Implementing Data Engineering Solutions Using Microsoft Fabric to Prepare easily 🍧 Open website ➽ www.prepawayete.com 🢪 and search for ▷ DP-700 ◁ for free download 🟡Authentic DP-700 Exam Questions
- 2026 DP-700 Reliable Exam Pattern | The Best 100% Free DP-700 Accurate Study Material 🧬 Search for 「 DP-700 」 and download exam materials for free through 《 www.pdfvce.com 》 😖DP-700 Pdf Torrent
- Valid Microsoft DP-700 exam pdf - DP-700 practice exam - DP-700 braindumps2go dumps 🧳 Search for ▛ DP-700 ▟ on ▷ www.vce4dumps.com ◁ immediately to obtain a free download 💏DP-700 Exam Tests
- 2026 DP-700 Reliable Exam Pattern | The Best 100% Free DP-700 Accurate Study Material 🧛 Immediately open ▶ www.pdfvce.com ◀ and search for ✔ DP-700 ️✔️ to obtain a free download 🐥Reliable DP-700 Study Plan
- DP-700 Prep Guide is Closely Related with the Real DP-700 Exam - www.troytecdumps.com 🤯 Go to website “ www.troytecdumps.com ” open and search for ☀ DP-700 ️☀️ to download for free 🕑DP-700 Valid Test Sample
- DP-700 Prep Guide is Closely Related with the Real DP-700 Exam - Pdfvce Ⓜ Search on ( www.pdfvce.com ) for ➡ DP-700 ️⬅️ to obtain exam materials for free download 🌊DP-700 Real Exams
- HOT DP-700 Reliable Exam Pattern - High-quality Microsoft DP-700 Accurate Study Material: Implementing Data Engineering Solutions Using Microsoft Fabric 🚘 Search for ⇛ DP-700 ⇚ and download it for free immediately on ( www.verifieddumps.com ) 🌋DP-700 Test Free
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of ITExamSimulator DP-700 dumps for free: https://drive.google.com/open?id=12u_f2YVuOKQ2bv1eLLp8hQ2MajNF2zJK