Pass Guaranteed Databricks Databricks-Certified-Professional-Data-Engineer - Marvelous Pass Databricks Certified Professional Data Engineer Exam Guide

After years of unremitting efforts, our Databricks-Certified-Professional-Data-Engineer exam materials and services have received recognition and praises by the vast number of customers. An increasing number of candidates choose our Databricks-Certified-Professional-Data-Engineer study braindumps as their exam plan utility. There are a lot of advantages about our Databricks-Certified-Professional-Data-Engineer training guide. Not only our Databricks-Certified-Professional-Data-Engineer learning questions are always the latest and valid, but also the prices of the different versions are quite favourable.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
|---|
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Available Languages: | English |
|---|
| Real Exam Qty: | 60 |
|---|
| Passing Score: | 70% |
|---|
| Related Certifications: | Databricks Certified Data Analyst Associate
Databricks Certified Associate Developer |
|---|
| Exam Price: | $200 USD |
|---|
| Exam Format: | Multiple Select, Multiple Choice |
|---|
| Exam Duration: | 90 minutes |
|---|
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
|---|
| Exam Way: | Online proctored exam (Pearson VUE) |
|---|
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
|---|
>> Pass Databricks-Certified-Professional-Data-Engineer Guide <<
Provides Excellent Databricks-Certified-Professional-Data-Engineer Prep Guide for Databricks-Certified-Professional-Data-Engineer Exam - PracticeTorrent
During your use of our Databricks-Certified-Professional-Data-Engineer learning materials, we also provide you with 24 hours of free online services. Whenever you encounter any Databricks-Certified-Professional-Data-Engineer problems in the learning process, you can email us and we will help you to solve them immediately. And you will find that our service can give you not only the most professional advice on Databricks-Certified-Professional-Data-Engineer Exam Questions, but also the most accurate data on the updates.
Databricks Certified Professional Data Engineer exam is a comprehensive assessment that covers a wide range of topics related to data engineering using Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to design, build, and optimize data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer exam is available online and can be taken from anywhere in the world, making it a convenient option for data professionals who want to validate their expertise in Databricks. Upon successful completion of the exam, candidates will receive a Databricks Certified Professional Data Engineer certification, which will demonstrate their proficiency in data engineering using Databricks.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q70-Q75):
NEW QUESTION # 70
A facilities-monitoring team is building a near-real-time Power BI dashboard off the Delta table device_readings :
* device_id STRING - unique sensor ID
* event_ts TIMESTAMP - ingestion timestamp (UTC)
* temperature_c DOUBLE - temperature in °C
* notes STRING
For each sensor, the team needs one row per non-overlapping 5-minute interval, offset by 2 minutes (for example, intervals like 00:02-00:07 , 00:07-00:12 , and so on), showing the average temperature in that slice.
The result must include each interval's start and end timestamps so downstream tools can plot time-series bars correctly. Which query satisfies the requirement?
- A. SELECT
device_id,
event_ts,
AVG(temperature_c) OVER (
PARTITION BY device_id
ORDER BY event_ts
RANGE BETWEEN INTERVAL 5 MINUTES PRECEDING AND CURRENT ROW
) AS avg_temp_5m
FROM device_readings
WINDOW w AS (window(event_ts, ' 5 minutes ' , ' 2 minutes ' )); - B. WITH buckets AS (
SELECT
device_id,
window(event_ts, ' 5 minutes ' , ' 5 minutes ' , ' 2 minutes ' ) AS win, temperature_c FROM device_readings ) SELECT device_id, win.start AS bucket_start, win.end AS bucket_end, AVG(temperature_c) AS avg_temp_5m FROM buckets GROUP BY device_id, win ORDER BY device_id, bucket_start; - C. SELECT
device_id,
date_trunc( ' minute ' , event_ts - INTERVAL 2 MINUTES) + INTERVAL 2 MINUTES AS bucket_start, date_trunc( ' minute ' , event_ts - INTERVAL 2 MINUTES) + INTERVAL 7 MINUTES AS bucket_end, AVG(temperature_c) AS avg_temp_5m FROM device_readings GROUP BY device_id, date_trunc( ' minute ' , event_ts - INTERVAL 2 MINUTES) ORDER BY device_id, bucket_start; - D. SELECT
device_id,
window.start AS bucket_start,
window.end AS bucket_end,
AVG(temperature_c) AS avg_temp_5m
FROM device_readings
GROUP BY device_id, window(event_ts, ' 5 minutes ' , ' 5 minutes ' , ' 2 minutes ' ) ORDER BY device_id, bucket_start;
Answer: B
Explanation:
Spark documents window(timeColumn, windowDuration, slideDuration=None, startTime=None) for time bucketing. The startTime argument is specifically the offset from the epoch used to align window boundaries, and the output is a window struct with start and end fields. That exactly matches the requirement for 5-minute non-overlapping intervals offset by 2 minutes. ( Apache Spark ) Option A correctly uses window(event_ts, ' 5 minutes ' , ' 5 minutes ' , ' 2 minutes ' ) , which creates tumbling
5-minute windows offset by 2 minutes and then exposes win.start and win.end . Option B is malformed in how it references the generated window column, option C creates minute-aligned groupings rather than true 5- minute tumbling windows, and option D computes a rolling window average instead of one row per non- overlapping time bucket. ( Apache Spark )
NEW QUESTION # 71
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
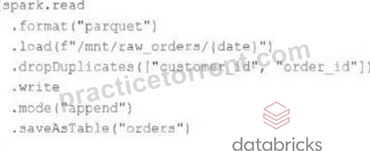
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- B. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- D. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: D
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 72
You are noticing job cluster is taking 6 to 8 mins to start which is delaying your job to finish on time, what steps you can take to reduce the amount of time cluster startup time
- A. Setup a second job ahead of first job to start the cluster, so the cluster is ready with re-sources when the job starts
- B. Use SQL endpoints to reduce the startup time
- C. Use All purpose cluster instead to reduce cluster start up time
- D. Reduce the size of the cluster, smaller the cluster size shorter it takes to start the clus-ter
- E. Use cluster pools to reduce the startup time of the jobs
Answer: E
Explanation:
Explanation
The answer is, Use cluster pools to reduce the startup time of the jobs.
Cluster pools allow us to reserve VM's ahead of time, when a new job cluster is created VM are grabbed from the pool. Note: when the VM's are waiting to be used by the cluster only cost incurred is Azure. Databricks run time cost is only billed once VM is allocated to a cluster.
Here is a demo of how to setup and follow some best practices,
https://www.youtube.com/watch?v=FVtITxOabxg&ab_channel=DatabricksAcademy
NEW QUESTION # 73
Which of the following describes a scenario in which a data engineer will want to use a Job cluster instead of
an all-purpose cluster?
- A. A data team needs to collaborate on the development of a machine learning model
- B. An ad-hoc analytics report needs to be developed while minimizing compute costs
- C. A Databricks SQL query needs to be scheduled for upward reporting
- D. A data engineer needs to manually investigate a production error
- E. An automated workflow needs to be run every 30 minutes
Answer: E
NEW QUESTION # 74
A nightly job ingests data into a Delta Lake table using the following code:
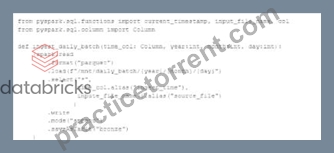
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.readStream.load("bronze")
- B.
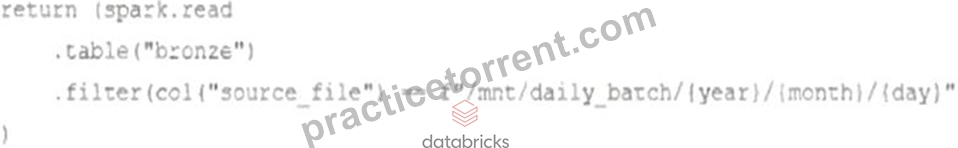
- C. return spark.read.option("readChangeFeed", "true").table ("bronze")
- D. return spark.readStream.table("bronze")
Answer: B
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 75
......
Updated Databricks-Certified-Professional-Data-Engineer Test Cram: https://www.practicetorrent.com/Databricks-Certified-Professional-Data-Engineer-practice-exam-torrent.html
- Free PDF Quiz 2026 Marvelous Databricks Databricks-Certified-Professional-Data-Engineer: Pass Databricks Certified Professional Data Engineer Exam Guide 🥤 Search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ and easily obtain a free download on 「 www.validtorrent.com 」 🙅Databricks-Certified-Professional-Data-Engineer Valid Test Registration
- Databricks-Certified-Professional-Data-Engineer Latest Exam Online 🦎 Databricks-Certified-Professional-Data-Engineer Mock Test 👭 Databricks-Certified-Professional-Data-Engineer Mock Test 🎲 Download ( Databricks-Certified-Professional-Data-Engineer ) for free by simply searching on ➥ www.pdfvce.com 🡄 🧪Reliable Databricks-Certified-Professional-Data-Engineer Study Plan
- 100% Pass Quiz Databricks - Databricks-Certified-Professional-Data-Engineer Fantastic Pass Guide ⛵ Copy URL “ www.prepawayete.com ” open and search for “ Databricks-Certified-Professional-Data-Engineer ” to download for free 🤜Databricks-Certified-Professional-Data-Engineer Study Guides
- 100% Pass Quiz Databricks - Databricks-Certified-Professional-Data-Engineer Fantastic Pass Guide 📳 Open ⇛ www.pdfvce.com ⇚ enter ▛ Databricks-Certified-Professional-Data-Engineer ▟ and obtain a free download 🍐Sample Databricks-Certified-Professional-Data-Engineer Exam
- 2026 Updated Pass Databricks-Certified-Professional-Data-Engineer Guide | 100% Free Updated Databricks-Certified-Professional-Data-Engineer Test Cram ☁ Open ➽ www.testkingpass.com 🢪 and search for { Databricks-Certified-Professional-Data-Engineer } to download exam materials for free 📀Reliable Databricks-Certified-Professional-Data-Engineer Test Materials
- Free PDF Quiz 2026 Marvelous Databricks Databricks-Certified-Professional-Data-Engineer: Pass Databricks Certified Professional Data Engineer Exam Guide 🧱 Simply search for 《 Databricks-Certified-Professional-Data-Engineer 》 for free download on { www.pdfvce.com } ⛳Sample Databricks-Certified-Professional-Data-Engineer Exam
- Quiz 2026 High Hit-Rate Databricks Databricks-Certified-Professional-Data-Engineer: Pass Databricks Certified Professional Data Engineer Exam Guide 🌕 Immediately open ▛ www.prepawayete.com ▟ and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to obtain a free download 🕤Databricks-Certified-Professional-Data-Engineer Test Braindumps
- Databricks-Certified-Professional-Data-Engineer Exam Cost 🅿 Reliable Databricks-Certified-Professional-Data-Engineer Test Materials 🥄 Reliable Databricks-Certified-Professional-Data-Engineer Learning Materials 🥵 The page for free download of ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ on ⏩ www.pdfvce.com ⏪ will open immediately 🍤Databricks-Certified-Professional-Data-Engineer Guaranteed Questions Answers
- 2026 Updated Pass Databricks-Certified-Professional-Data-Engineer Guide | 100% Free Updated Databricks-Certified-Professional-Data-Engineer Test Cram ⏰ Open website ⮆ www.exam4labs.com ⮄ and search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download ✉Reliable Databricks-Certified-Professional-Data-Engineer Learning Materials
- Excel in the Certification Exam With Real Databricks Databricks-Certified-Professional-Data-Engineer Questions 🌱 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download it for free immediately on [ www.pdfvce.com ] 🪑Databricks-Certified-Professional-Data-Engineer Study Guides
- 2026 Updated Pass Databricks-Certified-Professional-Data-Engineer Guide | 100% Free Updated Databricks-Certified-Professional-Data-Engineer Test Cram 🐣 Immediately open ⮆ www.practicevce.com ⮄ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to obtain a free download ⛑Latest Databricks-Certified-Professional-Data-Engineer Mock Exam
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes