2026 Latest BraindumpsPass Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1Bsp_EulrPCbCsieNcykMyJR4I1NrpZGu
If you prefer to Practice Databricks-Generative-AI-Engineer-Associate Exam dumps on paper, you can try the exam dumps of us. Databricks-Generative-AI-Engineer-Associate PDF version is printable, and you can take some notes on it and can practice them anytime. Besides through using Databricks-Generative-AI-Engineer-Associate e questions and answers of us, you can pass the exam and get a certificate successfully. We offer you pass guarantee and money back guarantee if you fail to pass the exam. Once you have made your decision, just add them into your cart and pay for it, we will send the downloading link in ten minutes.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Test Databricks-Generative-AI-Engineer-Associate Dump <<
To develop a new study system needs to spend a lot of manpower and financial resources, first of all, essential, of course, is the most intuitive skill learning materials, to some extent this greatly affected the overall quality of the learning materials. Our Databricks Certified Generative AI Engineer Associate study training dumps do our best to find all the valuable reference books, then, the product we hired experts will carefully analyzing and summarizing the related materials, such as: Databricks Databricks-Generative-AI-Engineer-Associate exam, eventually form a complete set of the review system. Experts before starting the compilation of " the Databricks-Generative-AI-Engineer-Associate Latest Questions ", has put all the contents of the knowledge point build a clear framework in mind, though it needs a long wait, but product experts and not give up, but always adhere to the effort, in the end, they finished all the compilation. So, you're lucky enough to meet our Databricks-Generative-AI-Engineer-Associate test guide l, and it's all the work of the experts. If you want to pass the qualifying exam with high quality, choose our products. We are absolutely responsible for you. Don't hesitate!
NEW QUESTION # 66
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: A,D
NEW QUESTION # 67
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: A
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval- Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
* Ingest documents from a source : This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
* Index the documents and save to Vector Search : Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
* User submits queries against an LLM : Users interact with the application by submitting their queries. These queries will be passed to the LLM.
* LLM retrieves relevant documents : The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
* LLM generates a response : Using the retrieved documents, the LLM generates a response that is tailored to the user ' s question.
* Evaluate model : After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
* Deploy it using Model Serving : Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 68
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: D
Explanation:
* Problem Context : When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options :
* Option A : Reaching out to data curators before using the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B : Using original data that you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C : Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D : Reaching out to the data curators after you have already started using the trained model is not appropriate . If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications.
It's essential to clarify the licensing terms before using the data, not after.
Thus, Option D is not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 69
A team wants to serve a code generation model as an assistant for their software developers. It should support multiple programming languages. Quality is the primary objective.
Which of the Databricks Foundation Model APIs, or models available in the Marketplace, would be the best fit?
Answer: C
Explanation:
For a code generation model that supports multiple programming languages and where quality is the primary objective, CodeLlama-34B is the most suitable choice. Here's the reasoning:
Specialization in Code Generation:
CodeLlama-34B is specifically designed for code generation tasks. This model has been trained with a focus on understanding and generating code, which makes it particularly adept at handling various programming languages and coding contexts.
Capacity and Performance:
The "34B" indicates a model size of 34 billion parameters, suggesting a high capacity for handling complex tasks and generating high-quality outputs. The large model size typically correlates with better understanding and generation capabilities in diverse scenarios.
Suitability for Development Teams:
Given that the model is optimized for code, it will be able to assist software developers more effectively than general-purpose models. It understands coding syntax, semantics, and the nuances of different programming languages.
Why Other Options Are Less Suitable:
A (Llama2-70b): While also a large model, it's more general-purpose and may not be as fine-tuned for code generation as CodeLlama.
B (BGE-large): This model may not specifically focus on code generation.
C (MPT-7b): Smaller than CodeLlama-34B and likely less capable in handling complex code generation tasks at high quality.
Therefore, for a high-quality, multi-language code generation application, CodeLlama-34B (option D) is the best fit.
NEW QUESTION # 70
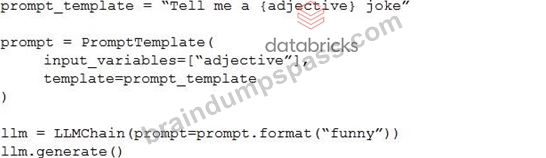
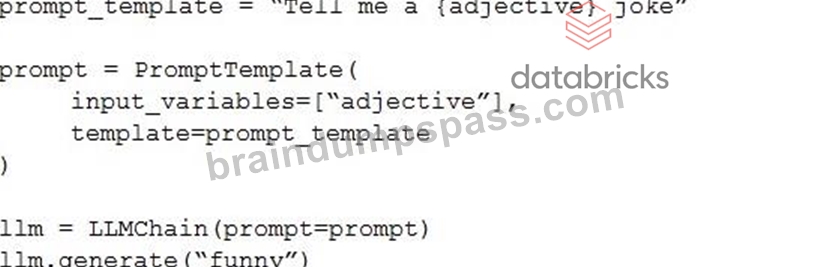
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?


Answer: D
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 71
......
The clients at home and abroad can both purchase our Databricks-Generative-AI-Engineer-Associate study tool online. Our brand enjoys world-wide fame and influences so many clients at home and abroad choose to buy our Databricks-Generative-AI-Engineer-Associate test guide. Our company provides convenient service to the clients all around the world so that the clients all around the world can use our Databricks-Generative-AI-Engineer-Associate Study Materials efficiently. Our company boosts an entire sale system which provides the links to the clients all around the world so that the clients can receive our Databricks-Generative-AI-Engineer-Associate exam questions timely.
Databricks-Generative-AI-Engineer-Associate Vce Test Simulator: https://www.braindumpspass.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
What's more, part of that BraindumpsPass Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1Bsp_EulrPCbCsieNcykMyJR4I1NrpZGu