P.S. Kostenlose und neue MLA-C01 Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1aeCLHUbZWh4lQKtbvbrGOOZUYyZINea1
Nun gibt es viele IT-Profis in der ganzen Welt und die Konkurrenz der IT-Branche ist sehr hart. So viele IT-Profis entscheiden sich dafür, an der IT-Zertifizierungsprüfung teilzunehmen, um ihre Position in der IT-Branche zu verstärken. Die MLA-C01 Prüfung ist eine sehr wichtige Amazon-Zertifizierungsprüfung. Aber wenn Sie eine Amazon-Zertifizierung erhalten wollen, müssen Sie die Prüfung bestehen.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Duration: | 130 minutes |
| Exam Price: | 150 USD |
| Available Languages: | Japanese, Simplified Chinese, English, Korean |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Certificate Validity Period: | 3 years |
| Passing Score: | 720 (scaled score 100–1000) |
| Exam Format: | Multiple choice, Case study, Matching, Ordering, Multiple response |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
Warum versprechen wir, dass wir Ihnen Geld zurückgeben, wenn Sie die Amazon MLA-C01 Prüfung nicht bestehen? Denn zahlose Kunden, die unsere Prüfungssofteware benutzt haben, bestehen die Amazon MLA-C01 Zertifizierungsprüfung, was uns die Konfidenz bringt. Amazon MLA-C01 Prüfung ist eine sehr wichtige Beweis der IT-Fähigkeit für die Angestellte im IT-Gewerbe. Aber die Prüfung ist auch schwierig. Die Arbeiter von It-Pruefung haben die Amazon MLA-C01 Prüfungsunterlagen mit große Einsätze geforscht. Die Software ist das Geistesprodukt vieler IT-Spezialist.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
87. Frage
A company uses 10 Reserved Instances of accelerated instance types to serve the current version of an ML model. An ML engineer needs to deploy a new version of the model to an Amazon SageMaker real-time inference endpoint.
The solution must use the original 10 instances to serve both versions of the model. The solution also must include one additional Reserved Instance that is available to use in the deployment process. The transition between versions must occur with no downtime or service interruptions.
Which solution will meet these requirements?
Antwort: D
88. Frage
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.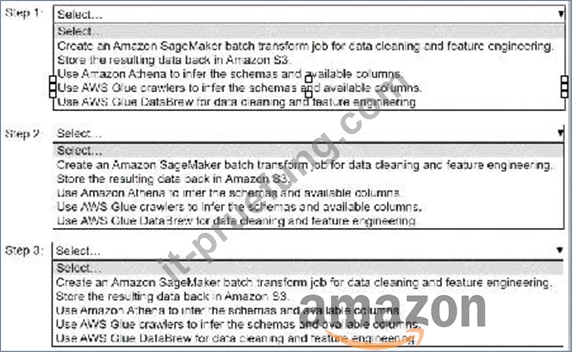
Antwort:
Begründung: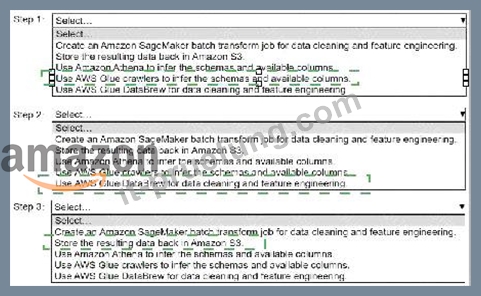
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
89. Frage
An ML engineer is setting up a continuous integration and continuous delivery (CI/CD) pipeline for an ML workflow in Amazon SageMaker AI. The pipeline needs to automate model re-training, testing, and deployment whenever new data is uploaded to an Amazon S3 bucket. New data files are approximately 10 GB in size. The ML engineer wants to track model versions for auditing.
Which solution will meet these requirements?
Antwort: A
Begründung:
AWS provides Amazon SageMaker Pipelines as the native CI/CD solution for ML. Pipelines can automatically trigger retraining when new data arrives in Amazon S3, handle large datasets (such as 10 GB files), and orchestrate preprocessing, training, evaluation, and deployment steps.
For governance and auditing, Amazon SageMaker Model Registry integrates directly with Pipelines to manage model versions, approval status, and metadata such as training metrics. This combination eliminates the need for custom tracking logic and ensures traceability across the ML lifecycle.
Option A lacks native ML lineage and version governance. Option C is unsuitable for large data and complex workflows. Option D is manual and not scalable.
Therefore, using SageMaker Pipelines with the Model Registry is the correct and AWS-recommended solution.
90. Frage
A company is developing an ML model for a customer. The training data is stored in an Amazon S3 bucket in the customer ' s AWS account (Account A). The company runs Amazon SageMaker AI training jobs in a separate AWS account (Account B).
The company defines an S3 bucket policy and an IAM policy to allow reads to the S3 bucket.
Which additional steps will meet the cross-account access requirement?
Antwort: D
Begründung:
For cross-account Amazon S3 access, AWS requires two components:
An S3 bucket policy in the owning account (Account A) that grants access to a principal in another account An IAM role policy in the consuming account (Account B) that allows the service to access the bucket Amazon SageMaker training jobs assume an IAM role in the account where the job runs-in this case, Account B. Therefore, the IAM policy must be attached to the SageMaker execution role in Account B.
The S3 bucket policy must reside in Account A because bucket policies are owned and enforced by the bucket owner. This policy explicitly allows the IAM role from Account B to read the training data.
Any other combination fails either because the policy is in the wrong account or because the role is not the one used by SageMaker.
AWS documentation clearly describes this pattern as the correct way to grant cross-account access for SageMaker training jobs.
Therefore, Option B is the correct and AWS-aligned solution.
91. Frage
A company is using Amazon SageMaker AI to build an ML model to predict customer behavior. The company needs to explain the bias in the model to an auditor. The explanation must focus on demographic data of the customers.
Which solution will meet these requirements?
Antwort: C
Begründung:
AWS documentation identifies Amazon SageMaker Clarify as the primary service for detecting, measuring, and explaining bias in ML models, particularly across demographic and sensitive attributes such as age, gender, and location. Clarify can analyze bias before training, after training, and during inference, making it suitable for audit and compliance requirements.
SageMaker Clarify generates bias reports using established fairness metrics such as difference in positive proportions, disparate impact, and conditional demographic disparity. These reports are exportable and auditor-friendly, directly meeting the requirement to explain bias to an external party.
AWS Glue DataBrew focuses on data preparation and quality, not bias detection. Amazon QuickSight does not provide ML fairness metrics. Amazon CloudWatch captures operational metrics, not demographic bias indicators.
AWS best practices explicitly recommend SageMaker Clarify for model transparency, fairness evaluation, and regulatory reporting.
Therefore, Option A is the correct and AWS-verified solution.
92. Frage
......
MLA-C01 Zertifizierungsantworten: https://www.it-pruefung.com/MLA-C01.html
P.S. Kostenlose und neue MLA-C01 Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1aeCLHUbZWh4lQKtbvbrGOOZUYyZINea1