DOWNLOAD the newest Dumpleader DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1sSmwdtt7k973O88j4FHKp4EniU2bL0wk
The Microsoft DP-600 exam questions are being offered in three different formats. These formats are DP-600 PDF dumps files, desktop practice test software, and web-based practice test software. All these three DP-600 exam dumps formats contain the Real DP-600 Exam Questions that assist you in your Implementing Analytics Solutions Using Microsoft Fabric practice exam preparation and finally, you will be confident to pass the final Microsoft DP-600 exam easily.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Microsoft DP-600 New Cram Materials <<
There are great and plenty benefits after the clients pass the test. Because the knowledge that our DP-600 study materials provide is conducive to enhancing the clients’ practical working abilities and stocks of knowledge, the clients will be easier to increase their wages and be promoted by their boss. Besides, they will be respected by their colleagues, friends and family members and be recognized as the elites among the industry. They will acquire more access to work abroad for further studies. So the clients must appreciate our DP-600 Study Materials after they pass the test.
NEW QUESTION # 115
You have an Azure Data Lake Storage Gen2 account named storage! that contains a Parquet file named sales.
parquet.
You have a Fabric tenant that contains a workspace named Workspace1.
Using a notebook in Workspace1, you need to load the content of the file to the default lakehouse. The solution must ensure that the content will display automatically as a table named Sales in Lakehouse explorer.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.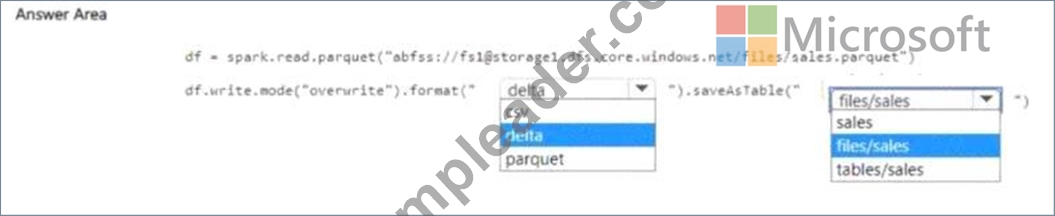
Answer:
Explanation: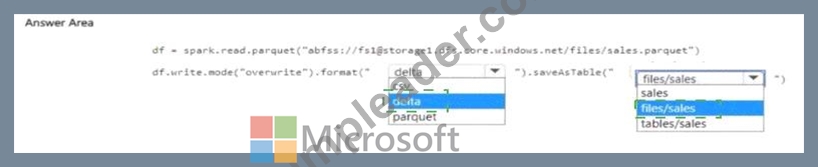
Explanation: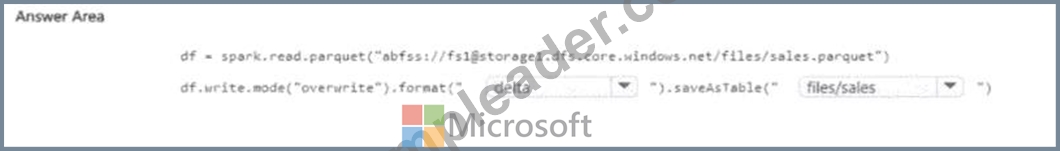
Step 1 - Read the Parquet file into a DataFrame
df = spark.read.parquet( " abfss://fs1@storage1.dfs.core.windows.net/files/sales.parquet " ) This correctly loads the Parquet data into Spark.
Step 2 - Write into the Lakehouse as a managed table
If we want the result to be registered as a Lakehouse table and automatically appear in Lakehouse Explorer, we must:
Write the data in delta format (because Fabric Lakehouse tables are Delta tables ).
Save the table under the tables folder, not files .
So the correct code is:
df.write.mode( " overwrite " ). format ( " delta " ).saveAsTable( " tables/sales " ) Format: delta SaveAsTable Path: tables/sales References:
Lakehouse tables in Microsoft Fabric
Save DataFrame as Delta Table in Spark
# Answer Selection:
First dropdown # delta
Second dropdown # tables/sales
NEW QUESTION # 116
You have source data in a folder on a local computer.
You need to create a solution that will use Fabric to populate a data store. The solution must meet the following requirements:
* Support the use of dataflows to load and append data to the data store.
* Ensure that Delta tables are V-Order optimized and compacted automatically.
Which type of data store should you use?
Answer: A,B
Explanation:
A lakehouse (A) is the type of data store you should use. It supports dataflows to load and append data and ensures that Delta tables are Z-Order optimized and compacted automatically. Reference = The capabilities of a lakehouse and its support for Delta tables are described in the lakehouse and Delta table documentation.
NEW QUESTION # 117
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.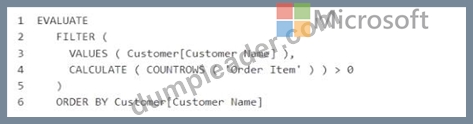
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
Answer: B
Explanation:
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.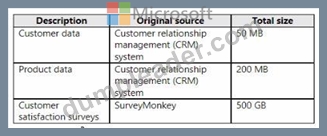
The Product data contains a single table and the following columns.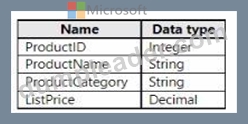
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 118
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.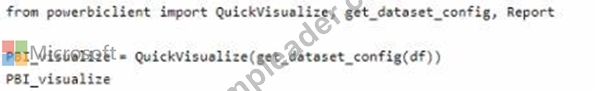
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.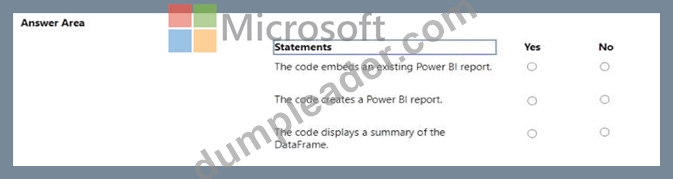
Answer:
Explanation: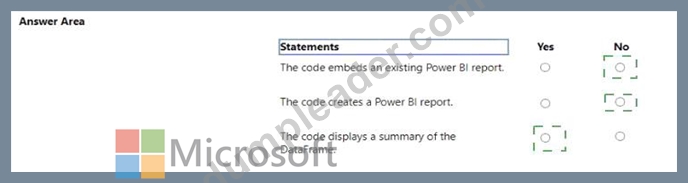
Explanation:
The code embeds an existing Power BI report. - No
The code creates a Power BI report. - Yes
The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report.
Instead, it's likely part of a data processing step that summarizes data.
References =
Introduction to DataFrames - Spark SQL
Power BI and Azure Databricks
NEW QUESTION # 119
You have a Microsoft Power Bl report and a semantic model that uses Direct Lake mode. From Power Bl Desktop, you open Performance analyzer as shown in the following exhibit.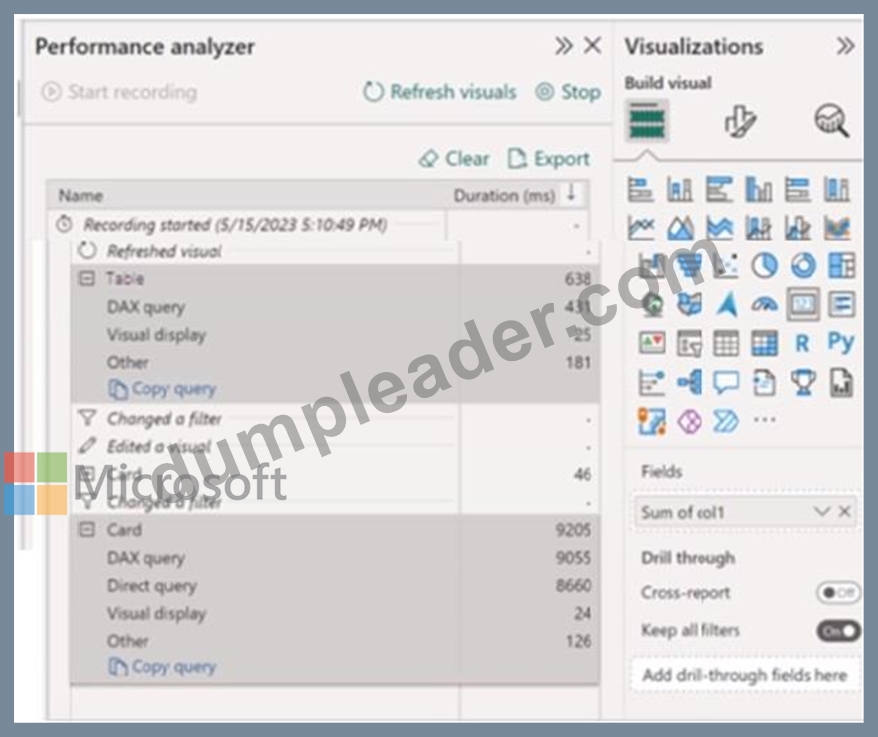
Use the dropdown menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.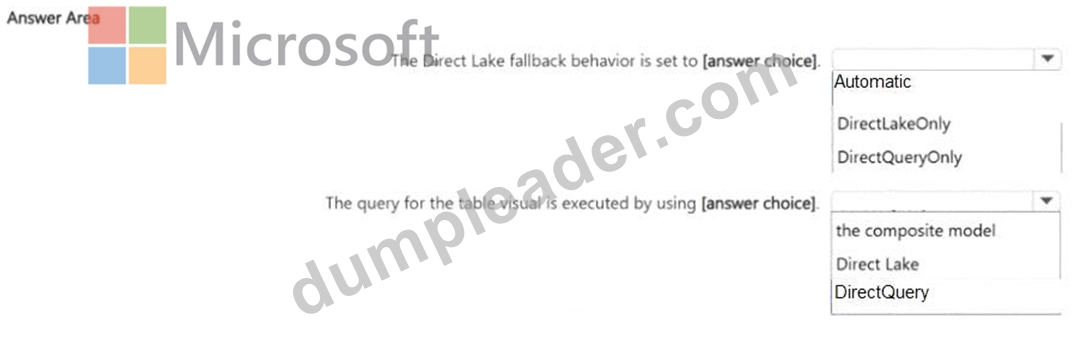
Answer:
Explanation: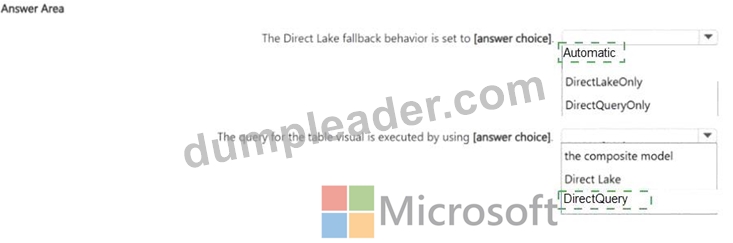
Explanation: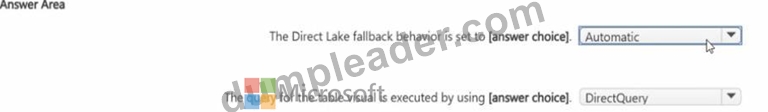
NEW QUESTION # 120
......
With our APP online version of our DP-600 learning guide, the users only need to open the App link, you can quickly open the learning content in real time in the ways of the DP-600 study materials, can let users anytime, anywhere learning through our App, greatly improving the use value of our DP-600 Exam Prep, but also provide mock exams, timed test and on-line correction function, achieve multi-terminal equipment of common learning.
New DP-600 Dumps Sheet: https://www.dumpleader.com/DP-600_exam.html
What's more, part of that Dumpleader DP-600 dumps now are free: https://drive.google.com/open?id=1sSmwdtt7k973O88j4FHKp4EniU2bL0wk