P.S. Tech4ExamがGoogle Driveで共有している無料かつ新しいMule-Arch-201ダンプ:https://drive.google.com/open?id=1hDn2l-vFTwZqLhGONhn-Vygi1WjAYR16
尊敬され、高い社会的地位を獲得することは、おそらくあなたが常に望んでいることです。しかし、それを達成したい場合は、特定の分野で優れた能力と深い知識を所有する必要があります。 Mule-Arch-201認定に合格すると、それが証明され、目標を実現するのに役立ちます。Mule-Arch-201クイズ準備を購入すると、Mule-Arch-201試験に合格できます。当社の製品は専門家によって編集され、長年の経験を持つ専門家によって承認されています。Tech4Exam購入前に、最新のMule-Arch-201クイズトレントを無料でダウンロードして試用できます。
| Section | Objectives |
|---|---|
| Data Integration and Transformation | - Batch vs real-time integration patterns - Data mapping and transformation strategies |
| Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Performance and Scalability | - High availability design patterns - Scaling Mule applications |
| Anypoint Platform Architecture | - Runtime Fabric architecture overview - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) |
| Integration Architecture Strategy | - Designing enterprise integration architecture - API-led connectivity principles - System, process, and experience APIs |
| API Management and Governance | - API lifecycle management - API security policies and enforcement - Governance frameworks and best practices |
Tech4ExamはMule-Arch-201認定試験に対する短期で有効な訓練を提供するウェブサイト、Mule-Arch-201認定試験が生活の変化をもたらすテストでございます。合格書を持ち方が持たない人により高い給料をもうけられます。
質問 # 74
An operations team is analyzing the effort needed to set up monitoring of their application network. They are looking at which API invocation metrics can be used to identify and predict trouble without having to write custom scripts or install additional analytics software or tools.
Which type of metrics can satisfy this goal of directly identifying and predicting failures?
正解:B
解説:
To monitor an application network and predict issues without custom scripts, policy violation metrics are critical. They provide insights into potential problems by tracking instances where API usage does not conform to defined policies. Here's why this approach is suitable:
Predictive Monitoring:
Tracking API policy violations (such as rate limits or spike controls being hit) can indicate surges in traffic or misuse, which may lead to throttling or service degradation if not addressed.
By monitoring these violations, teams can proactively adjust limits or optimize API handling to prevent actual failures.
No Custom Scripting Needed:
Policy violation metrics are available within MuleSoft's Anypoint Monitoring, meaning there's no need to implement custom solutions or external tools to gather and interpret this data.
of Incorrect Options:
Option B (effectiveness based on reuse) does not directly predict failures.
Option C (past invocation counts) offers historical usage data but does not inherently identify issues.
Option D (ROI from API invocation) is a business metric and does not provide technical insights for failure prediction.
Reference
For more details on leveraging policy violation metrics for proactive monitoring, refer to MuleSoft documentation on Anypoint Monitoring.
質問 # 75
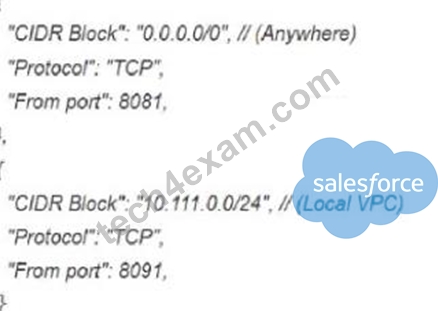
4 Production environment is running on a dedicated Virtual Private Cloud (VPC) on CloudHub 1,0, and the security team guidelines clearly state no traffic on HTTP.
Which two options support these security guidelines?
Choose 2 answers
正解:B、E
解説:
Security Guidelines Overview:
The production environment is hosted on a dedicated Virtual Private Cloud (VPC) on CloudHub 1.0, with a specific requirement from the security team that no traffic should occur over HTTP. This implies that only secure HTTPS traffic should be permitted, and HTTP access (port 8081, the default HTTP port in Mule applications) should be disabled.
Evaluating the Options:
Option A (Correct Answer): Configuring the HTTPS protocol in the HTTP listener in the Mule application ensures that all traffic is encrypted and occurs over HTTPS (port 8092 by default for HTTPS on Mule applications). This directly aligns with the security guideline to prevent unencrypted HTTP traffic.
Option B: Creating a custom policy for incoming and outgoing HTTP requests could provide some control over access, but it does not enforce the use of HTTPS exclusively. This option does not disable HTTP traffic and, therefore, does not meet the guideline effectively.
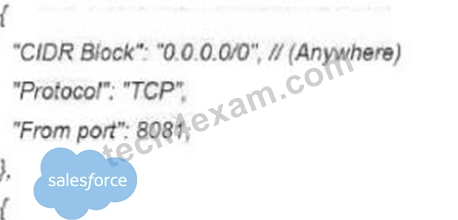
Option C (Correct Answer): Removing the entry for HTTP (port 8081) in the VPC firewall rule ensures that HTTP traffic is completely blocked at the firewall level. This prevents any HTTP requests from reaching the application, adding a layer of security that complies with the guidelines.
Option D: The IP Blocklist policy controls access based on IP addresses but does not enforce the use of HTTPS. This policy does not address the specific requirement of preventing HTTP traffic.
Option E: Adding a firewall rule entry for HTTP (port 8081) would enable HTTP traffic, which directly contradicts the security guidelines. Therefore, this option should be avoided.
Conclusion:
Option A and Option C are the correct choices. Configuring the HTTPS protocol in the Mule application's HTTP listener ensures that only HTTPS traffic is allowed, and removing the firewall rule for HTTP (port 8081) blocks any HTTP traffic from reaching the application. Together, these options enforce secure traffic as required by the security guidelines.
Refer to MuleSoft documentation on configuring HTTP listeners and managing VPC firewall rules for further details on implementing these security controls.
質問 # 76
Which component monitors APIs and endpoints at scheduled intervals, receives reports about whether tests pass or fail, and displays statistics about API and endpoint performance?
正解:D
解説:
Understanding API Functional Monitoring:
API Functional Monitoring is a feature within MuleSoft's Anypoint Platform that enables users to monitor the health and performance of APIs and endpoints by running functional tests at scheduled intervals.
It checks whether APIs are functioning as expected by running test calls and then evaluating if the response meets the desired conditions. This is particularly useful for testing endpoint availability, checking for specific data in responses, and measuring API performance over time.
Component Features:
Scheduled Intervals: Functional monitoring allows configuring tests to run at regular intervals, such as every minute, hour, or day, depending on the monitoring requirements.
Reports on Test Pass/Fail Status: After each test run, API Functional Monitoring reports whether the API passed or failed the test conditions.
Performance Statistics: It displays metrics like average response time, success rate, and error rates, giving insights into API health and performance.
Evaluating the Options:
Option A (API Analytics): API Analytics provides insights on API usage and metrics but does not involve scheduled tests for pass/fail status or endpoint health checks.
Option B (Anypoint Monitoring Dashboards): These dashboards display API metrics but do not actively test API endpoints or provide pass/fail reporting on a scheduled basis.
Option C (Correct Answer): API Functional Monitoring fits the description, as it is designed to monitor API and endpoint health with scheduled test runs and display statistics about performance.
Option D (Anypoint Runtime Manager Alerts): Runtime Manager alerts notify users of issues with application status but do not actively test endpoints at scheduled intervals.
Conclusion:
Option C (API Functional Monitoring) is the correct answer because it provides the necessary tools to test API functionality, monitor endpoint health, and display performance statistics in real-time.
Refer to MuleSoft documentation on API Functional Monitoring for further guidance on setting up and configuring these tests in Anypoint Platform.
質問 # 77
A Rate Limiting policy is applied to an API implementation to protect the back-end system. Recently, there have been surges in demand that cause some API client POST requests to the API implementation to be rejected with policy-related errors, causing delays and complications to the API clients.
How should the API policies that are applied to the API implementation be changed to reduce the frequency of errors returned to API clients, while still protecting the back-end system?
正解:D
解説:
When managing high traffic to an API, especially with POST requests, it is crucial to ensure the API's policies both protect the back-end systems and provide a smooth client experience. Here's the approach to reducing errors:
Rate Limiting Policy: This policy enforces a limit on the number of requests within a defined time period. However, rate limiting alone may cause clients to hit limits during demand surges, leading to errors.
Adding an SLA-based Spike Control Policy:
Spike Control is designed to handle sudden increases in traffic by smoothing out bursts of requests, which is particularly useful during high-demand periods.
By configuring SLA-based Spike Control, you can define thresholds for specific client tiers. For instance, premium clients might have higher limits or more flexibility in traffic bursts than standard clients.
Why Option D is Correct:
Keeping the Rate Limiting policy continues to provide baseline protection for the back-end.
Adding the SLA-based Spike Control policy allows for differentiated control, where requests are queued or delayed during bursts rather than outright rejected. This approach significantly reduces error responses to clients while still controlling overall traffic.
of Incorrect Options:
Option A (adding Client ID Enforcement) would not reduce errors related to traffic surges.
Option B (HTTP Caching) is not applicable as caching is generally ineffective for non-idempotent requests like POST.
Option C (only Spike Control without Rate Limiting) may leave the back-end system vulnerable to sustained high traffic levels, reducing protection.
Reference
For more information on configuring Rate Limiting and SLA-based Spike Control policies, refer to MuleSoft documentation on API Policies and Rate Limiting.
質問 # 78
4A developer for a transportation organization is implementing exactly one processing functionality in a Reservation Mule application to process and store passenger records. This Reservation application will be deployed to multiple CloudHub workers/replicas. It is possible that several external systems could send duplicate passenger records to the Reservation application.
An appropriate storage mechanism must be selected to help the Reservation application process each passenger record exactly once as much as possible. The selected storage mechanism must be shared by all the CloudHub workers/replicas in order to synchronize the state information to assist attempting exactly once processing of each passenger record by the deployed Reservation Mule application.
Which type of simple storage mechanism in Anypoint Platform allows the Reservation Mule application to update and share data between the CloudHub workers/replicas exactly once, with minimal development effort?
正解:C
解説:
Processing Requirements and Storage Mechanism:
The Reservation Mule application will be deployed to multiple CloudHub workers/replicas, meaning that each worker must share state information to handle records exactly once. This requires a shared storage mechanism where state can be stored and accessed by multiple instances to avoid duplicate processing of the same records.
A Persistent Object Store in Anypoint Platform can be used to store records in a way that is accessible across multiple workers, providing a reliable mechanism for "exactly once" processing.
Evaluating the Options:
Option A (Correct Answer): A Persistent Object Store is designed to retain data across different application instances and can be shared by all workers on CloudHub. It helps achieve idempotency by ensuring that a record is processed exactly once.
Option B: Runtime Fabric Object Store is used for applications deployed in Anypoint Runtime Fabric, not CloudHub. This option would not be compatible with the CloudHub deployment.
Option C: A Non-persistent Object Store does not retain data across application restarts or different instances, making it unsuitable for the requirement of synchronized storage for exactly-once processing.
Option D: An In-memory Mule Object Store is local to each worker and is not shared across instances, so it does not meet the requirement for a shared storage mechanism accessible to all CloudHub workers.
Conclusion:
Option A is the correct answer, as a Persistent Object Store allows data sharing across multiple CloudHub workers, enabling them to synchronize and achieve "exactly once" processing of passenger records with minimal development effort.
Refer to MuleSoft's documentation on Object Store configurations and usage for best practices on handling state across distributed instances.
質問 # 79
......
あなたが就職の面接に行くときにより競争上の優位性を得るために、ますます多くの人々がMule-Arch-201認定を取得することを切望しています。彼らは、認定が能力の具現化だと考えています。 Mule-Arch-201認定を取得することで、より良い仕事を探すことができるとすでに確信しています。ほとんどの人がMule-Arch-201試験に合格し、簡単に認定を受けることは非常に難しいことは間違いありません。また、Mule-Arch-201認定に関する問題に悩まされている場合は、問題を解決して安心させていただきます。
Mule-Arch-201ミシュレーション問題: https://www.tech4exam.com/Mule-Arch-201-pass-shiken.html
無料でクラウドストレージから最新のTech4Exam Mule-Arch-201 PDFダンプをダウンロードする:https://drive.google.com/open?id=1hDn2l-vFTwZqLhGONhn-Vygi1WjAYR16