PDII-JPNリンクグローバル &認定試験のリーダー & PDII-JPNミシュレーション問題

P.S. PassTestがGoogle Driveで共有している無料かつ新しいPDII-JPNダンプ:https://drive.google.com/open?id=1_OmGBbog8wR4ZCdXDzE_SFQlpp9Sbp_X
現在のステータスがPDII-JPNであるかどうかにかかわらず、試験問題は最も時間を節約し、自分の人生を持ちながらPDII-JPN試験に合格できます。 PDII-JPN試験問題のデモを無料でダウンロードした場合、当社の製品をより深く理解できると思います。また、PDII-JPN学習クイズも信頼する必要があります。当社の製品は、お客様に必要な高効率と高品質を提供できます。何を待っていますか?調査PDII-JPNの資料をすぐに使用してください!
Salesforce PDII-JPN Exam Syllabus Topics:
| Section | Objectives |
|---|
| Integration and Security | - Security implementation
- 1. CRUD/FLS enforcement in Apex
- 2. Sharing rules and security model
- Integration patterns
- 1. REST and SOAP APIs
- 2. External system integration patterns
|
| Advanced Apex Programming and Data Modeling | - Advanced Apex concepts
- 1. Asynchronous Apex (Queueable, Batch, Future, Scheduled)
- 2. Advanced SOQL/SOSL optimization
- Data Modeling
- 1. Performance considerations in data access
- 2. Schema design and relationships
|
| User Interface Development | - Lightning Component Development
- 1. Aura Components basics and integration
- 2. Lightning Web Components (LWC)
|
| Testing, Debugging, and Deployment | - Deployment practices
- 1. Salesforce DX and CI/CD basics
- 2. Change sets and metadata deployment
- Testing strategies
- 1. Apex unit testing and code coverage
- 2. Mocking and test data generation
|
>> PDII-JPNリンクグローバル <<
PDII-JPN試験の準備方法|更新するPDII-JPNリンクグローバル試験|真実的なミシュレーション問題
我々PassTestは一番行き届いたアフタサービスを提供します。Salesforce PDII-JPN試験問題集を購買してから、一年間の無料更新を楽しみにしています。あなたにSalesforce PDII-JPN試験に関する最新かつ最完備の資料を勉強させ、試験に合格させることだと信じます。もしあなたはPDII-JPN試験に合格しなかったら、全額返金のことを承諾します。
Salesforce 認定 PDII-JPN 試験問題 (Q130-Q135):
質問 # 130
開発者は、単一のカスタム コントローラーを使用して複数ページのウィザードを構築し、データのクエリと更新を行いました。
を。ユーザーは、ページの読み込みが遅いと不満を漏らしています。
何がパフォーマンスを向上させますか? (3つ選んでください。)
- A. 選択クエリの使用
- B. 標準スタイルシートをオフにする
- C. Apex ページ属性 cache=true の設定
- D. ビューステートを減らす
- E. actionRegion と rerender を使用する
正解:A、C、D
質問 # 131
Apex トリガーと Apex クラスは、ケースが変更されるたびにカウンター `Edit_Count__c` を増分します。
```java
public class CaseTriggerHandler {
public static void handle(List<Case> cases) {
for (Case c : cases) {
c.Edit_Count__c = c.Edit_Count__c + 1;
}
}
}
trigger on Case(before update) {
CaseTriggerHandler.handle(Trigger.new);
}
```
ケースオブジェクトに、ケースの作成または更新時に実行される保存前レコードトリガフローを本番環境に新しく追加しました。このプロセスを追加して以来、ケースの編集時に「Edit_Count__c」が複数回増加しているという報告を受けています。この問題を修正するApexコードはどれでしょうか?
- A. Edit_Count__c = c.Edit_Count__c + 1;
}
}
firstRun = false;
}
}
trigger on Case(before update) {
CaseTriggerHandler.handle(Trigger.new);
}
``` - B. ```java
public class CaseTriggerHandler {
Boolean firstRun = true;
public static void handle(List<Case> cases) {
if (firstRun) {
for (Case c : cases) { - C. ```java
public class CaseTriggerHandler {
public static Boolean firstRun = true;
public static void handle(List<Case> cases) {
for (Case c : cases) { - D. ```java
trigger on Case(before update) {
Boolean firstRun = true;
if (firstRun) {
CaseTriggerHandler.handle(Trigger.newMap);
}
firstRun = false;
}
``` - E. Edit_Count__c = c.Edit_Count__c + 1;
}
}
}
trigger on Case(before update) {
CaseTriggerHandler.firstRun = true;
if (CaseTriggerHandler.firstRun) {
CaseTriggerHandler.handle(Trigger.newMap);
}
CaseTriggerHandler.firstRun = false;
}
``` - F. ```java
public class CaseTriggerHandler {
public static Boolean firstRun = true;
public static void handle(List<Case> cases) {
for (Case c : cases) { - G. Edit_Count__c = c.Edit_Count__c + 1;
}
}
}
trigger on Case(before update) {
if (CaseTriggerHandler.firstRun) {
CaseTriggerHandler.handle(Trigger.new);
}
CaseTriggerHandler.firstRun = false;
}
```
正解:E
解説:
This scenario illustrates a classic trigger recursion issue triggered by the Salesforce Order of Execution. When a record is updated, Salesforce runs through a specific sequence: first, it executes "Before-Save" Record- Triggered Flows, then "Before" triggers, followed by "After" triggers, and finally "After-Save" flows and processes. If a process or flow updates the same record that initiated the transaction, the entire cycle of Apex triggers can be re-invoked within that single transaction.
To prevent logic from running multiple times during these re-entrant cycles, developers implement a static boolean variable as a "recursion guard." Static variables in Apex persist for the entire duration of a single transaction. By checking the value of a static boolean at the start of the trigger, the code can determine if it has already processed the current set of records.
Option B is the correct implementation of this pattern. It defines `public static Boolean firstRun = true;` in the handler class. The trigger checks if `firstRun` is true, executes the handler logic, and then immediately sets
`firstRun` to false. Any subsequent execution of the Case trigger within the same transaction will find the variable set to false and skip the increment logic.
Option A is incorrect because it resets `firstRun` to true every time the trigger starts, defeating the guard.
Option C incorrectly uses an instance variable (non-static), which is recreated for every call. Option D uses a local variable within the trigger body, which is re-initialized to true every time the trigger fires, providing no protection against recursion.
質問 # 132
ある開発者は、毎晩 10,000 件の取引先の売上高を更新するバッチ Apex プロセス Batch_Account_Sales を持っています。Batch Apex は Sandbox で設計どおりに機能します。ただし、開発者は Batch Apex クラスのコード カバレッジを取得できません。
テストクラスは次のとおりです。
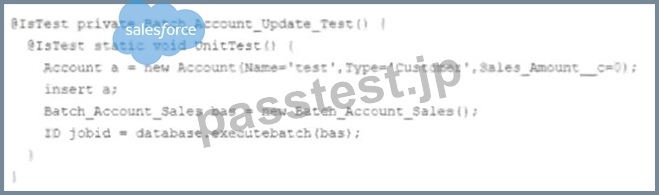
コード カバレッジの問題の原因は何ですか?
- A. バッチ プロセスは、同じセッションで作成された新しいアカウントを認識しません。
- B. アカウントの作成により、既に sates の金額が 0 に設定されています。
- C. executeBatch はテスト内で失敗する必要があります。startTest ( ) および - テスト。stopTest()。
- D. バッチには複数のアカウント レコードを作成する必要があります。
正解:C
質問 # 133
以下の Aura コンポーネントを参照してください。
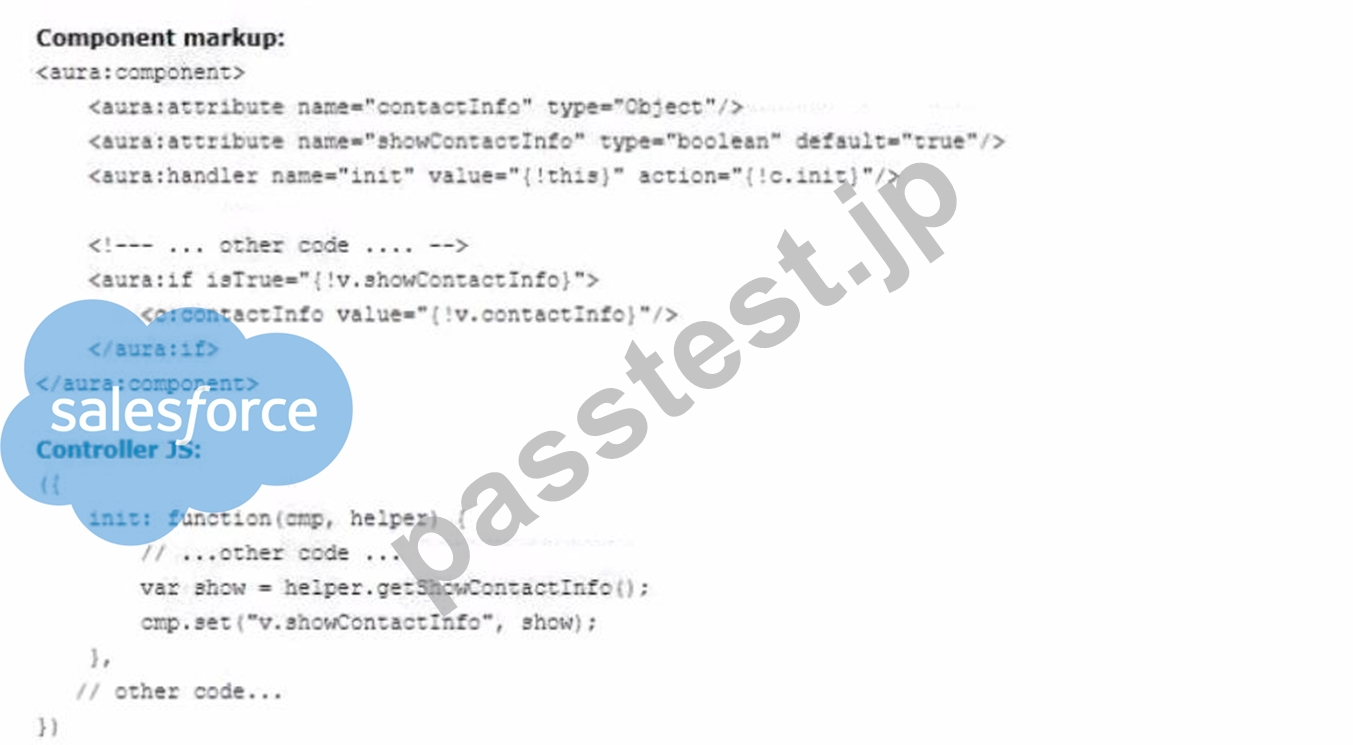
開発者は、コンポーネントの読み込みが遅いという苦情を受け取りました。
コンポーネントの動作を高速化するために、開発者はどの変更を実装できますか?
- A. contactInfo の種類を「マップ」に変更します。
- B. showContactInfo の変更イベント ハンドラーを追加します。
- C. showContactInfo のデフォルトを「False」に変更します。
- D. <c: contactInfo の内容をコンポーネントに移動します。
正解:C
質問 # 134
次のコード スニペットを考えてみましょう。

Apex メソッドはアカウントのデータ量が多い環境で実行されており、クエリのパフォーマンスが低下しています。
結果セット全体を保持しながらクエリを最適に実行するには、開発者はどの手法を実装する必要がありますか?
- A. メソッドに @Future アノテーションを付けます
- B. createdDate と RecordType の値を組み合わせる数式フィールドを作成し、数式に基づいてフィルターします。
- C. クエリを 2 つの個別のクエリに分割し、2 つの結果セットを結合します。
- D. データベースの queryLocator メソッドを使用してアカウントを取得します。
正解:C
解説:
The technique that the developer should implement to ensure the query performs optimally, while preserving the entire result set, is to break down the query into two individual queries and join the two result sets. This is because the query in the code snippet is using a complex filter condition that combines the CreatedDate and RecordType fields, which are not indexed by default. This means that the query will perform a full table scan on the Account object, which can be very slow and inefficient when the data volume is large. To avoid this, the developer can split the query into two queries, one that filters by the CreatedDate field and another that filters by the RecordType field. Then, the developer can use a Set or a Map to store the Ids of the Accounts that match both criteria, and use the Set or the Map to retrieve the Account records from the database. This way, the query will use the standard indexes on the Id, CreatedDate, and RecordType fields, and perform faster and more efficiently.
質問 # 135
......
今の競争が激しい社会にあたり、あなたは努力して所有したいことがあります。IT職員にとって、PDII-JPN試験認定書はあなたの実力を証明できる重要なツールです。だから、Salesforce PDII-JPN試験に合格する必要があります。それで、弊社の質高いPDII-JPN試験資料を薦めさせてください。
PDII-JPNミシュレーション問題: https://www.passtest.jp/Salesforce/PDII-JPN-shiken.html
- 100%合格率のPDII-JPNリンクグローバル試験-試験の準備方法-信頼的なPDII-JPNミシュレーション問題 😆 ➤ www.passtest.jp ⮘にて限定無料の➠ PDII-JPN 🠰問題集をダウンロードせよPDII-JPN模擬トレーリング
- 便利なSalesforce PDII-JPNリンクグローバル - 合格スムーズPDII-JPNミシュレーション問題 | 信頼的なPDII-JPN模試エンジン 🦊 今すぐ「 www.goshiken.com 」で「 PDII-JPN 」を検索し、無料でダウンロードしてくださいPDII-JPN試験関連情報
- 便利なSalesforce PDII-JPNリンクグローバル - 合格スムーズPDII-JPNミシュレーション問題 | 信頼的なPDII-JPN模試エンジン ⏫ [ www.it-passports.com ]を開き、➡ PDII-JPN ️⬅️を入力して、無料でダウンロードしてくださいPDII-JPN資格参考書
- PDII-JPN日本語版復習資料 🐾 PDII-JPN資格受験料 ♣ PDII-JPN最新受験攻略 🕑 ➥ PDII-JPN 🡄の試験問題は▛ www.goshiken.com ▟で無料配信中PDII-JPN資格参考書
- 便利なSalesforce PDII-JPNリンクグローバル - 合格スムーズPDII-JPNミシュレーション問題 | 信頼的なPDII-JPN模試エンジン 🌂 URL ☀ www.mogiexam.com ️☀️をコピーして開き、➤ PDII-JPN ⮘を検索して無料でダウンロードしてくださいPDII-JPN試験復習
- PDII-JPN関連合格問題 🕣 PDII-JPN過去問無料 🕕 PDII-JPN模擬解説集 🐀 ➥ PDII-JPN 🡄の試験問題は➤ www.goshiken.com ⮘で無料配信中PDII-JPNテストサンプル問題
- PDII-JPN試験復習 🆗 PDII-JPN模擬解説集 🚍 PDII-JPN資格トレーリング 🌞 ⏩ www.passtest.jp ⏪で《 PDII-JPN 》を検索し、無料でダウンロードしてくださいPDII-JPN資格トレーリング
- PDII-JPN関連資格知識 🐴 PDII-JPN模擬問題 😯 PDII-JPN模擬解説集 🖤 [ www.goshiken.com ]を入力して【 PDII-JPN 】を検索し、無料でダウンロードしてくださいPDII-JPN試験復習
- PDII-JPN認証資格 🤟 PDII-JPN模擬問題 🦛 PDII-JPNテストサンプル問題 🚏 ➤ www.mogiexam.com ⮘を開いて☀ PDII-JPN ️☀️を検索し、試験資料を無料でダウンロードしてくださいPDII-JPNテストサンプル問題
- PDII-JPN模擬問題 💑 PDII-JPN試験関連情報 🤓 PDII-JPN認証資格 🥵 ✔ PDII-JPN ️✔️の試験問題は☀ www.goshiken.com ️☀️で無料配信中PDII-JPN試験復習
- 効果的なPDII-JPNリンクグローバル - 合格スムーズPDII-JPNミシュレーション問題 | 真実的なPDII-JPN模試エンジン 🔕 “ www.it-passports.com ”サイトにて▛ PDII-JPN ▟問題集を無料で使おうPDII-JPN試験復習
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
さらに、PassTest PDII-JPNダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1_OmGBbog8wR4ZCdXDzE_SFQlpp9Sbp_X