Latest Certified-Data-Engineer-Professional Exam Objectives, Latest Certified-Data-Engineer-Professional Dumps

The advent of our Databricks Certified-Data-Engineer-Professional study guide with three versions has helped more than 98 percent of exam candidates get the certificate successfully. Rather than insulating from the requirements of the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Real Exam, our Certified-Data-Engineer-Professional practice materials closely co-related with it.
| Section | Objectives |
|---|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Use control flow operators in pipeline components
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Develop unit and integration tests for data processing code
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
>> Latest Certified-Data-Engineer-Professional Exam Objectives <<
Latest Certified-Data-Engineer-Professional Dumps & Certified-Data-Engineer-Professional Instant Access
As you know, the low-quality latest Certified-Data-Engineer-Professional exam torrent may do harmful influence on you which may causes results past redemption. Whether you have experienced that problem or not was history by now. The free demos do honor to the perfection of our latest Certified-Data-Engineer-Professional exam torrent, and also a performance of our considerate after sales services. Those demos serve as epitomes of real Certified-Data-Engineer-Professional Quiz guides for your reference. In our demos, some examples or question points were enumerated as some representatives of our Certified-Data-Engineer-Professional test prep. How convenient and awesome of it!
Databricks Certified Data Engineer Professional Sample Questions (Q195-Q200):
NEW QUESTION # 195
The data engineering team maintains the following code:

Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- B. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- C. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- D. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
- E. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
Answer: C
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 196
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API.
They need to list all jobs, identify a failed job, and rerun it. Which sequence of API actions should the data engineer perform?
- A. Use the jobs/cancel endpoint to remove failed jobs, then recreate them with jobs/create and run the new ones.
- B. Use the jobs/get endpoint to retrieve job details, then use jobs/update to rerun failed jobs.
- C. Use the jobs/list endpoint to list jobs, then use the jobs/create endpoint to create a new job, and run the new job using jobs/run-now.
- D. Use the jobs/list endpoint to list jobs, check job run statuses with jobs/runs/list, and rerun a failed job using jobs/run-now.
Answer: D
Explanation:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
NEW QUESTION # 197
Why are Pandas UDFs often preferred over traditional PySpark UDFs in performance-critical applications involving large datasets?
- A. They leverage Apache Arrow to enable vectorized operations between the JVM and Python runtimes, reducing serialization costs and improving computational efficiency.
- B. They minimize memory usage by streaming each row individually through a lightweight Python wrapper, avoiding batch processing overhead.
- C. They eliminate the JVM-Python boundary by bypassing serialization entirely, thereby avoiding data conversion overhead.
- D. They allow row-level execution of functions in Python with native Spark optimization, removing the need for columnar execution.
Answer: A
Explanation:
Pandas UDFs use Apache Arrow to transfer data between the JVM and Python in a columnar, vectorized format. This significantly reduces serialization overhead and enables efficient batch processing, resulting in much better performance than traditional row-by-row PySpark UDFs on large datasets.
NEW QUESTION # 198
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each microbatch of data is processed in less than 3s; at least 12 times per minute, a microbatch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution.
Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
- A. Increase the number of shuffle partitions to maximize parallelism, since the trigger interval cannot be modified without modifying the checkpoint directory.
- B. Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.
- C. Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.
- D. Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.
- E. Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to maximum allowable threshold should minimize this cost.
Answer: E
NEW QUESTION # 199
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
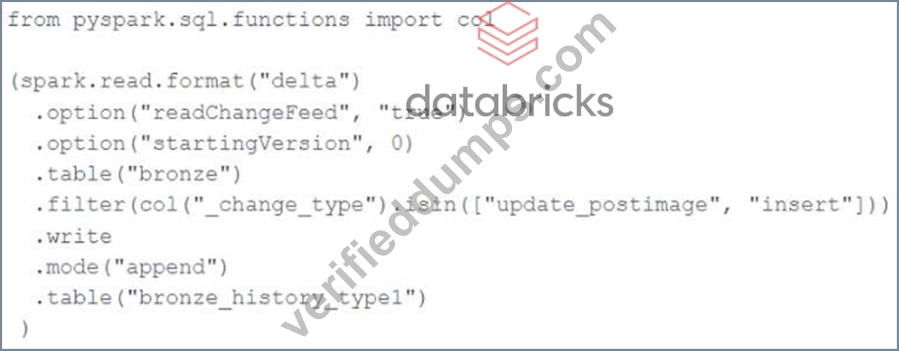
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- B. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- C. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
Answer: B
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 200
......
The Certified-Data-Engineer-Professional Learning Materials of us are pass guaranteed and money back guaranteed. Since the Certified-Data-Engineer-Professional exam dumps are of high accuracy and high quality, and it can ensure you pass the exam successfully. We also give you any help you want, if you need any help or you have any questions, just contact us without any hesitation, we will do all we can to help you pass the exam. Just have a try, and you will benefit a lot.
Latest Certified-Data-Engineer-Professional Dumps: https://www.verifieddumps.com/Certified-Data-Engineer-Professional-valid-exam-braindumps.html
- Reliable Certified-Data-Engineer-Professional Test Camp 🚑 Certified-Data-Engineer-Professional 100% Correct Answers 🦔 Certified-Data-Engineer-Professional Certification Dump 😰 Search for “ Certified-Data-Engineer-Professional ” on “ www.practicevce.com ” immediately to obtain a free download 🦂Certified-Data-Engineer-Professional Study Tool
- Quiz 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Unparalleled Latest Exam Objectives 😓 Open [ www.pdfvce.com ] enter 《 Certified-Data-Engineer-Professional 》 and obtain a free download 🐑Premium Certified-Data-Engineer-Professional Files
- Premium Certified-Data-Engineer-Professional Files 👤 Exam Certified-Data-Engineer-Professional Blueprint 🏪 Exam Certified-Data-Engineer-Professional Blueprint ▛ Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on ☀ www.exam4labs.com ️☀️ 👿Reliable Certified-Data-Engineer-Professional Test Camp
- Certified-Data-Engineer-Professional Certification Dump 🐅 Certified-Data-Engineer-Professional Certification Dump 🚑 Reliable Certified-Data-Engineer-Professional Test Camp 📃 Search for ➠ Certified-Data-Engineer-Professional 🠰 on ⏩ www.pdfvce.com ⏪ immediately to obtain a free download 🍓Certified-Data-Engineer-Professional Valid Dumps Ppt
- Quiz 2026 Databricks Efficient Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Exam Objectives 📭 Search for ▷ Certified-Data-Engineer-Professional ◁ on ⇛ www.prep4sures.top ⇚ immediately to obtain a free download 🤵Examcollection Certified-Data-Engineer-Professional Dumps
- Authoritative Latest Certified-Data-Engineer-Professional Exam Objectives | Amazing Pass Rate For Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional | Accurate Latest Certified-Data-Engineer-Professional Dumps 🧆 Open ⏩ www.pdfvce.com ⏪ enter ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download 💎Examcollection Certified-Data-Engineer-Professional Dumps
- Exam Certified-Data-Engineer-Professional Blueprint 🍁 Trustworthy Certified-Data-Engineer-Professional Exam Torrent 🍑 Premium Certified-Data-Engineer-Professional Files 🍐 Search for “ Certified-Data-Engineer-Professional ” and download it for free immediately on ▶ www.prep4away.com ◀ 🍶Certified-Data-Engineer-Professional Exam Dump
- Free PDF Latest Certified-Data-Engineer-Professional Exam Objectives - Leading Offer in Qualification Exams - Authorized Latest Certified-Data-Engineer-Professional Dumps 👉 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ⮆ www.pdfvce.com ⮄ 🔈Certified-Data-Engineer-Professional Study Tool
- Quiz 2026 Databricks Efficient Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Exam Objectives 🌻 Copy URL ⮆ www.practicevce.com ⮄ open and search for { Certified-Data-Engineer-Professional } to download for free 🏰Certified-Data-Engineer-Professional Exam Dumps Provider
- Pass Guaranteed 2026 Accurate Databricks Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Exam Objectives 😹 Easily obtain free download of ➠ Certified-Data-Engineer-Professional 🠰 by searching on ▷ www.pdfvce.com ◁ 👠Exam Certified-Data-Engineer-Professional Blueprint
- Certified-Data-Engineer-Professional Study Guides 🕶 Reasonable Certified-Data-Engineer-Professional Exam Price 🥅 Reasonable Certified-Data-Engineer-Professional Exam Price 🕯 Open ➤ www.prep4away.com ⮘ enter “ Certified-Data-Engineer-Professional ” and obtain a free download 🚦Latest Certified-Data-Engineer-Professional Exam Objectives
- faithlife.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes