What's more, part of that Exam4Free AI-300 dumps now are free: https://drive.google.com/open?id=1Gxzu-cpyBu5B2RDJiHKGyFgyJ64sUuJW
Free demos of Exam4Free AI-300 exam questions are available which you can download easily. Just choose the right Exam4Free AI-300 exam questions format and download the AI-300 exam product demo free of cost. Check the top features of AI-300 Exam Questions and if you feel that the Exam4Free Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam practice material can work with you then take your buying decision and download it accordingly. Best of luck!!!
| Section | Objectives |
|---|---|
| Topic 1: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates |
| Topic 2: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production |
| Topic 3: Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails |
| Topic 4: Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries - Configure source control, CI/CD pipelines, and automation for ML workflows - Implement security, governance, and compliance for MLOps |
| Topic 5: Optimize generative AI systems and model performance | - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies |
>> Reliable Study AI-300 Questions <<
Are you tired of preparing different kinds of exams? Are you stuck by the aimless study plan and cannot make full use of sporadic time? Are you still overwhelmed by the low-production and low-efficiency in your daily life? If your answer is yes, please pay attention to our AI-300 guide torrent, because we will provide well-rounded and first-tier services for you, thus supporting you obtain your dreamed AI-300 certificate and have a desired occupation. We can say that our AI-300 test questions are the most suitable for examinee to pass the exam, you will never regret to buy it.
NEW QUESTION # 205
A team deploys a generative AI application that uses a model deployed in Microsoft Foundry.
The application must support latency monitoring under production load.
You need to enable performance observability.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.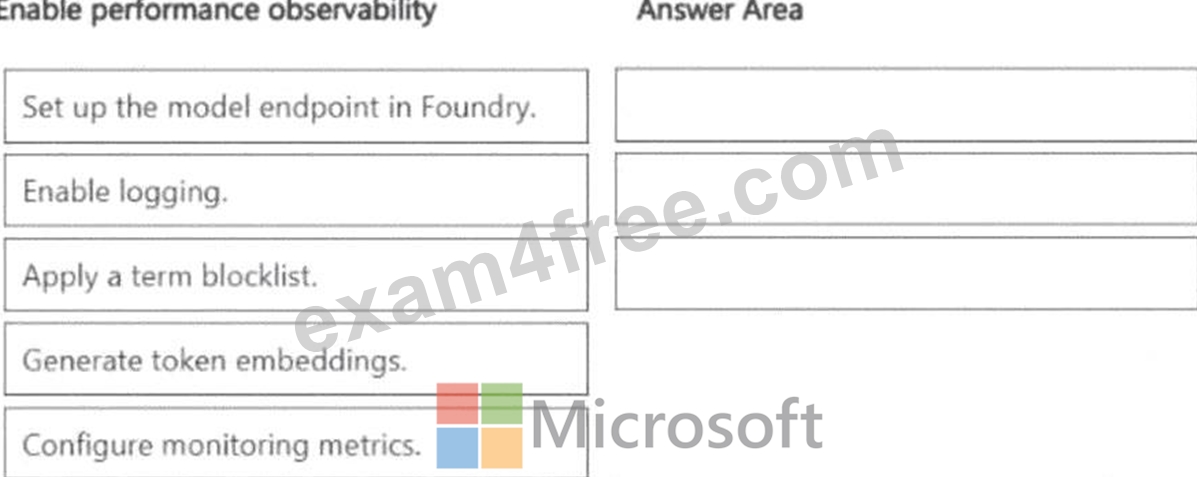
Answer:
Explanation: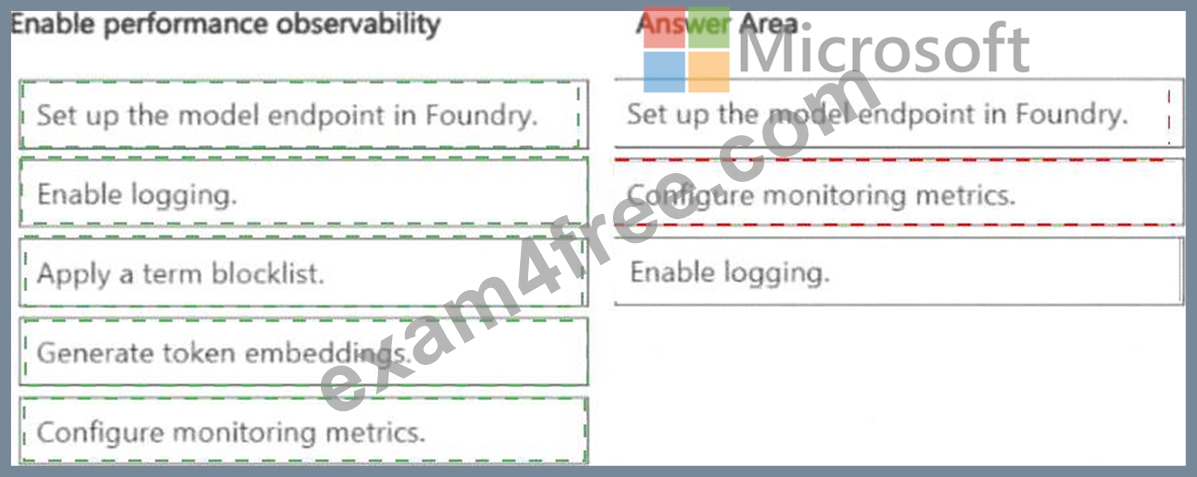
Explanation:
Microsoft ' s observability guidance for Azure AI Foundry applications describes a three-stage activation sequence. First, enable Tracing in the Microsoft Foundry project settings before deployment - Tracing instruments the application ' s LLM calls with OpenTelemetry-compatible spans that capture timing data for each step in the flow. Second, deploy the application to a production endpoint so that real traffic flows through the instrumented code path - without actual production traffic, there is no latency data to observe.
Third, configure Azure Monitor and Application Insights to receive, aggregate, and visualize the telemetry emitted by Tracing. Azure Monitor ' s metrics explorer and Application Insights ' performance views display p50, p95, and p99 latency distributions over time, enabling the team to identify latency regressions and set alert thresholds. This sequence - instrument, deploy, visualize - is the canonical Microsoft path to production AI performance observability.
Microsoft Learn Reference Topic: Monitor generative AI applications with Azure Monitor and Microsoft Foundry Tracing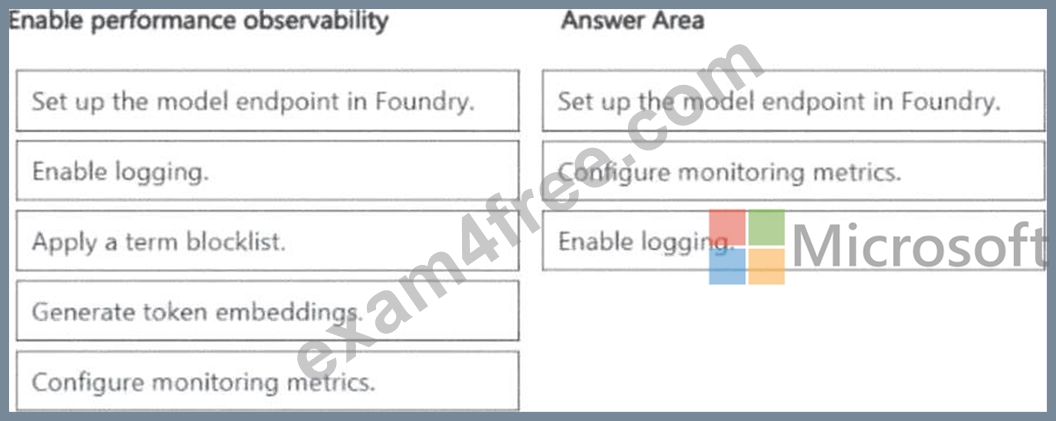
NEW QUESTION # 206
You must ensure full reproducibility of experiments including dataset, code, and environment across multiple runs and workspaces. Which combination of practices is MOST appropriate?
Answer: C
Explanation:
Reproducibility requires versioning all components: code, datasets, and environments. Missing any of these elements prevents exact replication of experiments. For example, the same code with different data or dependencies can produce different results, making debugging and auditing difficult.
NEW QUESTION # 207
Fabrikam Inc. needs to improve the performance of a GPT-5 model based on the stated technical requirements.
Which action should you perform first?
Answer: D
Explanation:
The first action should be to evaluate the model output . Fabrikam already has evaluation data containing manually defined expected responses, and the technical requirements explicitly state that the organization must use its existing evaluation datasets based on real data with input-output pairs . Microsoft Foundry supports evaluating a model against an existing curated dataset to establish measurable baseline performance before optimization. Evaluation results can identify weaknesses in accuracy, relevance, groundedness, safety, or other quality dimensions and provide objective evidence for subsequent changes.
This sequencing is critical because Fabrikam also requires that advanced fine-tuning be applied only when prompt engineering is insufficient . Therefore, immediately fine-tuning the model would bypass the required baseline evaluation and optimization process. Fine-tuning should be driven by demonstrated performance gaps, not applied automatically.
Deploying directly to production is also inappropriate because leadership requires low operational risk and gradual rollout. Production traffic should not be used as the first evaluation mechanism when curated evaluation data already exists. Synthetic interaction data is useful when evaluation coverage is insufficient, but Microsoft specifically positions synthetic generation as an option when an adequate test dataset is unavailable. Fabrikam already has suitable evaluation data.
Study Guide Reference: Optimize generative AI systems and model performance - evaluate model performance, benchmark against curated datasets, iterate on prompts, and apply advanced fine-tuning when justified.
NEW QUESTION # 208
A team manages an Azure Machine Learning workspace where they deploy models to online endpoints.
The team needs to introduce a new version of a model to production without disrupting existing users.
The team must validate the new version before full rollout.
You need to reduce risk during deployment.
What should you do?
Answer: B
Explanation:
According to Microsoft ' s Azure Machine Learning documentation on managed online endpoints, a single endpoint can host multiple named deployments simultaneously, and you can control what percentage of incoming traffic each deployment receives. This traffic-splitting capability is the foundation of blue/green and canary deployment strategies. When you route 10% of traffic to a new deployment and 90% to the existing one, you can monitor error rates, latency, and output quality of the new version under real production load without risking the majority of users. Microsoft explicitly recommends this pattern for safe rollouts. Option A (batch endpoint) is inappropriate for real-time serving. Option C (replacing the endpoint) is high-risk with no validation window. Option D (routing all traffic to the new deployment) provides zero protection if the new version has issues.
Microsoft Learn Reference Topic: Safe rollout of machine learning models - Traffic splitting on managed online endpoints
NEW QUESTION # 209
A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.
The endpoint returns errors after the new deployment is released.
You need to restore the service as quickly as possible.
What should you do first?
Answer: A
Explanation:
To restore the service as quickly as possible, you can roll back traffic to the previous deployment by updating the traffic allocation settings of your Azure Machine Learning online endpoint.
Azure Machine Learning managed online endpoints support multiple deployments under a single endpoint, allowing for blue-green deployment strategies where you can shift traffic between versions instantly.
Key Benefits of This Approach
Instant Recovery: Traffic shifting is a routing change and does not require redeploying the previous model's code or environment, making it the fastest recovery method.
No Downtime: Because the previous deployment remains "warm" (active but receiving no traffic), the switch happens without interrupting the service.
Isolation for Debugging: You can keep the failing deployment at 0% traffic to inspect its logs using az ml online-deployment get-logs without affecting end users How to Roll Back Traffic If your new deployment (e.g., "green") is returning errors, you can reallocate 100% of the traffic back to the known stable deployment (e.g., "blue") using the following methods:
* Azure CLI: Use the az ml online-endpoint update command to set the traffic percentage:
az ml online-endpoint update --name <your-endpoint-name> --traffic "blue=100 green=0"
* Azure Machine Learning Studio:
Navigate to Endpoints in the left menu.
Select your specific real-time endpoint.
Go to the Details or Live Traffic tab.
Adjust the traffic percentages so the previous deployment receives 100% and the failing deployment receives 0%.
Select Update or Save to apply the changes immediately
Reference:
https://learn.microsoft.com/en-us/answers/questions/1275110/azure-ml-v2-yaml-code-for-live- traffic-allocation
NEW QUESTION # 210
......
To become more powerful and struggle for a new self, getting a professional AI-300 certification is the first step beyond all questions. We suggest you choose our AI-300 test prep ----an exam braindump leader in the field. Since we release the first set of the AI-300 quiz guide, we have won good response from our customers and until now---a decade later, our products have become more mature and win more recognition. And our AI-300 Exam Torrent will also be sold at a discount from time to time and many preferential activities are waiting for you.
Practice AI-300 Online: https://www.exam4free.com/AI-300-valid-dumps.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=1Gxzu-cpyBu5B2RDJiHKGyFgyJ64sUuJW